tiny-cuda-nn: the model is a JSON dictionary, the speed is a JIT decision
Lightning fast C++/CUDA neural network framework
At a glance
- What is it?
- tiny-cuda-nn is a small C++/CUDA framework whose networks are described as nlohmann::json dictionaries, and whose v2.0 speedups come from compiling a model into a CUDA device function at runtime. The catch is that the flagship fully fused MLP only fits on high end cards, and JIT mode can quietly turn itself off.
- Who is it for?
- Adopt tiny-cuda-nn if you are writing C++ or PyTorch against an NVIDIA GPU you control, and you can live with the fact that the default network type will likely only work on an RTX 3090, an RTX 2080 Ti, or higher-end GPUs. Stay away if you need a CPU fallback, a licence you can read at a glance, or a stable release cadence, because the only 2.x tag shipped on 2025-07-08 and the licence is only stated in LICENSE.txt.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 46 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
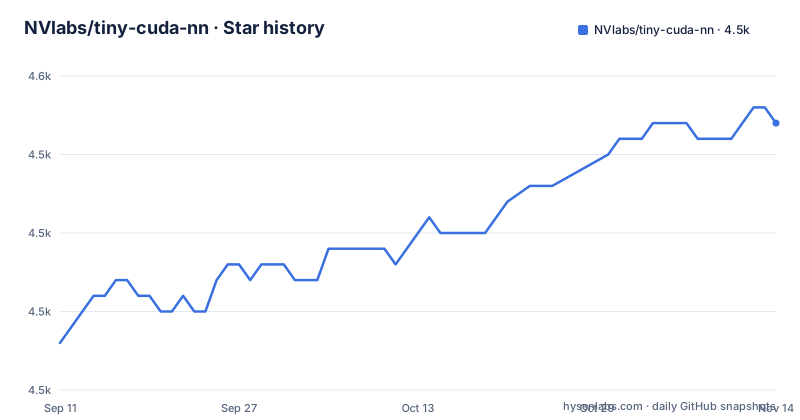
Star history
- NVlabs/tiny-cuda-nn4,547 ★ · +14
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| NVlabs/tiny-cuda-nn | 4.5k | 4.5k |
14 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Every network is four otype keys in a JSON dictionary
A model is a `nlohmann::json` object with four sections, and each section names its own implementation with an `otype` string: `L2` for the loss, `Adam` for the optimizer, `HashGrid` for the input encoding, `FullyFusedMLP` for the network. The remaining keys are parameters of whichever implementation the otype selected, so switching a loss or an encoding is a string swap rather than a code change.
#include <tiny-cuda-nn/common.h>

// Configure the model
nlohmann::json config = {
	{"loss", {
		{"otype", "L2"}
	}},
	{"optimizer", {
		{"otype", "Adam"},
		{"learning_rate", 1e-3},
	}},
	{"encoding", {
		{"otype", "HashGrid"},
		{"n_levels", 16},
		{"n_features_per_level", 2},
		{"log2_hashmap_size", 19},
		{"base_resolution", 16},
		{"per_level_scale", 2.0},
	}},
	{"network", {
		{"otype", "FullyFusedMLP"},
		{"activation", "ReLU"},
		{"output_activation", "None"},
		{"n_neurons", 64},
		{"n_hidden_layers", 2},
	}},
};
The values above are the README's example: 16 hash levels with 2 features each, a hashmap of 2 to the 19, a base resolution of 16 doubling per level, and a 64 wide network with two hidden layers.
FullyFusedMLP only fits on an RTX 3090 or better
The fully fused multilayer perceptron is the component the project is known for, and it is also the one with a hard hardware floor. In its default configuration it needs a very large amount of shared memory, and the README says it will likely only work on an RTX 3090, an RTX 2080 Ti, or higher end GPUs. Lower end cards have exactly two documented ways out: reduce `n_neurons`, or switch the otype to `CutlassMLP`, which is described as having better compatibility but being slower. Neither option is a tuning knob, one of them changes the network type you are benchmarking.
Tensor cores increase performance when they are available, and every result shown in the README comes from an RTX 3090. The headline comparison against TensorFlow v2.5.0 with XLA is drawn on 64 and 128 neuron wide perceptrons, and it is reproducible from the repository: `benchmarks/bench_ours.cu` and `benchmarks/bench_tensorflow.py` generate it from `data/config_oneblob.json`. The practical consequence is that a reader on a card that is not in that list should read the compatibility paragraph first and the performance figure last.
JIT fusion compiles the model into a device function, then turns itself off if it fails
JIT fusion arrived in v2.0 and is optional. The README calls it almost always recommended and puts the gain at 1.5x to 2.5x depending on model and GPU, with newer GPUs showing larger speedups. The mechanism is that a model is converted into a CUDA device function and compiled into a kernel using CUDA's runtime compilation feature, and the switch is one property on the model object.
auto model = tcnn::create_from_config(...);
model->set_jit_fusion(tcnn::supports_jit_fusion()); // Enable JIT if the system supports it
Setting `jit_fusion` to true applies to all later uses of that model, for inference and for training alike. The failure behaviour is the part to remember: if an error occurs during JIT compilation, a warning is emitted and JIT compilation mode is automatically turned off, and your code then runs on the 1.X code path. That is a quiet downgrade rather than an exception, so a benchmark that drops in speed after a driver change may simply be running the old path. The README also names the cases where JIT fusion can slow things down instead of helping.
Very large hash grids and RTX 3000 series parts are where JIT fusion backfires
The README is unusually direct about the downside. If a model has hash grids of roughly 20 million parameters or more, or multilayer perceptrons with layer sizes larger than 128 neurons, or if the GPU is an RTX 3000 series card or earlier, JIT fusion can slow training down. Rarely it slows inference as well. In that case the advice is to enable it separately for training and for inference and measure which half benefits.
Anyone reading a speedup figure should establish which side of the line their own configuration falls on before treating it as a property of the framework.
The size boundary is a parameter count on the encoding rather than on the network, so a model can cross it by changing `log2_hashmap_size` and `n_levels` alone while leaving `n_neurons` untouched. The layer boundary runs the other way, where a wider network is enough to push you over it. Because both thresholds sit in the same paragraph, a configuration that is fine on a current card can still be slow on an older one, and the frame you need is the GPU model plus those two counts.
Through PyTorch the same flag fuses less of your graph
JIT fusion can also be enabled through the PyTorch bindings, and the README warns that the speedup is lower there, particularly during training. The reason is structural rather than a tuning problem: the JIT compiler does not have access to the whole compute graph and can therefore fuse and optimize less of it.
import tinycudann as tcnn

model = tcnn.NetworkWithInputEncoding(...) # Or any other tcnn model
model.jit_fusion = tcnn.supports_jit_fusion() # Enable JIT if the system supports it
One line of configuration is the same on both sides, so a PyTorch integration that measures 1.5x has told you little about what the C++ path would do with the same model and the same GPU. Treat the language you bind from as part of the performance configuration, and benchmark in the language you actually ship. Note that the repository ships a PyTorch sample, `samples/mlp_learning_an_image_pytorch.py`, next to the C++ one, `samples/mlp_learning_an_image.cu`, which is a reasonable starting pair for doing that comparison yourself.
Manual fusion is three string operations and one runtime compile
The tighter integration path bypasses the model object. The README describes it as three steps: turn your kernel into a string, prepend the tiny-cuda-nn model's device function, pass the result to the runtime compilation API. The example builds a minimal kernel around a model with 32 input dimensions and 16 output dimensions through `tcnn::CudaRtcKernel`.
#include <tiny-cuda-nn/rtc_kernel.h>

auto model = tcnn::create_from_config(32 /* input dims */, 16 /* output dims */, ...);
auto fused_kernel = tcnn::CudaRtcKernel(
    "your_kernel",
    fmt::format(R"
        {MODEL_DEVICE_FUNCTION}
        __global__ void your_kernel(...) {
            // Get input to model from either registers or memory.
            tcnn::hvec<32> input = ...;
            // Call tiny-cuda-nn model. All 32 threads of the warp must be active here.
            tcnn::hvec<16> output = model_fun(nerf_in, params);
The reported payoff comes from Instant NGP, which reaches a 5x speedup by fusing an entire NeRF ray marcher into a single kernel, and the README points at two files in that project as reference implementations. Two caveats about the snippet itself: it stops before the closing braces, and it declares `input` but then passes `nerf_in` to `model_fun`, so read it as the shape of the call sequence and take the exact types from the header. The other stated constraint matters just as much: all 32 threads of the warp must be active at the call into the model.
Toolchain floor, release gaps, and a licence only named in a file
The requirements are stated as floors rather than suggestions: an NVIDIA GPU, a C++17 capable compiler, a recent CUDA, and CMake v3.21 or higher. Visual Studio 2019 or 2022 with CUDA 11.5 or higher on Windows, GCC/G++ 8 or higher with CUDA 10.2 or higher on Linux, and those are the combinations the project says it has tested. On Linux the one package line given is:
sudo apt-get install build-essential gitCUDA is recommended to be installed under `/usr/local/` and added to the PATH, with 12.6.3 used as the example version.
The release history is the thing to weigh against those floors. Version 1.5 shipped on 2022-04-22 and version 1.6 on 2022-12-15, then nothing until version 2.0 on 2025-07-08, and the default branch was pushed on 2026-09-29. Code, bindings or tutorials written against 1.x describe a path that a JIT fusion user no longer takes, so pin your version before reading anyone else's integration notes. The licence lives in LICENSE.txt, and the repository metadata does not name one, which is a detail to settle yourself before you vendor this into anything.
Editorial conclusion
Adopt tiny-cuda-nn if you are writing C++ or PyTorch against an NVIDIA GPU you control, and you can live with the fact that the default network type will likely only work on an RTX 3090, an RTX 2080 Ti, or higher-end GPUs. Stay away if you need a CPU fallback, a licence you can read at a glance, or a stable release cadence, because the only 2.x tag shipped on 2025-07-08 and the licence is only stated in LICENSE.txt. Verify first that your GPU can hold the fully fused configuration, and measure with JIT fusion both on and off before you keep it enabled.
Frequently asked questions
how to install tiny cuda nn
The README lists the prerequisites: an NVIDIA GPU, a C++17 capable compiler, CUDA, and CMake v3.21 or higher. Recommended and tested combinations are Visual Studio 2019 or 2022 with CUDA 11.5 or higher on Windows, and GCC/G++ 8 or higher with CUDA 10.2 or higher on Linux. On Linux the package line given is `sudo apt-get install build-essential git`.
what is tiny cuda nn
It is a small, self-contained C++/CUDA framework for training and querying neural networks. It ships a fully fused multi-layer perceptron, a multiresolution hash encoding, and support for other input encodings, losses and optimizers, with a simple API where a model is described as a `nlohmann::json` dictionary.
Does tiny-cuda-nn work with PyTorch, and is it as fast?
JIT fusion can be enabled through the PyTorch bindings, but the README says the speedup is lower there, particularly during training, because the JIT compiler does not have access to the whole compute graph and can fuse and optimize less of it. A PyTorch sample ships as `samples/mlp_learning_an_image_pytorch.py`.
When should I leave JIT fusion off in tiny-cuda-nn?
The README names three cases: hash grids with roughly 20 million parameters or more, multi-layer perceptrons with layer sizes larger than 128 neurons, and an RTX 3000 series GPU or earlier. In those cases JIT fusion can slow training down and rarely inference, so the advice is to enable it separately for training and for inference and measure each.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvlabs-tiny-cuda-nn)Star history chart for your README
[](https://hysenlabs.com/projects/nvlabs-tiny-cuda-nn)Was this useful?