VILA: the accuracy benchmark sections are empty headings
VILA is a family of state-of-the-art vision language models (VLMs) for diverse multimodal AI tasks across the edge, data center, and cloud.
At a glance
- What is it?
- VILA is a family of open vision-language models from a research lab, with published throughput and latency tables across three GPUs. The efficiency numbers are there in full; the accuracy sections are headings with nothing under them, and the dependency and container files have two reproducibility gaps worth naming.
- Who is it for?
- VILA suits someone who needs an open vision-language model they can run locally on an edge device and whose serving stack can accommodate a fixed dependency set. Four things to know before you install it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
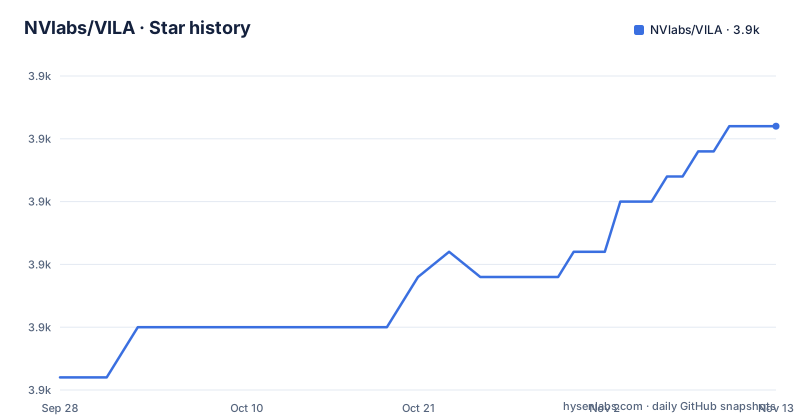
- NVlabs/VILA3,873 ★ · +10
| Repository | 2026-09-28 | 2026-11-13 |
|---|---|---|
| NVlabs/VILA | 3.9k | 3.9k |
10 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The accuracy sections are headings with nothing under them
The performance section opens with four headings in a row: performance, image benchmarks, video benchmarks, and efficient deployments. Two of those four are followed by nothing at all. The page then continues into inference performance and publishes two full tables. So the structure promises accuracy numbers and delivers efficiency numbers. That matters because the news list makes strong accuracy claims in prose: that one release ranked first among open source models on a long video benchmark, that another is the best open sourced model on a multimodal understanding benchmark and on a video benchmark, and that a medical variant significantly outperforms one open medical model and is on par with another. Every one of those claims points at somebody else's leaderboard rather than printing the numbers here. A reader comparing models on quality has to go and reproduce the comparison; a reader comparing throughput has everything on one page.
Throughput and first-token latency disagree about which backend wins
The two tables are only interesting read together, and where they are read together they tell a more complicated story than the headline. On the datacenter GPU the accelerated backend is worth roughly two and a half times the baseline for the eight-billion-parameter model: about 187 against 82 tokens per second on the A100, and about 163 against 62 on the 4090. For the three-billion model the same comparison gives roughly 1.2 to 1.3 times. The edge device is slower by an order of magnitude on the large model, and the video rows on that device wait about 5.8 seconds for the first token against roughly 0.7 on the desktop cards. And on the edge device at the small model size, the accelerated backend is consistently *slower* to first token than the baseline it beats on throughput: 0.136 against 0.117 seconds, and 0.124 against 0.120. So which backend is faster depends on whether you care about tokens per second or about the pause before the first one.
Two dependencies are git installs with no version reference
The dependency list pins almost everything to an exact version, which is the right discipline for a research codebase that has to reproduce numbers. Two entries do not follow it. One is a wrapper package installed straight from a third party's repository, and the other is a package from this organisation's own scaling repository, and neither carries a version, a tag or a commit reference. An install from a branch name resolves to whatever the branch head is on the day you run it, so two people installing this package can end up with different code under the same version number, and there is no way to ask afterwards which one you got. Two other pins are worth noting for the same reason: a fused attention kernel is pinned at a zero point one release, and the natural language toolkit is pinned at a release from the late 2010s, both sitting alongside a modern framework pin.
The container copies three files and suppresses warnings
The container file is short enough to audit, and it tells you exactly what the image is for. The base is the vendor's own PyTorch container. Then it downloads the Anaconda installer with a URL ending in the word latest, installs it to a fixed prefix, and puts that prefix first on the path. Then it copies three things from the repository: the project file, one source directory and the environment setup script, runs the setup, copies a single server script, and sets the command to run that script inside a named environment. So the image is inference only. The training, serving and benchmark directories are not copied in, and any code path that imports them will fail. Two smaller details: the installer is hardcoded to an x86-64 filename, so the image is single architecture, and the command line passes a flag that tells Python to ignore warnings entirely, which will hide deprecation notices from anyone debugging a model on the edge. The two lines that matter, as they appear in the file, are the installer fetch and the command:
RUN curl https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh -o ~/miniconda.sh \
    && sh ~/miniconda.sh -b -p /opt/conda \
&& rm ~/miniconda.shCMD ["conda", "run", "-n", "vila", "--no-capture-output", "python", "-u", "-W", "ignore", "server.py"]The example server defaults to listening on all interfaces and fetches image and video URLs supplied in requests. Before exposing it, restrict network access to trusted clients, add authentication at a suitable gateway, and prevent requests from reaching internal or otherwise sensitive URLs; otherwise a client may use the server to make network requests from its host.
The command line tools live inside a package named after another project
The project installs four console commands: one to run something, one to evaluate, one to infer and one to upload a model to a model hub. All four are entry points into a subpackage called after a different, well known vision-language codebase, and that subpackage is a top-level directory in the repository alongside the project's own package. So the tree contains a second codebase, the tool names are namespaced under it, and the project's own code sits beside it. That is a normal thing for research code that grew out of an earlier implementation, and it has one practical consequence worth knowing: when you read an error traceback from these tools, the paths will often point into the vendored package rather than into this project, which makes grepping the project's own source for the failure the wrong first move.
Code and models carry separate licences, and the owner changed in 2025
The badge row has two licence badges side by side, one for code and one for models, which is the first thing to read on this page. Model weights are frequently under different terms from the code that produces them, and a project that ships both as open releases has to state both. The news list then records a change of ownership: as of the sixth of January 2025 the project is part of a new family of vision language models from the same vendor. So the models in this repository's collection may now be tracked under a different product line, while the code repository continues under the original owner. The rest of the news list shows how much of this lives in other places: two sibling projects are in this organisation, one foundation model release is in a university laboratory's organisation entirely, and a medical variant's code was contributed into an external medical imaging project's repository with the weights published under that project.
Four related projects live in three different organisations
Count the homes. This repository belongs to a vendor organisation. A joint visual and audio model and a reinforcement learning toolkit for long video were both released by that same organisation. A unified foundation model for video, image and language understanding plus generation is in a university laboratory's account instead, which is also where the acceleration backend that most of the throughput numbers depend on lives. The medical variant is documented with a link into a third organisation, an open medical imaging project, with weights under that project's hub account. And the example media on the page are hosted as repository assets under a fourth, older organisation name that does not match the repository's owner. None of that is unusual for a research line, and all of it means the single most useful question, which is what a given model was trained on and where its weights live, has an answer outside this page.
An optional install step is gated on being an employee
The installation section has three steps and the third begins with a condition that has no business being in a public install guide: it applies if you are an employee of the vendor and have an account with the experiment tracker the project uses. The step installs the vendor's internal logging client and tells you to enable it by setting a specific training argument to true. So the public path is documented in three steps and the private path in four, and the difference is one environment package. That is worth reading for a second reason too: the same logging client is the mechanism behind much of the tracking implied by the published numbers, and knowing that an employee-only integration exists tells you something about how those runs were instrumented.
Editorial conclusion
VILA suits someone who needs an open vision-language model they can run locally on an edge device and whose serving stack can accommodate a fixed dependency set. Four things to know before you install it. Code and models are licensed separately, so the terms for a checkpoint are not the terms for the repository. The dependency set is almost entirely pinned but includes two git installs with no version reference, so two installs can produce different trees. The accuracy claims are not tabulated on the page, while the efficiency claims are, so evaluate quality yourself rather than from the leaderboard references in the news list. And the container is inference only, because it copies three files out of the repository.
Frequently asked questions
How do vision language models work?
The repository does not explain the field. It contributes to it: the original release proposed interleaved image and text pre-training, which it credits with enabling a model that handles several images in one prompt, and a later generation of the family added a vision encoder scaled to high-resolution pre-training and paired it with the model for detail-heavy images. The published tables measure decoding throughput and time to first token across three GPUs rather than accuracy.
Which are the vision language models?
This repository describes its own family and several siblings. The video-capable release came in four sizes at three, eight, thirteen and forty billion parameters. The second generation adds full-stack efficiency work, and a variant of it exists in a lighter form. There are also separate entries for a long-video model with a context length over a million tokens, a medical variant, a joint visual and audio model, a reinforcement learning toolkit for long video, and a high-resolution variant built on the scaling encoder.
Is VLM better than LLM?
The repository makes no such comparison, since a vision-language model contains a language model rather than competing with one. Its own claims are about two axes against other vision-language models: efficiency, for which it publishes throughput and first-token latency tables across a datacenter GPU, a consumer GPU and an edge module, and accuracy, for which it points at external leaderboards rather than printing numbers.
What is the NVIDIA Vision Language Model?
Nothing here answers that beyond noting that this project became part of a new family of vision-language models from the vendor as of January 2025. The repository describes its own family as open models optimised for video and multi-image understanding, distributed as a collection on a model hub under a collection belonging to the vendor, with the code under the Apache licence and the weights under their own separate terms.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvlabs-vila)Star history chart for your README
[](https://hysenlabs.com/projects/nvlabs-vila)Was this useful?