EO installs a 0.37.1 command line tool while the language ships 0.63
EOLANG, an Experimental Pure Object-Oriented Programming Language Based on 𝜑-Calculus
At a glance
- What is it?
- objectionary/eo is an experimental object-oriented language with no types, no classes and no NULL, compiled by a parser driven from a numbered rule specification. Its command line tool and its language releases are on two separate version lines, and one recent release title is a bug report.
- Who is it for?
- EO suits someone who wants to read a language design built on a published calculus rather than adopt one, and who is willing to treat every loop and conditional as an object you decorate instead of syntax you write. Three things to know before writing anything in it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
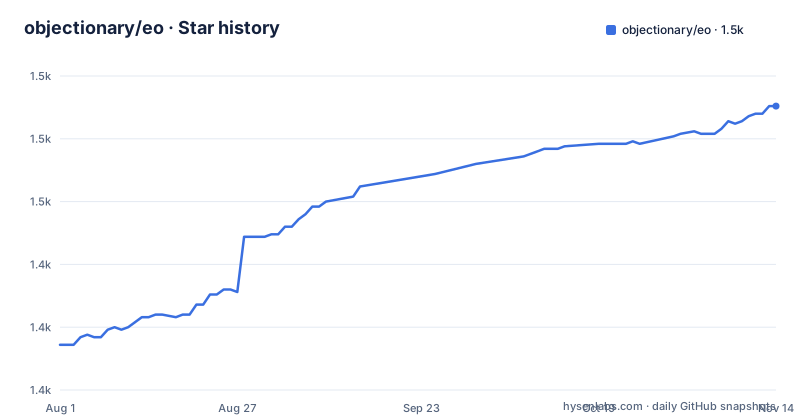
- objectionary/eo1,488 ★ · +95
| Repository | 2026-08-01 | 2026-11-14 |
|---|---|---|
| objectionary/eo | 1.4k | 1.5k |
95 Stars in the last 105 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The command line tool and the language are versioned separately
The quick start installs the tooling from npm at a fixed version:
npm install -g [email protected]The language releases, meanwhile, are numbered 0.63 and up: 0.63.0 on 27 August 2026, 0.63.1 on 4 September, and 0.63.2 on 1 October. The npm tool and compiler have independent version sequences, so their numeric difference does not by itself show that the tool is behind or incompatible. Pinning the tool helps reproduce the installation, but verify which compiler version that tool selects and pin or record it separately. There are two distribution channels in total. The command line arrives through npm under the name eolang, while the compiler itself is a set of Maven artifacts under the org.eolang group, with the parser published separately. Nothing in the quick start says which language version the installed tool expects, so the pairing is something you have to infer from the two pages.
One release title is a description of a regression
The three most recent releases are titled with what they changed rather than with a conventional note. Publishing the inference report to a documentation branch is what 0.63.0 says. Then 0.63.1 says that transpiled string.regex references atom classes that do not exist, breaking downstream compilation. A release title alone does not establish whether the described defect was introduced, fixed, or merely investigated in that release. Read the linked changes and test the relevant version before relying on that interpretation. The third, 0.63.2, says the lowering module is now built on a symbolic mode that folds EO formations into Java atoms. So one of the three headline changes in three months is a fix, one is a build rework, and one is documentation hosting.
The parser is written against a numbered rule specification
The grammar is not described in prose in the README. It is defined in a separate specification file, eo-parser/PARSER_SPEC.md, described as a spec-driven, line-by-line classification of every legal shape with numbered rules written in the form R-N.M. The implementation then references those rule numbers directly rather than restating them, which means a parser change and a specification change are expected to move together. The reference implementation sits in the parser module and converts EO source into XMIR in a single pass with no intermediate syntax tree. Removing the intermediate tree is the notable part: there is no stage where a tree can be inspected, so a malformed program is rejected against the numbered rules or accepted.
Fourteen things are banned, and loops come back as objects
The list of what the language does not have runs to fourteen items: types, static or class methods and attributes, classes, implementation inheritance, mutability, NULL, global scope, type casting, reflection, scalar types and data primitives, annotations, operators, traits and mixins, and flow control statements. Most of them carry a link to an essay arguing why. The last one is the interesting tension, because the tutorial's iteration example does have a loop. It uses malloc.for, an object named while, and an object named seq, nested as attributes. So the prohibition is on the language having those constructs as syntax, while the behaviour itself is available by decorating with canonical objects. The same pattern applies to conditionals, which appear as objects rather than keywords throughout the examples.
Two spaces of indentation, and two notations for one program
Layout is significant. Nesting is expressed by indentation with exactly two spaces per level, compared directly to Python in the documentation, and a program written vertically has an equivalent horizontal form where arguments sit side by side on one line. Brackets are available to group arguments when a horizontal line would otherwise be ambiguous, as in the version of the example that decorates stdout with a printf copy built from a nested copy. Two other rules explain most of the syntax. An abstract object cannot be used directly: a copy must be made, supplying the arguments it needs, which is why the tutorial builds stdout one argument at a time. And the attribute at sign names the object being decorated, so the outer object inherits the attributes of the object it points at and can add its own alongside it.
Nine Maven modules, one per stage of the pipeline
The repository is a multi-module Maven build and the module names describe the pipeline. eo-parser turns source into XMIR, eo-printer produces the human-facing form, eo-runtime holds the running objects, and eo-cache stores compiled artefacts. Two modules are newer than the rest and map directly onto the recent releases: eo-inference is what generates the report that 0.63.0 started publishing to a documentation branch, and eo-lowering is the module that 0.63.2 rebuilds on the symbolic mode, which is where the language is translated down into Java atoms rather than interpreted. eo-integration-tests and eo-maven-plugin sit alongside them for build integration, and a src directory exists at the root alongside the modules.
MIT in the metadata, a licences directory and REUSE metadata in the tree
The licence field records MIT. The root of the tree carries a LICENSE.txt, and it also carries a LICENSES directory and a REUSE.toml file, which together are the convention for a repository that licenses files individually rather than as one whole. So the repository describes itself as MIT while carrying the apparatus for per-file terms, and a consumer who needs to know exactly which terms apply to a given file has more to read than a single licence file. There is a matching supply-chain scanner configuration in the root as well, which is the sort of tool that reads those per-file records, and a citation file plus a code of conduct for the parts of the project that are not code.
The quality gate is a dozen separate services and files
The root of the tree is as much configuration as source. Separate entries exist for SonarCloud, codecov, a licence scanning service, a dependency risk scanner, a code complexity viewer, and a distributed review service for incoming changes. Alongside them are style configurations for several languages at once: one for Groovy, one for XML, one for XSL transformations, and an editor configuration. Dependency updates are handled by a bot configuration file, and there are two files for a puzzle-driven backlog tool with its own settings. A project this size would normally consolidate, so the reading to take from the list is that the gates are independent and each fails separately, which means a green badge on one says nothing about the others.
Editorial conclusion
EO suits someone who wants to read a language design built on a published calculus rather than adopt one, and who is willing to treat every loop and conditional as an object you decorate instead of syntax you write. Three things to know before writing anything in it. The command line tool is installed from npm at a pinned older version than the language releases, so the two are versioned independently and the pin is not decorative. Compilation goes through a parser driven by a numbered rule specification, which is the document to read if a program does not parse. And the feature list is a prohibition list, so anything you expect from a mainstream language, types, classes, operators, loop keywords, has to be found in the canonical object repository instead.
Frequently asked questions
How do I install and run an EO program?
Install Java SE and npm, then run npm install -g [email protected] to get the eoc command. Write the program in app.eo, compile it with eoc --easy link, which the documentation says may take up to a minute, and run it with eoc --easy --alone dataize app. The installed tool is pinned at 0.37.1 while the language releases are at 0.63.
What is XMIR in EO?
It is a dialect of XML used to represent an EO program, with its own schema and its own specification. The parser converts EO source into XMIR in a single pass with no intermediate syntax tree, so XMIR is the form the rest of the toolchain works with.
Does EO have types, classes or loop statements?
No. The project lists fourteen things it does not have, including types, classes, static methods, implementation inheritance, mutability, NULL, global scope, type casting, reflection, annotations, operators, traits and mixins, and flow control statements. Loops and conditionals are still reachable, but as canonical objects you decorate with, as the tutorial shows with malloc.for and an object named while.
How is the EO parser built?
The grammar is defined in eo-parser/PARSER_SPEC.md as a spec-driven, line-by-line classification of every legal shape with numbered rules written as R-N.M, which the implementation references directly. The reference implementation is in the parser module under a Java package path and converts source to XMIR in a single pass with no intermediate syntax tree.
What license is EO released under?
The project's licence field records MIT. The repository root carries a LICENSE.txt file, a LICENSES directory and a REUSE.toml file, which is the per-file licensing convention, and a supply-chain licence scanning configuration sits beside them.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/objectionary-eo)Star history chart for your README
[](https://hysenlabs.com/projects/objectionary-eo)Was this useful?