VLX-Seek turns localization into retrieval instead of coordinate generation
VLX-Seek is a device-native vision-language model that enables machines to see, understand, and reason about the visual world with high precision.
At a glance
- What is it?
- A fine-grained perception vision-language model for embodied vision that encodes candidate regions as addressable tokens and has the language model select and refer to them, rather than emit bounding box numbers. Only the 10B checkpoint of a planned three-size family has been released, and it needs a full CUDA setup.
- Who is it for?
- VLX-Seek is worth a look if your problem is open-vocabulary grounding on embodied imagery where a wrong box is worse than no box, because the None format and hard-negative training target exactly that failure. Check the sizing before you plan around it, since the 0.6B and 3B members of the planned family are not released and only the 10B model has published weights and inference code.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
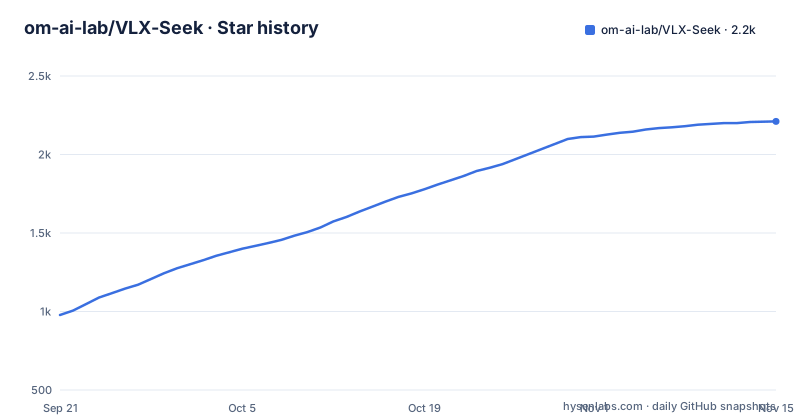
Star history
- om-ai-lab/VLX-Seek2,211 ★ · +1,233
| Repository | 2026-09-21 | 2026-11-15 |
|---|---|---|
| om-ai-lab/VLX-Seek | 978 | 2.2k |
1,233 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The task changes shape, not just accuracy
Most vision-language models that answer where something is do it by generating numbers. VLX-Seek reformulates the task, and the reformulation is the contribution:
image + text query -> generate coordinate numbers -> parse boxesbecomes
image + region tokens + text query -> retrieve matching regions -> grounded answerCandidate regions are encoded as addressable region tokens, and the language model answers by selecting, comparing and referring to those regions rather than emitting a coordinate sequence. The stated argument for this is that coordinates are brittle for language models: they are long numeric sequences, several objects multiply the output length, and a small formatting or ordering error makes the result invalid or inaccurate. The efficiency claim runs alongside the accuracy one, since coordinate generation needs more output tokens, lengthens the decoding path and lowers inference efficiency.
The reframing puts localization into the category of things language models already do well, which the project describes as compare, select, refer, explain and reason over explicit entities. Whether region tokens are cheaper than coordinates depends on how many candidate regions a proposal stage emits, and that number is set upstream of the language model.
The repository description calls this device-native, and the project positions itself for edge-side embodied vision rather than general image chat.
Four requirements, and the fourth is rejection
The overview separates global scene understanding from fine-grained perception, and the difference is spelled out as four capabilities. Precise localization asks where the target is and how its boundary should be separated from nearby objects. Instance distinction asks which object instance matches a language description, as opposed to the class. Multi-object reasoning asks how many targets exist and which regions should be returned. Open-vocabulary rejection asks the model to say so when no region matches the query, instead of hallucinating a box.
That last one is the requirement most systems fail quietly, and it is the one the 1.5 release names directly. Hard-negative rejection training and an explicit None format are the two mechanisms listed for reducing hallucinated detections. In a robotics or inspection loop, a fabricated box is worse than an empty result, because downstream code cannot tell the difference between a confident wrong answer and a correct one, while an empty list is unambiguous.
The training data behind it is described as expanded embodied-scene coverage: drone views, surveillance views and robot views. That is a different distribution from the web imagery most vision-language models are trained on, and it is the part of the design that a region-token reformulation alone would not give you.
Version 1.5 also brought a stronger auxiliary vision tower and VLM backbone for fine-grained region understanding and complex target detection, plus a faster proposal pipeline and more Linear Attention layers to cut inference and memory cost.
One of three planned sizes has shipped
VLX-Seek 1.5 is planned as a family of 0.6B, 3B and 10B models. What exists today is narrower: this repository releases the inference code and model weights for the 10B model, published on 2026-07-23, and the checkpoint table has a single row, VLX-Seek 1.5-10B, marked Released. The 1.5 release itself dates from 2026-07-06, bringing stronger fine-grained perception, faster inference and improved rejection of absent targets for embodied scenarios.
The weights are on Hugging Face at omlab/VLX-Seek-1.5-10B, with a mirror on ModelScope at Om_AI_Lab/VLX-Seek-1.5-10B. There are no GitHub releases attached to the repository, so the version you get is the one on the model hub rather than one pinned by a tag here.
The gap between the edge framing and the released artefact is worth naming. The model is described as device-native and for edge-side embodied vision, and the overview video is subtitled as edge multimodal fine-grained perception. The only checkpoint available is a 10B model whose install path asks for a CUDA-enabled PyTorch build. Nothing in the documentation claims a small model runs on a device today, but a reader arriving at the edge framing will want to know which number to expect on the hardware, and the repository does not answer that yet.
Two checkpoints download, and one of them is a detector
The first run fetches more than the language model. The main weights are downloaded and cached from Hugging Face automatically, with no manual download step. Separately, for detection, grounding and other proposal-dependent tasks, if --bbox-list is not supplied then the recommended region detector checkpoint is downloaded from Hugging Face to the default path resources/ when needed. Two flags change that behaviour: --detector-checkpoint overrides the path, and passing --bbox-list skips the detector entirely.
The detector is the part that makes the region-token design concrete. Something has to propose the candidate regions that then become addressable tokens, and that something is a separate checkpoint fetched at runtime rather than bundled. Supplying your own bbox list is therefore not only an optimisation, it is the escape hatch for running without the proposal stage at all, which is what you would do if you already have detections from another system.
Two files at the top of the repository are named after the same split: detect_tools/ and vlx_seek/, with inference.py at the root and vlx_seek_worker.py beside it. The docs directory and an assets directory sit alongside, and the demo directory holds demo_image.jpg and demo_image2.jpg, which is what the documented command points at.
Clone before you load, because the architecture is local
The dependency ordering is documented but easy to trip over. The model can be loaded straight from Hugging Face by name, without a manual download, but the model architecture is provided by the local vlx_seek package. The instructions therefore require the repository to be cloned and its dependencies installed first, and a first run that skips that step fails on the import rather than on the download.
Installation is three commands:
git clone https://github.com/om-ai-lab/VLX-Seek.git
cd VLX-Seek
pip install -r requirements.txt
Inference goes through inference.py, taking the hub identifier, an image, a task and the text query:
python inference.py \
  --model-path omlab/VLX-Seek-1.5-10B \
  --image-path demo/demo_image.jpg \
  --task detection \
  --text "orange; apple"
The semicolon-separated text is the query format in the example, asking for two object names in one pass, which is the multi-object reasoning case rather than a single lookup.
flash_attn is pinned, gradio is not
The requirements file is short and almost entirely pinned, with one exception worth noticing:
torch==2.10.0
torchvision==0.25.0
transformers==5.13.0
gradio
timm==1.0.9
einops==0.6.1
accelerate==1.4.0
flash_attn==2.8.3
flash_attn at a fixed version is the constraint that shapes an install. It is a compiled extension rather than a pure-Python wheel for most configurations, so it needs a matching CUDA toolchain and often a build step, which is why the requirements call for a CUDA-enabled PyTorch build that matches your system. The stack also sits on transformers 5.13.0, a major version, and torchvision 0.25.0 pinned to torch 2.10.0, so those three move together.
gradio is the one unpinned entry. It is the interactive demo dependency rather than part of the inference path, so leaving it floating keeps a demo surface from blocking a pinned core, and it is the sort of thing that will move under you. If you are building a container or a reproducible environment, pin it yourself.
The stated platform requirements are Python 3.10 or newer, PyTorch with a GPU recommended, and Linux as the primary tested platform.
The Python surface is one worker class
Embedding the model in your own code goes through a single class:
from vlx_seek_worker import VLXSeekWorker

worker = VLXSeekWorker("omlab/VLX-Seek-1.5-10B", device="cuda")
Two things are visible in those two lines. The model identifier is the Hugging Face repository, so the same caching behaviour applies as on the command line, including the detector checkpoint for proposal-dependent tasks. And the device is a constructor argument, which is what makes a CPU path possible even though a GPU is recommended. Whether the detector follows the same device argument, and what the class returns for a query that matches nothing, are not shown here; the None format is described as part of the model output, and mapping that onto the worker's return value is something to check in vlx_seek_worker.py before you build error handling around it.
For an interactive look, the project points at om-agent.com, and the README's contact address for technical support and partnerships is [email protected], alongside Discord and WeChat community links. The project metadata shows 1,327 stars, 190 forks and 3 open issues, with the last push to main on 2026-09-28, Apache-2.0 licensed.
Editorial conclusion
VLX-Seek is worth a look if your problem is open-vocabulary grounding on embodied imagery where a wrong box is worse than no box, because the None format and hard-negative training target exactly that failure. Check the sizing before you plan around it, since the 0.6B and 3B members of the planned family are not released and only the 10B model has published weights and inference code. Budget for a GPU install rather than an edge deployment, because flash_attn and a CUDA-enabled PyTorch are pinned and Linux is the primary tested platform. And clone the repository before the first run, since the model architecture ships in a local package that the download cannot substitute for.
Frequently asked questions
How does VLX-Seek locate objects instead of generating bounding boxes?
It reformulates localization as region retrieval and region reference. Candidate regions are encoded as addressable region tokens, and the language model answers by selecting, comparing and referring to those regions rather than emitting coordinate numbers.
Which VLX-Seek model sizes have released weights?
VLX-Seek 1.5 is planned as a family of 0.6B, 3B and 10B models, and only the 10B has released inference code and weights, as omlab/VLX-Seek-1.5-10B on Hugging Face, published on 2026-07-23.
What happens when VLX-Seek is asked for a target that is not present?
Open-vocabulary rejection is one of the four fine-grained perception requirements. Version 1.5 adds hard-negative rejection training and an explicit None format so the model can decline a requested target instead of hallucinating a box.
What does VLX-Seek need installed before the first run?
Clone the repository and install requirements.txt first, because the model architecture comes from the local vlx_seek package even when the weights are loaded from Hugging Face. You also need Python 3.10 or newer, a CUDA-enabled PyTorch build matching your system, and Linux is the primary tested platform.
Does VLX-Seek download a region detector checkpoint too?
Yes, for detection, grounding and other proposal-dependent tasks the recommended region detector checkpoint is fetched from Hugging Face into resources/ when needed. Use --detector-checkpoint to change the path, or pass --bbox-list to skip the detector entirely.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/om-ai-lab-vlx-seek)Star history chart for your README
[](https://hysenlabs.com/projects/om-ai-lab-vlx-seek)Was this useful?