RisingWave: what one system gives up when it absorbs ingest, compute, serving and storage
Event streaming platform for agentic AI. Continuously ingest, transform, and serve event streams in real time, at scale.
At a glance
- What is it?
- RisingWave is a Rust event streaming platform, Apache 2.0 licensed, that folds Debezium, Kafka, Flink and a serving database into a single system and adds an Apache Iceberg layer on top. Its headline latency numbers are real claims but they are conditioned on an object storage design and a local disk cache, and its only install command on the front page is a curl pipe.
- Who is it for?
- RisingWave makes sense when one team owns the whole pipeline and object storage is already available, because collapsing four systems into one removes real operational hops. It does not make sense if your latency target has no local SSD or EBS cache behind it, or if an anonymous telemetry call on first install is not acceptable to your procurement process.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
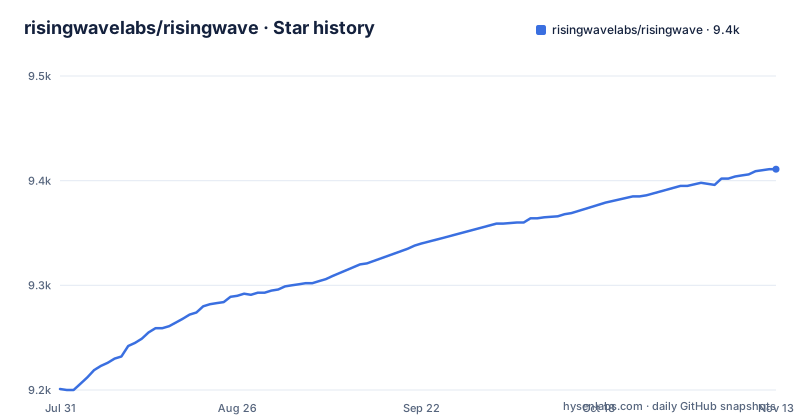
- risingwavelabs/risingwave9,411 ★ · +210
| Repository | 2026-07-31 | 2026-11-13 |
|---|---|---|
| risingwavelabs/risingwave | 9.2k | 9.4k |
210 Stars in the last 105 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The only install command is a curl pipe with no version argument
The entire install surface on the front page is one line:
curl -L https://risingwave.com/sh | shEverything else is deferred to the quick start guide, which is where Docker, Kubernetes and other options live. That makes this the fastest route in and the least controllable one. There is no version argument on the command, the script itself lives outside the repository, and the page names no checksum, mirror or pinned artifact, so nothing about what you just executed was reviewable beforehand. That trade is fine for a laptop trial and wrong for a build agent, an air gapped host or a regulated environment, all of which need the guide rather than the pipe. The named self hosted routes are Docker Compose, Kubernetes with Helm and Kubernetes with Operator, and the managed option is RisingWave Cloud.
The 10-20 ms p99 claim depends on a cache you have to add
Two latency figures appear in the serving section: end to end freshness under 100 ms and query results served at 10 to 20 ms p99. The design section ties the p99 figure to an elastic disk cache that pins hot data on local SSD or EBS for latency-sensitive workloads. Without that tier, hot state comes from object storage instead, and the page quotes no replacement number for that case. The two figures also belong to different layers. Freshness describes ingest through incremental computation, where only affected results are recomputed when upstream data changes. The p99 figure describes queries against the internal row store. Keeping them apart matters when something goes slow, because a join against reference data that is not pinned is a serving problem, and no amount of ingest tuning moves it.
Object storage as system of record moves cost, not work
Internal state, tables and materialized views are stored in object storage, S3 or equivalent, which the project puts at roughly 100x cheaper than RAM. Two things follow from that single choice. Elastic scaling works without data rebalancing, and failure recovery is described as taking seconds, because the durable copy was never inside the process that has to restart. The same choice also means three separate failure domains: the serving tier, the disk cache and the object store. A deployment that skips the local SSD or EBS cache has relocated its latency problem rather than removed it. The page does not describe a supported mode in which object storage alone carries the quoted p99, so treat the cache as part of the design rather than as an optional extra.
Two query layers means two engines, not one
RisingWave writes to Apache Iceberg tables, hosts the Iceberg REST catalog directly, and handles table maintenance, namely compaction, small file optimization and snapshot cleanup, without external tooling. Queries against that layer run through Apache DataFusion, a vectorized engine, and because Iceberg is an open format the data stays readable by Spark, Trino and DuckDB. The page is explicit that the row store and the Iceberg layer serve different purposes, the row store for low latency serving and Iceberg for durable open format storage and analytical queries. That split is the detail to hold on to: quoted p99 numbers describe the row store path, and anything handed to Spark, Trino or DuckDB has left the system and re entered through the file format, where no latency claim is made.
Postgres wire protocol is the whole client surface, and the only one named
The client path described for humans is the PostgreSQL wire protocol. RisingWave connects with psql, JDBC and any Postgres compatible tooling, and for agents it ships an MCP server, a CLI and Skills so an agent can query and operate the system without custom integration work. The upside is that anything already speaking Postgres can talk to it, and there is no proprietary API to learn first. The limit is what the page actually promises: it claims protocol connectivity, and it describes its own surface as SQL over streams and tables with materialized views updated incrementally. It does not claim compatibility with any particular Postgres feature set, so a tool that opens a connection is not the same as a tool that works unchanged against every setting.
Telemetry runs on first install, and the opt out is a separate page
RisingWave uses Scarf for anonymized installation analytics and collects anonymous usage statistics to improve the product. Both can be opted out, and the details live in a dedicated telemetry page rather than in the install instructions. Anonymized is a claim stated by the project, not a property you can inspect in the one line installer. For a company that runs a procurement review, the ordering is the whole issue: the first run of the curl pipe is when an outbound call happens, and the switch that stops it is documented one page away from the command. Baking the opt out into a container image is therefore a deliberate step, not something the default deployment gives you.
The workspace is more than sixty crates, and risedev is undocumented up front
The Cargo.toml workspace enumerates more than sixty members, and that list maps the system better than the prose does: src/meta, src/frontend, src/compute, src/stream, a src/storage with compactor, hummock_sdk and backup subcrates, plus src/connector, src/ctl, src/risedevtool, src/java_binding and src/jni_core. The same list exposes the testing surface, with src/tests/sqlsmith, src/tests/simulation and src/tests/regress, a bench crate, and spill and heap profiling crates under src/stream and src/common. Beside it sit risedev and risedev.yml, Makefile.toml, rust-toolchain, and directories for dashboard, java, grafana, ci, docker and standalone. None of that local tooling is explained on the front page, which sends contributors to the developer guide instead.
Editorial conclusion
RisingWave makes sense when one team owns the whole pipeline and object storage is already available, because collapsing four systems into one removes real operational hops. It does not make sense if your latency target has no local SSD or EBS cache behind it, or if an anonymous telemetry call on first install is not acceptable to your procurement process. Before committing, read the quick start guide for the Docker and Kubernetes paths, confirm what your agents will use out of the box, and turn the telemetry opt out on before the first run.
Frequently asked questions
what is risingwave
An event streaming platform for agentic AI, written in Rust and licensed under Apache 2.0. It ingests from webhooks, database change data, brokers and storage, computes incrementally, serves results at low latency over SQL, and writes long term data to Apache Iceberg tables.
Is RisingWave open source?
Yes, under the Apache License 2.0, with the LICENSE file at the repository root. The source is public on the main branch, and RisingWave Cloud is offered separately as the managed option.
What are the key differences between RisingWave and Apache Flink?
RisingWave frames the difference by scope rather than by feature. It says the standard approach chains Debezium for change data capture, Kafka for transport, Flink for processing and a database for serving, and that RisingWave replaces that whole stack, ingest, process, serve and store, with each hop removed also removing latency and operational overhead. No feature level comparison with Flink is given.
risingwave vs kafka
RisingWave lists Kafka as one of the event stream sources it ingests from, alongside Pulsar and Kinesis. At the same time it names Kafka as part of the traditional stack it replaces, so whether you keep Kafka is a deployment decision the page does not settle.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/risingwavelabs-risingwave)Star history chart for your README
[](https://hysenlabs.com/projects/risingwavelabs-risingwave)Was this useful?