OpenDataLoader PDF spawns a JVM per convert() call
OpenDataLoader PDF parses PDFs into Markdown, JSON with bounding boxes, and HTML for AI and RAG pipelines, with OCR for 80+ languages in its hybrid AI mode.
At a glance
- What is it?
- An Apache-2.0 Java PDF parser with Python, Node and Java bindings that turns digital and scanned files into Markdown, JSON with bounding boxes, HTML, or a Tagged PDF. The free core stops at Tagging, PDF/UA export is a paid add-on, and the batch API is the one detail that decides throughput.
- Who is it for?
- OpenDataLoader PDF suits a team that needs bounding boxes and reading order for citations, or needs untagged files Tagging for screen readers, and that can accept a Java runtime and a batch call rather than a single-file API. It does not suit a pipeline that must stay entirely in local deterministic mode and still wants OCR and borderless tables, because those are tied to hybrid mode, nor a team that needs PDF/UA-1 or PDF/UA-2 output from the free code.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
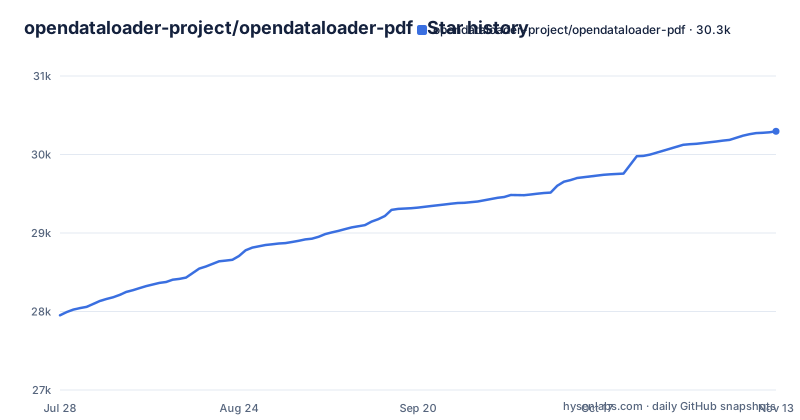
Star history
- opendataloader-project/opendataloader-pdf30,296 ★ · +2,344
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| opendataloader-project/opendataloader-pdf | 28k | 30.3k |
2,344 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One convert() call, one JVM, and that is the whole batch
The quick start is three lines, and one of them carries a warning that the surrounding text states more plainly than the example does. Each convert() call spawns a JVM process, so repeated calls are slow. The documented shape is therefore a single call with a list:
import opendataloader_pdf

opendataloader_pdf.convert(
    input_path=["file1.pdf", "file2.pdf", "folder/"],
    output_dir="output/",
    format="markdown,json"
)
The input_path takes files and a directory in the same list, and format takes a comma-separated set, here markdown and json in one pass. For a RAG pipeline this is the decision that matters more than any accuracy number: a Python loop that hands one path at a time to convert() pays a JVM start per document, and a directory entry pays one for the batch. The only way to size the overhead is to time one call with the real batch inside it.
An AI-AGENT-SUMMARY block sits above the README
The first thing in the file is an HTML comment named AI-AGENT-SUMMARY, and it is structured data rather than prose. It names a category, the Apache-2.0 license, an input of PDF files that are digital, scanned or tagged, outputs of Markdown, JSON with bounding boxes, HTML, Tagged PDF and PDF/UA for enterprise, SDKs for Python, Node.js and Java, and a requirement of Java 11 or later. It then carries a pricing line, a benchmark line and a list of key differentiators.
That block is genuinely useful, since an agent can read it without parsing a README, and it is also a duplication risk. Every number in it appears again in the prose below, and the two are edited separately. A reader who treats the summary as the spec and the tables as detail has no way to know which one the maintainers update first.
The pricing line is the part with teeth. It splits the project into an open-source core covering data extraction, layout analysis and auto-tagging to Tagged PDF, and an enterprise add-on for PDF/UA export and an accessibility studio. That boundary is stated in the summary, in the accessibility bullet list and in the capability table, which is the clearest evidence that the split is deliberate rather than a roadmap item.
The free core ends at Tagging, not at compliance
The accessibility story is split across two tiers, and the split lands exactly where a compliance deadline lands. Auto-tagging an untagged PDF into a Tagged PDF is in the free Apache-2.0 core, and the project claims to be the first open-source tool to generate Tagged PDFs end to end. Converting that result into PDF/UA-1 or PDF/UA-2 is the enterprise add-on, along with a visual accessibility studio.
So the pipeline a procurement team is asked to fund has a free first half and a paid last half. The framing in the README is explicit about it: auto-tagging generates the Tagged PDF, and PDF/UA export is the final step. For PDF/UA export within this product, the project lists an enterprise add-on. Teams should assess applicable accessibility requirements and validate the resulting documents for their intended use.
The alternative being argued against is doing it by hand, and the README puts manual remediation at $50 to $200 per document. That is the project's own figure, not an independent one, and no method is given for it. Either way the comparison is between a batch tool plus a licence and a person per file.
Local mode is deterministic, hybrid mode routes pages to an AI backend
Two technologies do the work, and picking one changes the character of the output. Local mode is deterministic: no model, repeatable text, and the summary block claims 0.015 seconds per page for it. Hybrid mode sends the complex pages to an AI backend, and the project's own figures for that path are 0.907 overall extraction accuracy and 0.928 on tables, measured across 200 real-world PDFs that include multi-column layouts and scientific papers.
The README links to a dedicated hybrid mode section, which is the place to check what the AI backend is and where it runs before adopting it.
Anyone who intends to rely on the number should open the benchmarks page rather than quote 0.907 from a summary comment.
OCR, borderless tables and formulas all belong to hybrid mode
Read the tier column in the capability table rather than the supported column, because that is where the real limits are. Free and local: correct reading order, a bounding box for every element, simple bordered table extraction, heading hierarchy, list detection, image extraction with coordinates, Tagged PDF structure extraction, header, footer and watermark filtering. Free but hybrid: complex and borderless tables, AI descriptions of charts and images, OCR, and LaTeX formula extraction.
The consequences stack. A pipeline that runs local mode for determinism has no OCR, so a scanned document produces nothing useful, and the 80-plus language OCR and the 300 DPI handling for poor scans are unavailable to it. It also has no borderless tables. A reader who sees every row marked Yes and skips the tier column will design a pipeline that fails on its first scan.
Two rows say No outright. Word, Excel and PowerPoint files are out of scope, so an office-heavy corpus needs a different tool upstream. A GPU is not required, which is the row that makes local mode viable on a locked-down or air-gapped machine.
options.json and schema.json are dumped from a Java CLI build
The repository is a monorepo with java/, node/, python/, samples/, examples/, skills/ and verification/ directories, and the root package.json is a private pnpm workspace that pins packageManager [email protected] and requires Node 22.13 or later. The two JSON files that describe the tool's options are not hand-written. The export-options script builds the Java CLI first and then runs it:
npm run build-java && java -Djava.awt.headless=true -Dapple.awt.UIElement=true -jar java/opendataloader-pdf-cli/target/opendataloader-pdf-cli-[0-9]*.jar --export-options > options.jsongenerate-options.mjs then turns that dump into options.json, and generate-schema.mjs produces schema.json, with sync-options and sync-schema wiring the pairs together. Two things follow. A Python user who never touches Node still inherits an option schema produced by a Java toolchain, and changing an option means editing the Java side and re-running the export. The command sets Java's AWT headless mode, which is relevant when building or running in a container without a display.
Three patch releases in a week, and the tag lags the branch
The release list shows v2.5.15 on 2026-10-22, v2.5.16 on 2026-10-27 and v2.5.17 on 2026-10-30, all patch-level moves on the same minor line. The last push was on 2026-10-30, the same day as the newest tag. For a reader pinning a version, the version string belongs in whatever you log about a conversion run.
The licensing files at the root are worth a look for the same reason. Beyond LICENSE there is a LICENSE_TEMPLATE, a NOTICE file and a THIRD_PARTY directory, which is the arrangement Apache-2.0 projects use when they redistribute components. The project lists the core under Apache-2.0 and PDF/UA export as an enterprise feature. Review the applicable licence and third-party notices for the components you actually use and redistribute.
Editorial conclusion
OpenDataLoader PDF suits a team that needs bounding boxes and reading order for citations, or needs untagged files Tagging for screen readers, and that can accept a Java runtime and a batch call rather than a single-file API. It does not suit a pipeline that must stay entirely in local deterministic mode and still wants OCR and borderless tables, because those are tied to hybrid mode, nor a team that needs PDF/UA-1 or PDF/UA-2 output from the free code. Before adopting, measure the one convert() call with your whole batch in it, then confirm which of OCR, tables, formulas and chart descriptions you can live without if the AI backend is off the table.
Frequently asked questions
How do I use OpenDataLoader PDF?
Install the Python package with `pip install -U opendataloader-pdf`, then call `opendataloader_pdf.convert()` once with a list of files or a folder, an output directory and a format such as markdown,json. Java 11 or later and Python 3.11 or later are required, and the README suggests running `java -version` first and installing a JDK 11 from Adoptium if it is missing.
Does OpenDataLoader PDF need Java installed?
Yes. The requirement is listed as Java 11 or later plus Python 3.11 or later, and the quick start tells you to run `java -version` before anything else. The parser itself is Java, which is also why each convert() call spawns a JVM process.
Is PDF/UA export part of the free OpenDataLoader PDF?
No. Auto-tagging an untagged PDF into a Tagged PDF is in the free Apache-2.0 core, but PDF/UA-1 and PDF/UA-2 export and the visual accessibility studio are the enterprise add-on. The project's own description says auto-tagging generates the Tagged PDF and PDF/UA export is the final step.
Can OpenDataLoader PDF run without a GPU?
Yes. The capability table has a limitations row for GPU required and marks it No. That said, the hybrid features, which include OCR, complex and borderless tables, formula extraction and AI chart descriptions, depend on hybrid mode's AI backend.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/opendataloader-project-opendataloader-pdf)Star history chart for your README
[](https://hysenlabs.com/projects/opendataloader-project-opendataloader-pdf)Was this useful?