OpenSearch Dashboards runs two version lines and pins a 2023 browser in its image
Open source visualization dashboards for OpenSearch. OpenSearch Dashboards gives you data visualization tools to improve and automate business intelligence and support data-driven decision-making and strategic planning.
At a glance
- What is it?
- The visualization panel for the OpenSearch search engine, and a repository whose README is five sections of process links rather than product description. The engineering signals are in the manifests: a package manager pinned to a classic major, three separate toolchain version files, a targeted clean list instead of a blanket one, and an image whose browser version has to match a driver version in the source.
- Who is it for?
- Adopt this if your data is already in OpenSearch and you want the first-party panel rather than assembling your own. Nothing in the repository argues otherwise; the framing throughout is that the tool exists so you need not build one.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
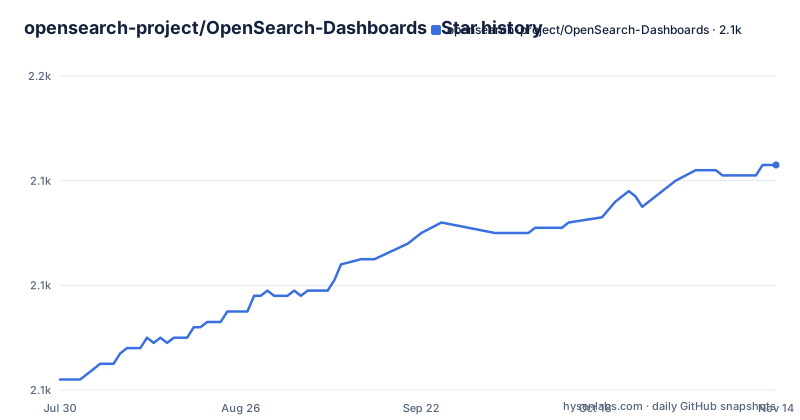
Star history
- opensearch-project/OpenSearch-Dashboards2,143 ★ · +41
| Repository | 2026-07-30 | 2026-11-14 |
|---|---|---|
| opensearch-project/OpenSearch-Dashboards | 2.1k | 2.1k |
41 Stars in the last 107 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two version lines are shipping at once
The release list interleaves two different numbering schemes, and that is the first thing to notice about this project.
Three releases are visible. The newest is on the three series. The middle one is on the two series, with a version number in the twenties, and it is dated between the two three-series releases. The oldest is also on the three series.
So the project is running a current line and an older maintenance line in parallel, with the older line still taking releases months after a newer one shipped. That is normal for infrastructure software with a large installed base, and it is exactly the situation where the newest version number is not necessarily the one you want.
There is a third number as well. The manifest on the default branch declares a version one step ahead of the newest published release, which is normal for a branch that is working toward the next tag.
So there are three numbers to reconcile before you pin anything: which line you want, which release of that line, and whether you are tracking the branch or a tag.
The Node version is enforced at install time, not assumed
The manifest pins the package manager to an exact version, and it is a classic major rather than a current one.
Three separate files at the repository root record toolchain versions for different tools: one for version managers, one for the runtime itself, and one for the browser support targets. That is not redundancy, it is three consumers that each need the answer in a different format, and having them in one place would have been worse.
Then there is the enforcement. Every script in the manifest is routed through a shared node shim rather than invoked directly, including the pre-install and post-install hooks, and the pre-install hook runs a dedicated check script.
So a mismatched runtime is caught before dependencies are installed rather than as a confusing failure three minutes into a build. It does mean every script invocation pays for the shim, which is the trade this project made.
The clean configuration follows the same philosophy. Rather than deleting broadly, the manifest enumerates the directories that actually accumulate: build output, an optimisation data directory, built assets, a linter cache, downloaded runtime binaries, and per-package build and cache directories.
The image pins a browser release to match a driver in the source
The container definition is where the pinning becomes concrete, and one comment explains most of it.
The base runtime is pinned to an exact patch-level version. Then the image installs a desktop environment: a virtual frame buffer, the GTK and X11 stacks, font packages, an indicator library, and a legacy configuration daemon. For a server-side panel that is an odd list, and it is there because the package bundles a browser for certain features.
A second build argument pins a Chrome package to an exact version, and the comment above it says the reason: it must match the chromedriver version in the manifest. The comment then points at a third-party distribution index as the place to find valid version pairs, because neither the image nor the manifest can be the authority on which browser and driver versions go together.
The image also installs a cloud command line tool and a small set of utilities, then creates an unprivileged system user with its own home directory and switches to it for the rest of the build. Ending as a non-root user is the part worth copying.
The cost is that the browser version is years behind the runtime version next to it, and any security update to that browser has to be coordinated with a driver version in the source.
Continuous integration runs through two systems at once
The repository root contains a Jenkins build definition and a directory of hosted workflow files, which means both a self-hosted server and a hosted workflow service are in use.
That is a normal consequence of corporate sponsorship, where part of the build runs on internal infrastructure, but it has a cost for a contributor: the authoritative gate is not obvious from looking at the tree. The README does not say which one blocks a merge, and neither does the contribution guide in the visible text.
The testing story is similarly split across four mechanisms, and each has its own entry point in the manifest. Unit tests with coverage reporting, and a continuous-integration variant of the same. A separate backward-compatibility path with its own runner script, because a panel that stores saved dashboards cannot break its own file format without someone's existing setup breaking. An end-to-end browser suite with its own configuration file and directory. And a link checker, which has its own ignore file because documentation links rot.
The link checker and the browser baselines are the two that most projects of this size skip, and both are here. A performance configuration with stored baseline files means visual regressions are caught, which is a real safeguard for a panel whose entire output is pixels.
Agent configuration directories sit beside a codebase that predates them
Three things at the repository root are worth grouping together.
There is a configuration directory for one assistant, a top-level instruction file for another, and a configuration directory for a third tool. All three are committed, alongside the human-facing contributor and developer guides.
For a project of this age that is unremarkable in itself; assistants are part of the toolchain now, and committing their configuration makes behaviour reproducible across a team. What is notable is that they sit next to a repository that also has a machine-readable telemetry configuration, a commercial dependency-scanning configuration, and two changelog directories with different names and evidently different purposes.
So the root is doing three jobs at once: toolchain configuration for humans, toolchain configuration for machines, and the governance documents that a large foundation-style project accumulates.
That is not a criticism. It is a sign of what the project is: a mature, process-heavy repository where the README has been reduced to pointing at the process documents, and everything interesting is in the manifests.
The code of conduct carries a corporate name and a corporate contact
The conduct section names a specific company's code of conduct rather than the project's own, and gives a contact address at that company's domain, linking a FAQ hosted on that company's site.
That is worth naming plainly because it answers a practical question: who does the escalation path actually run through. For a foundation-style project the answer is usually either the foundation or a rotating maintainer committee, and here it is a corporate entity. That is a legitimate arrangement and plenty of large open source projects do it.
Alongside it the repository carries separate documents for maintainer responsibilities, for triage, for release management, for testing and for security. Five process documents plus a communications guide is a lot of governance for a panel, and it is the reason the README can be as short as it is: the prose is in those files rather than on the front page.
Licensing is the conventional part. An Apache 2.0 licence file at the root, and a separate notice file that the README points to for copyright details, which is the correct arrangement for an Apache 2.0 project and a small sign the legal side is handled properly.
The examples directory documents features by task, not by product area
There is a directory of worked examples, and the way it is organised is the closest thing in this repository to a feature list.
Rather than folders per menu item, the examples are named after the thing you are trying to do. There is one for an application performance topology view, one for a document fetcher, several for the two different embedding paths, one for expressions, several for search, one for a star schema data source, one for multiple data sources, and a group for the newer state-management and interface-action work: state containers, state management, interface actions, an explorer for those actions, and URL generators with their own explorer.
Two of the embedding example directories have a full explorer alongside them, which suggests those features have a standalone sandbox you can play with rather than only documentation.
That structure is a reasonable choice for a panel whose feature set is large and whose users arrive with a task rather than a mental model of the menu. The cost is that it tells you what the panel can do indirectly, and the README itself will not tell you at all.
Editorial conclusion
Adopt this if your data is already in OpenSearch and you want the first-party panel rather than assembling your own. Nothing in the repository argues otherwise; the framing throughout is that the tool exists so you need not build one. Two things to check before you pin a version. Releases are landing on a current line and an older maintenance line at the same time, so read which line you are installing rather than assuming the newest number is the only one. And the build environment is tightly pinned, which is good for reproducibility and awkward for a laptop, since the package manager is a classic major and the image fixes a browser release from years back.
Frequently asked questions
What are OpenSearch dashboards?
OpenSearch Dashboards is an open-source data visualization tool designed to work with OpenSearch. The page describes it as giving visualization tools to improve and automate business intelligence and to support data-driven decision-making and strategic planning.
what is opensearch dashboards
It is the browser-based analytics and search dashboard for OpenSearch, published under the package name opensearch-dashboards and versioned on its own schedule rather than in step with the search engine. The manifest on the default branch is marked private and carries its own version and a build number.
Which versions of OpenSearch Dashboards are supported?
Releases appear on two lines at once: a current three series and an older two series that still took a release months after the newer line shipped. The manifest on the default branch declares a version one step ahead of the newest published release, so three numbers need reconciling before pinning.
What does OpenSearch Dashboards need to build?
An exact package manager version, which is a classic major, plus three separate toolchain version files at the root for version managers, the runtime and browser targets. Every script is routed through a shared runtime shim, and a check script runs at install time to catch a mismatched runtime early.
How does OpenSearch Dashboards test itself?
Through four mechanisms with separate entry points: unit tests with coverage reporting, a backward-compatibility path with its own runner script, an end-to-end browser suite with its own configuration, and a link checker with an ignore file. There is also a performance configuration with stored baseline files, so visual regressions are caught.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/opensearch-project-opensearch-dashboards)Star history chart for your README
[](https://hysenlabs.com/projects/opensearch-project-opensearch-dashboards)Was this useful?