OpenGrok: a source browser whose version number tells you whether to reindex
OpenGrok is a fast and usable source code search and cross reference engine, written in Java
At a glance
- What is it?
- OpenGrok searches and cross-references a source tree from Java, and its most useful section is not about features but about upgrade cost: major, minor and micro each mean a different amount of work.
- Who is it for?
- Adopt OpenGrok when you have a tree large enough that grep stops working and you want cross references over it, and you can live with setup that lives in a wiki rather than in the repository. Do not adopt it on the strength of the speed claim, because no index time or query figure appears anywhere in the project documentation.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
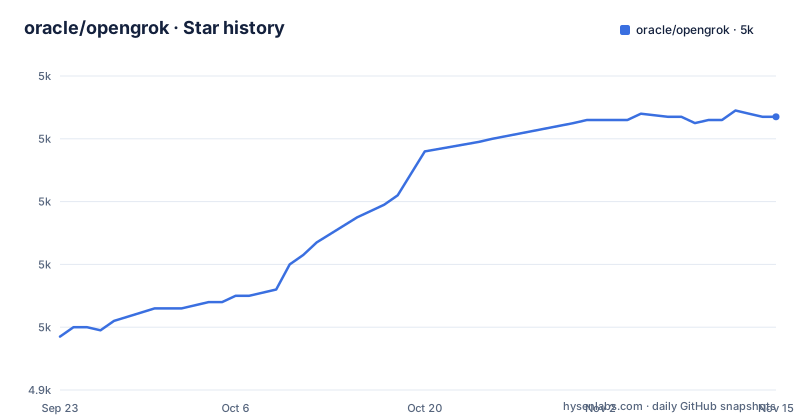
- oracle/opengrok5,027 ★ · +70
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| oracle/opengrok | 5k | 5k |
70 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The README hands setup to the wiki and holds no commands
OpenGrok searches, cross-references and navigates a source tree. It understands various program file formats and version control histories of many source code management systems, and it is written in Java. That is the entire introduction, three sentences and a link to the official page at https://oracle.github.io/opengrok/.
The installation section is one sentence and one link: see the How-to-setup-OpenGrok page in the project wiki. So the repository holds no clone step, no prerequisite list and no first command. Someone who clones the project looking for a getting started path finds three other links instead, to the developer intro and developer wiki pages, to docker/README.md for the container route, and to CONTRIBUTING.md.
That arrangement has a cost. Setup knowledge lives in the wiki, which is not part of this repository, so it can drift away from the code without a pull request here to catch it. Anyone installing OpenGrok is following instructions held somewhere other than the thing they downloaded.
major.minor.micro decides between a redeploy and a full reindex
OpenGrok uses semantic versioning, and the README says exactly what each component of the number costs you. A major change is a backwards incompatible update that requires a full reindex as well as configuration changes. A minor change means a full clean reindex of your repositories is needed, for instance when the index format has changed. A micro change means redeploy the web application.
That turns a version string into an operations plan. A micro bump touches only the deployed web app. A minor bump means rebuilding every index from scratch. A major bump means reindexing and changing configuration, and moving backward is only possible within the micro version, so the decision to step up is nearly one way.
The published releases sit three deep in one range: 1.14.18 on 2026-09-02, 1.14.19 on 2026-09-14 and 1.14.20 on 2026-10-12. Read through the documented scheme, each is a micro update, so each should be a redeploy of the web application with no reindex, provided your index was built by an earlier 1.14.x in the first place.
opengrok-indexer and opengrok-web are separate Maven modules
The layout splits the work in two and hangs five other directories beside them:
opengrok-indexer/
opengrok-web/
plugins/
suggester/
distribution/
tools/
dev/
The module names give the split: opengrok-indexer for building the index, opengrok-web for the application you deploy. plugins/, suggester/, distribution/, tools/ and dev/ sit around those two, and a comment in the Dockerfile describes distribution and tools as the modules with no dependencies worth caching.
Maven drives all of it, and through the wrapper rather than a system install. The root holds pom.xml, mvnw, mvnw.cmd and a .mvn/ directory, so a build does not need Maven on the PATH. That matters for CI images and for anyone reproducing a build on a machine they do not control: the wrapper pins what the project pinned, and the .mvn directory travels with the checkout.
The container build skips tests and checkstyle to warm the Maven cache
The Dockerfile is the most concrete document in the repository, and it explains itself as it goes. It starts from ubuntu:jammy, installs openjdk-21-jdk with python3 and python3-venv, then copies the parent pom and the module poms before any source, so dependency downloads can be cached in their own layer:
COPY pom.xml /mvn/
COPY mvnw /mvn/
COPY .mvn /mvn/.mvn
Two modules are dropped from that throwaway build with a sed edit, and the cache is filled by a dummy package step:
RUN ./mvnw -DskipTests -Dcheckstyle.skip -Dmaven.antrun.skip packageOnly after that does the source get copied in and the real build run:
RUN /mvn/mvnw -DskipTests=true -Dmaven.javadoc.skip=true -B -V packageTwo things follow for anyone treating the image as a trusted build. Tests are off for both builds and checkstyle is off for the dependency-caching build, so a green image build says nothing about the tests. And the tarball is chosen with cp `ls -t distribution/target/*.tar.gz | head -1`, which takes whatever archive in that directory is newest rather than a version you named, with the project version written out separately by mvnw help:evaluate so the tools can report it. The runtime stage is FROM tomcat:10.1.60-jdk21.
openapi.yaml describes the API and nothing pins it
Three files at the root describe how the thing runs rather than what it does. openapi.yaml is an API description. logging.properties configures logging for the Java side. sonar-project.properties feeds the SonarCloud new code summary badge at the top of the README, and the dashboard badge points at the same project, org.opengrok:opengrok-top.
What none of them settles is whether any of it stays put. The README does not describe the endpoints in openapi.yaml, does not say which release introduced them, and gives no compatibility policy for clients. Treat the YAML as a description of the release you are running rather than a promise about the next one. The major.minor.micro rules cover the index and the web application, and say nothing at all about API stability, so a client written against one release has no documented upgrade path to the next.
Six extra licence texts sit next to LICENSE.txt
The licence arrangement explains why the repository root looks the way it does. LICENSE.txt holds the licence text, the badge in the README points at the Common Development and Distribution License 1.0 on opensource.org, and the copyright line reads 2006, 2025 Oracle and/or its affiliates.
Beside LICENSE.txt sit LICENSE-adaic.org.txt, LICENSE-eclipse.txt, LICENSE-ecma.txt, LICENSE-mandoc.txt, LICENSE-ruby.txt and LICENSE-scala.txt, with NOTICE.txt above them. Those files record the terms of code that came from other projects, which is ordinary for a codebase of this age, and they make a per-file audit possible rather than guesswork. What they do not do is give a quick scan one answer to return: a tool that reads the root licence alone finds six extra texts to reconcile. Contributors are asked to read CONTRIBUTING.md before a pull request, and vulnerability reports go to the process in SECURITY.md rather than to a public issue.
Conceived at Sun Microsystems, with releases through September 2026
The project was originally conceived at Sun Microsystems by Chandan B.N. The copyright now sits with Oracle, the README closes on a support badge, and contact runs through GitHub Discussions. The last push was on 2026-10-26, after release 1.14.20 on 2026-10-12.
Its own claim is a fast and usable source code search and cross reference engine, and the heading calls it a wicked fast source browser. No figure backs either phrase: the README gives no index time, no query latency and no hardware description. The README carries a GitHub Actions badge. Judge the speed on your own tree, and remember that the index format is exactly what the minor component of the version number is protecting.
Editorial conclusion
Adopt OpenGrok when you have a tree large enough that grep stops working and you want cross references over it, and you can live with setup that lives in a wiki rather than in the repository. Do not adopt it on the strength of the speed claim, because no index time or query figure appears anywhere in the project documentation. Before deploying, check two things: that your current index was built by a 1.14.x release, and that docker/README.md matches the tomcat:10.1.60-jdk21 runtime in the Dockerfile if you plan to run the container rather than the wiki path.
Frequently asked questions
What is OpenGrok used for?
It is a source code search and cross reference engine written in Java, for searching, cross-referencing and navigating a source tree. It understands various program file formats and version control histories of many source code management systems, and the official page is at https://oracle.github.io/opengrok/.
Who owns OpenGrok?
The copyright is held by Oracle and/or its affiliates, covering 2006 and 2025. The project was originally conceived at Sun Microsystems by Chandan B.N., and the contact route is GitHub Discussions.
Is OpenGrok free?
It is open source. The licence badge in the README points at the Common Development and Distribution License 1.0, and the repository root carries LICENSE.txt with six further licence texts for code borrowed from other projects.
how to install opengrok
The README does not hold the steps. Its installation section points at the How-to-setup-OpenGrok page in the project wiki, with a separate route for running OpenGrok as a Docker container described in docker/README.md.
how to setup opengrok on ubuntu
The repository has no Ubuntu-specific setup steps; its Dockerfile build stage starts from ubuntu:jammy with openjdk-21-jdk, python3 and python3-venv, builds with the Maven wrapper, and ends on a tomcat:10.1.60-jdk21 runtime. The full setup instructions still live in the wiki page the README links.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oracle-opengrok)Star history chart for your README
[](https://hysenlabs.com/projects/oracle-opengrok)Was this useful?