Ostris AI Toolkit: diffusion training from a browser, a launcher script or a container
The ultimate training toolkit for finetuning diffusion models
At a glance
- What is it?
- One training suite covering FLUX and Qwen image models, Wan and LTX video, Ace Step and YuE2 audio, with a manager-based installer, per-platform launchers and a compose file. The model coverage is the strongest argument for it; the lack of GitHub releases is what you inherit with it.
- Who is it for?
- Adopt it if you are fine-tuning FLUX, Qwen-Image, Wan or Ace Step on a single NVIDIA machine and are willing to read the config/ and jobs/ directories yourself, because that is where the real contract lives. Skip it if you need a released version to pin.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
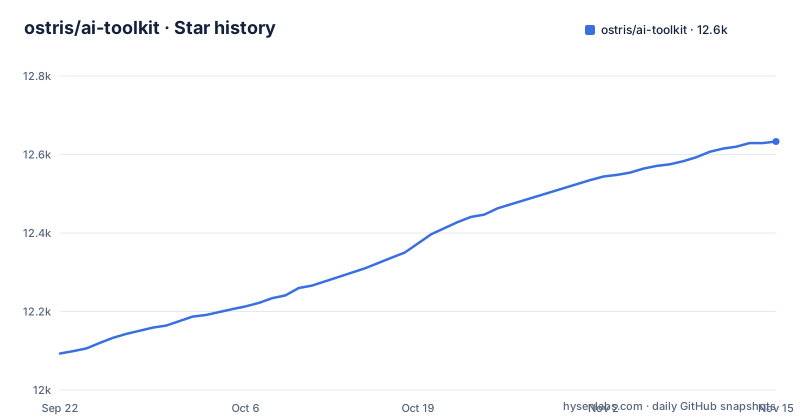
- ostris/ai-toolkit12,633 ★ · +540
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| ostris/ai-toolkit | 12.1k | 12.6k |
540 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four model families share one jobs/ and config/ layout
AI Toolkit is a training suite for diffusion models, and its argument is coverage. The model list runs from FLUX.1 and FLUX.2, including the FLUX.2-klein-base-4B and 9B variants, through Flex.1, Chroma, Qwen-Image, HiDream I1, SDXL, Krea 2, Anima and a long tail of newer releases, then switches to a separate instruction and edit list, a video list covering Wan 2.1 and 2.2 plus LTX-2 and MiniMax-H3, an audio list with Ace Step 1.5 and YuE2, and one LLM entry, Qwen2.5-Omni-7B. Coverage is the argument, so check the list before anything else: an entry missing there is a run you cannot start here.
The layout underneath is conventional for this kind of project. `toolkit/` holds the code, `jobs/` the training jobs, `config/` the user configuration, `extensions/` and `extensions_built_in/` a split between community and bundled plugins, `ui/` the web front end, and `manager/` the installer. An `output/` directory sits beside them, so trained weights land inside the checkout rather than somewhere on your home drive, and `docker/`, `notebooks/` and `testing/` round out the top level.
The manager skips updates for files you have edited
The README's installation section starts with installing through the AI Toolkit Manager, which lives in the `manager/` directory. The README describes the toolkit as runnable either as a GUI or as a CLI. The README describes the manager as experimental: it detects hardware, prepares a local environment, checks for updates on launch and skips an update with a warning if local files have been modified. It then starts the interface at localhost:8675.
run_windows.bat and run_mac.zsh are the same trainer per platform
The repository includes `run.py`, `run_linux.sh`, `run_mac.zsh`, `run_windows.bat` and `run_modal.py`. The README presents the platform-specific shell and batch scripts as entry points to the experimental manager, which prepares the environment and starts the UI. `run.py` is a separate CLI entry point; consult the current documentation for the workflow you intend to use.
`run_modal.py` and `spark_requirements.txt` point at hosted and cluster-shaped variants; anyone shopping for a rented GPU path should read those files.
docker-compose.yml publishes 8675 and reserves only NVIDIA devices
Container use goes through the checked-in compose file, which names the published image, binds the port, and reserves GPU devices with the `nvidia` driver at `count: all`:
version: "3.8"

services:
  ai-toolkit:
    image: ostris/aitoolkit:latest
    restart: unless-stopped
    ports:
      - "8675:8675"
    volumes:
      - ~/.cache/huggingface/hub:/root/.cache/huggingface/hub
      - ./aitk_db.db:/app/ai-toolkit/aitk_db.db
      - ./datasets:/app/ai-toolkit/datasets
      - ./output:/app/ai-toolkit/output
      - ./config:/app/ai-toolkit/config
Five host paths are bound in: the Hugging Face hub cache, the SQLite database mapped to `/app/ai-toolkit/aitk_db.db`, and the `datasets`, `output` and `config` folders. Sharing the hub cache with the host is the part that earns its keep, since base weights you already pulled are then visible inside the container. The environment and device reservation look like this:
    environment:
      - AI_TOOLKIT_AUTH=${AI_TOOLKIT_AUTH:-password}
      - NODE_ENV=production
      - TZ=UTC
    deploy:
      resources:
        reservations:
          devices:
            - driver: nvidia
              count: all
              capabilities: [gpu]
`AI_TOOLKIT_AUTH` falls back to the literal string `password`, so any host that can reach the published port shares a known credential with anyone else until you export the variable before the first start. `restart: unless-stopped` means the container returns on its own after a reboot, with whatever state was in `output/` at the time. The device block names one driver, so an AMD or ROCm reader gets no reservation from this file and has to find another path.
requirements.txt pins scipy and leaves torch to the manager
Dependency control is thinner than the model list suggests. `requirements.txt` holds two lines: one pulling in `requirements_base.txt`, one pinning `scipy==1.12.0`. No PyTorch version appears in it directly; the rest of the dependency list lives in `requirements_base.txt`.
Versioning is the other gap. A `version.py` sits at the top level, and the project publishes no GitHub releases at all, so there is no numbered version to pin a deployment to and reproducing a run means pinning a commit. The repository is not archived and the last push landed on 2026-10-31, so the tree is active, and an active tree with no release tags is a moving target: the model list has grown across FLUX.1, FLUX.2, krea 2, Ming-Image and Mage-Flow entries, and a config naming one checkpoint can be orphaned by a later commit that renames or drops it.
YuE2 training depends on a tokenizer the model authors never released
Audio training has a supply chain the README is direct about. For YuE2, the official audio-to-token encoder is unreleased, so training uses a community tokenizer written by Kytra and published as `Mothersuperior/yue2-mothersuperior-realaudio-tokenizer-v4`. Your dataset gets encoded with a third-party artifact the model authors did not ship and the trainer does not own, and a silent update to that checkpoint changes the tokens a run sees with no change on your side and no version pin in `requirements.txt` to catch it.
The same list shows how separate modes collapse into one path. Qwen-Image-2.1 appears under both lists as one model for both jobs, and it edits when your dataset has control images, so a mislabelled dataset trains the wrong task instead of failing. Two other entries are marked for what they are: Flex.2-preview is a preview, and Zeta Chroma sits under the Experimental heading rather than with the settled image models.
The config directory, not the docs, is the contract
The compose file mounts `aitk_db.db` from your working directory, so that database lives outside the container and survives an image upgrade.
The `datasets/` folder is bind-mounted the same way. Reading `config/`, `jobs/` and the repository's FAQ.md before your first run is worthwhile.
A browser trainer against a command-line one
The other common route into diffusion fine-tuning is a command-line trainer such as Kohya's sd-scripts, launched from a terminal. AI Toolkit takes a recognisable job shape and puts a browser interface in front of it on port 8675, adds an installer manager, and publishes a container image. That is a difference in where the work happens, not a claim about which trains better.
The trade is that the interface and the manager are the project's own code, so a failure in either is a failure of the tool rather than of your config, though the README says the toolkit can also be run as a CLI. If your workflow is scripted, reproducible from a terminal, and version-controlled as plain text, the browser layer buys nothing. The `config/` and `jobs/` directories are the parts worth reading either way, since that is where a run is actually defined.
Editorial conclusion
Adopt it if you are fine-tuning FLUX, Qwen-Image, Wan or Ace Step on a single NVIDIA machine and are willing to read the config/ and jobs/ directories yourself, because that is where the real contract lives. Skip it if you need a released version to pin. Before the first long run, check three things: which commit you are on, since the repository has no GitHub releases and the last push was on 2026-10-31, whether AI_TOOLKIT_AUTH is set to anything other than the default password, and whether the checkpoint you intend to train still appears under the model list in that same commit.
Frequently asked questions
How do I install ostris ai toolkit?
The README's installation section starts with the AI Toolkit Manager, found in the manager/ directory. A compose file for the ostris/aitoolkit:latest image is also checked in as a container alternative, publishing the interface on port 8675.
How do I install ai toolkit on Windows?
There is no separate Windows build. The repository ships run_windows.bat at the top level as the Windows entry point.
How do I use ai toolkit in VS Code?
The repository contains a .vscode/ directory and a tsconfig.json, and the training code is Python, so opening the repository root as a workspace is the working setup. Training still starts through the launchers or the manager, which serves the interface on port 8675 rather than exposing a VS Code command.
Is AI Toolkit free?
The repository is MIT licensed and describes itself as free and open source. Model weights are separate downloads from Hugging Face, and the container path reserves GPU devices through the nvidia driver.
How do I use ai toolkit?
Training jobs are defined in the jobs/ and config/ directories, and a run is entered through run.py, run_linux.sh, run_mac.zsh, run_windows.bat or run_modal.py, with a web interface on port 8675 in the compose setup. Finished weights land in the output/ directory inside the checkout.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ostris-ai-toolkit)Star history chart for your README
[](https://hysenlabs.com/projects/ostris-ai-toolkit)Was this useful?