LLM Agents Ecosystem Handbook: 24+ providers, two pinned SDKs, 45 top-level directories
One-stop handbook for building, deploying, and understanding LLM agents with 60+ skeletons, tutorials, ecosystem guides, and evaluation tools.
At a glance
- What is it?
- An MIT-licensed Python handbook that organises agent work into twelve stack layers and six provider families, with adapters, templates and evaluation tooling included. Its own numbers do not agree, its quick-start router snippet calls a variable it never defines, and its dependency file pins two provider clients.
- Who is it for?
- Work from this repository when you need the vocabulary and the file layout for a full agent system rather than a single integration: the twelve-layer stack table and the six provider families are the parts that survive contact with a real project, and the example workspaces are named after stack layers rather than after demos.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 138 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
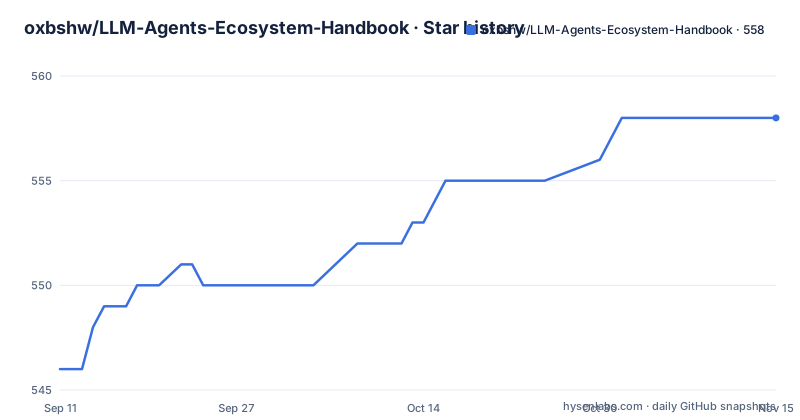
- oxbshw/LLM-Agents-Ecosystem-Handbook558 ★ · +12
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| oxbshw/LLM-Agents-Ecosystem-Handbook | 546 | 558 |
12 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The quick-start router call references a variable the snippet never defines
The provider quick start is the first thing a reader copies, and its second half does not run:
from utilities import get_provider
from utilities.provider_router import ProviderRouter

# Use any single provider
out = get_provider("groq").chat(
    [{"role": "user", "content": "Summarize MCP."}],
    model="llama-3.1-8b-instant",
)

# Or route by task class with fallback
router = ProviderRouter()
out = router.chat(messages, task_class="cheap")  # Groq → DeepSeek → Together → OpenRouter
The first call inlines its message list as a literal, a single user turn asking for a summary of MCP. The second takes `messages` as a bare name that appears nowhere above it, so a reader who runs the block from the top gets a name error on the line meant to demonstrate the router. The one piece of real information in that line is the trailing comment: the fallback chain for the `cheap` task class is Groq, then DeepSeek, then Together, then OpenRouter. That ordering is a cost and latency claim about four providers at once, and it is the kind of default worth rewriting for your own priorities rather than inheriting.
24+ providers are advertised, and requirements.txt pins two clients
The handbook ships an `LLMProvider` abstraction covering 24 or more providers, and the repository description leads with 60 or more skeletons plus tutorials, guides and evaluation tools. The dependency file reflects none of that:
gradio
streamlit
pandas
numpy
pytest
openai>=1.0.0         # required for OpenAI and MiniMax (OpenAI-compatible API)
anthropic             # optional: for Anthropic Claude models
The file installs two user-interface frameworks for the example agents and web apps, three general-purpose libraries and a test runner, then two provider clients. One of those clients does double duty: `openai>=1.0.0` is annotated as required for both OpenAI and MiniMax, because MiniMax is reached over an OpenAI-compatible API. That annotation is the pattern the provider section describes when it says most providers go through a single OpenAI-compatible code path while specialty and local providers are first-class. The consequence for a reader is that the adapter layer, not the dependency file, is what makes the 24-plus figure real, and that `pip install -r requirements.txt` gives you a working demo rather than a working catalogue.
Six provider families, and one paragraph recommending a commercial control plane
Providers are grouped into six families with a stated purpose each: frontier APIs such as OpenAI, Anthropic and Google Gemini for reasoning, tool use and production agents; fast inference such as Groq, Cerebras and SambaNova for low-latency workloads; marketplaces such as OpenRouter, Together, Fireworks and DeepInfra for model choice and routing; enterprise clouds such as Azure OpenAI, AWS Bedrock and Vertex AI for compliance and governance; specialty providers including xAI, Perplexity, Mistral, Cohere, DeepSeek, Hugging Face, Replicate, NVIDIA NIM and MiniMax for domain-specific work; and local runtimes such as Ollama, LM Studio, vLLM and llama.cpp for privacy, cost control and offline development. Those names add up to twenty-six, which is consistent with the 24-or-more claim. Four documents carry that section in full: `providers/README.md`, `providers/provider_matrix.md`, `providers/router_patterns.md` and `providers/local_models.md`, the last two matching the two families most likely to need their own guidance, routing and local hosting. Tucked into the section is one sentence recommending an outside commercial runtime by name and link, offered as a governed OpenAI-compatible control plane for policy enforcement, approval gates, MCP and agent tracing, and usage or cost visibility without changing the surrounding framework. Everything else in the handbook is vendor-neutral, so that paragraph is the single place where it is not, and it is the only external product link in the visible documentation.
.env.example is organised by provider family, and Bedrock is the odd one out
The environment template mirrors the six-family table, one comment block per family, with `LLM_PROVIDER=openai` as the default that `utilities/llm_provider.py` reads. Frontier keys are `OPENAI_API_KEY`, `ANTHROPIC_API_KEY` and `GOOGLE_API_KEY`. The enterprise block carries `AZURE_OPENAI_API_KEY` alongside `AZURE_OPENAI_ENDPOINT`, then AWS_ACCESS_KEY_ID, AWS_SECRET_ACCESS_KEY and AWS_REGION, and Bedrock is the one family with no provider-specific key at all because it uses standard AWS auth. Fast inference gets three keys, marketplaces four, specialty eight including `HF_TOKEN` and `REPLICATE_API_TOKEN`. Local runtimes are the only entries commented out, with their default base URLs shown so they can be overridden: `OLLAMA_BASE_URL=http://localhost:11434/v1`, `LMSTUDIO_BASE_URL=http://localhost:1234/v1` and `VLLM_BASE_URL=http://localhost:8000/v1`. The header says never to commit `.env` and never to paste real keys into the template, with the full reference at `providers/env_vars.md`.
Forty-five top-level entries, including three near-duplicate directory pairs
The README's own repository map describes eight directories in one line each: `agent_os/` for the Agent OS concept, layers and workspace examples, `providers/` for the provider documents, adapters and router patterns, `templates/` for AGENTS.md, SOUL.md, MEMORY.md, SKILL.md, DESIGN_DOC and ADR, `skills/` for the design guide, taxonomy, maturity model, curated catalog and four examples, `memory/` for the memory taxonomy, distillation, security and examples, and `mcp/` for MCP basics, architecture, security, a server catalog and examples. The actual top level carries forty-five entries, and several overlap in purpose. There is both `design/` and `design_docs/`, both `evals/` and `evaluation_frameworks/`, and both `agents/` and `agent_os/`, with the reader table and the stack table routing people to the second name of each pair while the first sits beside it. Then there are directories neither table mentions: `datasets/`, `resources/`, `notebooks/`, `complete_apps/`, `web_apps/`, `scripts/`, `tests/`, `examples/` and a top-level `github/` whose purpose is not stated in the visible documentation. The files around them are conventional, `CHANGELOG.md`, `ROADMAP.md`, `CONTRIBUTING.md`, `CODE_OF_CONDUCT.md`, `SECURITY.md` and `TRANSLATION.md`, except for a `MIGRATION_AND_PROVIDER_EXPANSION_PLAN.md` that sits at the root rather than inside `design_docs/`.
Twelve reader routes and twelve stack layers, with one row addressed to a coding agent
Two tables do the organising work. The who-this-is-for table routes by situation rather than describing an audience: newcomers to `docs/beginners_guide.md` then `agent_os/README.md`, production work to `blueprints/` then `checklists/production_readiness_checklist.md`, provider selection to `providers/provider_matrix.md`, framework comparison to `docs/framework_comparison.md`, memory and retrieval to `memory/` and `tutorials/rag_tutorials`, MCP to `mcp/mcp_security.md`, skill design to `skills/skill_design_guide.md`, coding agents to `coding_agents/prompts/`, and safety and evaluation to `safety/` and `evals/`. The final row addresses a machine rather than a person: a coding agent reading the repository starts at `llms.txt` and then `llm_wiki/index.md`, both at the root alongside `llms-full.txt`, with a `llm_wiki/` directory behind the second. The stack table then makes the central claim operational, giving twelve layers from model and provider through orchestration, tool, MCP, memory, skills, identity, prompt, safety and observability to deployment and a coding-agent harness.
Seven example workspaces, six of them named after a stack layer
The `examples/` directory holds seven runnable workspaces and the naming is the point. `agent_workspace_minimal` and `agent_workspace_production` are the only explicit pair, and the difference between them is the handbook's own argument about scope in two filenames. The other five take a layer name directly: `guarded_action_agent` for safety and approvals, `mcp_enabled_coding_agent` for the MCP layer, `memory_enabled_assistant` for memory, `skill_enabled_research_agent` for the skills layer, and `traced_agent_run` for observability. Each is a directory rather than a notebook, and `examples/README.md` heads them, so the examples are meant to be read as projects with their own structure rather than as cells to run top to bottom. That naming convention does two useful things: it makes the stack table executable, since you can open the layer you are reading about and find a runnable version of it, and it keeps the seven from overlapping with the skeletons in the curated catalogue, which are third-party projects rather than workspaces shipped here. The `tests/` directory at the root is the only other place a reader would expect to find verification for those seven, and nothing visible says whether the example workspaces are covered by it.
The description says 60+ skeletons, the catalogue section says 100+
A handbook that grades advice with a maturity model has two different counts for its own catalogue. The repository description advertises 60 or more skeletons, tutorials, ecosystem guides and evaluation tools. The seventh part of the contents list describes a curated catalogue of 100 or more existing agent skeletons, plus framework comparisons, evaluation tools and tutorials, preserved and improved. Part three, the skills ecosystem, is described differently again: a curated in-repo catalog with a design guide, a taxonomy, a maturity model, a security checklist and four examples. Both counts can be defensible under different readings, one counting notebooks or workflows and one counting skeletons, but neither document says which is which, so a reader deciding whether the catalogue is comprehensive has no way to tell which figure describes what. Versioning offers no help either: there are no GitHub releases to pin against, and the default branch was last pushed on 2026-06-30.
Editorial conclusion
Work from this repository when you need the vocabulary and the file layout for a full agent system rather than a single integration: the twelve-layer stack table and the six provider families are the parts that survive contact with a real project, and the example workspaces are named after stack layers rather than after demos. Do not treat its dependency file as a setup path, since `requirements.txt` installs gradio, streamlit, pandas, numpy, pytest and two provider clients against a catalogue that advertises 24+ providers. Before you rely on a number it states, check it, because the description says 60+ skeletons while the catalogue section says 100+, and before you paste the router snippet, note that its second call references a `messages` variable the snippet never defines.
Frequently asked questions
How many LLM providers does the LLM Agents Ecosystem Handbook support?
24 or more through an `LLMProvider` abstraction, grouped into six families: frontier APIs, fast inference, marketplaces, enterprise clouds, specialty providers and local runtimes. Most go through a single OpenAI-compatible code path, while specialty and local providers are treated as first-class.
What does requirements.txt in the LLM Agents Ecosystem Handbook install?
gradio, streamlit, pandas, numpy and pytest, plus `openai>=1.0.0`, which is required for both OpenAI and MiniMax because MiniMax is reached over an OpenAI-compatible API, and `anthropic`, marked optional for Anthropic Claude models. Only those two provider clients are pinned.
Where should a coding agent start when reading this handbook?
The reader table routes a coding agent to `llms.txt` and then `llm_wiki/index.md`, both at the repository root alongside `llms-full.txt`. Human readers are routed by situation instead, from `docs/beginners_guide.md` for newcomers through to `checklists/production_readiness_checklist.md` for production work.
Does the LLM Agents Ecosystem Handbook release versioned versions?
No GitHub release exists for it. Versioning is by commit, with `CHANGELOG.md` and `ROADMAP.md` at the root and no tags to pin against. The default branch was last pushed on 2026-06-30.
What counts as an LLM agent in this handbook's stack model?
Not a prompt plus a tool. The stack table gives twelve layers: model and provider, orchestration, tool, MCP, memory, skills, identity, prompt, safety, observability, deployment and a coding-agent harness, with the opening claim adding evals and a provider strategy to the list of things an agent system carries.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oxbshw-llm-agents-ecosystem-handbook)Star history chart for your README
[](https://hysenlabs.com/projects/oxbshw-llm-agents-ecosystem-handbook)Was this useful?