perplexity-scraper: documentation for a hosted API, with no source code and no licence
Perplexity Scraper Track brand mentions, analyze rankings, and gain competitor intelligence from Perplexity. Get started in minutes.
At a glance
- What is it?
- This repository documents a paid service that sends prompts to an AI search engine and hands back parsed results. It is worth reading carefully because most of what a user needs is not in it: there is no source, no licence file, both output examples on the page are incomplete, and the one field that tells you whether the parse worked uses a success code nobody would guess.
- Who is it for?
- Use this service if you need to audit or track a generative search engine's answers at volume and you are willing to route that traffic through a third party's proxy infrastructure rather than your own. Before you build on it, settle three things.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 59 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
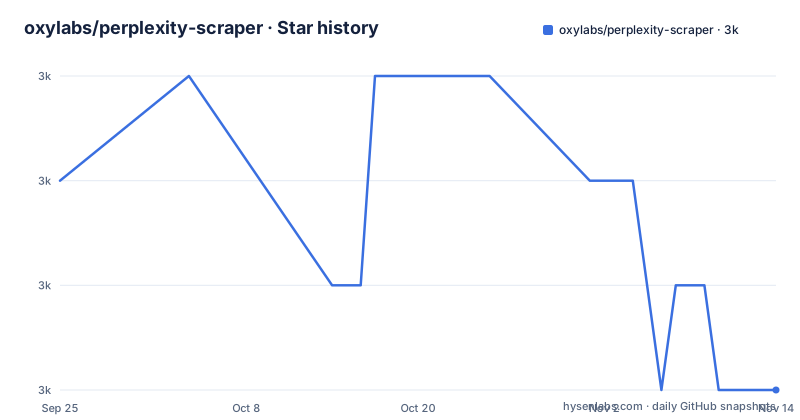
- oxylabs/perplexity-scraper3,027 ★ · -2
| Repository | 2026-09-25 | 2026-11-14 |
|---|---|---|
| oxylabs/perplexity-scraper | 3k | 3k |
-2 Stars in the last 50 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository is a product page with a code sample, not a tool
The tree is the first thing worth reading, and it reframes everything else. It holds a readme, a directory of code examples in several languages, one complete output sample stored as a JSON file, and seven images at the root, of which two are promotional banners for the vendor's own site and one has a space and an at sign in its filename. There is no source code, no package manifest, no build file, no continuous integration directory and no licence file. So there is nothing here to install, build, fork or vendor. What you consume is a hosted endpoint running on the vendor's infrastructure, and this page is its reference documentation. That framing matters before any of the technical detail, because the answer to every operational question turns out to be a plan tier rather than a line of code, and because the absence of a licence file means the samples have no stated reuse terms.
You cannot run this without a commercial account
The how-it-works section is three sentences and one of them is the whole dependency. The scraper handles rendering, parsing and delivery; you need to provide your prompt, your credentials and a few optional parameters. Then the request sample shows what credentials means in practice: a username and a password passed to the vendor's query endpoint using standard basic authentication. So the credential is an account with the vendor, not an account with the service being queried, and there is no path in this repository to using the interface without one. That is the single most important thing in the sample for anyone evaluating it, and it sits in a code block whose real purpose is to show the payload shape. A free trial is offered by registering on the vendor's dashboard, which answers the commercial half of the question without touching the technical one.
Six parameters, one of them mandatory and also carrying a default
The parameter table is short and has one internal tension. The source selector identifies this particular scraper, it carries the fixed value that says so, and it is also marked mandatory, which leaves a reader unsure whether a constant must be sent explicitly. The prompt is the other mandatory field and it has a hard ceiling of eight thousand characters, which matters immediately if your plan is to feed it documents rather than questions. Parsing is opt-in and off by default, so a default call returns the raw document rather than the structured form, and asking for the structured form is an explicit choice. Geography selects the country the prompt is sent from, which links out to the vendor's documentation about proxy location rather than about the service itself. There is a callback for push delivery instead of waiting, and a field for custom browser instructions when the page renders with scripting.
Parse success is reported with the code 12000
The output structure table has a field for the parse status, and it is the field most likely to be missed:
| `parse_status_code` | `12000` - successful. Otherwise, parser failed to extract structured fields. | integer |So success is an invented value rather than a number anybody would guess, and it is not the status of the request, which in the sample response is the conventional two hundred. One response object therefore carries two different notions of success, one invented and one standard, and a client that checks the familiar one will read a failed parse as a success. This is the most likely integration bug in this interface, and it appears in a table cell rather than being called out anywhere. Everything the parser failed to produce will be simply absent from the payload, which then looks like an answer that contained nothing.
Six of the twelve documented keys exist only when the answer mentions them
Half the rows in the field table are marked as conditional, returned only when the relevant content appears in the response, and a note above the table says that the number of items and fields can vary with the submitted prompt. That is an honest admission about a generative interface, and it has a direct consequence for your code. You cannot assume a fixed schema, so the parsing has to tolerate absent keys, and an absent array is not the same thing as an empty one. Two rows are worth naming. The generated answer appears twice, once as a tree of nodes and once as a single flattened Markdown string, so you pick a representation rather than receiving one. And the suggested follow-up questions come back as plain strings rather than objects, which means you cannot attach a score or a rank to them even though the page calls them related.
Both output examples on the page are incomplete
There is a heading for an HTML example and nothing under it. The structured snippet that follows stops in the middle of a string value, with an ellipsis standing in for the rest of the array. The complete sample does exist, as a JSON file committed to the repository, and the page links it, which is the right arrangement and the right thing to point at. But the two examples printed on the page are the ones a reader skims while deciding whether the output shape suits them, and both of those fail: one is empty and one is cut mid-string. Open the file rather than trusting the page, and check the parse status field while you are there.
The legal question is asked and answered halfway
The page ends with a frequently-asked-questions section whose first entry asks whether scraping the target service is allowed. The answer opens by observing that the target does not provide a public API for all of it, and then stops mid-sentence. That is the question a reader most needs answered, and it is left open by a truncation rather than by a decision to be vague, which is a different and more annoying problem. The three listed use cases are unobjectionable on their face: comparing the quality and consistency of generated answers over time, watching how a topic gets summarised as that changes, and tracking how a brand is mentioned relative to competitors. What none of them tells you is whether the terms of the service permit automating this volume, and that is a question for the vendor rather than for a readme. Settle it before you build a pipeline on it, and settle whether you can rely on this at all before you depend on an interface whose success sentinel is an undocumented-looking number.
Editorial conclusion
Use this service if you need to audit or track a generative search engine's answers at volume and you are willing to route that traffic through a third party's proxy infrastructure rather than your own. Before you build on it, settle three things. What the licence is, because the repository has no licence file at all and nothing on the page grants you reuse of the code samples. Whether the parse succeeded, because the field that reports it uses an invented success value while the request's own status is a conventional one, and checking the wrong one gives you a false pass. And whether the target's terms permit what you intend, since the page's own answer to that question stops halfway through a sentence. Also plan for a prompt-dependent schema: half the documented keys appear only when the answer happens to contain the matching content, so your parsing has to tolerate missing fields.
Frequently asked questions
Is AI scraping illegal?
This repository asks a version of that question and does not finish the answer. Its frequently-asked section opens with whether scraping the target service is permitted, notes that the target does not offer a public API for all of it, and then stops mid-sentence. Legality also depends on where you are and on the target's terms, neither of which this page covers, so the question belongs with the vendor and with whoever owns the compliance decision.
Is web scraping legal or illegal?
The page takes no position on the general question and is not about general scraping. It documents one hosted endpoint for one target, and its own use cases are auditing generated answers, tracking how a summary changes over time, and comparing brand visibility. The one piece of guidance it attempts is the truncated answer about whether this particular target permits it.
Which AI is best for scraping data?
Not a question this repository addresses. It is not about choosing a model to scrape with; it is about sending prompts to one generative search engine through a vendor's proxy network and receiving the results parsed into structured fields. The only model reference on the page is the name the target reports back for the answer it generated, which appears in the output as a string field.
Is scraping with BeautifulSoup legal?
That library is not mentioned here, and the point does not apply: there is no scraping code in this repository to run. The service renders and parses the page for you, on the vendor's infrastructure, and returns either the raw document or a structured object. The only sample code is a client that posts a prompt and prints the response.
How do I know if the Perplexity scraper parsed the answer?
Check the dedicated parse status field in the output structure table. It is an integer with one value meaning the structured fields were extracted successfully and anything else meaning the parser failed, and that value is not the request's status code, which is the conventional two hundred in the same object. The page does not highlight this anywhere outside the table, so it is the field most likely to be missed and most likely to be checked wrongly.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oxylabs-perplexity-scraper)Star history chart for your README
[](https://hysenlabs.com/projects/oxylabs-perplexity-scraper)Was this useful?