Parca: continuous profiling that keeps raw pprof and compares profiles across deploys and versions
Continuous profiling for analysis of CPU and memory usage, down to the line number and throughout time. Saving infrastructure cost, improving performance, and increasing reliability.
At a glance
- What is it?
- Parca pairs an eBPF profiler that discovers Kubernetes and systemd targets with a Go server that stores raw pprof profiles and compares them by label. The awkward part is that the profiler and the server install separately, and the repository covers only the server.
- Who is it for?
- Parca fits teams that already run Kubernetes or systemd fleets and want profiles they can diff across deploys, versions and regions without adding instrumentation. Before adopting it, check on parca.dev how retention is bounded so raw pprof does not fill your disk, how a forwarding mode authenticates to its remote gRPC endpoint, and how storage is selected.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
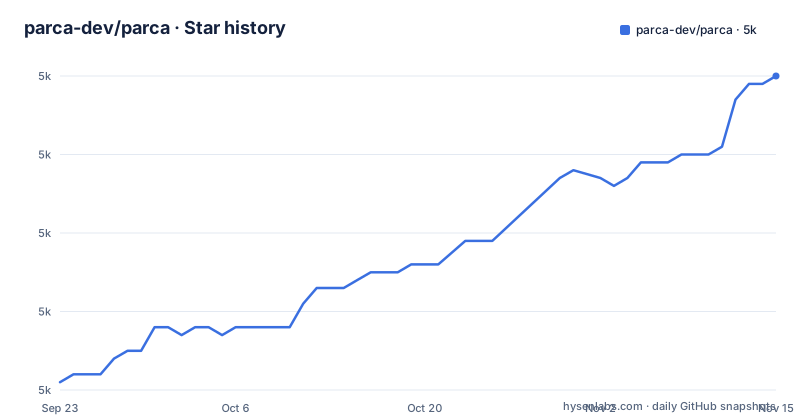
- parca-dev/parca5,020 ★ · +39
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| parca-dev/parca | 5k | 5k |
39 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One eBPF profiler discovers targets across Kubernetes and systemd
The profiling half of Parca is an agent that attaches to processes through eBPF. It finds its own targets, either from Kubernetes or from systemd, across a whole infrastructure, and the project claims very low overhead from that. Nothing has to be added to your source: the pitch is zero instrumentation for the whole infrastructure, so the agent lands next to running services rather than inside a build. Supported languages named by the project are C, C++, Rust, Go and more, and the agent is not what you talk to when you open the web UI. The distribution page linked at the top of the README is a snap for `parca-agent`, which tells you the agent ships and versions on its own, separately from the server binary the rest of this article is about. Parca itself was originally developed by Polar Signals, and the same organisation also maintains the `frostdb` and `iceberg-go` libraries that appear in the server's dependency list, so the agent, the storage layer and the query layer come from one small group rather than from unrelated vendors.
pprof is both the format Parca writes and the format it accepts
Parca ingests pprof formatted profiles and also produces them. Anything that can emit pprof, whether the built-in eBPF profiler or another tool you already run, can be queried in the same interface. That is the interoperability claim in the project description, and it is the part with real consequences for you: a service profiled by a different agent does not need to be switched over to Parca to become queryable, so adoption can start with whatever coverage you have and widen later. The dependency list backs this up rather than just asserting it. `github.com/google/pprof` is pinned in `go.mod` for parsing, `github.com/felixge/fgprof` is there for wall clock profiles that include off CPU time, and `github.com/prometheus/client_golang` appears alongside them. The format is a boundary that Parca does not own, which is convenient for you. Storage keeps the raw bytes rather than only pre-aggregated views, so a question you did not think to ask at collection time can still be answered later, at the cost of disk you have to manage.
--mode decides whether the process scrapes or serves
One flag decides which components a Parca process runs:
Usage: parca [flags]

Flags:
  -h, --help                     Show context-sensitive help.
      --config-path="parca.yaml"
                                 Path to config file.
      --mode="all"               All runs all components. Scraper-only and
                                 forwarder send profiles to a remote Parca
                                 gRPC endpoint. OTLP-forwarder converts pprof
                                 profiles and sends them to an OTLP profiles
                                 gRPC endpoint.
      --http-address=":7070"     Address to bind HTTP server to.
Read that carefully. `--mode="all"` is the default and runs every component in one process, which is why a locally started Parca starts scraping right away. The alternatives are scraper-only and forwarder, which send profiles to a remote Parca gRPC endpoint, and otlp-forwarder, which converts pprof profiles and sends them to an OTLP profiles gRPC endpoint; that is the shape a split deployment takes: agents close to the workloads, one server holding the data. The README's OTLP section names `--store-address`, `--bearer-token`, `--bearer-token-file`, `--grpc-headers`, TLS flags and `--insecure` for that upstream connection, and hands you to parca.dev for installation guides. The same gap applies to access control on the web server itself: `--http-address=":7070"` binds all interfaces by default, so do not expose that port on a network you do not control without reading the documentation first.
make build compiles a binary with optimisation switched off
The only commands in the repository are for working on Parca rather than installing it, and they need Go, Node and pnpm on the machine first:
git clone https://github.com/parca-dev/parca.git
cd parca
make build
`make build` depends on `ui/build` and `go/bin`, so the web interface is compiled first and the Go binaries second. The Go step is one line in the `Makefile`, and the flags on it matter:
go build $(SANITIZERS) -gcflags="all=-N -l" -o bin/ ./cmd/parcaOptimisation and inlining are disabled across every package there, which is what you want for a profiler you intend to read profiles from and not what you want for a server handling production traffic. Release artifacts come from `.goreleaser.yml` instead. The result lands in `bin/parca`, and starting it with no arguments serves the web UI on http://localhost:7070/ and starts scraping. That default is worth understanding before you conclude the tool is broken: out of the box Parca profiles its own pprof endpoints, so profiles appearing over time in a fresh checkout are Parca profiling Parca, not your application. The scrape configuration to change is `parca.yaml` in the root of the repository, and the flag default for the config path points at the same filename. Dependency hygiene is scripted too, with `go mod tidy` and a vulnerability check:
go mod tidy
govulncheck ./...
Version numbers come from `git describe --tags --match='v*'` when a release tag is present, which is another reason the local build behaves differently from a tagged one.
Keeping raw bytes is what makes a deploy comparable to a version
The storage and query layer is the reason to keep Parca around after the novelty of seeing a flame graph wears off. Data is stored efficiently while the raw data is retained, and the interface slices it through a label based search. You can aggregate across the whole infrastructure, view a single profile in time, or compare on any dimension the labels carry. The project's own examples of a label dimension are deploys, versions and regions, and that comparison is the feature with teeth: a regression hunt becomes a query that puts the profile from before a deploy next to the profile after it, rather than a memory of what a flame graph looked like last week. The claim that this works with confidence rests on collecting over time rather than on sampling a single run, which is the argument for always-on profiling over on-demand capture, and it is also the argument for accepting the storage bill that comes with it. The interface does not merely store aggregates either, so you can aggregate infrastructure wide and view single profiles in time.
Storage choices are visible in go.mod and invisible in the flags
The dependency list names several storage-related libraries:
- `github.com/ClickHouse/clickhouse-go/v2` at v2.43.0, the column store option - `github.com/dgraph-io/badger/v4` at v4.9.1, an embedded key value store that needs no server - `github.com/parquet-go/parquet-go` at v0.24.0 and `github.com/apache/arrow-go/v18` at v18.5.2 for columnar files - `github.com/polarsignals/frostdb` and `github.com/polarsignals/iceberg-go`, both from the organisation that wrote Parca - `github.com/minio/minio-go/v7` at v7.0.72 for object storage - `github.com/pierrec/lz4/v4` for compression, `github.com/alecthomas/kong` at v0.9.0 for the command line parser
Two practical consequences follow. Badger means you can try Parca with no database to run, and MinIO in the same list means the same binary can push profiles into object storage. The README sends you to the website for configuration detail, so check there for how each library is turned on. The server also pulls in `github.com/grpc-ecosystem/grpc-gateway/v2` at v2.30.0 and `github.com/improbable-eng/grpc-web`, which is how the browser side of the interface reaches the same API that agents push to, and it is worth knowing that the UI is not a separate service with its own release cycle.
The container build retries a health probe download fifty times
The `Dockerfile` is two stages and both ends are pinned to a digest rather than a tag, which is the right instinct for a released image. The builder is `docker.io/busybox:1.37.0` with a sha256 digest, the runner is `docker.io/alpine:3.24.3` with its own digest, and the runner carries the standard `org.opencontainers.image` labels pointing back at the repository. The copy step is arch specific and expects the layout `.goreleaser.yml` produces, picking `dist/parca_${TARGETOS}_${TARGETARCH}_${TARGETVARIANT:-v1}/parca` on amd64 and a variant stripped path on arm, so the image cannot be built straight from a checkout without running the release pipeline layout first. The published location is `ghcr.io/parca-dev/parca`, set as the default `OUT_DOCKER` in the `Makefile`. Nearby files complete the picture for anyone automating this: `Dockerfile.dev`, `Dockerfile.go.dev`, a `Tiltfile` for running Parca as a container inside Kubernetes, `deploy/` for manifests, and `snap/`.
Editorial conclusion
Parca fits teams that already run Kubernetes or systemd fleets and want profiles they can diff across deploys, versions and regions without adding instrumentation. Before adopting it, check on parca.dev how retention is bounded so raw pprof does not fill your disk, how a forwarding mode authenticates to its remote gRPC endpoint, and how storage is selected. Build from a release tag rather than `make build` for anything you intend to run for a while, because the local Makefile compiles with optimisation disabled.
Frequently asked questions
How does Parca compare to Pyroscope?
The repository makes no direct comparison, so the honest answer covers only Parca's side: a single eBPF profiler that discovers Kubernetes or systemd targets with no instrumentation, pprof as both input and output format so profiles from other tools can be ingested, and raw profile data kept for label based comparison across deploys, versions or regions.
Does Parca need instrumentation in my code?
No. The project states that the profiler requires 0 instrumentation for the whole infrastructure, and that a single eBPF based profiler discovers targets from Kubernetes or systemd on its own. Supported languages named are C, C++, Rust, Go and more.
Where does Parca put profile data and how long does it keep it?
The project describes storing profiling data while retaining the raw data, sliced through a label based search. The dependency list shows the candidate backends: ClickHouse, Badger, Parquet, Arrow, FrostDB, Iceberg and MinIO.
What is the difference between the Parca modes?
The flag `--mode="all"`, which is the default, runs all components in one process. The scraper-only and forwarder modes send profiles to a remote Parca gRPC endpoint, and otlp-forwarder converts pprof profiles and sends them to an OTLP profiles gRPC endpoint without starting a local profile store.
Which languages can the Parca agent profile?
C, C++, Rust, Go and more are the languages the project names for the eBPF profiler. Separately, Parca ingests any pprof formatted profile, so a runtime covered by a different pprof producing tool can still have its profiles queried in the same interface.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/parca-dev-parca)Star history chart for your README
[](https://hysenlabs.com/projects/parca-dev-parca)Was this useful?