BDH: the headline number precedes the sentence saying this repo cannot reproduce it
BDH (Dragon Hatchling) – Architecture and Code
At a glance
- What is it?
- pathwaycom/bdh publishes two Python files behind a paper-style README whose Architecture section is an empty heading and whose Scaling Laws section is one sentence, while a 97.4 percent Sudoku figure from an internal implementation is presented in a comparison table and only then explained as not reproducible from the open-source code.
- Who is it for?
- Read it if you are interested in the architecture, and read the paper, because the README's Architecture section is empty and the Scaling Laws section contains a claim rather than a law. Two things to weigh before you build on the code.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 9 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
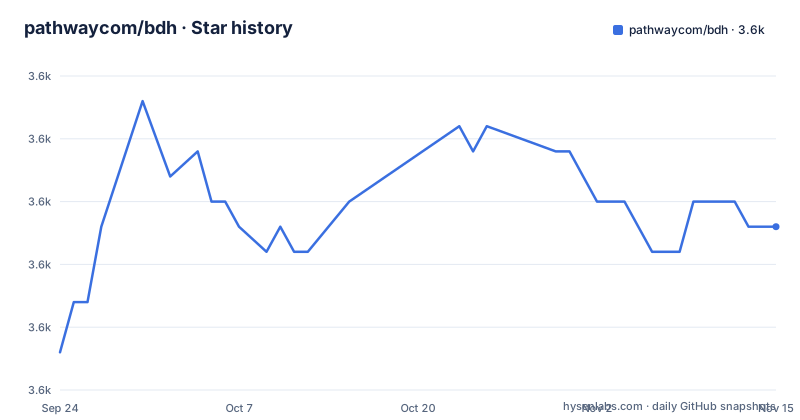
- pathwaycom/bdh3,579 ★ · +5
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| pathwaycom/bdh | 3.6k | 3.6k |
5 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Architecture section is an empty heading
The README has four top level sections that read like a research paper: Overview, Architecture, Relation to Transformers, and Scaling Laws. They are separated by horizontal rules, which is the paper convention.
Three of them have content. Architecture has none. It is a heading followed immediately by a horizontal rule and the next heading.
That is a strange thing to leave in a document whose central claim is that the architecture is the contribution. The overview lists five key properties, and they are substantive: a scale-free network topology, locally interacting neuron particles with excitatory and inhibitory dynamics, Hebbian working memory through synaptic plasticity displaying monosemanticity, a GPU-friendly state-space formulation, and activations that are sparse and positive. The claim is that reasoning emerges from micro-level neuron dynamics. Where the reader would expect the mechanism to be described, there is nothing.
Relation to Transformers gets one paragraph, which does the important conceptual work: the two share attention-inspired computation, but in BDH attention emerges from neuron-level interactions rather than being an explicit mechanism.
So the document explains what BDH is, why it should be interesting, and how it differs from the thing it is replacing. It does not explain how it is built. For a repository billed as architecture and code, the architecture section being the empty one is the most consequential gap on the page, and it is a gap a reader will notice within thirty seconds of arriving.
Everything you would want is one click away, in the paper. The README says the repository contains the official implementation from the paper, and gives the paper's title, its five authors and its arXiv identifier. What it does not do is summarise the architecture the code implements.
The Scaling Laws section is one sentence with no law in it
There is a section headed Scaling Laws. It contains one sentence: BDH follows Transformer-like scaling laws, maintaining parameter efficiency while achieving interpretability at any scale.
That is a claim with three parts and no evidence attached. A scaling law is a relationship: as parameters or compute or data grow, performance does something, and the shape of that something is the law. The README states that the laws are followed and that parameter efficiency is maintained, and gives no exponents, no ranges, no figure and no comparison point.
The figures directory exists at the top level of the repository, so there is somewhere a plot could live. The README does not reference it, and the section does not embed anything.
This sits oddly against the one empirical claim in the document that is quantified. The Sudoku benchmark has a number, a dataset size, a table and a source note. The scaling behaviour, which for a model architecture is the more general and more useful claim, has none.
It also sits oddly against the framing. The overview says BDH scales like a Transformer on performance benchmarks. That is a benchmark-equivalence claim. The scaling section extends it to the asymptotic regime. And the Sudoku section, two headings later, reports a single point on one task from an implementation that is not in this repository.
A reader trying to decide whether this architecture is worth building on has three things to weigh: a qualitative statement that it matches transformers, a one-sentence claim about scaling, and a headline benchmark the repository says it cannot reproduce. The middle of those three is the one that would decide it for a research audience, and it is the thinnest.
The 97.4 percent figure appears before the sentence saying this repository cannot reproduce it
The Sudoku section opens with the result. BDH reaches 97.4 percent accuracy across roughly 250,000 difficult puzzles, without chain-of-thought, solution backtracking or external tool use, while leading language models struggle on the benchmark at all.
The disclaimer is the second paragraph.
It says the result refers to the authors' internal BDH implementation and not to the current open-source repository. It says the repository contains the baseline variant described in the public paper. And it says the repository does not reproduce the 97.4 percent result out of the box.
That is an unusually clear statement of what a repository can and cannot do, and whoever wrote it should be credited for it, because most papers with a headline number and a partial release would not put it that plainly.
The problem is entirely one of placement and framing. The number is the reason a reader is on the page. It arrives first, alone, with no qualifier. The correction is a paragraph below it, inside a section whose title is Latest research update, in a document whose preceding sections have already told you this is the official implementation.
By the time you reach the disclaimer you have read the number, the comparison to leading models, and a cost claim. The sentence that tells you none of it is reproducible from this code arrives after all three.
A reader skimming, which is most readers of a repository README, takes away the 97.4. A reader who finishes takes away the caveat. Moving the caveat above the number, without removing it, would cost the project nothing and change what the page actually communicates.
The comparison table merges two papers and one set of internal numbers
The performance table has two rows. One is the authors' architecture at 97.4 percent accuracy with a relative cost of ten times lower and no chain-of-thought. The other is a row of three named language models at approximately zero percent, with relative cost described as high because of chain-of-thought.
The source note underneath is the part to read closely. It attributes the model row to an arXiv paper whose identifier is different from the one the README cites for BDH itself, and attributes the BDH row to internal data.
So the table is a join between two documents and a private measurement. The competitor figure is taken from someone else's evaluation of three specific models at specific settings. The BDH figure is the authors' own. The note also states that the accuracy measure is top-1 and that the approach uses neither chain-of-thought nor backtracking.
Top-1 accuracy on a puzzle benchmark is a strange metric to compare against language models at all, because the competitor models are being asked to do something they have no affordance for. That is the argument the paragraph above the table makes, that search-heavy non-linguistic reasoning is awkward for token-by-token processing. It is a plausible argument. It is also the argument for why the comparison is not a like-for-like measurement, and the README does not draw that line.
What the ten-times cost figure is relative to is never stated. Cost of what, measured how, at what scale.
None of this makes the work wrong. It makes the table a press summary rather than a result, and a reader who wants to evaluate the claim has to go to two papers and one blog post to do it.
The implementation is two Python files and a toy dataset
The top level of the repository has seven entries. A gitignore, a licence file, this readme, a requirements file, a directory of figures, and two Python files: one named after the architecture and one named train.
That is the whole implementation. There is no package directory, no module layout, no packaging manifest, so nothing here can be installed as a library; you run it from a clone.
The install section is correspondingly short:
# install dependencies
pip install -r requirements.txt

# train BDH on a toy dataset
python train.py
Three dependencies, all unpinned, and then one training command.
The comment on the training command says it trains on a toy dataset. The acknowledgements confirm what toy means: the code from nanoGPT and a tiny Shakespeare dataset are the things this demonstration stands on. And the paper's own scale claim is parameter counts from ten million to one billion, which is the regime a Shakespeare character-level model is not in.
So the repository is an architecture reference implementation at demonstration scale, not a reproduction of the paper's results. That is a completely reasonable thing to publish, and the Sudoku disclaimer says as much. It is worth being explicit about it anyway, because the repository is called the official implementation and has 3582 stars, which is the profile of something people clone expecting to reproduce a headline number.
The unpinned torch is the other thing to note. For a research artefact people will run to check a claim, an unpinned deep learning framework means the numbers you get depend on when you installed, across a period in which the framework's defaults have moved more than once.
The notebook directory the README points at is inside a comment
There is exactly one line in this README that mentions notebooks, and it will not appear on the rendered page.
It is wrapped in an HTML comment, so it is present in the file and invisible to every reader. It points at a notebooks directory for visualization and interpretability analysis.
There is no notebooks directory at the top level of the repository. The seven entries do not include one.
So there are three separate states here. The directory is referenced, the reference is hidden, and the directory is absent. Someone with a clone and a text editor can find the comment and go looking; everyone else has no way to know it was ever mentioned.
This matters more than a stray comment usually would, because interpretability is the project's headline claim. The overview says BDH retains full interpretability, that its activations are sparse and positive, that Hebbian working memory displays monosemanticity, and the whole pitch is that you can read the reasoning off the neurons. The one artefact that would let a reader check any of that is the one thing the README points at from inside a comment to a directory that is not there.
The other half of this is that the figures directory exists and is not referenced. A paper-style README usually embeds its figures. This one has a heading, a paragraph of claims, and no diagrams.
Both are probably working-in-progress artifacts of a research release rather than oversights in a documentation file. The visible consequence is the same either way: the page that makes the interpretability claim is the page with no way to show it.
There is no test suite, no continuous integration and no version floor
Seven top level entries, and three things a software repository usually has are absent. There is no directory for tests. There is no continuous integration configuration, because there is no directory for it either. And there is no version floor on any dependency, because the requirements file lists three names with nothing after them.
For a two-file research artefact this is unremarkable. The code is short enough to read, and the claims it backs are about a paper rather than about a service.
It still has consequences for anyone who intends to build on it. With no tests, the only check that the architecture does what the paper says is running it and looking at the output. With no continuous integration, nobody re-runs that check when the framework underneath moves, so a repository whose entire value is that it implements a specific architecture has no mechanism for noticing when it stops doing so.
And with three unpinned dependencies, two clones of the same commit can install different versions of the deep learning framework weeks apart. For a claim about interpretability at the level of individual neurons, that is a meaningful source of variance and it is not acknowledged anywhere.
The project does have a community section listing five third-party repositories, including ports to two other machine learning frameworks, one of them a systems language and one of them Apple's. That is real adoption. It is also adoption of an architecture described in a two-file repository, which means the reference implementation is the specification, and the specification is unpinned.
Editorial conclusion
Read it if you are interested in the architecture, and read the paper, because the README's Architecture section is empty and the Scaling Laws section contains a claim rather than a law. Two things to weigh before you build on the code. The 97.4 percent Sudoku figure comes from an internal implementation the repository explicitly says it does not reproduce, so treat it as motivation rather than as something you can check here. And what is in the repository is a two-file, unpinned, untested reference implementation at Shakespeare scale, which makes it documentation for the architecture rather than a usable library.
Frequently asked questions
What is BDH in AI?
A biologically inspired language model architecture described as a scale-free network of locally interacting neuron particles with excitatory and inhibitory dynamics, Hebbian working memory through synaptic plasticity, sparse positive activations, and a GPU-friendly state-space formulation. The README says it matches GPT-2-scale transformers on language and translation tasks at parameter scales from 10 million to 1 billion.
Does this repository reproduce the 97.4 percent Sudoku result?
No, and the README says so directly. It states that the Sudoku Extreme result refers to the authors' internal implementation rather than this open-source repository, that the repository contains the baseline variant described in the public paper, and that it does not reproduce the figure out of the box.
How do I run the BDH code?
Install the dependencies with pip install -r requirements.txt, which are torch, numpy and requests with no version constraints, then run python train.py, which the README describes as training on a toy dataset.
What files are in the BDH repository?
Seven top level entries: a gitignore, the licence, the readme, a requirements file, a figures directory, and two Python files named bdh.py and train.py. There is no package manifest, no test directory and no continuous integration configuration.
Where does the leading model accuracy figure in the BDH comparison come from?
The source note under the table attributes the competitor row to an arXiv paper with a different identifier from the one the README cites for BDH itself, and attributes the BDH row to the authors' internal data. The note also states the measure is top-1 accuracy.
Who wrote BDH?
Researchers at Pathway. The README lists five paper authors, Kosowski, Uznański, Chorowski, Stamirowska and Bartoszkiewicz, on an arXiv paper from 2025. The acknowledgements credit nanoGPT code from Andrej Karpathy and a tiny Shakespeare dataset for the demonstration.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pathwaycom-bdh)Star history chart for your README
[](https://hysenlabs.com/projects/pathwaycom-bdh)Was this useful?