Langchainrb: one Ruby interface over eleven LLM providers, with the extra gems left to you
Build LLM-powered applications in Ruby
At a glance
- What is it?
- Langchainrb is a Ruby gem that puts Anthropic, OpenAI, Gemini, Ollama and other backends behind one embed, complete and chat interface, plus prompt templates and RAG building blocks. This analysis covers what the shared interface does, where it stops, and what you still wire up yourself.
- Who is it for?
- Use Langchainrb if you are a Ruby team that wants to change LLM vendors by changing one constructor line and you are happy to add the vendor and vector store gems yourself. Skip it if you need Rails wiring out of the box, since that lives in langchainrb_rails, and check the CHANGELOG against your provider before relying on a feature, because the latest tagged release is 0.19.5 from May 2025.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 25 days ago.
- What is it written in?
- Mainly Ruby, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
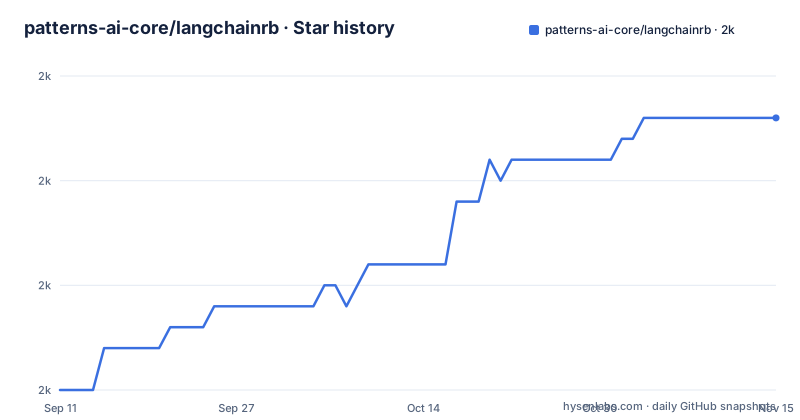
Star history
- patterns-ai-core/langchainrb2,008 ★ · +13
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| patterns-ai-core/langchainrb | 2k | 2k |
13 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Switching provider means swapping one constructor, not one config flag
Every backend in Langchainrb is a separate class under Langchain::LLM, and all of them inherit from Langchain::LLM::Base. Moving between vendors is a change to the line that builds the client:
# Using Anthropic
anthropic_llm = Langchain::LLM::Anthropic.new(api_key: ENV["ANTHROPIC_API_KEY"])

# Using Google Gemini
gemini_llm = Langchain::LLM::GoogleGemini.new(api_key: ENV["GOOGLE_GEMINI_API_KEY"])

# Using OpenAI
openai_llm = Langchain::LLM::OpenAI.new(api_key: ENV["OPENAI_API_KEY"])
The supported list is Anthropic, AWS Bedrock, Azure OpenAI, Cohere, Google Gemini, Google Vertex AI, HuggingFace, Mistral AI, Ollama, OpenAI and Replicate. The code that calls the client stays the same, but the credentials do not. The .env.example file shows how different they are: Azure needs AZURE_API_KEY plus separate AZURE_CHAT_URI and AZURE_EMBEDDING_URI values, Vertex AI wants GOOGLE_VERTEX_AI_PROJECT_ID and GOOGLE_CLOUD_CREDENTIALS, and Ollama is addressed through OLLAMA_URL=http://localhost:11434 with no key at all. The practical result is that your application code is portable while your deployment secrets and endpoints are not.
Embeddings and completions each take a short, fixed parameter list
The unified interface covers three operations: embeddings, prompt completions and chat completions. Embeddings go through embed, which needs only text and optionally a model name. If you leave the model out, the default embedding model for that provider is used:
response = llm.embed(text: "Hello, world!")
embedding = response.embedding
Plain completions go through complete, where prompt is the only required argument:
response = llm.complete(prompt: "Once upon a time")
completion = response.completion
The optional arguments for complete are max_tokens, temperature, top_p, n, stop, presence_penalty and frequency_penalty. Temperature and top_p are alternatives to each other for controlling randomness, so setting both is something to avoid unless a provider explicitly asks for it. Anything outside these three operations, such as image input, is not part of the shared interface. The only image example in the examples directory is examples/ollama_inquire_about_image.rb, so check how your chosen provider class handles it before assuming it works elsewhere.
The chat parameter list is shared, but a provider may not honor all of it
Chat is the call most applications use. It takes an array of role and content hashes:
messages = [
  { role: "system", content: "You are a helpful assistant." },
  { role: "user", content: "What's the weather like today?" }
  # Google Gemini and Google VertexAI convert these to their own format, and also accept it directly:
  # { role: "user", parts: [{ text: "why is the sky blue?" }]}
]
response = llm.chat(messages: messages)
chat_completion = response.chat_completion
Only messages is required. The optional list is longer than for complete: model, temperature, top_p, n, max_tokens, stop, presence_penalty, frequency_penalty, logit_bias, user, tools and tool_choice. A note in the docs says that while the core interface is consistent, some LLMs offer additional features or parameters and that each LLM class has its own documentation. The consequence is that a name like logit_bias or tool_choice appearing in the shared list does not tell you that every one of the eleven backends acts on it. Before you ship on a new provider, send each parameter you depend on through that provider's class and look at the response, rather than trusting the common list.
Provider SDKs and vector store clients are not installed for you
Installation is a single command when Bundler manages your dependencies:
bundle add langchainrbWithout Bundler, use:
gem install langchainrbThe catch is the sentence that follows: additional gems may be required, and they are not included by default so that you can include only what you need. Langchainrb does not pull in everything it can talk to. If you use Pinecone, Qdrant, Weaviate, Milvus, Chroma or pgvector, which all have example scripts in the examples directory, the client library for that store is something you add to your own Gemfile. The same applies to the provider side. A Ruby process that requires "langchain" and builds a class for a vendor whose supporting gem is missing will fail at that point, and the failure is yours to diagnose. That keeps the dependency tree small, but it also means a first install is rarely the last edit to your Gemfile, and the gemspec in the repository is the place to look for what is and is not bundled.
Response objects give you token counts without parsing vendor JSON
Each LLM method returns a response object with the same accessors, so you do not read raw vendor payloads. The accessors are embedding for the vector, completion for generated text, chat_completion for the chat reply, tool_calls for calls the model wants to make, and three usage counters: prompt_tokens, completion_tokens and total_tokens. Because the counters sit on the wrapper, a single logging or cost tracking helper can serve every provider. That is a real saving if you plan to compare vendors on token use. What the wrapper does not remove is the difference in meaning behind the numbers. Each provider counts tokens with its own tokenizer, so a total_tokens value from Ollama and one from OpenAI describe different units of work. Treat the counters as per-provider measurements and do not add them together across backends. The tool_calls accessor is similarly only a way to read what came back. Executing the tool and feeding the result back into the conversation is application logic, handled in your own loop or through the Assistants feature listed in the table of contents.
PromptTemplate formats strings with named variables and infers them when you let it
Prompt management starts with Langchain::Prompt::PromptTemplate. You give it a template string with braces and a list of the variable names, then call format with values:
prompt = Langchain::Prompt::PromptTemplate.new(template: "Tell me a {adjective} joke about {content}.", input_variables: ["adjective", "content"])
prompt.format(adjective: "funny", content: "chickens") # "Tell me a funny joke about chickens."
If the prompt has no variables, from_template builds one without an input_variables list, and the resulting input_variables is an empty array:
prompt = Langchain::Prompt::PromptTemplate.from_template("Tell me a funny joke about chickens.")
prompt.input_variables # []
The repository also carries example scripts for few shot templates and for templates paired with a structured output parser, named create_and_manage_few_shot_prompt_templates.rb and create_and_manage_prompt_templates_using_structured_output_parser.rb. Templates are plain string substitution, so they do not validate that the model's answer matches a shape. That job belongs to the output parsers, which the table of contents lists as a separate section.
Rails integration is a different gem, and this one has no web layer
The first line under the README title points elsewhere: for deep Rails integration, use the langchainrb_rails gem. Langchainrb itself is a library of LLM classes, prompts, parsers, vector search, assistants and evaluations. It does not ship controllers, generators or ActiveRecord hooks. If your goal is a Rails app with embeddings stored beside your models, you are installing two gems and reading two sets of documentation. The use cases the README names are retrieval augmented generation with vector search, and assistants for chat bots. The example scripts show the shape of that work: assistant_chat.rb, openai_qdrant_function_calls.rb, pdf_store_and_query_with_chroma.rb, and store_and_query scripts for Milvus, pgvector with metadata, Pinecone, Qdrant and Weaviate. Each one needs its own URL or key in the environment, for instance CHROMA_URL, MILVUS_URL=http://localhost:19530, PINECONE_API_KEY with PINECONE_ENVIRONMENT, POSTGRES_URL, QDRANT_URL with QDRANT_API_KEY, or WEAVIATE_URL with WEAVIATE_API_KEY. Running a vector database is outside what the gem does for you.
The newest tagged release is from May 2025, so read the CHANGELOG before trusting a feature
The repository is not archived, and the last push landed on 21 October 2026. The most recent releases are 0.19.5 on 1 May 2025, 0.19.4 on 17 February 2025 and 0.19.3 on 13 January 2025. That gap matters in practice. Commits on the main branch since 0.19.5 are not in the gem you get from bundle add langchainrb unless a newer version has been published, so a fix you see on GitHub may not be in your install. In a field where providers rename models and change request formats often, a gem tied to eleven different vendors needs its own changes to keep up, and each provider class can drift independently. The repository includes a CHANGELOG.md, a spec directory and a lefthook.yml for local checks, so read the changelog for your provider before choosing it, and pin the version in your Gemfile. The project is MIT licensed, and the maintainer advertises paid consulting engagements in the README, which tells you where to ask for help beyond the Discord server and the RubyDoc pages.
Editorial conclusion
Use Langchainrb if you are a Ruby team that wants to change LLM vendors by changing one constructor line and you are happy to add the vendor and vector store gems yourself. Skip it if you need Rails wiring out of the box, since that lives in langchainrb_rails, and check the CHANGELOG against your provider before relying on a feature, because the latest tagged release is 0.19.5 from May 2025.
Frequently asked questions
What is Langchainrb used for?
Langchainrb is a Ruby gem for building LLM-powered applications. Its listed use cases are retrieval augmented generation with vector search, and assistants such as chat bots.
Which LLM providers does Langchainrb support?
The supported providers are Anthropic, AWS Bedrock, Azure OpenAI, Cohere, Google Gemini, Google Vertex AI, HuggingFace, Mistral AI, Ollama, OpenAI and Replicate. All of them inherit from Langchain::LLM::Base.
How do I install Langchainrb?
Run bundle add langchainrb if Bundler manages your dependencies, or gem install langchainrb otherwise. Extra gems for providers and vector stores are not included and must be added separately.
Does Langchainrb work with Rails?
Langchainrb itself is not Rails specific. For deep Rails integration the project points to a separate gem called langchainrb_rails.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/patterns-ai-core-langchainrb)Star history chart for your README
[](https://hysenlabs.com/projects/patterns-ai-core-langchainrb)Was this useful?