pytorch-cpp builds from Ubuntu 18.04, and its compose file declares no command
C++ Implementation of PyTorch Tutorials for Everyone
At a glance
- What is it?
- pytorch-cpp is a C++ port of a well known Python tutorial series: thirteen compiled tutorials across three levels, plus notebooks. Its documentation covers Colab and a local machine and never mentions the container files in the repository, while those container files pin a 2018 base image, a fixed user id, and a compose service with nothing to run.
- Who is it for?
- pytorch-cpp fits someone learning the C++ frontend of PyTorch who wants a working example per concept and already has the toolchain, since every tutorial is a single readable source file. It fits someone who wants a maintained library less well, because the project is a tutorial port and its release tags track upstream framework versions rather than its own.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
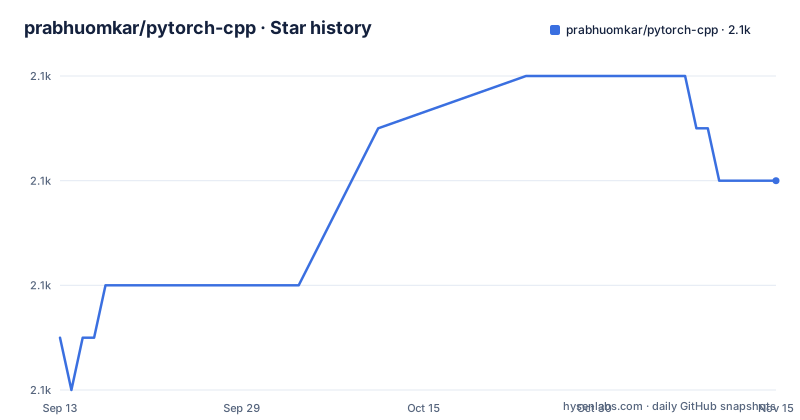
- prabhuomkar/pytorch-cpp2,140 ★ · +3
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| prabhuomkar/pytorch-cpp | 2.1k | 2.1k |
3 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The compose file builds an image and never says what to run in it
The repository carries a compose file, a container file and a docker directory, and the documentation mentions none of them.
The getting started section offers two routes: a hosted notebook for a browser, and a local machine route that clones and configures with CMake. There is no third route, and no sentence anywhere points at the container.
What the compose file contains is one service:
version: "3"

services:
  pytorch-cpp:
    build: .
    volumes:
      - .:/pytorch-cpp
    container_name: pytorch-cpp
It builds from the repository root and bind-mounts the whole checkout into the container at the path the container file uses as its working directory. It names the image and the container. And it specifies no command, no entrypoint override, no interactive flag and no port mapping.
So the compose file is a development shell container by convention rather than by configuration. Anyone who runs it expecting a tutorial to execute gets an image with no instruction attached, and anyone who wants the shell has to attach one themselves.
The build image starts from a 2018 distribution and a Python that reached end of life
The container file takes its base and its interpreter as build arguments, and both defaults are old.
ARG BASE_IMAGE=ubuntu:18.04
ARG PYTHON_VERSION=3.8
The framework version defaults are current, pinned to a specific release of the tensor library and its vision counterpart. So one file holds a 2018 operating system, a Python release that has been end of life for over a year, and a framework build from this year. Nothing in the file explains why the base needs to be old.
The build is staged in four steps. The first installs a compiler toolchain, curl, git and certificates. The second installs a distribution manager from a download whose URL ends in a filename that says latest, with automatic updates turned off afterwards. The third installs the framework for CPU only, from the framework's own channel. The fourth is the build itself.
That third step also sets an environment variable that disables CUDA for the whole image, which is consistent with the compose file having no device configuration. A user who wants the GPU path in a container has to change the build arguments, not just pass a runtime flag.
A hardcoded user id decides who owns the files in your checkout
The build stage creates a group and a user, and both ids come from build arguments that default to one thousand.
The user is created with a home directory and a login shell, that home is recursively given to the new user, the build switches to the new user, and the home variable is repointed at it. Everything after that point in the build runs unprivileged.
Combined with the compose file's bind mount of the entire repository into the container, that has a concrete effect on the host: files a build writes into the checkout are owned by uid and gid one thousand, whatever the host user's actual id is.
The container file's own header credits a blog post about running containers as the current host user, which suggests the intent was to avoid exactly this problem. The ids are build arguments, so a caller can override them, but neither the documentation nor the compose file does. A host user whose own id is not one thousand ends up with files they did not create and cannot easily delete.
Two rows of the options table disagree about what a bare configure does
The configure step takes six options and every one of them changes something expensive.
The first downloads a framework build for a chosen accelerator version, and its default is the value that means the CPU version. The last one takes a path to an existing local framework install, and its default is empty, described as skipping the download entirely and using your own local version instead.
Those two defaults cannot both describe what happens when you run configure with no arguments. Either an empty path means download the CPU build, or it means use whatever is already on the machine. The table says both, in adjacent rows, without saying which wins.
The other four defaults are at least consistent. Datasets are downloaded during the build by default, into a data directory at the repository root, and only when they are not already there. Script module files, which wrap pre-trained weights for the C++ side, default to off, and turning them on requires a Python installation with the framework and its vision package already present. That is a build-time dependency on a Python environment for a tutorial set written in C++, and it is the one that surprises people.
Windows needs the configuration flag appended to every build
The Windows path carries three separate warnings and they compound.
First, the framework only supports 64-bit Windows, so the generator has to be told to target the 64-bit architecture, and the note says to append a flag to the configure command for Visual Studio. That is because the default generator for a 64-bit host is not always a 64-bit generator.
Second, one of the six configure options is documented as relevant only on Windows: it chooses between a release and a debug build of the framework to download, and defaults to release. That flag is inert on the other two platforms because the frameworks there are single archives.
Third, and this is the one that bites later: the configure script downloads the release version, so the build command has to have the release configuration appended to it. That is a multi-configuration generator behaviour, and it applies to every build invocation, not just the first.
The two worked examples on the page make the asymmetry concrete. The Linux example assumes an existing Python and framework installation and asks you to create the script module files. The Windows example asks for nothing local and downloads a framework build for a specific accelerator version instead, and explicitly does not create the script modules.
The notebooks run on a nightly build while the tutorials are pinned
The project splits its content into three tutorial levels, one interactive section and one section of other tutorials that is a link rather than code.
The interactive section is a single notebook on tensor slicing, and it comes with its own warning. The interactive tutorials currently run against a nightly build of the framework, and the page says plainly that some tutorials can break when working with a nightly version. Nightly means the API can change under you between one day and the next.
The reason is structural rather than careless. A compiled tutorial is built against a specific framework version, and the project's release tags are named after framework versions, so pinning works there. A notebook is interpreted, and the tool used to run it is a C++ kernel for Jupyter installed from a community channel rather than a versioned dependency. Matching a nightly kernel to a released framework is not something the page attempts.
The notebook route therefore carries a different risk profile from the compiled one, and nothing in the getting started section separates them. The multi-target tip at the end of the build section, which would let you build several tutorials at once, is cut off partway through its command.
Tutorial paths disagree about where the source file lives
The table of contents links thirteen tutorial source files, and they are not laid out the same way.
Four of them sit directly in the tutorial folder, with the source file at that level. The other nine put the source file inside a nested source directory within the tutorial folder. So the path a contributor expects depends on which tutorial they open, and there is no rule on the page that explains the split.
The build target names are derived from the same folder names, and the page documents the transformation: the target is the folder name with underscores replaced by hyphens. Which means the target for the neural style transfer tutorial is spelled with hyphens even though its folder uses underscores, and that the nested source directories do not appear in target names at all.
The scope is stated in one line and it is narrower than the heading suggests. This repository provides tutorial code in C++ for researchers to learn the framework, covering sections one to three of an existing Python tutorial series, which is credited and linked. Sections four and five are not ports: one is a notebook, the other is a directory for a different tutorial series entirely.
Release tags are framework versions, and two of them were cut a minute apart
The tags do not count the project's own versions. They name framework versions.
The newest tag is two point fourteen, matching the framework release, and it was cut on the same day as the last push to the branch. Before it there are tags for two point eight and two point six, and both were published on the same date less than two minutes apart.
That pattern says backfill rather than release. Someone created two tags for framework versions that had already shipped, back to back, a year before the next one. A reader counting releases would see three and infer a cadence; the dates say the project moved from two point six to two point fourteen in one step.
The newest release name also carries a leading space before the framework name, which suggests it was generated from a variable rather than typed.
The continuous integration table follows the same logic. It has one column, for the current framework version, and three rows for operating system and compiler: macOS with one clang version, Linux with two gcc versions, and Windows with a named toolset version. So the matrix tracks upstream support rather than the project's own history, which is the right thing to test and the wrong thing to read as a changelog.
Editorial conclusion
pytorch-cpp fits someone learning the C++ frontend of PyTorch who wants a working example per concept and already has the toolchain, since every tutorial is a single readable source file. It fits someone who wants a maintained library less well, because the project is a tutorial port and its release tags track upstream framework versions rather than its own. Before using it, check four things. Read the options table rather than running configure with no arguments, because the default download behaviour is described in two contradictory ways. Decide whether you want the container, and if so build it with your own user id or accept files owned by another uid in your checkout. On Windows, append the release configuration flag to every build. And treat the interactive notebooks as a separate product, since they run against a nightly build while everything else is pinned.
Frequently asked questions
Is PyTorch in cpp?
This repository is the closest thing to a yes in tutorial form: a C++ port of an existing Python tutorial series, with thirteen compiled tutorials across three levels from basics through advanced, plus one interactive notebook. It is teaching code, not a library, and it tracks framework releases rather than its own versions.
What does pytorch-cpp require before you can build it?
A compiler with C++17 support, CMake at version 3.28.6 or newer, a framework distribution between version 1.12.0 and 2.14.0 inclusive, and a distribution manager for the interactive notebooks. The interactive notebooks additionally need a C++ Jupyter kernel installed from a community channel.
How do I build one tutorial instead of all of them in pytorch-cpp?
By category with a target such as basics, intermediate, advanced or popular, or by a single tutorial target. The page notes that the target argument is the tutorial's folder name with underscores replaced by hyphens, so the source file's nested location does not appear in the target name.
Does pytorch-cpp download datasets and models when I build it?
Datasets are downloaded during the build by default, into a data directory at the repository root, and only if they are not already present. Files wrapping pre-trained weights default to off, and enabling them requires a Python installation with the framework and its vision package available at build time.
What is the difference between pytorch-cpp on Windows and on Linux?
Windows needs a 64-bit generator flag appended to configure, has one option that only applies there to pick a release or debug framework build, and requires a release configuration flag appended to every build command because the configure step downloads the release build. The worked Linux example instead assumes an existing local Python and framework installation.
Is pytorch-cpp's Docker setup documented?
Not in the README. The getting started section offers only a hosted notebook route and a local machine route, while the repository carries a compose file, a container file and a docker directory. The compose file declares one service that builds the image and bind-mounts the checkout, but specifies no command to run.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/prabhuomkar-pytorch-cpp)Star history chart for your README
[](https://hysenlabs.com/projects/prabhuomkar-pytorch-cpp)Was this useful?