numpyro's manifest names a license file and a changelog that are not in the tree
Probabilistic programming with NumPy powered by JAX for autograd and JIT compilation to GPU/TPU/CPU.
At a glance
- What is it?
- numpyro is a NumPy backend for Pyro built on JAX, with No-U-Turn sampling and variational inference at its centre. Its pyproject.toml points the license at LICENSE and the changelog at a file on the main branch, and the repository root has neither, holding LICENSE.md on the master branch instead.
- Who is it for?
- numpyro earns its place if you are already on JAX and want NUTS with the integrator compiled, or need distributions that share PyTorch semantics and batching rules. Check two packaging details before you pin it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
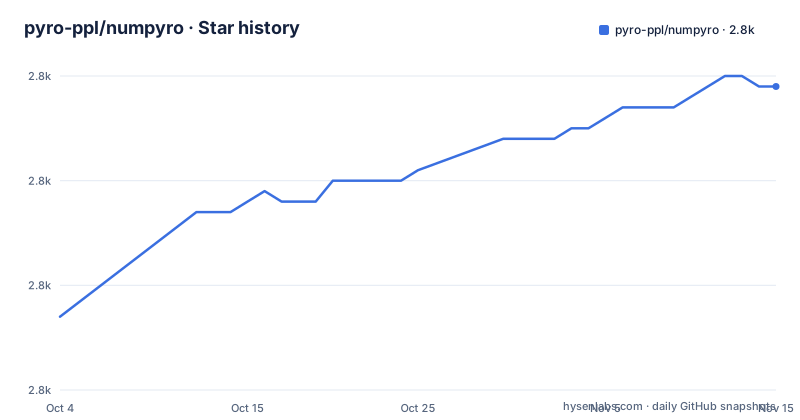
- pyro-ppl/numpyro2,779 ★ · +22
| Repository | 2026-10-04 | 2026-11-15 |
|---|---|---|
| pyro-ppl/numpyro | 2.8k | 2.8k |
22 Stars in the last 42 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The manifest names two files the repository root does not have
Two entries in pyproject.toml point at paths that are not in the top level listing. The license is declared in the old table form, license = { file = "LICENSE" }, and the root holds LICENSE.md instead, with no file called LICENSE beside it. The project URLs block goes further and names a changelog at a blob/main/CHANGELOG.md address, so it gets two things wrong at once: the repository's default branch is master, not main, and there is no CHANGELOG.md at the root either. The classifiers still carry the OSI identifier for the Apache Software License, so the licensing intent is not in doubt, but the file reference and the URL are both dead ends. That matters beyond tidiness, because the license file is what a build backend copies into the wheel.
The four extras are accelerator selectors, and none installs optax
optional-dependencies in the manifest contains exactly four entries: cpu, cuda12, cuda13, and tpu. Each one is a bracketed variant of jax at 0.7.0 or later and nothing else. There is no extra for the features the README spends most of its space on. Variational inference is advertised, with a basic implementation, many flexible guides for ADVI, and both TraceGraph_ELBO and TraceEnum_ELBO for models with discrete latent variables, and Optax appears only in the development dependency group. Optax must be installed separately when using an Optax optimizer; NumPyro SVI also accepts its own optimizer wrappers and JAX example optimizers without Optax. The cuda12 and cuda13 extras target different CUDA versions. Selecting an incompatible combination can cause installation or runtime errors, or leave acceleration unavailable; follow JAX's current installation guidance and verify the detected devices.
Every dependency carries a floor except numpy, tqdm, and multipledispatch
The runtime dependency list has five entries and they are not consistent about versions. jax and jaxlib both carry a floor of 0.7.0, which is the strongest constraint in the manifest and pins the project to a recent JAX generation. numpy has no specification at all, neither a floor nor a ceiling. multipledispatch is also bare, and it is the package that carries the effect handler dispatch described in the README. tqdm has no version either, which is worth noting because it is what puts progress bars on long MCMC and SVI runs. So a fresh resolve can move numpy underneath a fixed JAX without the manifest objecting. The development group is more disciplined in one respect, pinning jaxns to a closed range of 2.6.3 through 2.6.9 while leaving gpjax, optax, pandas, and pytest on open lower bounds.
make test runs ruff, a header check, and a type checker before pytest
The default target is all: test, and test is not just the test suite. It depends on lint, and lint is a forced target running ruff check, then ruff format with a check flag, then python scripts/update_headers.py with a check flag, then ty check. Only after all four does pytest run against the test directory. There is a FORCE target with an empty recipe at the bottom of the file, which is how lint, license, install, doctest, test, clean, docs, and notebooks are all made to re-run every time rather than being skipped when a file of the same name exists. The practical consequence is that a failing license header or a formatting nit blocks your test run, which is unusual but defensible, and it means a ty version bump can turn into a red build in a repository where nothing about types changed.
make clean is git clean with a dfx, not a build directory removal
The clean target runs git clean -dfx with a single exclusion, -e numpyro.egg-info. Read the flags rather than the target name. The d removes untracked directories, the f forces it, and the x extends it to files that gitignore hides. So this is not a build artifact sweep, it is a reset of the working tree to exactly what git tracks, and it will take out .venv directories, local build outputs, downloaded data, editor state, and anything else that is not committed. The one thing deliberately preserved is the egg-info directory, presumably so an editable install survives. It is a target worth reading before running, and worth never wiring into a script that runs automatically.
The eight schools walkthrough stops before it prints anything
The tutorial builds the classic eight schools model from Gelman and colleagues, defines mu and tau, opens a plate of size J, samples theta, and runs NUTS with 500 warmup steps and 1000 samples, collecting potential_energy through the extra_fields argument. It explains why extra_fields exists: by default only samples from the target distribution are collected, and fields such as potential energy or acceptance probability have to be requested. The run call itself looks like this:
>>> from jax import random
>>> from numpyro.infer import MCMC, NUTS

>>> nuts_kernel = NUTS(eight_schools)
>>> mcmc = MCMC(nuts_kernel, num_warmup=500, num_samples=1000)
>>> rng_key = random.key(0)
>>> mcmc.run(rng_key, J, sigma, y=y, extra_fields=('potential_energy',))
Then the text stops mid sentence, at we can print the summary of the MCMC run, and examine if we observed any. So the one worked example in the file demonstrates model definition and the run call, including the diagnostic field, and stops before it prints the summary or inspects anything. The print call itself is not in the visible text.
Two separate things get compiled, the integrator and the tree
The performance argument is stated as two mechanisms, and they are different. The first is the verlet integrator inside Hamiltonian Monte Carlo, which is where the gradient computations live. Composing jit with grad in JAX compiles the whole integration step into one XLA optimised kernel. The second is the tree building stage in NUTS, which normally costs Python overhead on every iteration, and that is compiled away too using an iterative NUTS construction. The stated motivation for the library existing at all was to speed up Hamiltonian Monte Carlo, so both optimisations sit on the same critical path rather than being incidental. Alongside that sit two MCMC variants beyond plain NUTS: MixedHMC, which can accommodate discrete latent variables, and HMCECS, which computes the likelihood only for subsets of the data on each iteration.
The distributions module follows PyTorch and borrows from TensorFlow Probability
The lineage of the distributions API is stated three times in one paragraph, and the three do not agree. The design largely follows PyTorch, a major subset of the API is implemented covering most of the common distributions that exist there, and the stated payoff is that Pyro and PyTorch users get the same API and the same batching semantics as torch.distributions. Underneath, the classes wrap samplers built for JAX's functional pseudo-random number generator, which is the part that differs from every other framework mentioned. Separately, distributions from TensorFlow Probability can be used directly in a model through the contrib namespace entry TFPDistribution, so a TFP habit does not have to be rewritten. Alongside the classes sit constraints and bijective transforms, which the README singles out as the tools for bounded support.
Editorial conclusion
numpyro earns its place if you are already on JAX and want NUTS with the integrator compiled, or need distributions that share PyTorch semantics and batching rules. Check two packaging details before you pin it. The license is declared as a file called LICENSE while the root holds LICENSE.md, and the changelog URL points at a main branch this repository does not use, so do not rely on either path when you audit a dependency. And if you plan to use variational inference, install optax yourself, because it appears only in the development dependency group while the extra list contains nothing but four accelerator selectors for JAX.
Frequently asked questions
What is NumPyro?
A lightweight probabilistic programming library that provides a NumPy backend for Pyro, relying on JAX for automatic differentiation and JIT compilation to GPU or CPU. NumPyro programs can contain ordinary Python and NumPy code alongside Pyro primitives such as sample and param, and the module name is numpyro. The project states plainly that it is under active development and warns of brittleness, bugs, and API changes as the design evolves.
How do you install NumPyro?
The README links installation to a documentation page rather than giving the command, but the manifest defines four extras that are accelerator selectors for JAX: cpu, cuda12, cuda13, and tpu. The manifest also requires Python 3.11 or later, and the Makefile installs the development set with pip install -e '.[dev,doc,test,examples]'.
What is the relationship between NumPyro and JAX?
JAX is a hard dependency, not an integration: both jax and jaxlib are required at 0.7.0 or later, which are the only runtime dependencies carrying version floors. NumPyro uses it for automatic differentiation and for compiling the verlet integrator in Hamiltonian Monte Carlo into an XLA optimised kernel, and for JIT compiling the NUTS tree building stage to remove Python overhead.
Is the NumPyro API the same as PyTorch distributions?
A major subset of it is, by design. The distributions module largely follows PyTorch, implements most of the common distributions that exist there, and is intended to give Pyro and PyTorch users the same API and batching semantics as torch.distributions. The samplers underneath are written for JAX's functional pseudo-random number generator instead.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pyro-ppl-numpyro)Star history chart for your README
[](https://hysenlabs.com/projects/pyro-ppl-numpyro)Was this useful?