pyspur: three organisation names and a production-mode example file
A visual playground for agentic workflows: Iterate over your agents 10x faster
At a glance
- What is it?
- A visual playground for agentic workflows, written mostly in TypeScript, extended in Python, whose own development instructions clone a different GitHub organisation than the one hosting them, and whose example environment file arrives in production mode with insecure OAuth transport switched on.
- Who is it for?
- PySpur is worth trying if you want to iterate on agent workflows in a UI with traces, breakpoints and evals rather than in a terminal, and it costs you a Postgres instance and a set of provider keys to do it well. Three things to check before you rely on it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 138 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
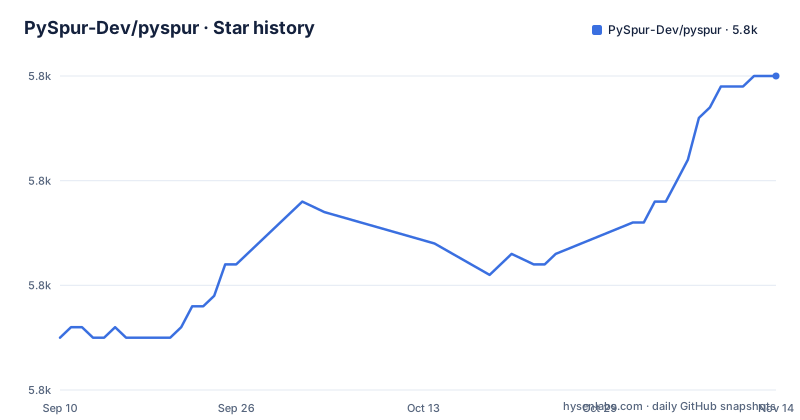
Star history
- PySpur-Dev/pyspur5,810 ★ · +25
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| PySpur-Dev/pyspur | 5.8k | 5.8k |
25 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The clone instructions point at a different organisation
The development setup gives one clone command:
git clone https://github.com/PySpur-com/pyspur.git
cd pyspur
That is one organisation name. The repository hosting this page is under another, and the example environment file names a third:
GITHUB_REPOSITORY=pyspur-dev/pyspurThe compose file reads that same variable, with `pyspur-dev/pyspur` as its fallback, to work out which container image to pull:
image: ghcr.io/${GITHUB_REPOSITORY:-pyspur-dev/pyspur}-backend:${VERSION:-latest}So a developer following the manual setup clones from `PySpur-com`, and a deployment built from that clone defaults to images under `pyspur-dev`, while the repository itself is hosted under the `PySpur-Dev` account. Renames and redirects make this survivable. What it costs is that the three names are not interchangeable in scripts, and the image path is assembled from a variable that a copied environment file silently supplies a value for.
The example environment file arrives in production mode
The repository ships an example environment file, and reading it top to bottom is the fastest way to understand what a default deployment looks like.
The first meaningful line sets the environment, and it is set to production. The development line sits directly above it, commented out.
# ENVIRONMENT=development
ENVIRONMENT=production
Two lines later, insecure transport is on, with a comment explaining it is there so OAuth2 works over http. Then the host is set to a wildcard address, so the application listens on every interface rather than loopback, and debug is off.
PYSPUR_HOST=0.0.0.0
PYSPUR_PORT=6080
DEBUG=False
The database block follows the same logic. The database name, the user name and the password are all the same word, and the host is the compose service name. Every model provider key in the file is commented out, which is the one default that is safe, and there is a commented line for pointing at any OpenAI compatible base URL.
The file then has an Ollama section with a note about reaching an Ollama service running on the host machine.
Compose loads the example file into the container as well as yours
The compose file reads two environment files for the backend, in this order:
env_file:
  - ./.env.example
  - ./.env
Your own file is listed second, so it wins where the two define the same key. The consequence is that the example file's values arrive regardless. A deployment with no local `.env` at all still gets production mode, insecure OAuth transport, the wildcard bind address and the placeholder database password, and a deployment that sets four of those keys in its own file still inherits the rest.
The rest of the service definition is ordinary. The container's command is a bash entrypoint script rather than the CLI. One port is published, from a variable that defaults to 6080, onto container port 8000. Two volumes are attached: the environment file itself, and a named volume for data such as uploaded files, evaluation outputs and datasets. An extra host mapping is declared so the container can reach services on your machine, which is what the Ollama note in the example file is pointing at.
The database service has a readiness check using the standard Postgres probe, and a restart policy. The backend service has neither.
The quick start runs sqlite, and the configuration only knows postgres
The installation path is four steps. Python 3.11 or higher is required, then:
pip install pyspurpyspur init my-project
cd my-projectThat creates a directory holding a `.env` file. Then the server starts:
pyspur serve --sqliteWhich brings the app up at `http://localhost:6080` on a sqlite database, and the very next sentence recommends configuring a Postgres instance URL in the `.env` file for a more stable experience. So the documented default is the one the project asks you to move away from.
The files in the repository agree with the recommendation rather than with the default. The example environment file has a Postgres block and states that PySpur uses PostgreSQL as the database. The compose file runs Postgres as its only database, on version 17 alpine, with a named volume for the data directory, and the backend waits for it to pass a health check before starting. There is a migration generation script at the root of the repository as well.
Eighteen months of commits behind a March 2025 tag
The release list is short and it is old. v0.1.16 was published on 2025-03-23. v0.1.17 followed on 2025-03-25 at 21:05, and v0.1.18 sixty-five minutes later the same evening at 22:10.
Two patch releases sixty-five minutes apart, then no further tags. The repository is not archived, and it was pushed to as recently as 2026-06-29, so roughly fifteen months of commits sit on the default branch with no tag behind them.
That gap has two consequences for anyone picking this up. The install line in the quick start installs from a package index, so it gives you whatever was last published there rather than the code in the repository. So the feature list on the page may not match the released artifact. Nothing on the page states a version requirement beyond Python 3.11, which means the compatibility question is left entirely to the reader.
The repository is mostly TypeScript and the extension point is Python
The primary language recorded for this repository is TypeScript. The product it serves is a Python tool. The feature list says new nodes are added by creating a single Python file, the server is started with a Python command line, and the development section recommends editor settings optimised for both Python and TypeScript.
The tree explains the split. There is a `backend/` and a `frontend/`, each with its own Dockerfile, plus an `nginx/` directory in front of them. Three compose files sit at the root, for the base stack, for development and for staging, and a shell script starts the stack in one step. A script for generating database migrations is checked in at the root as well, rather than living under a migrations directory.
The tooling configuration is just as layered: a pre-commit configuration, a Cursor directory, a dev container definition, and seven README files, one in English and six translations. The development section recommends the dev container as the primary route and offers the compose based setup as the manual alternative, while stating that Windows and PC development is not supported.
A ten times claim repeated three times, measured nowhere
The word ten appears in the project's own description, again in the bolded line at the top of the page, and the claim is that you can iterate over your agents ten times faster. No benchmark, dataset, agent, or comparison against a different tool appears anywhere on the page, so the number cannot be checked.
The rest of the feature list is more concrete and mostly self-explanatory: breakpoints that pause a workflow until a human approves it, iterative tool calling with memory, file upload or pasted URLs, a UI editor for JSON schemas, a retrieval pipeline that parses, chunks, embeds and upserts into a vector database, multimodal input, named integrations, automatically captured execution traces, evaluation against datasets, and publishing as an API. The same list advertises support for more than a hundred providers, embedders and vector databases, again without a list.
The project's own account of why it exists is the most honest paragraph on the page: the team shipped a graphic design agent in early 2024, reached thousands of users, and struggled with its reliability and with the debugging tools available. The roadmap section ends with a feature labelled as coming soon, self-improvement, with a video and nothing else.
Editorial conclusion
PySpur is worth trying if you want to iterate on agent workflows in a UI with traces, breakpoints and evals rather than in a terminal, and it costs you a Postgres instance and a set of provider keys to do it well. Three things to check before you rely on it. Pick a version deliberately, since the newest tag is from March 2025 while the repository has been pushed to as recently as June 2026, and the quick start installs whatever is on the package index rather than the code you are reading. Copy the example environment file only after editing it, because it arrives in production mode with insecure OAuth transport enabled and a wildcard bind address. And expect the documented default, sqlite, to be the path the project itself steers you away from.
Frequently asked questions
How do I install and run PySpur?
Python 3.11 or higher is required. Run `pip install pyspur`, then `pyspur init my-project`, `cd my-project`, and `pyspur serve --sqlite`, which serves the app at `http://localhost:6080` on sqlite. The page recommends configuring a postgres instance URL in the `.env` file instead for a more stable experience.
Does PySpur need an API key before it will start?
The example environment file ships with every provider key commented out, `ENVIRONMENT=production` and `DEBUG=False`. Keys can be added in the app's API Keys tab or by editing the `.env` file and restarting with `pyspur serve`.
Can I develop PySpur on Windows?
The development section is written for Unix-like systems and states that Windows and PC development is not supported. It recommends the dev container in Cursor or VS Code, or a manual setup that clones the repository and runs `docker compose -f docker-compose.dev.yml up --build -d` and then edits `.env` for PostgreSQL settings.
Which PySpur version should I install?
The newest tag is v0.1.18, published 2025-03-25, with v0.1.17 published sixty-five minutes earlier the same evening. The repository is not archived and was last pushed to on 2026-06-29, so the tagged release is well behind the default branch.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pyspur-dev-pyspur)Star history chart for your README
[](https://hysenlabs.com/projects/pyspur-dev-pyspur)Was this useful?