ExecuTorch: from torch.export capture to a right-sized .pte runtime
On-device AI across mobile, embedded and edge for PyTorch
At a glance
- What is it?
- ExecuTorch turns a PyTorch model into a .pte file per hardware target and a runtime that links only the kernels that deployment needs. Where the platform coverage ends, where the .pte compatibility promise stops, and which vendor toolchains you still have to install are the decisions this repository actually settles.
- Who is it for?
- ExecuTorch fits teams that already train in PyTorch and can name a runtime window for every .pte they ship. It does not fit anyone expecting one binary to cover every vendor NPU.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
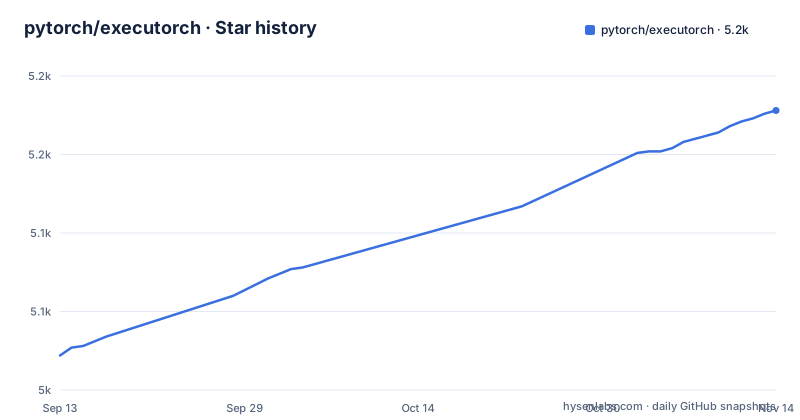
Star history
- pytorch/executorch5,178 ★ · +156
| Repository | 2026-09-13 | 2026-11-14 |
|---|---|---|
| pytorch/executorch | 5k | 5.2k |
156 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
torch.export capture, then one .pte per hardware target
ExecuTorch is PyTorch's open source stack for running models on the device, and its pipeline has three fixed steps: capture a PyTorch model with torch.export, optimize it for the target hardware, then call the result from C++, Python, Swift/Objective-C, Kotlin/Java or JavaScript. The deployment unit is a file with the .pte extension, produced per target, so one Python model can end up as several binaries that differ in which hardware they lean on. Acceleration is partitioned rather than all or nothing: supported graph regions are delegated to CPU, GPU, NPU or DSP backends while portable CPU kernels stay in place as fallback. Staying on torch.export also keeps PyTorch program metadata and source mappings available to export and debugging tools, which is what you want when a model misbehaves on a phone and not in a notebook. The README names torch.export as the capture path, and the artifact is a .pte.
Selective build decides what links into the runtime
A full inference runtime is larger than the model it serves, so ExecuTorch's answer is that you link only the operators, kernels and delegates a deployment needs. Selective build is the name given to this, and examples/selective_build/ sits in the tree beside apple/, arduino/, cuda/, qualcomm/ and the other platform directories. Two things follow. Binary size becomes a build configuration choice instead of something you trim afterwards. And the operator set becomes yours to get right, because deployment depends on torch.export capture plus operator, runtime and selected-backend coverage. The README is careful on this point too, calling its own workload table a set of starting points rather than a compatibility list.
ETDump and ETRecord for when the numbers come out wrong
Numerical debugging has named instruments: ETDump for what a program executes, ETRecord for a record of it, and the model debugging pages for numeric debugging, with custom operators and backends as the extension point. These exist because ExecuTorch spreads a single model across several execution providers. Once a region runs on an NPU delegate instead of the CPU kernels, an accuracy difference has somewhere to come from and no obvious explanation attached to it. The instruction in the README is to validate numerical accuracy, memory use and performance on the target, and this is the tooling for answering why a number moved. For compatibility questions, the runtime compatibility file and the API lifecycle policy are the documents to read.
Three pip commands, and the one that can downgrade your PyTorch
Installation starts in a Python 3.11 to 3.15 environment with the stable package:
pip install executorchNightlies come from main and take a longer command, where torch is named explicitly because nightly ExecuTorch wheels do not declare it as a dependency:
pip install --upgrade --pre executorch torch --extra-index-url https://download.pytorch.org/whl/nightly/cpuThat second line is a trap on a Linux machine with an NVIDIA GPU. It installs a CPU-only PyTorch nightly, and pip can replace a CUDA-enabled PyTorch installation with the CPU build. The fix the README gives is to pick the command matching your CUDA version in the PyTorch installation selector and use its nightly/cu* index instead, and it states that ExecuTorch CUDA wheels are published for Linux only. Backend export tools pull their own extras, Ethos-U ahead-of-time export being the example:
pip install 'executorch[ethos_u]'Embedded toolchains, simulators and target runtimes install separately, so a Cortex-M or Pico workflow is never one command. The prebuilt Python wheel is published for platforms including Linux x86-64, Linux AArch64 and macOS arm64.
make targets build a runner into cmake-out/examples/models
Building from source is where the repository layout becomes the documentation. The Makefile offers the shortcut: targets named model plus backend, which build the ExecuTorch core libraries with that backend and a model-specific runner executable under cmake-out/examples/models/<model>/.
make llama-cpu
make voxtral-cuda
make whisper-metal
make help lists what exists and make clean removes the artifacts. The comment block pairs each model with the backends it has, from silero_vad on CPU to whisper on CPU, CUDA and Metal, so the target name is where backend availability shows up first. Underneath, pyproject.toml asks for cmake>=3.26,<4.0.0 off Windows and cmake>=3.27 on Windows, packaging>=24.2, setuptools>=77.0.3, and patchelf on Linux to write the runtime search paths that let the shipped libraries find each other. Dependencies are dynamic because they vary by build mode: the EXECUTORCH_BUILD_MINIMAL wheel declares a slimmer runtime set. The wheel metadata declares BSD-3-Clause, and setup.py points at the LICENSE file in the repository root.
A .pte survives exactly one following non-patch runtime release
The artifact carries a promise with a short fuse. A .pte created with stable APIs is guaranteed to load and execute for at least one following non-patch runtime release, and the runtime compatibility file plus the API lifecycle policy define where the edges are. Set that against a release history of v1.4.1 on 2026-08-14, v1.5.0 on 2026-09-16 and v1.5.1 on 2026-09-23, with the last push to the repository on 2026-11-02. Because the guarantee is written in terms of the next non-patch release, a patch update stays inside the window and so does the next non-patch release; the one after that is the first the guarantee does not cover. The practical effect lands on release engineering: every .pte in the field names a runtime it survives, and an app fleet spread across minor versions means keeping several runtimes alive.
Vendor NPU toolchains still ship from the vendor
ExecuTorch does not replace the accelerator toolchains underneath it, and the embedded row of the workload table makes that plain: Cortex-M CPU kernels, Ethos-U and NXP NPUs, Cadence DSPs, Zephyr, Arduino and Raspberry Pi Pico workflows. Those vendor tools still arrive from the vendor, which is why embedded toolchains, simulators and target runtimes install separately from the Python package. That is the difference in approach worth weighing against a vendor SDK: your model and export flow stay in PyTorch and you get a .pte per specialized target, while everything below the runtime boundary is somebody else's install. The decision rests on two things you can check here: whether your operators exist for the backend you need, and whether the prebuilt wheel covers your platform. Arriving with a TorchScript mental model, the artifact is what changes: a .pte governed by the compatibility window above.
An experimental LLM server and no browser example in the tree
One edge of the stack is flagged as experimental. The LLM workload row lists an experimental OpenAI-compatible local server under examples/llm_server/, and the README calls it experimental, which is the word to weigh before routing product traffic through it. For a new language-model architecture, the README sends you to a custom LLM guide rather than to a flag, and the tree carries examples/llm_manual/ and examples/llm_pte_finetuning/ beside the model runners, so adapting an architecture is a project rather than a configuration. Coverage is the theme running through all of it: operator, runtime and selected-backend coverage decide whether your model runs at all.
Editorial conclusion
ExecuTorch fits teams that already train in PyTorch and can name a runtime window for every .pte they ship. It does not fit anyone expecting one binary to cover every vendor NPU. Check two things before you export: that your operations have kernel coverage in the backend you picked, and that the runtime version you pin is the one the .pte was built against, because the guarantee covers at least the next non-patch release.
Frequently asked questions
What is ExecuTorch?
It is PyTorch's open source stack for running AI locally on phones, wearables, laptops, browsers, embedded systems and microcontrollers. You start with a PyTorch model, capture it with torch.export, optimize it for target hardware, and run it through C++, Python, Swift/Objective-C, Kotlin/Java or JavaScript APIs.
How do I install ExecuTorch?
In a Python 3.11 to 3.15 environment, run pip install executorch. Nightly builds from main need a longer command that names torch explicitly, because nightly ExecuTorch wheels do not declare it as a dependency, and the prebuilt wheel is published for platforms including Linux x86-64, Linux AArch64 and macOS arm64.
How do I use ExecuTorch?
Capture a PyTorch model with torch.export, optimize it for the target hardware, and call it through the C++, Python, Swift/Objective-C, Kotlin/Java or JavaScript API for your platform. The repository carries per-vendor examples such as examples/apple/, examples/arduino/, examples/cuda/ and examples/qualcomm/.
What are the key differences between ExecuTorch and TorchScript?
The README documents torch.export as the capture path and a .pte file as the artifact, and it attaches a versioned contract to that file: a .pte made with stable APIs is guaranteed to load and execute for at least one following non-patch runtime release.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pytorch-executorch)Star history chart for your README
[](https://hysenlabs.com/projects/pytorch-executorch)Was this useful?