NeuTTS: on-device voice cloning with a 120m to 360m backbone
On-device TTS model by Neuphonic
At a glance
- What is it?
- Neuphonic ships NeuTTS as a family of small speech language models with GGUF quantisations and a 50hz codec. The pitch is local inference and cloning from three seconds of audio; the catch is a custom licence on every model except Air.
- Who is it for?
- Adopt NeuTTS if you need speech synthesis that runs on the user's own device, you can accept phoneme input for Air and Nano, and you have read the NeuTTS Open License 1.0 that covers everything except Air. Do not adopt it if you need streaming from the PyTorch path, a documented rollback story, or a licence you can skim.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 108 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
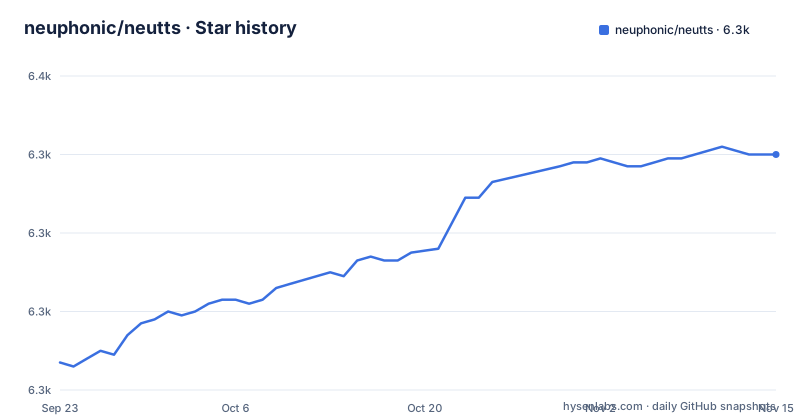
- neuphonic/neutts6,340 ★ · +53
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| neuphonic/neutts | 6.3k | 6.3k |
53 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem NeuTTS targets: speech that never leaves the device
The README opens with a complaint: state-of-the-art voice AI has been locked behind web APIs. NeuTTS is Neuphonic's answer, a collection of open source speech language models meant to run locally. The intended audience is narrow and specific. It is for people building embedded voice agents, assistants, toys, and what the README calls compliance-safe apps, where sending audio to a remote endpoint is either too slow, too expensive, or not allowed.
The models are small by design. NeuTTS-Air has roughly 360m active parameters, the Nano models roughly 120m, and NeuTTS-2E roughly 125m. That is the whole point: a model that fits on a phone or a Raspberry Pi, not one that needs a datacentre. Cloning is the second hook. The README claims a speaker can be created from as little as 3 seconds of audio, which puts it in the same territory as hosted cloning services but without the upload.
How the LM plus codec architecture actually splits the work
NeuTTS is not a single model. It is a backbone paired with a codec, and the two are chosen independently. The backbone is a small LLM that predicts audio tokens; the codec, NeuCodec, turns those tokens into a waveform. NeuCodec is described as a 50hz neural audio codec using a single codebook, which is what keeps the bitrate low enough for on-device use.
The pairing matters because the tables list four codec variants with different capabilities. `neuphonic/neucodec` and `neuphonic/distill-neucodec` run on PyTorch and can both encode and decode. `neuphonic/neucodec-onnx-decoder` and `neuphonic/neucodec-onnx-decoder-int8` are ONNX and decode only. That asymmetry has a real consequence: if you pick a decoder-only ONNX codec, you cannot encode a new reference clip at runtime, so the reference audio must already be encoded. The README states that pre-encoded references ship with the repository for all bundled voices, including the NeuTTS-2E speakers. Anything outside that set is on you.
Input format is the other split worth knowing. NeuTTS-Air and the Nano models take phonemes. NeuTTS-2E takes text. That is not a cosmetic difference: phoneme input means a grapheme-to-phoneme step somewhere in your pipeline, and the `phonemizer` dependency in `pyproject.toml` is where that lives. NeuTTS-2E trades that step for a smaller speaker set, four fixed speakers rather than open cloning, plus six emotions and a neutral state.
Installing NeuTTS and generating a first clip
The package is published as `neutts` and requires Python 3.10 up to but not including 3.14. The build backend is scikit-build-core, and the CMake configuration copies an `espeak-ng-data` directory into the package, which is the phonemisation data. Core dependencies include `torch>=2.8.0`, `transformers==5.1.0`, `librosa`, `soundfile`, and `neucodec>=0.0.4`.
The `pyproject.toml` defines three optional dependency groups: `llama` for `llama-cpp-python` and `gguf`, `onnx` for `onnxruntime`, and `all` for all three. The repository ships `examples/basic_example.py` and `examples/basic_streaming_example.py`, plus emotion variants, which is where a first run should start. The examples directory also contains `examples/encode_reference.py`, which is the script to reach for if you intend to use a decoder-only codec and need to pre-encode a reference clip.
The repository has no published releases, so treat the example files as the authoritative usage reference.
What the benchmark table measures, and what it leaves out
The README publishes throughput numbers for the Q4_0 quantisations of Air and Nano, measured with `llama-bench` from llama.cpp on CPU and with vLLM on an RTX 4090. On a Galaxy A25 5G, Air reaches 20 tokens/s and Nano 45 tokens/s. On an AMD Ryzen 9 HX 370, 119 and 221. On an iMac M4 16GB, 111 and 195. The GPU figure is 16194 and 19268 tokens/s respectively.
Read the caveats before quoting any of these. The README states that the benchmarks cover only the speech language model and do not include the codec, so end-to-end latency will be higher than the token rates suggest. The numbers assume 500 prefill tokens and 250 generated tokens, with 14 threads for prefill and 16 for decode on the Ryzen and M4, and 6 threads each on the Galaxy. Those are benchmark conditions, not a default configuration you inherit.
The context window is 2048 tokens, which the README says is enough for roughly 30 seconds of audio including the prompt duration. That is the hard ceiling on a single generation, and it is the constraint most likely to bite in practice, because the prompt audio for cloning is counted inside it.
Where NeuTTS is the wrong tool
Streaming is the clearest limitation. The backbone table marks streaming as GGUF only, so the PyTorch path does not stream. If your application needs low time-to-first-audio and you were planning to stay on PyTorch, this project does not offer that combination.
Cloning is the second boundary. Open cloning is available on Air and the Nano models, but NeuTTS-2E is limited to four fixed speakers. If your requirement is expressive control over an arbitrary voice, 2E gives you six emotions plus neutral but not the voice you want. If your requirement is an arbitrary voice, Air or Nano gives you cloning but no emotion dimension.
The context window is the third. Thirty seconds including the prompt is not a lot for narration, and it means long text must be chunked, with all the prosody seams that implies. Finally, the README carries a caution that sites such as neutts.com are not affiliated with Neuphonic, and states that the project is on neuphonic.com only. If you are auditing a dependency, that warning is worth taking literally: the model weights live on HuggingFace under the `neuphonic` namespace, and that is the source to trust.
NeuTTS versus Piper and edge-tts
Piper is the obvious comparison for anyone shopping in this category, and the difference is architectural. Piper is a conventional TTS system built around fixed voices you download. NeuTTS is built off LLM backbones and treats cloning as a first-class feature, with the reference clip encoded through NeuCodec. If you need a stable, predictable voice and nothing else, Piper's model of shipping a voice file is simpler than pairing a backbone with a codec and managing reference encodings.
edge-tts is a different proposition again. It is a client for a hosted service, so the audio is generated remotely. NeuTTS exists precisely to avoid that, which is why the README frames the project as an escape from web APIs. The trade is real: a hosted service does not care about your device's token throughput, and NeuTTS does. On a Galaxy A25 5G at 45 tokens/s for Nano, generation is happening on the device in real time, not instantly.
The honest framing is that NeuTTS competes on deployment location, not on peak quality. The README claims best-in-class realism for their size, which is a claim scoped to model size. Whether that holds for your language and your listeners is something only your own listening test settles.
Licence and maintenance: read this before you ship
The licence situation is the part most likely to cause a surprise. NeuTTS-Air is Apache 2.0. Every other model in the family, including the Nano collection and NeuTTS-2E, is under the NeuTTS Open License 1.0. The repository's own LICENSE file is flagged as NOASSERTION by the tooling, which means the licence could not be automatically classified. That is a signal to open the file and read it, not to assume it matches the README table. This is not legal advice; if the distinction matters to your product, get it reviewed.
On maintenance, the last push to the default branch was on 2026-07-30. The repository is not archived. The repository has no published GitHub releases, so there is nothing to say about a version history beyond the `version = "1.4.1"` declared in `pyproject.toml`. The presence of `TRAINING.md`, `examples/finetune.py`, and `examples/finetune_config.yaml` indicates the project documents a fine-tuning path, which is relevant to upgrade cost: if you fine-tune, you are tracking upstream changes to both the backbone and the codec, and the codec is versioned separately (`neucodec>=0.0.4`). A codec upgrade that changes token semantics would invalidate a fine-tune. Pin both.
Editorial conclusion
Adopt NeuTTS if you need speech synthesis that runs on the user's own device, you can accept phoneme input for Air and Nano, and you have read the NeuTTS Open License 1.0 that covers everything except Air. Do not adopt it if you need streaming from the PyTorch path, a documented rollback story, or a licence you can skim. Before committing, verify which backbone and codec pair your target device can actually run, and check the licence text for the specific model you download.
Frequently asked questions
Is NeuTTS good?
The README claims best-in-class realism for the model size, and publishes throughput numbers for the Q4_0 quantisations on four devices. Those benchmarks cover only the speech language model and exclude the codec, so they do not tell you end-to-end latency. Whether it is good enough for your use depends on your language and your listeners.
How does NeuTTS compare with edge-tts?
edge-tts generates speech through a hosted service, while NeuTTS is designed to run on the local device. That difference drives everything else: NeuTTS depends on your hardware's token throughput, and the README gives 45 tokens/s for Nano on a Galaxy A25 5G.
How does NeuTTS compare with Piper?
Piper ships fixed voices you download. NeuTTS is built off LLM backbones and treats cloning as a core feature, with reference audio encoded through NeuCodec. If you only need a stable voice, Piper's model is simpler than managing a backbone and codec pair.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/neuphonic-neutts)Star history chart for your README
[](https://hysenlabs.com/projects/neuphonic-neutts)Was this useful?