Torch-TensorRT: two deploy formats, a Python cap justified by a third-party wheel, and a flag that only picks tests
PyTorch/TorchScript/FX compiler for NVIDIA GPUs using TensorRT
At a glance
- What is it?
- A compiler that turns PyTorch and TorchScript modules into TensorRT engines, reachable as a single compiler backend argument or as a serialized artefact you deploy to Python or to C++. The support table, the package metadata and the build script do not agree with each other about which platforms and which interpreter versions are actually covered.
- Who is it for?
- Adopt this when you are already on NVIDIA hardware and want inference latency improvement without leaving PyTorch, and choose the compiler backend route if you never deploy outside Python. Three things to check first.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
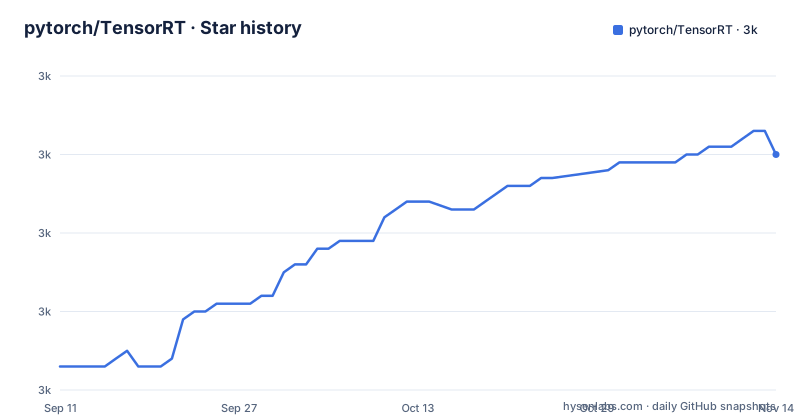
Star history
- pytorch/TensorRT3,020 ★ · +27
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| pytorch/TensorRT | 3k | 3k |
27 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two serialized formats exist because one of them cannot leave Python
The export workflow writes two files from one optimized module, and the difference between them is the deployment target. The example compiles with a named intermediate representation and a list of representative inputs, then saves twice:
trt_gm = torch_tensorrt.compile(model, ir="dynamo", inputs=inputs)
torch_tensorrt.save(trt_gm, "trt.ep", inputs=inputs) # PyTorch only supports Python runtime for an ExportedProgram. For C++ deployment, use a TorchScript file
torch_tensorrt.save(trt_gm, "trt.ts", output_format="torchscript", inputs=inputs)
The comment is the whole explanation and it is buried in a code sample. The exported-program file loads back through the standard export loader and is Python only. The script-format file loads through the JIT loader and is what the C++ sample uses, with a header for the scripting module and one for the runtime. So the artefact you keep is decided by where the model will run, not by which is faster, and picking the wrong one costs you the C++ deployment option entirely.
Windows is supported on one path, and macOS is not in the table at all
The platform table has six rows and each one carries a different qualification. Linux on two architectures is simply supported. Windows is supported with an explicit restriction to one code path. The two Jetson rows are supported only by compiling from source on a particular release. One architecture is marked not supported outright. Two things are worth noticing. The restriction on Windows is the same word used for one of the intermediate representations elsewhere in the project, so a reader has to know that term to learn what Windows actually supports. And there is no row for macOS at all, not a row saying unsupported, simply no row, so anyone on a Mac reads the table and finds nothing rather than an answer.
The Python upper bound exists because a third-party wheel stops at 3.14
The package metadata caps the interpreter, and the comment above the cap explains why in unusual detail. The stated reason is that the resolver has to find a solution for every version the range admits, and a pinned dependency ships no wheel above one version, so leaving the upper bound open fails the lock on a version nothing supports. The comment then adds that the list of required environments already stops one version lower than the cap. So the range admits a Python version that no test environment covers, and the reason the cap exists is a wheel published by something else. That is a more honest explanation than most packages give, and it is also a reminder that the build constraints of a dependency chain are what actually set your interpreter range.
The build script imports a module that newer supported interpreters removed
The build script's imports include a command class from the distribution utilities module that Python removed from the standard library in a version this package explicitly supports. The declared range starts at a much older interpreter and runs up to the cap discussed above, so the range includes interpreters newer than the one that dropped that module. Whether an install still works depends on the packaging tooling vendoring a replacement, which it commonly does, but nothing in the repository's own files says so. Two smaller signals in the same file point the same way: it imports a wheel building command from a path the packaging project has since deprecated, and it defines several version variables as placeholder strings filled in later. It also reads a git revision with a bare exception handler that prints a warning and falls back to a fixed value.
The variant flag changes which tests run, not which build you have
The build file has a variable that looks like a backend selector and says so in a comment, and the comment is emphatic that it is not one. It selects between a standard run and an alternative run, and it does so by choosing which tests execute, with different flags for one group of them. It explicitly does not switch the installed build, and to run that variant locally you have to already have a separate build installed with a specific environment flag turned on. So a person who reads the variable name, sets it, and runs the suite gets a different test selection against the same binary they had before. It is the kind of flag that makes a green run easy to over-interpret, and the comment exists precisely because someone has already been misled.
A shared temporary directory is a documented multi-user failure mode
The build file spends a paragraph on a filesystem problem, and the paragraph is worth reading because the failure is confusing when it happens. The engine and timing cache lives under a per-user temporary path derived from the user name, and the reason is that on a shared host the default location is created by whoever runs first and then fails for everybody else with a permission error. The fix is to give each user their own temporary directory, which the file does by defaulting the variable to a path containing the user name. The same file sets the parallel job count to four and explains why: the suites build engines, which are memory heavy on the graphics device, and a single device runs out before it runs out of processor cores, so asking for one job per core is the wrong default here.
Metadata says Linux only while the support table lists Windows
The two disagree. The classifier list in the package metadata names one operating system, and it is the Linux one. The support table in the documentation lists Windows as supported, with a restriction. A package index will therefore show this as a Linux package, and a Windows developer reading the table will find the platform listed and then find no wheel promised by the metadata for it. The licence is expressed differently in the two places too: the metadata uses the file form rather than a named licence string, while the classifier names the BSD licence and the documentation says a BSD style licence without naming a variant. Both source files carry a machine-readable licence identifier and a company copyright line, which is the clearest statement of terms anywhere in the repository.
Deprecation runs on a six-month clock and warns at runtime
The deprecation policy is one of the more precisely written sections in the documentation, and it has five parts. Notices appear in the release notes. A deprecated function carries a statement in the source recording when it was deprecated. A deprecated method or class emits a warning at runtime when used. There is a six-month migration period, during which the API keeps working. And after that period ends the API is removed in a way consistent with semantic versioning. The runtime warning is the part with teeth: it means a deprecation reaches you in your own logs rather than only in a changelog you did not read, which is what makes a six-month clock enforceable rather than aspirational.
Editorial conclusion
Adopt this when you are already on NVIDIA hardware and want inference latency improvement without leaving PyTorch, and choose the compiler backend route if you never deploy outside Python. Three things to check first. If you deploy to C++ you must serialize the script-format artefact rather than the exported-program one, and that constraint is stated in a code comment rather than in prose. The declared Python range includes versions the build script may not import cleanly on. And the variant flag in the build file looks like it selects a backend but only selects which tests run, so read it before assuming a local run exercises what you think it does.
Frequently asked questions
What is pytorch/TensorRT, also called Torch-TensorRT?
It is a compiler that brings TensorRT to PyTorch, turning PyTorch, TorchScript and FX modules into TensorRT engines while leaving the model a PyTorch module. The README states it can accelerate inference latency by up to five times against eager execution, and it is reached either as a compiler backend or through an export workflow.
Is TensorRT a part of NVIDIA?
The repository presents it that way. The package metadata lists NVIDIA Corporation as the author, both source files carry a machine-readable licence identifier and an NVIDIA copyright line, and the documentation points at NVIDIA's developer download page, NVIDIA's container catalogue and NVIDIA's own TensorRT repository.
how to use tensorrt with pytorch
There are two documented routes. The first passes the TensorRT backend name to the PyTorch compiler call, which compiles on the first run and is fast afterwards. The second compiles explicitly with a list of representative inputs and serializes the result, either to an exported program for Python or to a script-format file for C++ deployment.
Which platforms does Torch-TensorRT support?
The table lists Linux on two architectures as supported, Windows as supported on one code path only, two Jetson entries as supported by compiling from source on a particular release, and one architecture as not supported. There is no row for macOS. The package metadata names only the Linux operating system among its classifiers.
How does Torch-TensorRT handle deprecation?
Notices go in the release notes, deprecated functions document the date in the source, and deprecated methods and classes emit a warning at runtime. There is a six-month migration period during which the API keeps working, after which it is removed consistent with semantic versioning.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pytorch-tensorrt)Star history chart for your README
[](https://hysenlabs.com/projects/pytorch-tensorrt)Was this useful?