dive-into-spring-ai runs a Java, Node, MySQL, Redis-Stack and Neo4j stack
A hands-on Spring AI tutorial covering SSE streaming, AI agents, knowledge-graph RAG, function calling, chat history, image generation, image understanding, embeddings, vector databases, and RAG.
At a glance
- What is it?
- A Chinese-language Spring AI teaching project that puts SSE streaming, agents, function calling, embeddings, vector search, RAG, graph RAG, message history and image work into one Maven module. The interesting part for a reader is the infrastructure bill: four backing services, two of them in Docker, and one IntelliJ step that blocks the first compile.
- Who is it for?
- Take this project if you want a runnable Spring AI sample that reaches graph RAG and function calling without assembling the vector store and the graph database yourself, and read it as teaching material rather than as a library, since the tree is one Maven module with a SQL dump and a front end rather than a reusable artifact.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 10 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
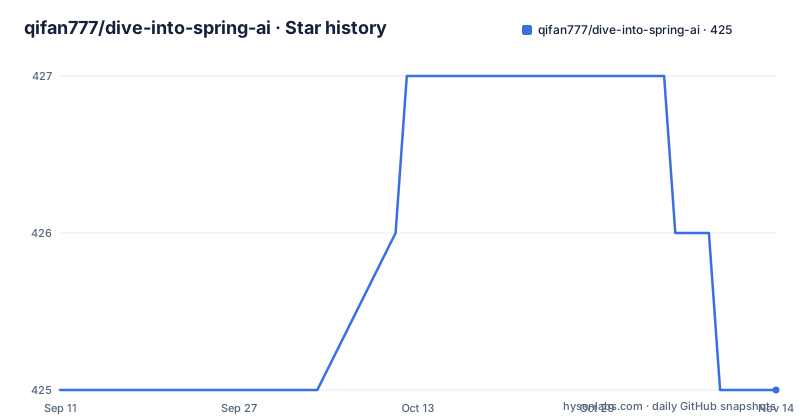
- qifan777/dive-into-spring-ai425 ★ · +0
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| qifan777/dive-into-spring-ai | 425 | 425 |
0 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Ten Spring AI topics in one Maven module
The repository is a single teaching project, not a library. It is a Java project built with Maven, with a `pom.xml` at the root, sources under `src/`, a `database.sql` schema dump, and a `front-end/` directory holding the client.
The subject list is what the README leads with, and it runs to ten entries: SSE streaming, agents, function calling, embeddings, a vector database, RAG, graph RAG, message history, image generation, and image understanding. The repository description carries a slightly different list that adds a knowledge graph RAG entry next to plain RAG, so treat the two lists as the same set described twice rather than as two different scopes.
Written material sits outside the tree. The documentation is at a separate blog site linked from the README, and there is a matching video course on Bilibili, so the repository is the code that accompanies the teaching rather than the teaching itself.
There is no `LICENSE` file in the tree and the repository reports no licence, which is worth settling before you copy any of it.
Five services before the first compile
The stated runtime requirements are Java 17, Node.js 18 or newer, MySQL 8, an API key for DashScope or another provider, Redis-Stack, and Neo4j 5 or newer. Redis-Stack is the one that needs a word of explanation: it is Redis extended with vector query capability, which is why the project needs it at all when MySQL is already present.
Two of these run as containers and the README gives the exact commands. The other three are assumed to exist already, and MySQL in particular needs a schema, which is what `database.sql` at the repository root is for. There is no migration tool named, so applying that dump is a manual step.
Neo4j comes with a browser UI on port 7474 and its own protocol port on 7687. The README states the default account and password are both `neo4j`, which is the pair to change before the port is reachable by anything other than your own machine.
The provider key is the fifth moving part. The README asks for a DashScope key or an equivalent, and separately explains how to point the project at any model that speaks the OpenAI protocol.
Redis-Stack ships with a password already written into the command
The Redis-Stack container is the first command the README gives, and it is complete enough to run as pasted:
docker run -d \
--name redis-stack \
--restart=always \
-v redis-data:/data \
-p 6379:6379 \
-p 8001:8001 \
-e REDIS_ARGS="--requirepass 123456" redis/redis-stack:latest
Two ports are published rather than one. 6379 is the Redis protocol the application talks to, and 8001 is the vector query API that comes with the stack, so both have to be reachable for the embedding features to work. Data goes into a named volume, `redis-data`, and `--restart=always` means the container comes back after a reboot without you starting it.
The password is passed as `--requirepass 123456` through the `REDIS_ARGS` environment variable, and it is a placeholder rather than a secret. Whatever you use here has to match the Redis configuration you put in `application.yml`, and the README does not spell out which key holds it, so treat finding that key as part of step three.
The image tag is `latest`, which means an unpinned build, another thing to change if you care about reproducibility.
Neo4j needs APOC unlocked and its volume mounted twice
The Neo4j command is longer than the Redis one because APOC has to be enabled explicitly. The plugin list is set through `NEO4JLABS_PLUGINS`, and four further `NEO4J_apoc` variables follow it, covering file export, file import, the import config switch, and unrestricted procedures.
That last one deserves a second look. Unrestricted procedures is what lets APOC run procedures the database would otherwise block, and it is turned on in a command the README expects you to paste. It is a development convenience, and it is not something to leave in place on a database that holds anything you mind losing.
The volume handling is odd in a way that is easy to copy without noticing: `neo4j-data` is mounted at both `/data` and `/plugins`, so one named volume backs two different directories. Whether that is deliberate or a copy and paste slip is not something the README says, but it is the kind of detail worth checking against the APOC documentation before you rely on it.
After startup you reach the browser at `localhost:7474` and sign in with `neo4j` and `neo4j`.
application.yml is the only file the README asks you to edit
The configuration step is deliberately short: open `application.yml` and fill in the API key, MySQL, Redis-Stack and Neo4j settings. That is the entire configuration surface the README describes, which is friendly for a first run and unhelpful later, since there is no table of optional keys and no mention of profiles.
The model endpoint is the part with a specific gotcha. For any model that speaks the OpenAI protocol, the settings go under `spring.ai.openai` as a `base-url` and an `api-key`, and the URL must be given without the trailing `/v1` segment, because the client appends it. Getting that wrong produces a request to a path that does not exist rather than a clear configuration error.
The README also points at the author's own API relay as a convenient source of OpenAI protocol keys, advertised with a signup credit. That is worth thinking about before using it in anything real: a relay is a third party, so your prompts, your key and your model traffic pass through an endpoint you do not control. Using a provider key you hold directly costs nothing extra in setup.
Marking target/generated-sources as a source root is not optional
Running the backend is described in two steps, and the second one is the one people get stuck on. You start `ServerApplication.java`, and then, in IntelliJ, you right-click `target/generated-sources/annotations` and mark the directory as a generated source root.
The reason this is a manual step is that the folder is a build output. Annotation processing creates it during compilation, so it does not exist in a fresh clone, and the IDE cannot offer a menu item for a directory it cannot see. In practice that means you run once, let the compiler fail or finish on generated code, then mark the folder, and only then does the project resolve cleanly.
The README says to open the project in IDEA, which also tells you this workflow assumes an IntelliJ based setup rather than a command line build. Nothing in the described steps compiles and runs the module with Maven, even though a `pom.xml` is sitting at the root, so anyone who prefers a terminal will need to work out that path themselves.
The front end wants the backend up before npm run api
The client lives in `front-end/` and the README gives three commands to run there:
npm run install
npm run api
npm run dev
The ordering is the substance. `npm run api` is stated to need the backend running first, so this is not a plain install and dev cycle; the dependency direction runs from the Java service outward to the front end tooling.
One thing to check when you get there: the first line is written as `npm run install`, which invokes a package script named install rather than the plain `npm install` command. That only works if the front end defines such a script, and the README does not say what any of the three scripts do, nor is the front end package manifest part of the top level listing. If the first command errors with a missing script, running `npm install` directly is the thing to try.
Support for this project is not self service. The README lists paid remote setup and custom development on WeChat, and three QQ groups for installation and runtime errors, one of which is marked as full.
Editorial conclusion
Take this project if you want a runnable Spring AI sample that reaches graph RAG and function calling without assembling the vector store and the graph database yourself, and read it as teaching material rather than as a library, since the tree is one Maven module with a SQL dump and a front end rather than a reusable artifact. Before you start, have MySQL 8, Redis-Stack, Neo4j 5 and Node 18 running, and budget for the fact that two of them are container commands you have to paste and configure yourself. Verify three things in particular: that the Redis-Stack password in the README command matches what you put in `application.yml`, that you have changed the default Neo4j credentials before binding port 7474 anywhere reachable, and which model endpoint you point `spring.ai.openai` at, since the relay the README suggests is a third party that your prompts and keys pass through. The last push was on 2026-07-15 and no releases are published, and the repository carries no licence file at all, which matters if you intend to reuse the code rather than read it.
Frequently asked questions
What does dive-into-spring-ai cover?
The README lists ten Spring AI topics: SSE streaming, agents, function calling, embeddings, a vector database, RAG, graph RAG, message history, image generation, and image understanding. It is a Java 17 teaching project built with Maven, with a SQL dump and a front end alongside the sources.
What do I need installed before running dive-into-spring-ai?
Java 17, Node.js 18 or newer, MySQL 8, Redis-Stack, Neo4j 5 or newer, and a model API key such as a DashScope key. Redis-Stack and Neo4j are given as Docker commands in the README, and MySQL needs the `database.sql` schema applied by hand.
Why is Redis-Stack used instead of plain Redis?
Because the project needs vector search, and Redis-Stack is Redis extended with vector query capability. That is also why its Docker command publishes two ports, 6379 for the Redis protocol and 8001 for the vector query API.
How do I point dive-into-spring-ai at a different model provider?
For a model that speaks the OpenAI protocol, set `base-url` and `api-key` under `spring.ai.openai` in `application.yml`, and give the base URL without the trailing `/v1` because the client appends it. Otherwise you supply a DashScope key or an equivalent through the API key setting.
Why does the backend step ask me to mark target/generated-sources as a source root?
That folder is a build output created by annotation processing, so it is missing in a fresh clone and the IDE has nothing to offer a menu item on until you run once. Marking it afterwards is what lets the project resolve cleanly in IntelliJ.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qifan777-dive-into-spring-ai)Star history chart for your README
[](https://hysenlabs.com/projects/qifan777-dive-into-spring-ai)Was this useful?