Qualcomm AI Hub Models: one CLI with two install names, and an install that fails on Windows ARM64
Qualcomm® AI Hub Models is our collection of state-of-the-art machine learning models optimized for performance (latency, memory etc.) and ready to deploy on Qualcomm® devices.
At a glance
- What is it?
- A PyPI collection of machine learning models packaged for Qualcomm silicon, with a command-line interface, per-model extras, three runtimes and a hosted path that compiles and profiles on real devices in the cloud. The honest constraints are in the small print, and one of them sits directly against the project.
- Who is it for?
- The value here is the packaging rather than the models: one interface that compiles for a named device, quantizes, profiles on real hardware and compares the on-device output against PyTorch, which is exactly the loop most people skip. Two things to settle before adopting it.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
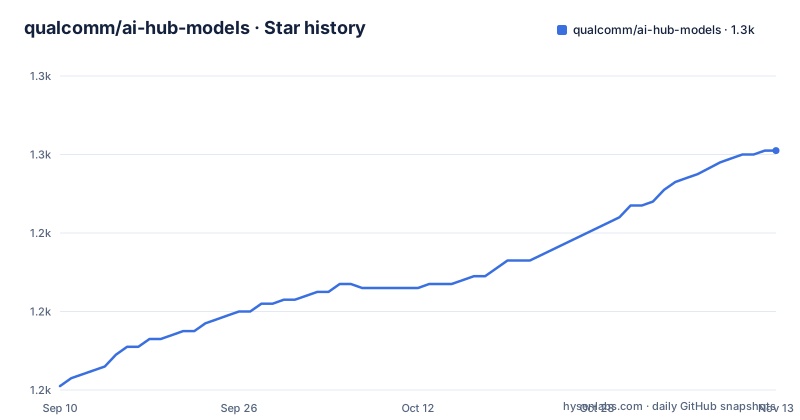
- qualcomm/ai-hub-models1,261 ★ · +60
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| qualcomm/ai-hub-models | 1.2k | 1.3k |
60 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The install fails on the two platforms the project lists as targets
The pip install block carries a comment above the command that is easy to skim past.
It says that for Snapdragon X Elite and Snapdragon X2 Elite users, only AMD64 64-bit Python is supported on Windows, and that installation will fail when using Windows ARM64 Python.
Both of those chips appear in the chipset list further down the document, under the compute platforms, alongside the Snapdragon 8 Elite family and the automotive platforms.
So the two Windows-on-Arm machines this collection is partly aimed at are the two machines on which its own install step is documented not to work. The workaround is not stated, since the note does not say what a user on an X Elite laptop should do instead, only that the ARM64 path fails.
That is a rare thing to find written down rather than discovered, and it changes the first question for anyone on recent Snapdragon-based hardware: not which model to compile, but whether the package installs at all.
One command, two package names, and two spellings of the same flag
The quick start introduces a command-line interface and immediately complicates it.
pip install qai_hub_models_cli # (the CLI is also available with the qai-hub-models package)

qai-hub-models models                                                # browse the catalog
qai-hub-models info mobilenet_v2                                     # model details + download options
qai-hub-models fetch mobilenet_v2 --runtime tflite --precision float # download a deployable asset
# ... and more
So the same executable ships in two distributions, and the reader has to pick one without being told which is preferred or whether they differ.
The command surface is small: models to browse the catalog, info for model details and download options, fetch to download a deployable asset, export to compile for a device, demo to run an end-to-end example, and configure for the Workbench token. The CLI also offers a Python API.
The inconsistency is inside the verb set. fetch takes --runtime, as in fetch mobilenet_v2 --runtime tflite, while export takes --target-runtime, as in export yolov7 --target-runtime tflite. Same idea, two flag names, in the same tool, with no note explaining why.
Anything that touches hardware needs a Qualcomm account
The setup has two steps and only one of them is pip.
The second step is access to AI Hub Workbench, described as required by many features such as model compilation and on-device profiling. That means creating a Qualcomm ID, logging in to Workbench, and configuring an API token with qai-hub configure --api_token.
The export command then walks through five stages: compile the model for the chosen device and runtime, quantize it if applicable, profile the compiled model on a real device in the cloud, run inference with sample input and compare the on-device output against the PyTorch output, and download the compiled model to disk.
So the PyTorch comparison is built into the flow rather than left to the user, which is the part worth having. The cost is that the compile and profile stages are remote.
The end-to-end demos make the split explicit with an --eval-mode flag that takes either fp for a local PyTorch run or on-device for the cloud-hosted hardware, and the documentation says most demos use Workbench in the latter mode.
Three runtimes, three operating systems, and one runtime short a platform
The support tables are short enough to hold in your head, and they are not symmetric.
Qualcomm AI Engine Direct covers Android, Linux and Windows. ONNX, through the QNN execution provider, also covers Android, Linux and Windows. LiteRT, the former TensorFlow Lite, covers Android and Linux only.
So a Windows deployment has two of the three runtimes available and no TFLite path, which is the runtime most people reach for first on a non-Apple target.
The precision table is organised by compute unit rather than by runtime. A CPU takes FP32, INT16 and INT8. A GPU takes FP32 and FP16. An NPU, which includes the Hexagon DSP and the HTP, takes FP16, INT16 and INT8, with a footnote that some older chipsets do not support fp16 inference on their NPU.
That footnote is the kind of detail that decides whether a model runs at all on a given device, and it sits in a parenthesis under a table rather than in the per-model documentation.
The chipset list covers the Snapdragon 8 Elite family from Gen 1 to Gen 5, the X2 Elite and X Elite compute platforms, three SA automotive platforms, and QCS 6490, 8250 and 9075.
The Python apps are written to be read, not to be fast
There are two kinds of sample application, and the README draws the distinction explicitly.
Native applications that run the models with pre- and post-processing on physical devices live in a separate AI Hub Apps repository. Python applications are defined for every model and are imported from the model's own package, with the example showing the pattern as from qai_hub_models.models.model_name import App. They wrap inference in torch and numpy steps, and the README says in as many words that they are optimised to be an easy-to-follow example rather than to minimise prediction time.
That sentence is the most useful line in the sample section. It tells you exactly what not to benchmark them for.
Dependencies are also per model. The main install is pip install qai_hub_models, but models with extras are installed as pip install "qai_hub_models[yolov7]", and the note about extra dependencies points at the model README rather than at a single list.
The demos follow the same split, describing preprocessing, inference and postprocessing as the three stages every end-to-end example performs.
The Python version support is visible only as a broken badge
The badge row at the top of the document has four entries. Two point at the latest release, one at PyPI, and the fourth renders as a URL-encoded fragment: %2C%203.11%2C%203.12%2C%203.13-yellow).
Read as an escaped fragment of a Python version badge, it names 3.11, 3.12 and 3.13 with the usual colour suffix. So the supported Python versions are recoverable, but only by recognising what a Shields.io badge parameter looks like, and the badge itself does not render.
Nothing else in the document states a Python requirement. The install block mentions only the Windows architecture caveat, and the runtime tables cover operating systems for models rather than for Python.
For a package that has just moved through two 0.62 releases and a 0.63 release in three weeks, the supported interpreter range is the kind of thing that changes between minor versions, so a reader who decodes the fragment should still check the release notes.
Agent tooling, protocol buffers and two extra pre-commit gates
The top level is unusually instrumented for a model collection.
There is a .claude directory, a .claude-plugin directory, a plugin directory and a CLAUDE.md, which is the same agent-facing pattern the Elixir LangChain project uses and a growing convention among libraries that publish prompts and configuration.
There is also a proto/ directory, so something in the collection speaks a defined protocol, and cli/, scripts/, src/ and tutorials/ as the expected code layout.
The quality tooling is specific. ruff.toml configures the Python linter, .shellcheckrc configures shell checking, and there are two standalone pre-commit configurations beyond the main one: .pre-commit-license-header.txt, which enforces a licence header on source files, and .pre-commit-line-ending-check.yaml, which enforces line endings.
Two entries have no explanation anywhere in the document. EXTERNAL_ONBOARDING.md is a process file with no mention, and .breeze/ is a directory whose purpose is not stated. Both are the kind of thing a new contributor discovers rather than reads about.
Editorial conclusion
The value here is the packaging rather than the models: one interface that compiles for a named device, quantizes, profiles on real hardware and compares the on-device output against PyTorch, which is exactly the loop most people skip. Two things to settle before adopting it. Anything touching hardware needs a Qualcomm account and a cloud round trip, so confirm that is acceptable for your data before you compile anything, and treat the Python apps as documentation rather than as a performance baseline, since the project says so itself.
Frequently asked questions
What is Qualcomm AI Hub Models?
A collection of machine learning models packaged for deployment on Qualcomm devices, published on PyPI as qai_hub_models, with a command-line interface for browsing the catalog, inspecting a model, and downloading or exporting a deployable asset for a named device.
Do I need a Qualcomm account to use AI Hub Models?
Yes for anything that touches hardware. Compilation, quantization, profiling and on-device inference run on AI Hub Workbench and need a Qualcomm ID plus an API token configured with qai-hub configure --api_token. The local path is PyTorch, selected with --eval-mode fp.
Which runtimes and chipsets does AI Hub Models support?
Three runtimes: Qualcomm AI Engine Direct and ONNX through the QNN execution provider on Android, Linux and Windows, and LiteRT on Android and Linux only. Targets include Snapdragon 8 Elite Gen 5 back to 8 Gen 1, the X2 Elite and X Elite compute platforms, three SA automotive platforms, and QCS 6490, QCS 8250 and QCS 9075.
How do I install a model that needs extra dependencies?
Through per-model extras, as pip install "qai_hub_models[yolov7]". The README notes that some models, YOLOv7 among them, require additional dependencies, and that the model README carries the specific instructions rather than a single combined list.
Does AI Hub Models install on Windows ARM64?
Not according to its own documentation. The install block states that only AMD64 64-bit Python is supported on Windows and that installation fails with Windows ARM64 Python, and the note is placed specifically for Snapdragon X Elite and X2 Elite users, both of which are listed as target compute platforms.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qualcomm-ai-hub-models)Star history chart for your README
[](https://hysenlabs.com/projects/qualcomm-ai-hub-models)Was this useful?