AI Hub Apps: one directory per recipe, and the language follows the runtime
The Qualcomm® AI Hub apps are a collection of state-of-the-art machine learning models optimized for performance (latency, memory etc.) and ready to deploy on Qualcomm® devices.
At a glance
- What is it?
- The repository is a set of sample apps keyed to a deployment target, and the pattern is consistent enough to read as a design: Android is Java on TensorFlow Lite, Windows is C++ and Python on ONNX, Ubuntu is Python on TensorFlow Lite with GStreamer for video. NPU acceleration has a numeric floor stated as a hardware architecture version.
- Who is it for?
- This suits someone who has picked a Snapdragon device, has a model from the companion models catalogue, and wants a working path from that model to an app rather than a tuning exercise. It is a poor fit if you want a library, since each directory is a self-contained sample with its own readme, and a poor fit if you are on hardware older than the stated accelerator floor.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
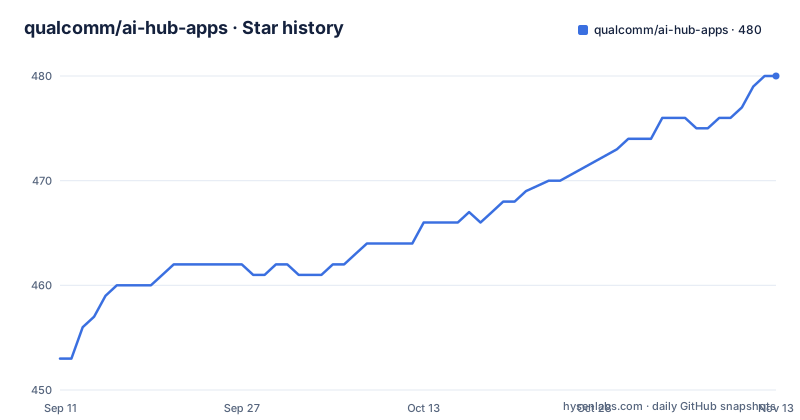
- qualcomm/ai-hub-apps480 ★ · +27
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| qualcomm/ai-hub-apps | 453 | 480 |
27 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository is a directory of recipes, not a library
The stated purpose is a collection of sample apps and tutorials for deploying models on devices from this hardware vendor, and each app is designed to work with one or more models from a separate models catalogue.
The structure follows from that. The top level of the repository is not a source tree with modules in it. It is a flat list of directories named after a task and a platform, such as an image classification app for Android, a C++ one for Windows, and a Python one for Ubuntu, plus a directory of tutorials. There is no shared package that you import, and no build that produces one artefact.
That makes it a recipe collection. You find the row you want in a table, you read that directory's own readme, and you build inside that directory. The readme states this as the getting-started procedure in two steps: search the tables for your operating system and app, and then follow the build and installation instructions in the selected app's readme.
Three things are claimed as possible with the repository, and the middle one is the one that matters most. You can browse apps that have been optimized for on-device deployment across a range of tasks, you can read open-source recipes for running catalogue models on a local device, and you can find tutorials for end to end workflows.
The contributor documentation is pointed at separately for development setup, repository architecture, and how to add a new app, which suggests the tables are the maintained interface and each directory is a pull request.
Three runtimes, and the third is itself built on a lower-level one
Three inference runtimes are supported, and the third has a footnote inside its own name.
The first two are industry standard. One is a lightweight runtime built for mobile, and the other is the open inference runtime for the interchange format. Most of the directory listings are one of those two.
The third is a generative artificial intelligence runtime, and it is described as sitting on top of the vendor's own direct engine SDK. So the generative path is not a peer of the other two; it is a layer above a vendor SDK. That distinction matters when you are deciding which runtime to standardise on, because a generative model cannot be moved to the other two by changing a flag.
The tables make the split visible. Most Android and Ubuntu apps use the mobile runtime, most Windows apps use the interchange runtime, and the two chat apps use the generative one, with the table calling it by a shorter name than the runtime list does.
The tutorials section has two entries, and both are about the generative path. One covers exporting and deploying a large language model with the vendor generative SDK, and the other covers the same job with the other generative runtime, specifically running and exporting with it.
So if your task is classification, detection, segmentation, audio, or image generation, the runtime choice is a technical detail inside a recipe. If your task is text generation, the runtime choice is the decision.
Accelerator support has a numeric floor, and it differs by numeric precision
The compute units listed are the processor, the graphics unit, and a neural processing unit, and the neural one is qualified by two separate constraints that are easy to skim past.
The first is a chipset list. Two laptop platforms, then the current top smartphone platform and its predecessor, then two older generations, then a catch-all clause for every other chipset the vendor's own compiler toolkit supports. So the list is a floor plus a pointer, not an exhaustive enumeration.
The second constraint is the interesting one, and it is split by numeric precision. Floating point acceleration is available on all chipsets with a stated hardware architecture generation or newer. Integer acceleration, in either 8-bit or 16-bit form, is available on all chipsets.
So if you want to run in 16-bit integers, there is no generation floor at all. If you want floating point, there is one, and it is expressed as an architecture version number rather than a chipset name. That is a better way to express it, because chipset names change every year and the architecture version does not, but it also means you have to look up the architecture version of the part you are holding rather than match it against a list.
A note below the list says some of these apps will run without accelerator support on chipsets from other vendors. That is a separate claim from the acceleration list and worth keeping separate: an app can run on hardware that is not in the list, just without the neural unit.
The three tables tell you the language, and the language is not your choice
Each platform table has the same four columns: task, language, inference API, and special tags. Read across the three tables and a pattern appears that is useful before you open any directory.
The Android table is almost entirely one language and one runtime. Image classification, object detection, semantic segmentation, and super resolution are all written in Java against the mobile runtime. The two that carry extra tags are the ones doing live camera work, both tagged with a computer vision library and a live camera feed. The generative chat app is the only entry in Kotlin and Java rather than Java alone.
The Windows table splits across three languages. The three classical vision tasks, image classification, object detection, and super resolution, are C++ with the interchange runtime. Everything else is Python against the same runtime: speech to text, image generation, and segmentation. The generative chat app is the odd one out in Go.
The Ubuntu table is entirely Python and almost entirely the mobile runtime. Seven of the eight entries are vision or audio, and the tagging distinguishes the ones that need a video pipeline: hand gestures, pose estimation, face recognition, three dimensional object detection, and semantic segmentation are all tagged with a streaming media framework, while audio classification, portrait segmentation, and the sensor segmentation entry are not.
The pattern is that the language follows whatever the runtime's natural binding is on that platform, and that the video path needs a streaming framework. If you were hoping to write one app that runs on all three, the tables say otherwise.
Two entries are source-available rather than shipped, and the footnote says so
The app tables carry an asterisk on two rows, and the footnote at the bottom of the page defines it as source available on a code forge and not included in the command line release.
Both starred entries are speech to text. The Android one is a third-party project linked to its own repository, and the generative chat entry for Windows is linked to another separate repository. The Linux or desktop equivalent in the Ubuntu table is a directory inside this repository, so it does not carry the marker.
The distinction is worth catching before you plan a deployment. A directory in this repository is something you clone and build. A starred entry is a link out, which means the recipe is not here, the build instructions are not here, and the compatibility with a specific runtime version is whatever that project says.
The generative chat entries show the same pattern on both platforms, one linked out and one in a directory, so the inconsistency is per app rather than a rule about generative models.
There is also a small mismatch in naming that is easy to trip over. The supported runtimes list names the generative runtime in full, with a parenthetical explaining what it is built on. The app tables then refer to it by a different, shorter name, and the tutorial directory has one entry for each of the two. Nothing in the visible page reconciles the two names, so if you are following a tutorial you may need the runtime list to know which SDK a table row actually means.
The default branch is named for release, and one link still points elsewhere
The default branch for this repository is not the main line. It is a branch named for release, which is a meaningful signal for a repository that ships tagged versions rather than a moving tip.
The visible releases are recent and follow a two-part scheme. There is a patch release and a minor release inside a single month, with the latest minor tagged a few days after the patch. The newest tag and the last push carry the same date, so the tip and the release are aligned.
Against that, one link in the contributor documentation points at a path on a branch named for the main line. So either the branch exists as well and the link is stale, or the link redirects. Either way it is the kind of thing that sends a first-time contributor looking in the wrong place.
The deployment targets are listed once, near the top, and they are specific. One is a named mobile release and newer, with an API level floor. One is a specific desktop release. One is a specific Linux distribution release and newer. The desktop and mobile entries are version numbers rather than minimums, so a machine on the previous release of either is not in the stated support set.
For a recipe collection, the practical consequence is that the tables describe what has been tested on the listed targets, and the tags tell you when each was last revisited. Neither is a compatibility guarantee, but together they are more than most sample collections offer.
Editorial conclusion
This suits someone who has picked a Snapdragon device, has a model from the companion models catalogue, and wants a working path from that model to an app rather than a tuning exercise. It is a poor fit if you want a library, since each directory is a self-contained sample with its own readme, and a poor fit if you are on hardware older than the stated accelerator floor. Before you pick a directory, check three things: which runtime your model ships in, because that decides the table you read and often the language you write; whether your chipset meets the stated architecture version for the precision you intend to use, since floating point acceleration needs a newer accelerator generation than integer does; and whether the app you want is source-available or shipped, because one entry is marked as available on a forge rather than included in the release. The newest release is v0.38.0 from 2026-09-30, and the default branch is named for release rather than for the main line.
Frequently asked questions
What is the Qualcomm AI Hub Apps repository?
It is a collection of sample apps and tutorials for deploying machine learning models on devices from this hardware vendor, where each app is built to work with one or more models from the companion models catalogue. Each app lives in its own top-level directory with its own build and installation readme.
Which inference runtimes do the AI Hub Apps support?
Three: a lightweight mobile runtime, the open ONNX runtime, and a generative artificial intelligence runtime that is itself built on the vendor's direct engine SDK. Most apps use one of the first two, while the two chat apps and the two large language model tutorials use the generative path.
What do I need for neural processor acceleration in the AI Hub Apps?
Integer inference in 8-bit or 16-bit form is available on all supported chipsets, while floating point acceleration requires a chipset with a stated hardware architecture generation or newer. The repository also notes that some apps will run without acceleration on chipsets from other vendors.
Why does the AI Hub Apps documentation not build a single application?
Because it is a recipe collection rather than a library. There is no shared package to import and no single build artefact; you find your operating system and task in one of the tables and then follow the build and installation instructions in that app's own readme.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qualcomm-ai-hub-apps)Star history chart for your README
[](https://hysenlabs.com/projects/qualcomm-ai-hub-apps)Was this useful?