SenseVoice: a five-language speech model that tags emotion and audio events, but needs help for long audio and speaker labels
Open-source SenseVoiceSmall model for Mandarin, Cantonese, English, Japanese, and Korean ASR, language ID, emotion recognition, and audio event detection.
At a glance
- What is it?
- QwenAudio/SenseVoice hosts the SenseVoiceSmall speech model for Mandarin, Cantonese, English, Japanese and Korean, covering recognition, language ID, emotion tags and audio events. It runs through FunASR, ships a FastAPI Docker server, and leaves speaker diarization and long recordings to companion pieces.
- Who is it for?
- SenseVoiceSmall is a good fit when you want Mandarin, Cantonese, English, Japanese or Korean transcripts with emotion and sound-event tags from one model, served through FunASR or the bundled FastAPI container. It is the wrong tool for speaker labels out of the box, for languages outside those five, or for event detection that must match specialised classifiers.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 45 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
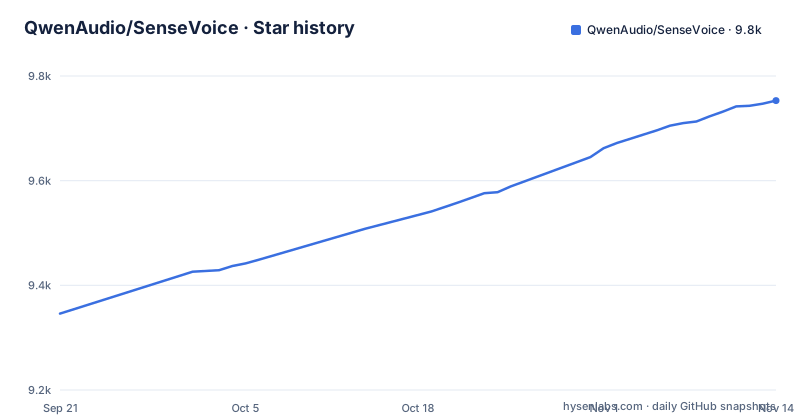
- QwenAudio/SenseVoice9,753 ★ · +407
| Repository | 2026-09-21 | 2026-11-14 |
|---|---|---|
| QwenAudio/SenseVoice | 9.3k | 9.8k |
407 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The released checkpoint covers five languages, while the research claim is fifty
The broader SenseVoice work reports training on more than 400,000 hours and support for more than 50 languages. The released SenseVoiceSmall checkpoint is narrower: Mandarin, Cantonese, English, Japanese and Korean, together with emotion and audio-event tags. The README itself says the benchmark comparisons are task and language specific.
The consequence is simple. If you read the headline numbers and plan for a language outside the five, the model you can download will not cover it. Check the language list against your audio before anything else, including any dialects or code-switching in your recordings, and treat the fifty language figure as a statement about the research and not about the file you will run.
Speaker diarization is a separate pipeline, not an output of the model
A note near the top of the README says SenseVoiceSmall supports recognition and language ID with emotion and audio-event tags, and that speaker diarization is a composed FunASR pipeline using separate FSMN-VAD and CAM++ models. It is not an output of the checkpoint itself.
So a transcript from SenseVoice alone carries no speaker labels. If your use case is meetings or interviews, you have to assemble the extra models yourself. The What's New section points at an alternative in the wider FunASR ecosystem, OpenMOSS/MOSS-Transcribe-Diarize, which supports offline transcription, timestamps and anonymous speaker labels without composing external VAD and speaker models. That is a different model with its own deployment guide, not a switch inside SenseVoice.
Long recordings must be segmented before the encoder sees them
The inference section states that long recordings must be segmented before they are sent to the encoder, and the example uses FSMN-VAD for that. The model is created through FunASR with the VAD attached:
from funasr import AutoModel
from funasr.utils.postprocess_utils import rich_transcription_postprocess

model_dir = "iic/SenseVoiceSmall"

model = AutoModel(
    model=model_dir,
    trust_remote_code=True,
    remote_code="./model.py",
    vad_model="fsmn-vad",
    vad_kwargs={"max_single_segment_time": 30000},
    device="cuda:0",
)
The max_single_segment_time value of 30000 caps each segment, and trust_remote_code=True with remote_code pointing at ./model.py means the model class is loaded from this repository's own file. There is also long_audio_no_vad.py, which uses bounded overlapping windows and preserves raw chunk outputs, so hour-scale recordings do not need one unbounded GPU allocation.
Two version pins disagree: funasr 1.4.14 in the news, funasr 1.3.26 in the requirements
The What's New entry names the current deployment path as installing funasr==1.4.14 for the Python usage, the OpenAI-compatible service and the container workflows. The Requirements section says the examples and the composed diarization path require funasr>=1.3.26, and requirements.txt carries the same lower bound. The install command is:
pip install -r requirements.txtIf you installed earlier and the demos fail, the README tells you to run pip install -U "funasr>=1.3.26". The two statements are compatible, but they are not the same instruction. For a reproducible environment, pin the exact funasr version yourself. The requirements file also pins numpy at 1.26.4 or lower and asks for torch 2.12.1 or newer and torchaudio 2.11.0 or newer, with a comment saying to install a matching torch and torchaudio pair first for CUDA-specific wheels.
The Docker image is a FastAPI server, and the compose file reserves no GPU
The Dockerfile builds on pytorch 2.12.1 with CUDA 12.6, installs ffmpeg and libsndfile1, installs requirements and starts uvicorn with api:app on port 50000. It sets MODELSCOPE_CACHE to /models and the device to auto, and has a health check with a five minute start period.
The docker-compose file maps port 50000 and mounts a volume for models, but deliberately makes no GPU reservation. A comment explains that a default reservation makes docker compose up fail on hosts without the NVIDIA runtime, and says GPU users should use docker run with --gpus all instead. So compose runs on CPU unless you change it. If you expect GPU throughput from compose, you will not get it. Uncommenting the optional preload line in the Dockerfile would put the weights in the image and avoid a download at first start.
Benchmark claims are specific, and the audio-event numbers come with a stated gap
On recognition, the README compares SenseVoice with Whisper on AISHELL-1, AISHELL-2, Wenetspeech, LibriSpeech and Common Voice, and says SenseVoice-Small has advantages for Chinese and Cantonese. On efficiency, it says that in the benchmark setup shown, SenseVoiceSmall runs more than 5 times faster than Whisper-Small and 15 times faster than Whisper-Large at a similar parameter count, because it uses a non-autoregressive end-to-end architecture.
On emotion, the text names the SenseVoice-Large model as best on nearly all datasets, while the Small model surpassed other open-source models on most. The Large model is not the checkpoint linked in this repository. On audio events, the README admits that classification on ESC-50 has gaps compared with specialised models, against BEATS and PANN, because of limits in training data and methodology. Use it as a convenient tagger, not as a replacement for a dedicated classifier.
The license field says MIT while the container label says Apache-2.0, and releases are runtime builds
GitHub lists the repository license as MIT, but the Dockerfile sets the image license label to Apache-2.0. Before shipping the container in a product, read the LICENSE file and the model cards on ModelScope and Hugging Face and settle which terms apply to the weights as well as the code.
The recent releases are not model releases. They are runtime-llamacpp tags: v0.2.1 on 2026-08-27, v0.1.9 on 2026-07-24 and v0.1.4 on 2026-06-29, named as the FunASR llama.cpp runtime. The last push was on 2026-09-30. The repository also contains ONNX and libtorch demos, an export script, a finetune.sh with deepspeed configuration and a webui.py, so there are several ways to run and adapt it. The services pitch includes multi-concurrent requests, with client languages named as Python, C++, HTML, Java and C#. Fine-tuning is offered as a way to handle long-tail samples in your own business scenario, which is where a general five-language model usually needs adjustment.
Editorial conclusion
SenseVoiceSmall is a good fit when you want Mandarin, Cantonese, English, Japanese or Korean transcripts with emotion and sound-event tags from one model, served through FunASR or the bundled FastAPI container. It is the wrong tool for speaker labels out of the box, for languages outside those five, or for event detection that must match specialised classifiers. Before deploying, settle the funasr version, confirm the license you need given the conflicting labels, and test long recordings with your own audio.
Frequently asked questions
How does SenseVoice small compare with Whisper?
In the README's benchmark setup, SenseVoiceSmall runs more than 5 times faster than Whisper-Small and 15 times faster than Whisper-Large at a similar parameter count. It also reports advantages for Chinese and Cantonese recognition.
What is the relationship between SenseVoice and FunASR?
SenseVoice is loaded through FunASR's AutoModel, and the current deployment path installs funasr for the Python, OpenAI-compatible service and container workflows. Speaker diarization is a composed FunASR pipeline, not part of the SenseVoiceSmall checkpoint.
Which languages does SenseVoiceSmall support?
The released SenseVoiceSmall checkpoint supports Mandarin, Cantonese, English, Japanese and Korean for recognition and language ID, with emotion and audio-event tags.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qwenaudio-sensevoice)Star history chart for your README
[](https://hysenlabs.com/projects/qwenaudio-sensevoice)Was this useful?