Every edge in this knowledge graph is a text chunk, and the weights are two constants
Convert any text to a graph of knowledge. This can be used for Graph Augmented Generation or Knowledge Graph based QnA
At a glance
- What is it?
- rahulnyk/knowledge_graph turns a body of text into a graph by asking a locally hosted language model for the concepts in each chunk, then assuming that two concepts mentioned in the same chunk are related. There are exactly two edge types and two weights, which makes the whole method easy to reason about and easy to criticise.
- Who is it for?
- This repository suits a developer who wants to see the whole construction of a concept graph end to end, in a notebook, with no hosted model calls and no database to install. It suits someone prototyping graph retrieval, because the two-weight scheme is small enough to change in a cell.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 91 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
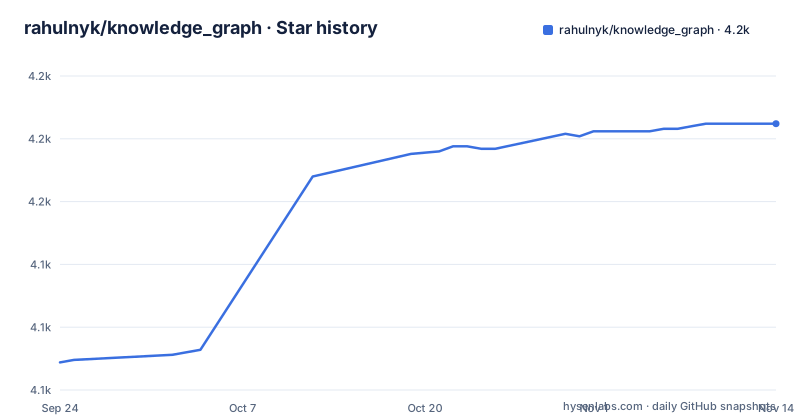
- rahulnyk/knowledge_graph4,181 ★ · +95
| Repository | 2026-09-24 | 2026-11-14 |
|---|---|---|
| rahulnyk/knowledge_graph | 4.1k | 4.2k |
95 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Concepts are extracted by a local model, not by an entity recogniser
The method starts with a deliberate choice that shapes everything downstream. The author is explicit that he is not using an entity recogniser, and explains the difference with an example: a city name is an entity, whereas a phrase about pleasant weather in that city is a concept. His conclusion, based on his own experience, is that concepts make a more meaningful graph than entities. So each text chunk is sent to a language model and asked for the concepts mentioned inside it, and the model's output becomes the vocabulary of the graph. That has an obvious strength, which is that concepts are what a reader would say the document is about, and an obvious weakness, which is that the vocabulary is only as consistent as the model's phrasing from one chunk to the next. The project lists that weakness itself as an open task.
Two edge types, two weights, and then a merge
The graph has exactly two kinds of edge and no more. The first comes from the model: for each chunk it extracts concepts and their semantic relationships, and each such relationship is an edge with a weight given one constant. The second comes from proximity alone: concepts occurring in the same chunk are assumed to be related by contextual proximity, with a second weight, and the same pair may occur in several chunks. Then the merge happens. Similar pairs are grouped, their weights summed, and their relationship descriptions concatenated, so the finished graph has exactly one edge between any two distinct concepts, carrying a summed weight and a list of relations as its label. That is the whole construction. It is a small, legible model of relatedness, and its simplicity is both the reason it is easy to understand and the reason it will not match a hand-curated graph.
Degree and community detection do sizing and colouring, not semantics
After the graph is built, two graph algorithms run, and their purpose is stated plainly: the degree of each node is used for sizing, and communities are used for colouring in the rendered graph. Neither step changes the graph. They are presentation layers that happen to reveal structure, since a node with a high degree is a concept the text keeps returning to and a community is a cluster of concepts that co-occur. The broader argument in the documentation is that a graph buys you things a bag of vectors does not: centralities to judge which concept matters to a body of work, communities to bunch concepts for analysis, and an explanation for why two seemingly unconnected concepts are connected at all. Whether that argument holds is an empirical question, but it is at least a question about structure rather than about similarity.
The documented path runs a notebook server in a container on port 8888
The install instructions are three commands, and the only prerequisite is a container runtime. The first clones the repository and changes into it:
git clone https://github.com/rahulnyk/knowledge_graph.git
cd knowledge_graph
The second builds the image:
docker build -t knowledge-graph .The third runs it with a port mapping:
docker run -p 8888:8888 knowledge-graphThe container definition explains why that port is in use: it starts a notebook lab server bound to all interfaces on that port rather than running the notebook as a one-shot script. That is a deliberate choice for a notebook-based project, since you want the lab rather than the file executed once. It also means the container is a development environment rather than a packaged tool, and that the interesting artefact is the notebook you edit rather than a command. The repository ships a second notebook about entity recognition alongside the main one, plus older notebooks kept in their own directory, which suggests the exploration history is part of the deliverable.
One model, hosted locally, with a name mismatch in the setup step
The model story is short and mostly about cost. The author states that all components are set up locally so the project runs on a personal machine, and that he took a no-paid-model approach to keep things economical, using a seven-billion-parameter instruction-tuned open model that he credits with handling this particular job well. A local runtime makes it available, and the model is already packaged there for use out of the box. There is one detail worth flagging: the documented first step for the runtime is to run a command that pulls a different model and starts the server. So the setup instruction and the model named as the choice are not the same, which is worth checking before you conclude that extraction quality is the model's fault.
The graph is built with dataframes and rendered as a JavaScript page
The stack is small enough to list, and each entry has a stated job. A tabular library holds the graph schema, with the author noting a graph database could be used at a later stage, which tells you the current implementation is in memory and lost when the session ends. A graph library does the graph work, and a separate one handles visualisation by generating JavaScript graph pages from Python, which is why the published example graph is a web page. That combination is the reason the finished artefact is shareable without a running service: the output is a page, not a database endpoint. Two other dependencies deserve a note for what they imply. A PDF parsing library is present, matching the fact that the worked example starts from a PDF, and a document-chunking library is present alongside it, matching the chunk-first method.
The contributor list is the honest description of the project's state
The last section is a list of unimplemented ideas with attributions, and it is more informative than any feature claim. The top item is using embeddings to merge semantically identical concepts, with the specific failure named: the model writing the same concept two ways, such as singular and plural, and the related question of whether strongly similar concepts should be clustered together. The second is filtering out redundant or outlier concepts, with the example given being generic concepts that occur too often in the text to be informative. Both are marked unchecked. Read together with the opening line, which says the project needs a lot more work, the picture is a method demonstration with a visible and acknowledged list of what a real system would have to add. That is a better thing to build on than a polished library that hides its edges.
Editorial conclusion
This repository suits a developer who wants to see the whole construction of a concept graph end to end, in a notebook, with no hosted model calls and no database to install. It suits someone prototyping graph retrieval, because the two-weight scheme is small enough to change in a cell. It does not suit a production pipeline, since the deliverable is a notebook rather than a library and the project says outright that it needs a lot more work, with semantic deduplication and outlier filtering both listed as unfinished. Before building on it, read the contributor list rather than the feature claims, because the two things named there are the two that would bite you: the same concept written two ways by the model, and generic concepts that occur too often to say anything.
Frequently asked questions
What is meant by a knowledge graph?
It is a network of real-world entities, which can be objects, events, situations or concepts, together with the relationships between them. The information is usually stored in a graph database and visualised as a graph structure, which is where the name comes from.
How do you use a knowledge graph with an LLM?
The project argues for graph retrieval rather than vector retrieval: build a graph once, then use it as the retriever when chatting with the text, which it calls graph retrieval augmented generation. On top of that you can run graph algorithms, compute node centralities to see which concepts matter to the body of work, and compute communities to group concepts.
How do I set up this knowledge graph project?
Clone the repository, build the container image with `docker build -t knowledge-graph .`, and run it with `docker run -p 8888:8888 knowledge-graph`, which starts a notebook server on that port. You also need the local model runtime installed on the host, since the model runs outside the container. The deliverable is the notebook, which you edit.
Why does the graph use concepts instead of named entities?
The author deliberately avoids an entity recogniser and argues that concepts make a more meaningful graph, giving the example that a city name is an entity while a phrase about the weather there is a concept. Concepts are extracted from each chunk by a locally hosted language model rather than by a named-entity model.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rahulnyk-knowledge-graph)Star history chart for your README
[](https://hysenlabs.com/projects/rahulnyk-knowledge-graph)Was this useful?