Pinecone examples: production-ready notebooks in one directory and learning notebooks in another, owned by two different teams
Jupyter Notebooks to help you get hands-on with Pinecone vector databases
At a glance
- What is it?
- The examples repository that splits into two tiers with different maintainers and different promises, sends its getting started guide into the tier it describes as being for exploration, carries an agent framework and a model provider in its development dependencies, and configures a formatter with a line length it then tells the linter to ignore.
- Who is it for?
- Pinecone examples suits someone who wants to see a vector database used against a real retrieval pattern rather than described, because the two directories are split by intent and by owner, so you can tell which one carries an engineering support commitment. Verify four things first.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 24 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
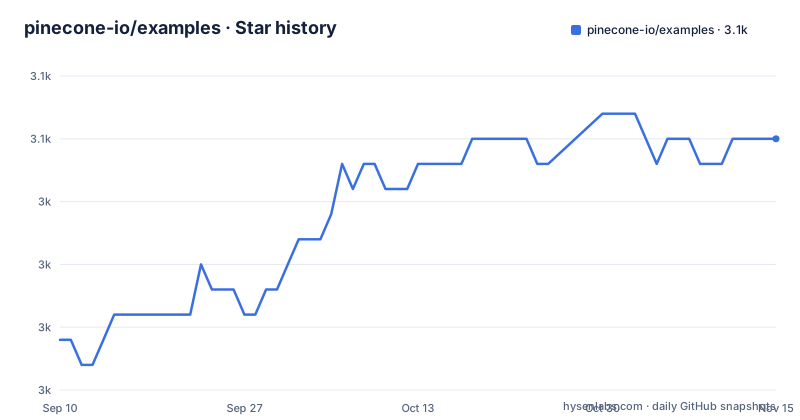
- pinecone-io/examples3,050 ★ · +8
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| pinecone-io/examples | 3k | 3.1k |
8 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two directories, two owners, two different promises
The entire structural explanation of the repository is a numbered list of two. The first directory holds examples described as production ready, which receive regular review and support from the vendor's engineering team. The second holds examples optimized for learning and for exploring techniques and application patterns, created and maintained by a developer advocacy team. So the repository contains code with an engineering support commitment sitting next to code with an advocacy owner, and nothing in the tree distinguishes them beyond the directory they are in and the sentence in the readme. There is no per-example status marker and no coverage badge. There is no per-example status, no coverage marker and nothing a reader can check. The distinction is real and worth having, because it tells you who to ask when one of them breaks, and it is also entirely maintained by convention in one file.
The getting started guide is inside the tier the readme calls for exploration
The readme's only installation guidance is a pointer, and the pointer goes into the learning directory rather than to a guide at the root. It sends the reader to a getting started section of that directory's own readme for detailed instructions and a walkthrough of running a notebook in a hosted notebook environment. So the first-time path for somebody who arrived to use the production tier runs through the documentation written for people who are exploring, and a reader who wants to know which tier to start with has to make that decision before they can install anything. There is no environment file in the visible tree, no credentials walkthrough, and no statement about what a reader needs before running a notebook against a hosted vector database.
The development environment includes an agent framework and a model provider
The manifest has one optional dependency group and it is called dev, and its contents describe the notebooks better than the readme does. Alongside the vector database client and a formatter library for terminal output, it carries an agent framework, a model provider SDK, a tokenizer, and a dotenv loader. That combination tells you the notebooks are expected to orchestrate retrieval and then call a hosted model, which means running one is not necessarily an offline exercise even though the project itself is just files on a disk. It also means the example code carries two more service dependencies than the product being demonstrated, which is worth weighing when you decide whether a notebook is a reference implementation or a demo. A dotenv loader in the same list implies the credentials come from an environment file rather than from configuration.
Two notebook tools and a linter configured to lint notebooks
The same dependency group carries two different notebook toolkits, one for handling notebooks programmatically and one that is an alternative reactive notebook environment. So the repository supports notebooks written in two conventions, which matters if you are automating something across the examples. The lint configuration extends the file matching to notebooks, so cells are checked rather than just markdown.
extend-include = ["*.ipynb"]
line-length = 88

select = ["E", "F", "I"]
ignore = ["E501"]
The same block sets a line length of eighty-eight and then tells the linter to ignore the rule that checks line length, which is a normal combination rather than a contradiction, since the formatter still uses the width. Three rule groups are selected and one is disabled, and the formatter is told to format code inside docstrings as well, which for a notebook repository mostly means it formats code inside markdown cells, which is a surprisingly opinionated thing to apply to documentation you did not write.
Two build systems are configured only to say this is not a package
The manifest contains a project table with a name, a version, and a description, which is what a distributable looks like, and then immediately disables packaging twice in a row for two different build tools. One declaration says the project is not a package. The other sets the package list to empty. Neither is necessary for a repository of notebooks, and together they suggest the manifest grew up as a library manifest and was never simplified. The name is the generic word for what the repository contains, and the version is a placeholder, which together mean the manifest cannot be used to identify anything, and the commit history is the only signal that distinguishes one state of the examples from another. The Python floor is a narrow band, three point ten or newer and below three point fourteen, so the examples will not run on a very new interpreter without someone widening it.
No releases, a placeholder version, and four instructions for coding agents
The repository publishes no releases, so there is no version to pin, and the placeholder in the manifest is not a substitute for one. The commit history is the only version signal, and the default branch is where you would read it. Alongside that, the root carries four surfaces aimed at automated tools: a directory for one assistant's configuration, a directory for a second, a directory for a third, and a single instruction file at the root. A pre-commit configuration sits beside them, and a lock file is committed even though the project is explicitly not a package, which means the lock describes the notebook environment rather than anything a consumer would install. The remaining directories are the two example tiers plus an assets directory and a scripts directory, so the tree is small and almost entirely content.
The readme points at the same contribution file twice and says nothing else about contributing
There are two sentences about contributing in this file and they say the same thing. The first appears after the description of the two tiers and thanks readers for feedback while pointing at the contribution file. The second is a heading of its own near the bottom that says the contribution file has the guidelines. Neither adds a requirement, a workflow or a review process, so the whole of the contribution guidance is one link repeated. There is a support section too, offering the product documentation and a community forum, and a short section inviting readers to open an issue when something is confusing. The file is short enough that all of this fits in under a hundred lines, which is a reasonable choice for a repository whose real documentation is the notebooks themselves, and it means the file you are reading is a signpost rather than a manual.
Editorial conclusion
Pinecone examples suits someone who wants to see a vector database used against a real retrieval pattern rather than described, because the two directories are split by intent and by owner, so you can tell which one carries an engineering support commitment. Verify four things first. The strongest claim in the readme, that one tier is production ready, is made about notebooks, and the repository publishes no releases at all. The getting started guide lives inside the tier the readme describes as being for learning and exploration. The development environment includes two hosted service SDKs, so running a notebook may call out to a provider. And the manifest is configured for two build systems purely in order to state that the project is not a distributable package.
Frequently asked questions
What is in the pinecone-io/examples repository?
Two tiers of notebooks. One directory holds examples described as production ready that receive regular review and support from the vendor's engineering team. The other holds examples for learning and for exploring techniques and application patterns, created and maintained by a developer advocacy team. Both sit beside an assets directory and a scripts directory.
How do I run a Pinecone example notebook?
The readme sends you to the getting started section of the learning directory's own readme, which carries the detailed instructions and a walkthrough of running a notebook in a hosted notebook environment. There is no installation section at the root and no credentials walkthrough in the visible text.
Which Python versions do the Pinecone examples support?
Three point ten or newer, and below three point fourteen. The manifest also disables packaging for two build systems, so the file is not describing something you install; it describes the environment the notebooks run in, and its name and version are placeholders.
What does the Pinecone examples development environment install?
One optional group containing the vector database client, an agent framework, a model provider SDK, a tokenizer, a dotenv loader and a terminal formatting library, alongside notebook tooling for handling notebooks programmatically and for an alternative reactive notebook environment, plus linting and pre-commit hooks.
Are the Pinecone examples versioned?
There are no published releases, so there is nothing to pin. The manifest carries a placeholder version and the generic name for what the repository contains, with packaging explicitly disabled, so the commit history is the only version signal available.
Does the Pinecone examples repository check its notebooks?
Yes. The lint configuration extends file matching to notebooks so cells are checked, selects three rule groups and disables one of them, sets a formatter width that the disabled rule would otherwise enforce, and tells the formatter to format code inside docstrings, which in a notebook repository mostly means code inside markdown cells.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pinecone-io-examples)Star history chart for your README
[](https://hysenlabs.com/projects/pinecone-io-examples)Was this useful?