Chroma: A Rust-Based Vector Database with a Four-Function API
Search infrastructure for AI. Create a DB and try it out in under 30 seconds with $5 of free credits.
At a glance
- What is it?
- Chroma is an open-source vector database for AI workloads, offering a minimal Python API, in-memory prototyping, and a cloud service. This review assesses its core design, setup, and limits.
- Who is it for?
- Adopt Chroma if you need a simple vector store for AI prototyping or production, especially with Python or JavaScript, and you accept a young project with weekly releases. Do not adopt it if you require a mature, feature-complete database with a stable API and extensive operational tooling.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
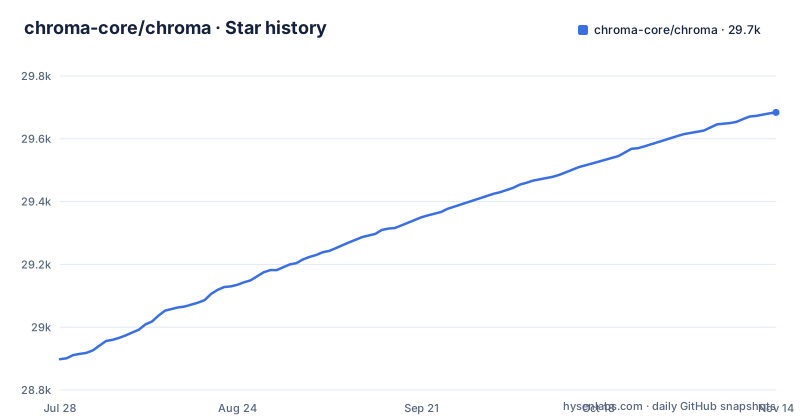
Star history
- chroma-core/chroma29,681 ★ · +783
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| chroma-core/chroma | 28.9k | 29.7k |
783 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Chroma Solves and Who It Serves
Chroma targets developers building AI applications that need to store and retrieve embeddings, documents, or metadata. The README frames it as "the open-source data infrastructure for AI." The core value is simplicity: the API is only four functions, and you can get a database running in under 30 seconds, according to the project's cloud pitch. This is aimed at teams that want to prototype quickly, such as a developer adding semantic search to a chatbot or a researcher testing retrieval-augmented generation. It is not aimed at database administrators looking for a full-featured enterprise system. The description's emphasis on "easy prototyping" and the in-memory setup confirms this focus. The project is written in Rust, which suggests a performance-oriented core, but the primary interface is a Python client, with a JavaScript option via npm. This makes it accessible to the typical AI developer who works in Python.
The Four-Function API and Its Data Flow
The core API is deliberately minimal. The README shows four operations: create a client, create a collection, add documents, and implicitly query. The example uses `chromadb.Client()` to set up an in-memory instance, then `create_collection("all-my-documents")` to define a namespace, and `collection.add()` to ingest documents. The `add` call handles tokenization, embedding, and indexing automatically, according to the README, though you can supply your own embeddings. This is a key design choice: Chroma abstracts away the embedding pipeline, so you don't need to manage a separate embedding model. The data flow is: you pass raw text (or embeddings) plus optional metadata, and Chroma stores them in the collection. Querying is not shown in the README example. The README also mentions `get_collection`, `get_or_create_collection`, and `delete_collection`, so the API is a small set of CRUD operations. This minimalism lowers the learning curve.
Getting Running: Commands and Modes
The README gives three concrete installation paths. For Python, you run `pip install chromadb`. For JavaScript, you use `npm install chromadb`. For a client-server deployment, you run `chroma run --path /chroma_db_path`. This last command starts a server that persists data to a specified path, which is the production-oriented mode. The in-memory mode, shown in the code example, is for prototyping and is the default when you instantiate a client without arguments. The README notes that persistence is easy to add, but it does not specify the exact command to enable it in the Python client. The cloud service, Chroma Cloud, is a hosted option: "Create a DB and try it out in under 30 seconds with $5 of free credits." This is a separate path from the open-source code. The setup is straightforward, but note that the README does not show how to configure authentication, network settings, or embedding model choices. You would need to check the docs for those details.
Limitations and Wrong-Tool Cases
Chroma's simplicity comes with trade-offs. The README explicitly says the core API is only four functions and points to the Docs for all features. The project is "rapidly developing," as the README states, with weekly releases on Mondays and hotfixes anytime. That cadence implies instability: APIs may change, and production users must track releases closely. The in-memory mode is not suitable for large datasets or multi-user access; it is for prototyping only. The client-server mode addresses persistence, but the README does not document scaling behavior, replication, or backup mechanisms. If you need a battle-tested vector database with strong consistency guarantees, Chroma may be the wrong tool. Also, the cloud service is a proprietary offering, so if you want to avoid vendor lock-in, you must run the open-source version yourself, which requires managing the Rust server. The README does not mention any performance benchmarks, so claims about speed are unverified.
Alternatives and Different Approaches
A real alternative to Chroma is a dedicated vector database like Qdrant or Weaviate, though the README does not name them. The difference is in approach: those systems offer a richer API with configurable indexing algorithms (e.g., HNSW parameters), filtering, and distributed deployment. Chroma's approach is to hide those details behind a minimal API, trading flexibility for simplicity. Another alternative is to use a relational database with a vector extension, such as PostgreSQL with pgvector, which gives you SQL integration and transactional guarantees. The key difference is that Chroma is purpose-built for AI embeddings, while pgvector is an add-on. Chroma also differs from full-text search engines like Elasticsearch because it is optimized for vector similarity, not keyword matching, though the cloud service mentions hybrid and full-text search. For a user who needs only vector search and values a quick start, Chroma's minimalism wins. For a user who needs complex queries or operational features, a more comprehensive system is better.
Maintenance, Upgrade Cost, and License
The maintenance cost is directly tied to the release cadence. The README states that new tagged versions of the pypi and npm packages are released on Mondays, with hotfixes at any time. This means you should expect frequent updates, and you must test your application against each new version to catch breaking changes. The project is not archived and had a recent push on October 30, 2026, so it is actively maintained. The license is Apache-2.0, which is permissive for commercial use, but you should review the full license text for any specific conditions. The repository does not show a long-term support policy or a versioning scheme beyond the release tags. For production, you would need to pin versions and set up a testing pipeline. The upgrade cost is moderate: because the API is small, migrating between versions may be simple, but the rapid development means you cannot assume backward compatibility. The README does not mention any migration tools or upgrade guides, so you would rely on the changelog and community Discord.
Editorial conclusion
Adopt Chroma if you need a simple vector store for AI prototyping or production, especially with Python or JavaScript, and you accept a young project with weekly releases. Do not adopt it if you require a mature, feature-complete database with a stable API and extensive operational tooling. Before committing, verify the current API surface, the persistence model in client-server mode, and the licensing terms of the Apache-2.0 license. The project is evolving quickly, so test against the latest release and check the roadmap for upcoming features like a row-based API.
Frequently asked questions
What is chroma in AI?
Chroma is the open-source data infrastructure for AI, described as search infrastructure for AI. The hosted offering, Chroma Cloud, covers serverless vector, hybrid, and full-text search, while the open-source side is a Python or JavaScript client over a Rust core.
how to install chroma
The README gives three lines: `pip install chromadb` for the Python client, `npm install chromadb` for JavaScript, and `chroma run --path /chroma_db_path` for client-server mode. Docker is also supported through a compose file that builds the Rust cli target and publishes port 8000.
How can I use chroma?
The core API is described as 4 functions: create a client, create a collection, and add documents, with get_collection, get_or_create_collection, and delete_collection also available. The sample notes that tokenization, embedding, and indexing are handled automatically, and that you can add your own embeddings instead.
What does chroma mean?
In this repository, Chroma is the open-source data infrastructure for AI, with a four-function core API, a Rust workspace of about forty crates, with python_bindings and js_bindings crates in that workspace. The project spells out nothing about the word itself.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/chroma-core-chroma)Star history chart for your README
[](https://hysenlabs.com/projects/chroma-core-chroma)Was this useful?