RAGNotebook: GraphRAG in five containers, and the passwords that come with it
A RAG project built with LangChain, FastAPI and React. The main branch is a knowledge-graph-based knowledge management platform; the base-rag branch is a ready-to-use basic RAG project for learning.
At a glance
- What is it?
- A LangChain, FastAPI and React knowledge notebook that builds a Neo4j graph from your documents and retrieves over it. The Docker path is well documented, and it ships a default admin account and two identical default database passwords.
- Who is it for?
- This is a full application rather than a library, so judge it as one: the graph-guided retrieval, the per-user isolation and the hybrid RRF search are real engineering, and the Docker path gets a browser in front of you in one command. Change the defaults before you do anything else, because the login and both database passwords are committed in the compose file, and remember that the compose layer overrides whatever host addresses you put in backend/.env.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 15 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
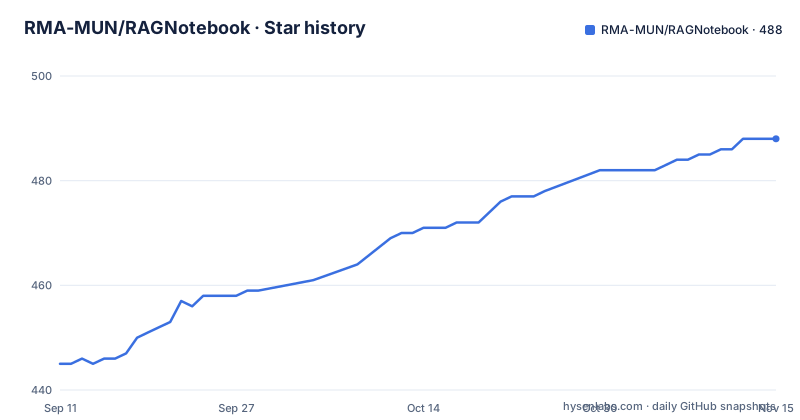
- RMA-MUN/RAGNotebook488 ★ · +43
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| RMA-MUN/RAGNotebook | 445 | 488 |
43 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two branches, two different products
The repository carries an earlier version of itself on a second branch, and the comparison table is blunt about the difference. The base-rag branch is a plain RAG chat service: upload a document, retrieve by vector, ask questions, with no knowledge graph in the path. The master branch is the current product, a note assistant with Markdown editing, a Neo4j knowledge graph, Agentic RAG and AI writing help. The stated reason for keeping the older branch is that it stays permanently available for learning, and the page says RAG remains the core engine of both. The full change history is delegated to docs/project_develop.md. For a reader deciding what to install, that distinction matters more than the feature list: the lightweight service people search for and the knowledge graph platform share a name and a repository, but not a codebase. The table even assigns each an audience, developers who want to integrate RAG quickly or learn it, against individuals who want their notes and a knowledge base managed for them, with a resume project named as a motive. Both branches sit on the FastAPI and LangChain foundation, so code written against the older one is a starting point rather than a drop-in upgrade.
A default login and two identical default passwords ship in the compose file
Three sets of default credentials arrive with the stack. The frontend comes up on http://localhost:3000 with the account admin and the password admin1234, created automatically when the backend starts, so there is no first-run setup step to skip it. Underneath, docker-compose.yml defaults the MySQL root password and the Neo4j password to the same string, ragnotebook123, through two variables that both fall back to that default. The database user is root, and the MySQL schema is named chat_history, which also holds the notes and review tables. The compose file lets you override both passwords from a .env file in the repository root, and the quick start tells you to do exactly that if you want something else. Every one of these values is localhost-only by default, so the risk is entirely about what happens when someone binds a port.
Both database healthchecks put the password in the command line
The compose file checks both databases by running a client that takes the credential as an argument. MySQL runs mysqladmin ping with the root password passed inline, retried every ten seconds with a thirty second grace period at start. Neo4j runs cypher-shell with the user name and the password in the same line, executing RETURN 1, retried every fifteen seconds, twenty times, with a sixty second start period because the graph database is the slowest of the three to accept connections. Both passwords come from the same fallback string. The health checks are the reason the backend waits for its dependencies instead of crashing on boot, and the reason the startup notes can promise a browser opens once the stack is ready. The cost is that the credential appears in the container's process arguments, which is visible to anything that can inspect the container. The rest of the stack is pinned by tag rather than by digest: mysql:8.0, redis:7-alpine and neo4j:5.26-community, each with restart unless-stopped and a named volume, while the backend image is built from the ./backend directory rather than pulled.
The compose layer silently overrides the addresses in backend/.env
The environment file and the compose file describe the same settings twice, and the compose file wins. backend/.env is loaded through env_file and is where the model configuration lives: OPENAI_*, VISION_*, EMBED_*, RERANKER_*, WEB_SEARCH_* and SECRET_KEY. A shared anchor block below it then merges infrastructure settings over that file, setting MySQL to the host mysql, Redis to redis, and Neo4j to a bolt URI inside the compose network, with the passwords injected there rather than read from the file. A comment in the compose file explains why, saying the localhost values in backend/.env do not apply to containers, and the quick start repeats it: do not edit those localhost entries. The result is that the file you are told to create and edit is only half honoured, and a developer who changes a database address there will see no effect and no error.
Local development installs several gigabytes of parsers by default
The non-Docker path asks for Python 3.12 or newer, uv at 0.11.9, and Node.js 16 or newer. The backend install is one command:
cd backend
uv sync --extra dev
The note under it is the important part. The document parsing dependencies, unstructured plus torch, are described as several gigabytes and live in a parsers dependency group that uv sync installs by default, both locally and in Docker. Continuous integration avoids that weight by running uv sync with the dev extra and the parsers group excluded, so the environment your tests use is not the environment you develop in. Services then start separately, with uvicorn on port 8000 and npm run dev on port 3000, plus MySQL, Redis and optionally Ollama on 11434. The MySQL and Redis commands are written in the net start form used on Windows.
Retrieval fuses Neo4j vectors with full text, and the cloud reranker can drop out
Search is a hybrid. The semantic search path runs Neo4j vector retrieval together with full-text search, fuses the two with RRF, and treats notes and the knowledge base as one recall space. The graph is not decoration: entities and relations are extracted by an LLM and stored, browsable on a canvas, and expanded along edges when a query retrieves evidence. Related-note suggestions run the same retrieval in reverse, taking top matches from both sources. Two dependencies degrade quietly by design. The reranker is a cloud API, configured with a base URL, a key and a model name, and the copy states that it falls back to the original ordering when it fails. Embedding settings fall back to the chat settings when they are empty. And with no LLM key configured, the stack still starts and can be browsed, with the AI features simply unavailable.
The documented directory tree and env sample both stop mid-line
Two of the reference blocks in the copy available here are incomplete. The project structure listing walks down backend/app through the agent, cache, config, core and db packages and into the graph package, naming its extraction, routers and services subdirectories, and then ends on a partial directory name that reads stora, with no closing entry and no front end directory, even though the startup instructions tell you to change into front and run npm run dev. The environment sample ends the same way, at a comment made of equals signs, in the middle of the reranker block. The page also stops mid-sentence while explaining that the reranker is a hosted service. None of that changes the code, but a reader mapping the layout from these sections is working from a partial picture of a repository whose backend alone has more directories than the listing shows. The top-level view gives the rest: backend/ and front/ as the two applications, docker-compose.yml for the stack, a docs directory, a plan directory, an images directory, and the two Windows batch files start.bat and stop.bat.
Editorial conclusion
This is a full application rather than a library, so judge it as one: the graph-guided retrieval, the per-user isolation and the hybrid RRF search are real engineering, and the Docker path gets a browser in front of you in one command. Change the defaults before you do anything else, because the login and both database passwords are committed in the compose file, and remember that the compose layer overrides whatever host addresses you put in backend/.env. Local development is the harder path, since the default dependency group pulls several gigabytes of parsing libraries that CI deliberately skips. Anyone evaluating it should also read the branch split: the base-rag branch is a different, much smaller product.
Frequently asked questions
What is the difference between the two branches of RAGNotebook?
The default master branch is the note assistant with a Neo4j knowledge graph, Agentic RAG and AI writing. The base-rag branch is the earlier plain RAG chat service, document upload to vector retrieval to question answering with no graph, and it is kept for learning.
How do I start RAGNotebook with Docker on Linux or macOS?
Copy backend/.env.example to backend/.env, fill in OPENAI_BASE_URL, OPENAI_API_KEY and OPENAI_MODEL_NAME, then run `docker compose up -d --build`. The start.bat script is Windows only. The front end is on port 3000 and the API docs on port 8000.
What default accounts does RAGNotebook ship with?
The front end logs in with admin and admin1234, an account the backend creates at startup. docker-compose.yml also defaults both MYSQL_ROOT_PASSWORD and NEO4J_PASSWORD to ragnotebook123, which you can override from a .env file in the repository root.
Which model providers can RAGNotebook talk to?
Any OpenAI-compatible service. The sample environment file points OPENAI_BASE_URL at the DashScope compatible-mode endpoint with qwen3-max, and the documentation also names DeepSeek, Bailian compatible-mode, Zhipu, Moonshot and Ollama on /v1. Empty EMBED_* settings fall back to the chat settings.
Does RAGNotebook start without a model API key?
Yes. The copy states that without an LLM key the service starts and can be browsed, but the question answering and other AI features are unavailable until OPENAI_BASE_URL, OPENAI_API_KEY and OPENAI_MODEL_NAME are filled in.
How does RAGNotebook retrieve answers?
Neo4j vector retrieval and full-text search are fused with RRF across notes and the knowledge base, evidence is expanded along graph edges, and a cloud rerank API reorders the results, falling back to the original order when it fails. Retrieval is limited to the requesting user's own data.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rma-mun-ragnotebook)Star history chart for your README
[](https://hysenlabs.com/projects/rma-mun-ragnotebook)Was this useful?