LingBot-World camera pose control, and the notice that sends you to v2
Advancing Open-source World Models
At a glance
- What is it?
- LingBot-World turns camera pose arrays into video through a Wan2.2 derived inference script, but the repository now opens by telling you to move to lingbot-world-v2 and carries no releases of its own.
- Who is it for?
- Read this repository as a frozen snapshot rather than an active project. Its useful facts are concrete: camera intrinsics and poses in OpenCV coordinates, one torchrun line with FSDP and Ulysses sharding, 480P and 720P size strings, and a dated news list that stops in April 2026.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 129 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
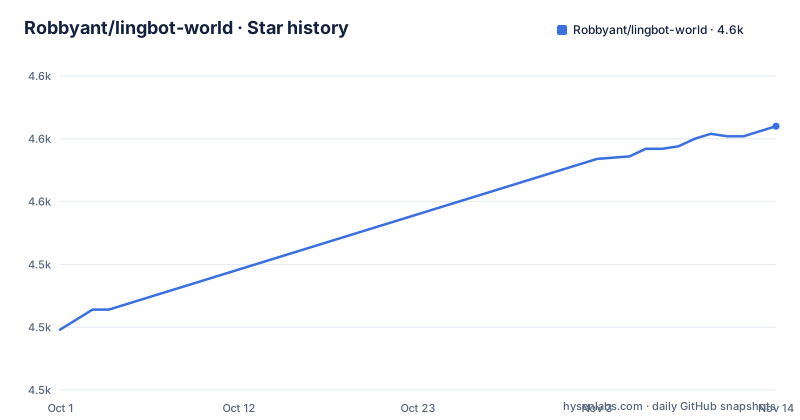
- Robbyant/lingbot-world4,580 ★ · +81
| Repository | 2026-10-01 | 2026-11-14 |
|---|---|---|
| Robbyant/lingbot-world | 4.5k | 4.6k |
81 Stars in the last 44 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The README opens by telling you to leave
The first thing this repository does is redirect you. A callout at the top of the README announces that LingBot-World-Infinity is available, states that this repository is no longer actively maintained, and points at https://github.com/Robbyant/lingbot-world-v2 as the place where all future updates, new models, and new features will be released.
Nothing is hidden from you. The archive flag is still off and the last recorded push is 2026-07-09, so the tree is reachable, but the code, the model table, and the news list describe a stopped snapshot. The repository also has no GitHub releases, which means there is no tag to pin, no release notes to read, and no versioned artifact to download. Every reproducible fact on this page traces back to the news entries and the reference inference scripts, whose dated entries stop at Apr 10, 2026.
Control arrives as intrinsics.npy and poses.npy, in OpenCV coordinates
The control interface is camera geometry rather than text. Before inference runs, the README asks for three things: an input image, a text prompt, and control signals that are marked optional and can be generated from a video with ViPE (https://github.com/nv-tlabs/vipe).
Those signals are two NumPy files with fixed shapes:
- `intrinsics.npy`: shape [num_frames, 4], the four values are [fx, fy, cx, cy] - `poses.npy`: shape [num_frames, 4, 4], each [4, 4] is a transformation matrix in OpenCV coordinates
The coordinate choice matters. Poses are expressed in OpenCV convention, so a pose stream produced by a renderer that uses the opposite handedness needs conversion before it is placed in the directory passed to `--action_path`. The repository ships examples/00 through examples/05 as ready made signal folders, and examples/ also contains persistent_inference.py.
Eight ranks, 161 frames, and one torchrun line
The 480P reference invocation for LingBot-World-Base (Cam) is a single distributed command:
torchrun --nproc_per_node=8 generate.py --task i2v-A14B --size 480*832 --ckpt_dir lingbot-world-base-cam --image examples/00/image.jpg --action_path examples/00 --dit_fsdp --t5_fsdp --ulysses_size 8 --frame_num 161 --prompt "The video presents a soaring journey through a fantasy jungle. The wind whips past the rider's blue hands gripping the reins, causing the leather straps to vibrate. The ancient gothic castle approaches steadily, its stone details becoming clearer against the backdrop of floating islands and distant waterfalls."Read the flags as one hardware decision rather than ten. `--nproc_per_node=8` asks for eight processes, `--dit_fsdp` and `--t5_fsdp` shard the diffusion transformer and the text encoder across those ranks, and `--ulysses_size 8` sets sequence parallelism to the same width. `--frame_num 161` fixes the output length, `--action_path examples/00` supplies the intrinsics and poses, and `--task i2v-A14B` is passed through from the Wan2.2 codebase this project is built on. The 720P line keeps every flag and changes `--size` to 720*1280. Other entry points sit in the root: generate_fast.py, run_fast.sh, run_act2cam.sh, and run_act2cam_string.sh.
Two dependency lists that disagree about transformers
The Quick Start leans on another project for setup, then gets very short. It states the codebase is built upon Wan2.2 and sends you to that project's documentation for installation instructions, so the sequence here is only:
git clone https://github.com/robbyant/lingbot-world.git
cd lingbot-world# Ensure torch >= 2.4.0
pip install -r requirements.txtpip install flash-attn --no-build-isolationThe last command is worth noting because flash_attn already appears inside both dependency lists, so the separate install is not redundant by accident. The two lists also differ. requirements.txt pins `transformers>=4.49.0,<=4.51.3` and adds torchaudio plus `imageio[ffmpeg]`, while pyproject.toml declares `transformers>=4.49.0` with no ceiling and plain imageio. Both pin opencv-python>=4.9.0.80, diffusers>=0.31.0, accelerate>=1.1.1, and numpy>=1.23.5,<2. pyproject.toml requires Python >=3.10,<4.0. If you install from the package metadata instead of requirements.txt you get a different transformers range.
One download link covers two different models
Three checkpoints are offered, and the table that lists them points two rows at the same place.
| Model | Control Signals | Resolution | | :--- | :--- | :--- | | LingBot-World-Base (Cam) | Camera Poses | 480P & 720P | | LingBot-World-Base (Act) | Actions | 480P & 720P | | LingBot-World-Fast | Camera Poses | 480P & 720P |
LingBot-World-Base (Cam) is listed on both HuggingFace at robbyant/lingbot-world-base-cam and on ModelScope, and LingBot-World-Fast points at robbyant/lingbot-world-fast, but the Base (Act) row, the one that takes actions instead of camera poses, carries the same HuggingFace path as the Cam row. So the signals you feed and the weights you fetch are decided by two different rows of the same table, and the Act row gives you nowhere new to download from.
pip install "huggingface_hub[cli]"
huggingface-cli download robbyant/lingbot-world-base-cam --local-dir ./lingbot-world-base-campip install modelscope
modelscope download robbyant/lingbot-world-base-cam --local_dir ./lingbot-world-base-camThe two commands are near twins, differing only in the directory flag, `--local-dir` for the HuggingFace CLI and `--local_dir` for ModelScope.
The claims are three numbers wide, and the hardware story is empty
The feature list is short and quantitative: high fidelity across realism, scientific contexts, and cartoon styles, a minute-level horizon with contextual consistency over time, and latency under 1 second when producing 16 frames per second.
The reference inference commands name no GPU model, VRAM figure, guidance scale or sampler step count.
The consequence for a reader is concrete. The eight rank FSDP command tells you the parallelism the authors used, not the hardware it needs, so any capacity planning before your first run is your own estimate rather than a number the reference commands supply.
The paper, the license, and the dates in the tree
What you can audit lives in the repository rather than in a release feed. Root entries include LingBot_World_paper.pdf, LICENSE.txt, pyproject.toml, requirements.txt, generate.py, generate_fast.py, run_fast.sh, run_act2cam.sh, run_act2cam_string.sh, plus assets/, examples/, and the wan/ package. The package metadata declares the name lingbot-world at version 1.0.0 under the Apache-2.0 license file, publishes packages = ["wan"], and lists dev extras with pytest, black, flake8, isort, mypy, and huggingface-hub[cli]. Formatting is pinned too: black uses line-length 88, isort uses profile black, and mypy is set to strict.
The news list dates the work precisely: technical report, code, and models on Jan 29, 2026, Base (Act) weights on Mar 2, Fast weights on Apr 2, Fast inference scripts on Apr 7, and user friendly Base (Act) scripts on Apr 10. Reactor provides an online demo at https://www.reactor.inc/. The homepage is https://technology.robbyant.com/lingbot-world, the report is at arxiv.org/abs/2601.20540, and a HuggingFace collection groups the weights. Any documentation fix you need now belongs in the v2 repository, not here.
Editorial conclusion
Read this repository as a frozen snapshot rather than an active project. Its useful facts are concrete: camera intrinsics and poses in OpenCV coordinates, one torchrun line with FSDP and Ulysses sharding, 480P and 720P size strings, and a dated news list that stops in April 2026. The reference commands state no memory footprint, GPU model or step count, and the transformers ceiling differs between requirements.txt and pyproject.toml. Check lingbot-world-v2 before you plan any work against this code.
Frequently asked questions
How to try LingBot World?
Reactor hosts an online demo at https://www.reactor.inc/. Locally, the README offers reference inference scripts for LingBot-World-Base (Cam) at 480P and 720P, each launched with torchrun across 8 processes.
How to install lingbot world?
Clone the repository, run pip install -r requirements.txt with torch at 2.4.0 or newer, then run pip install flash-attn --no-build-isolation. The README states the codebase is built upon Wan2.2 and refers you to that project's documentation for installation instructions.
How to use lingbot world?
Prepare an input image, a text prompt, and control signals that are optional: intrinsics.npy of shape [num_frames, 4] holding [fx, fy, cx, cy], and poses.npy of shape [num_frames, 4, 4] in OpenCV coordinates. Then run generate.py with torchrun --nproc_per_node=8, --dit_fsdp, --t5_fsdp, --ulysses_size 8, and --frame_num 161.
What is lingbot world?
It is an open-sourced world simulator stemming from video generation, positioned by its authors as a top-tier world model with a minute-level horizon and latency under 1 second at 16 frames per second. The README also states the repository is no longer actively maintained and directs users to lingbot-world-v2.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/robbyant-lingbot-world)Star history chart for your README
[](https://hysenlabs.com/projects/robbyant-lingbot-world)Was this useful?