CodeGen ships three generations of checkpoints and no version to pin them to
CodeGen is a family of open-source model for program synthesis. Trained on TPU-v4. Competitive with OpenAI Codex.
At a glance
- What is it?
- CodeGen is a family of open-source program synthesis models from Salesforce AI Research, released as Hugging Face Hub checkpoints across three generations. What the repository hands you is three loading snippets with three different flag combinations, no GitHub releases at all, and a training pipeline that lives somewhere else entirely.
- Who is it for?
- CodeGen makes sense if you want a text generation model from 2022 and 2023, published in an Apache-2.0 repository, that still loads through transformers, and you are prepared to do your own evaluation. It is not a foundation for production code generation as published here: the news section stops at July 2023, every comparison to another model is asserted without a metric, and the ethics note describes the release as being for research purposes only.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 166 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
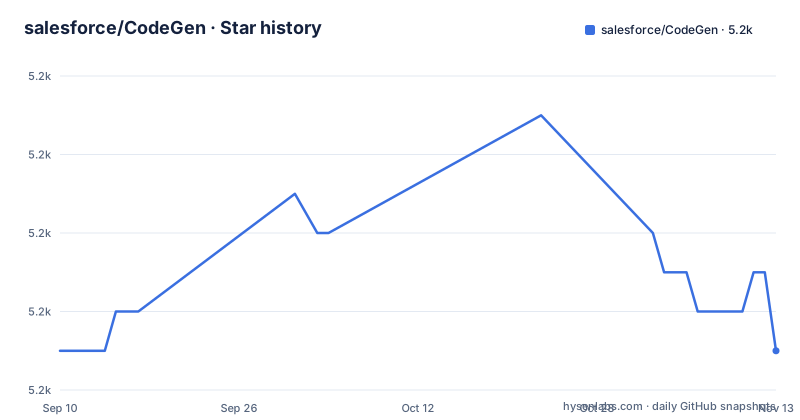
- salesforce/CodeGen5,179 ★ · +0
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| salesforce/CodeGen | 5.2k | 5.2k |
0 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
trust_remote_code changes hands between the three snippets, so a copy paste changes what runs
The same six lines of loading code differ in one flag across the three generations, and the placement is not where you would expect it. The CodeGen1.0 example loads `Salesforce/codegen-2B-mono` with no extra arguments at all. The CodeGen2.0 example loads `Salesforce/codegen2-7B` and passes `trust_remote_code=True` together with `revision="main"`. The CodeGen2.5 example passes `trust_remote_code=True` to the tokenizer and leaves it off the model. That last arrangement is the one that will surprise you: moving the flag between the two calls, which reads as an equivalent edit, is not. And because the flag is what allows the Hub repository to supply its own modelling code, the choice is about executing Python fetched from a remote repository at load time, not about formatting.
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM

tokenizer = AutoTokenizer.from_pretrained("Salesforce/codegen2-7B")
model = AutoModelForCausalLM.from_pretrained("Salesforce/codegen2-7B", trust_remote_code=True, revision="main")
inputs = tokenizer("# this function prints hello world", return_tensors="pt")
sample = model.generate(**inputs, max_length=128)
print(tokenizer.decode(sample[0], truncate_before_pattern=[r"\n\n^#", "^'''", "\n\n\n"]))
revision main pins nothing, and the two calls in that snippet do not pass the same arguments
Only the CodeGen2.0 example names a revision, and the value it names is a branch rather than a commit. `revision="main"` tells transformers to resolve whatever the branch tip is at the moment you load, so two runs on different days can pull different weights while your code stays byte for byte identical. In the same snippet the tokenizer call carries no revision at all, so the tokenizer and the model are not resolved through the same instruction. There is nothing to tighten this up against, because the repository publishes no GitHub releases. The only immutable identifiers are the checkpoint names on the Hugging Face Hub, and the README does not show what a commit hash goes where. If you need reproducibility, that substitution is yours to make.
The size list runs 350M to 16B, and the example checkpoints are 2B, 7B and 7B
The header announces the CodeGen1 and CodeGen2 models in five sizes: `350M`, `1B`, `3B`, `7B` and `16B`. The three usage examples then load `Salesforce/codegen-2B-mono`, `Salesforce/codegen2-7B` and `Salesforce/codegen25-7b-mono`. Two things fall out of putting those two lists side by side. A 2B checkpoint appears in the examples without appearing in the size list, so the enumeration is not a complete index of what is published. And nothing anywhere maps a size to a task: no context length, no language coverage, no quality figure, no guidance on which size to start from. The only size attached to a claim is in the news section, where the July 2023 CodeGen2.5 entry says it outperforms 16B parameter models using 7B, with no benchmark named. Choosing between sizes from what is written here is guesswork.
Two checkpoint names carry mono and one does not, and the word is never defined here
`codegen-2B-mono` and `codegen25-7b-mono` end in an infix the README never explains. `codegen2-7B`, the CodeGen2.0 example, does not have it. So the one visible structural difference between the generations in these examples is a token in the name that carries no definition anywhere in the repository. Whatever it distinguishes, whether a packaging property or a property of the training data, you cannot resolve it from this file; it has to come from the Hub model card. A second detail is easy to trip over in code. The 7B in `codegen25-7b-mono` is lower case while the 7B in `codegen2-7B` is upper case, so any string you build by concatenating a generation prefix with a size will produce a name that is wrong for at least one of them.
The 2.5 example drops truncate_before_pattern, so the print statement has nothing to stop it
The CodeGen1.0 and CodeGen2.0 examples both decode with `truncate_before_pattern=[r"\n\n^#", "^'''", "\n\n\n"]`, which cuts the output at a blank line preceding a comment, at the opening of a triple-quoted block, or at a triple newline. The CodeGen2.5 example decodes `sample[0]` and stops there. Same prompt, same `max_length=128`, no truncation, so the 2.5 snippet prints whatever the model wrote after the useful part, and trimming it becomes your problem. That difference is easy to miss because the rest of the snippet is identical line for line. The examples also set no sampling parameters: there is no temperature, no top_p, no repetition penalty anywhere in the three snippets, so generation runs on whatever defaults your installed version of transformers applies.
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM

tokenizer = AutoTokenizer.from_pretrained("Salesforce/codegen25-7b-mono", trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained("Salesforce/codegen25-7b-mono")
inputs = tokenizer("# this function prints hello world", return_tensors="pt")
sample = model.generate(**inputs, max_length=128)
print(tokenizer.decode(sample[0]))
Training lives in another repository, so this tree is three weight directories and a policy file
Look at the top level and the shape of the project is visible: `AI_ETHICS.md`, `CODEOWNERS`, `CODE_OF_CONDUCT.md`, `CONTRIBUTING.md`, `LICENSE.txt`, `README.md`, `SECURITY.md`, an `assets/` directory, and three version directories, `codegen1/`, `codegen2/` and `codegen25/`. There is no training script, no configuration, no dataset pipeline and no evaluation harness in that list. The work is elsewhere by design: data pre-processing, training and fine-tuning are handled by the Jaxformer library at `github.com/salesforce/jaxformer`, and the CodeGen2.5 news entry links into the `codegen25` directory rather than to a separate project. So reproducing a checkpoint means depending on a second repository whose version relationship to these three directories is not stated anywhere here, and the version directories themselves are not described either.
Every comparison in the file is an adjective with no benchmark attached to it
Four comparative claims appear across the repository description and the news section, and none of them carries a number you could check. The project summary calls the models competitive with OpenAI Codex. The March 2022 entry says CodeGen1.0 was released on par with OpenAI Codex at the time, which is a claim about a moment more than four years past. The May 2023 entry credits CodeGen2.0 with strong infill sampling capability, again without naming a benchmark or a dataset. The July 2023 entry says CodeGen2.5 outperforms 16B parameter models with only 7B. The only evidence linked anywhere is bibliographic: two papers, one on multi-turn program synthesis and one on lessons for training models on programming and natural languages, both listed as ICLR 2023 with arXiv numbers. If you need to know whether the claim holds, the papers are the route, not this file.
The news section ends in July 2023 while the last commit landed in June 2026
The publication record and the commit record in this repository do not meet. The news entries stop at July 2023 with CodeGen2.5, the two papers are from 2023, and the last push to the repository was on 2026-06-02. There are no GitHub releases to bridge that space, so the intervening commits have no changelog attached to them anywhere in the file. For a family of model weights this is the question that matters most in practice: whether a checkpoint name still points at something the author supports, and whether the loading snippets above still match what the Hub serves. The repository does not answer that, and the ethics note makes the intent clear enough to quote: the release is for research purposes only in support of an academic paper, and the models, datasets and code are not specifically designed or evaluated for all downstream purposes.
Editorial conclusion
CodeGen makes sense if you want a text generation model from 2022 and 2023, published in an Apache-2.0 repository, that still loads through transformers, and you are prepared to do your own evaluation. It is not a foundation for production code generation as published here: the news section stops at July 2023, every comparison to another model is asserted without a metric, and the ethics note describes the release as being for research purposes only. Before depending on a checkpoint, pin it by commit on the Hub rather than by the revision used in the CodeGen2.0 example, because this repository has no releases to pin against.
Frequently asked questions
how to use codegen
With salesforce/CodeGen it means naming a checkpoint on the Hugging Face Hub and calling generate on it. The repository gives three Python snippets: Salesforce/codegen-2B-mono for CodeGen1.0, Salesforce/codegen2-7B for CodeGen2.0, and Salesforce/codegen25-7b-mono for CodeGen2.5, each with a different set of loader arguments.
how to install codegen
There is nothing to install from this repository. It publishes no package and no GitHub releases, and its top level holds documentation, policy files and three version directories. In practice you need torch and transformers available and then fetch a checkpoint by name, with no version pinned unless you pass a revision yourself.
What is meant by code generation?
In this project's terms it is program synthesis, and CodeGen is a family of open-source models for it in 350M, 1B, 3B, 7B and 16B sizes, released by Salesforce AI Research and trained on TPU-v4. The model sizes listed there are the only capacity figures the repository gives.
Which tool is best for code generation?
The repository compares no tools. Its own claim is that CodeGen1.0 was released on par with OpenAI Codex in March 2022, stated without a benchmark name, dataset or score. The only linked evidence is two ICLR 2023 papers with arXiv numbers, so the comparison has to be made outside this file.
how to use codegen graphql
Nothing in salesforce/CodeGen relates to GraphQL. The usage section holds three Python snippets that load a text checkpoint from the Hugging Face Hub and call generate on it. There is no schema input, no query file handling and no generator configuration in the repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/salesforce-codegen)Star history chart for your README
[](https://hysenlabs.com/projects/salesforce-codegen)Was this useful?