MiniCPM-V 4.7: OpenBMB's on-device MoE, and the llama.cpp fork its phone numbers depend on
A Pocket-Sized MLLM for Ultra-Efficient Image and Video Understanding on Your Phone
At a glance
- What is it?
- OpenBMB/MiniCPM-V hosts the MiniCPM-V and MiniCPM-o multimodal model families. The new 35B-A3B MoE variant is the headline, but its on-device speed comes from a scheduling technique documented in a separate llama.cpp fork, and the Python stack in this repository is pinned to old library versions.
- Who is it for?
- MiniCPM-V suits developers who need image and video understanding on phones or local hardware under Apache-2.0, and the 1B variant is the low-risk entry point. The 35B-A3B MoE is the more interesting model but its on-device claims, 13+ tokens/s in 3 GB on an iPhone 17 Pro Max, rest on Lookahead Expert Scheduling in OpenBMB's llama.cpp-omni fork, so verify that runtime on your own target device before committing.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
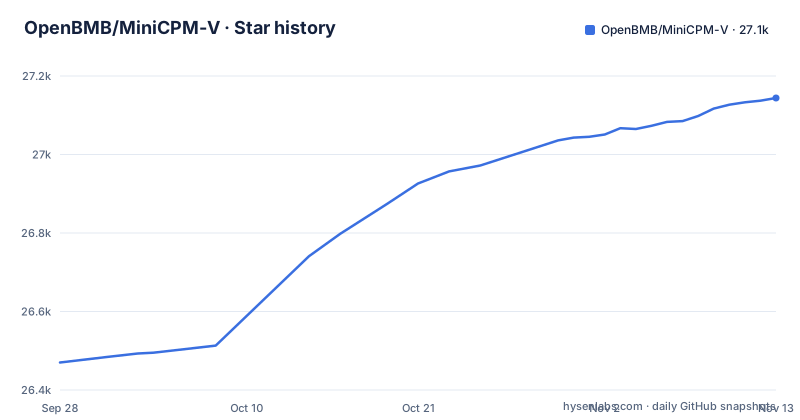
- OpenBMB/MiniCPM-V27,144 ★ · +674
| Repository | 2026-09-28 | 2026-11-13 |
|---|---|---|
| OpenBMB/MiniCPM-V | 26.5k | 27.1k |
674 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two model lines share one repository and one news feed
The repository carries two families under the tagline "See, hear, and interact on your local devices": MiniCPM-V, currently at 4.7, and MiniCPM-o, currently at 4.5. Each has its own write-up in docs/, minicpm_v4dot7_en.md and minicpm_o4dot5_en.md, and its own hosted demo: a Hugging Face Space for MiniCPM-V 4.7 and minicpmo45.modelbest.cn for MiniCPM-o 4.5, whose weights are published as openbmb/MiniCPM-o-4_5.
The GitHub releases page is not where model versions show up. Its only entry is 20250527, titled MiniCPM-V & MiniCPM-o, from 27 May 2025, while MiniCPM-V 4.7 was announced on 12 October 2026. Weights are distributed through Hugging Face and ModelScope, and the News list at the top of the README is the place to follow new drops. The repository itself is active, with the last push on 30 October 2026. Code lives in chat.py, finetune/, eval_mm/, omnilmm/ and web_demos/, and the license is Apache-2.0.
MiniCPM-V 4.7 comes as a 35B-A3B MoE and a 1B model
MiniCPM-V 4.7 has two variants. The 35B-A3B variant is the first mixture of experts model in the series; the 1B variant builds on MiniCPM-V 4.6's core capabilities. Weights for 35B-A3B are on Hugging Face as openbmb/MiniCPM-V-4.7-35B-A3B in BF16, with an FP8 build at openbmb/MiniCPM-V-4.7-35B-A3B-FP8, mirrored on ModelScope under OpenBMB/. The 1B weights are at openbmb/MiniCPM-V-4.7-1B.
On 15 October 2026 OpenBMB added DSpark speculative decoding heads for both variants, each in BF16 and GGUF: MiniCPM-V-4.7-1B-DSpark and MiniCPM-V-4.7-1B-DSpark-gguf for the small model, and MiniCPM-V-4.7-35B-A3B-DSpark and MiniCPM-V-4.7-35B-A3B-DSpark-gguf for the MoE. These are separate downloads from the base weights, so a deployment that wants speculative decoding needs the matching head for its variant and format. The model weights table pairs each model row with its heads, which is the quickest way to see which files belong together.
Lookahead Expert Scheduling hides expert loading behind compute
The problem OpenBMB sets out is specific. An MoE model on a phone can keep expert weights on SSD to get around memory limits, but every expert load can stall generation unless loading overlaps with computation. The cheap fixes, limiting how many experts run or pinning a fixed subset, buy speed by giving up model capability.
Lookahead Expert Scheduling, or LES, takes a different route. Cross-layer routing prediction preloads the experts the next layer is expected to need, and the scheduler prioritizes computation for experts the real router picked that are already in memory, which cuts loading stalls. Weight quantization and an optimized storage layout shrink the footprint and make scattered reads cheaper. OpenBMB reports a 5x speedup on real devices without loss of capability, and for the 35B-A3B variant a decoding speed of 13+ tokens/s using 3 GB of memory on an iPhone 17 Pro Max. A recording in assets/minicpmv4.7 compares generation speed before and after the optimization.
The on-device speed lives in a llama.cpp fork, not in this repository
LES is documented in docs/les/lookahead-expert-scheduling.md inside OpenBMB/llama.cpp-omni, a separate repository. The Python code here, chat.py and the web demos, runs on the PyTorch and transformers stack pinned in requirements.txt, and nothing in that file references llama.cpp-omni.
The consequence is that cloning MiniCPM-V and running its Python entry points does not give you the phone performance in the headline. The 13+ tokens/s figure is tied to one model variant, one device and one inference runtime. If your target is an Android phone, a HarmonyOS device, or a Rockchip board, the 4.7 announcement lists those platforms and chip vendors as supported, but the measured number you can quote is the iPhone 17 Pro Max one. Budget time to build and benchmark llama.cpp-omni on your own hardware, with the GGUF weights and DSpark heads, before promising latency to anyone.
requirements.txt pins old libraries and fetches a wheel over plain HTTP
The root requirements.txt pins exact versions: torch==2.1.2, torchvision==0.16.2, transformers==4.40.0, accelerate==0.30.1, numpy==1.24.4, Pillow==10.1.0, timm==0.9.10, gradio==4.41.0 and opencv_python_headless==4.5.5.64, among others. Three entries are commented out, spacy, xformers and flash_attn, so none of them are installed by default. Two dependencies, gradio_client and decord, are unpinned, which means they resolve to whatever is newest at install time while everything around them is frozen.
One line installs modelscope_studio-0.4.0.9 from http://thunlp.oss-cn-qingdao.aliyuncs.com, a plain HTTP URL with no checksum. Anyone installing this into a shared environment should expect pip to downgrade torch and transformers to these versions, and security reviewers will flag the unauthenticated download. A separate requirements_o2.6.txt exists for the MiniCPM-o 2.6 code path. requirements.txt does not name the model versions it targets, so check the MiniCPM-V 4.7 doc in docs/ before assuming these pins load the newest weights. Use a dedicated virtual environment.
The comparison charts are OpenBMB's own numbers
The README makes direct comparisons. In Instruct mode, OpenBMB says the 35B-A3B variant achieves a higher overall score in less inference time than Qwen3.6 35B-A3B, and that the 1B variant substantially outperforms Qwen3.5 0.8B in both overall score and inference efficiency. Charts for vision-language and language performance of the 35B-A3B model, the 1B model and a performance-efficiency frontier plot sit in assets/minicpmv4.7.
These are vendor results presented as images. The eval_mm/ directory is in the repository for running evaluations, so the comparison you need for a decision is one you run on your own prompts and images. The same caution applies to the MiniCPM-OCR suite announced on 28 October 2026 in its own repository, OpenBMB/MiniCPM-OCR: MiniCPM-OCR 1.0 is based on MiniCPM-V 4.6 and is described as state of the art on Real5-OmniDocBench and OCRBench v2, paired with MiniCPM-OCR Jev for checking result correctness. Note that the OCR model builds on 4.6, not 4.7.
Platform coverage and Self-Replay Fine-Tuning
For deployment targets, MiniCPM-V 4.7 lists iOS, Android and HarmonyOS, and chip platforms from Intel, AMD, Arm, Rockchip and Houmo. That breadth is the reason to pick this family over a server-only model if you need local inference on mixed hardware, with the caveat from the LES section that a published speed figure exists for one iPhone configuration.
For adapting the model, OpenBMB has open-sourced Self-Replay Fine-Tuning, SRFT, described on the openbmb.cn blog as a way to extend model capabilities at low cost while reducing forgetting of what the model already does. The finetune/ directory in the repository holds the fine-tuning code. If you are teaching the model a new document type or domain vocabulary, forgetting is the failure that hurts in production, so SRFT is the method to try before a plain fine-tune. Check which model versions the scripts in finetune/ support against the 4.7 doc before starting a run on the MoE variant.
Editorial conclusion
MiniCPM-V suits developers who need image and video understanding on phones or local hardware under Apache-2.0, and the 1B variant is the low-risk entry point. The 35B-A3B MoE is the more interesting model but its on-device claims, 13+ tokens/s in 3 GB on an iPhone 17 Pro Max, rest on Lookahead Expert Scheduling in OpenBMB's llama.cpp-omni fork, so verify that runtime on your own target device before committing. Teams that need to slot the Python code into an existing environment should check the pins in requirements.txt first, and anyone choosing between models should rerun OpenBMB's comparisons on their own data.
Frequently asked questions
What is MiniCPM-V?
MiniCPM-V is OpenBMB's family of multimodal language models for image and video understanding on phones and local devices, released under Apache-2.0. The latest version, MiniCPM-V 4.7, comes in 35B-A3B MoE and 1B variants.
What is MiniCPM-o?
MiniCPM-o is the companion model line in the same OpenBMB/MiniCPM-V repository, currently at version 4.5. Its weights are on Hugging Face as openbmb/MiniCPM-o-4_5 and a demo runs at minicpmo45.modelbest.cn.
How does MiniCPM-V compare to other LLMs?
OpenBMB reports that MiniCPM-V 4.7 35B-A3B scores higher overall in less inference time than Qwen3.6 35B-A3B in Instruct mode, and that the 1B variant outperforms Qwen3.5 0.8B in overall score and efficiency. These are OpenBMB's own charts.
How do I use MiniCPM-V?
Download the weights from Hugging Face or ModelScope, for example openbmb/MiniCPM-V-4.7-1B, or try the MiniCPM-V 4.7 demo Space first. For phone-speed inference on the 35B-A3B MoE, OpenBMB's figures use Lookahead Expert Scheduling from the llama.cpp-omni fork.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openbmb-minicpm-v)Star history chart for your README
[](https://hysenlabs.com/projects/openbmb-minicpm-v)Was this useful?