CosyVoice pins torch 2.3.1, and its fast text normalizer only exists for Python 3.10 on Linux
Multi-lingual large voice generation model, providing inference, training and deployment full-stack ability.
At a glance
- What is it?
- CosyVoice is a multilingual text-to-speech family with zero-shot voice cloning, streaming generation, training and serving code in one repository. The practical shape is set by a fully pinned requirements file, a ttsfrd wheel built for a single platform, and an English error rate that sits above the human baseline row.
- Who is it for?
- CosyVoice suits Mandarin-first speech work where streaming latency and dialect coverage matter, and where a pinned Python 3.10 environment is acceptable. It suits English content less well, given a test-en WER above the human row for the non-RL checkpoint, and it does not suit macOS, Windows or arm64 users who want ttsfrd normalization.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 173 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
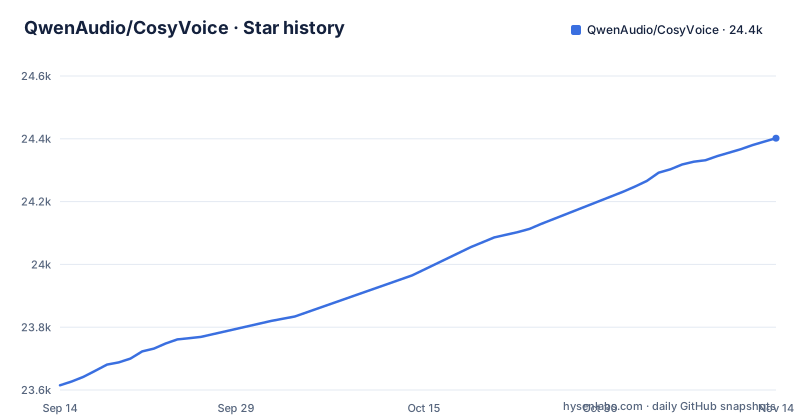
- QwenAudio/CosyVoice24,402 ★ · +787
| Repository | 2026-09-14 | 2026-11-14 |
|---|---|---|
| QwenAudio/CosyVoice | 23.6k | 24.4k |
787 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
requirements.txt names exact versions with no ranges
The install path is a pinned environment rather than a resolver conversation. requirements.txt holds exact pins: torch==2.3.1, torchaudio==2.3.1, transformers==4.51.3, numpy==1.26.4, protobuf==4.25, gradio==5.4.0, modelscope==1.20.0, fastapi==0.115.6. The accelerator side is chosen by hand as well, with an extra index for the PyTorch cu121 wheels and a second extra index pointing at onnxruntime-cuda-12 packages, then onnxruntime-gpu==1.18.0 on linux against plain onnxruntime==1.18.0 on darwin and win32, plus tensorrt-cu12, tensorrt-cu12-bindings and tensorrt-cu12-libs at 10.13.3.9 on linux alone.
The consequence is that there is no supported way to move torch without editing that file. The setup asks for a conda environment created with python=3.10, and everything downstream, deepspeed on linux and the tensorrt packages included, assumes that shape. If your cluster already runs a different torch release, expect to fork requirements.txt rather than negotiate with it.
The ttsfrd wheel is cp310 linux_x86_64, and nothing else
Text normalization has an optional accelerator with a very narrow footprint. The CosyVoice-ttsfrd resource is unzipped and installed as a pair of wheels:
cd pretrained_models/CosyVoice-ttsfrd/
unzip resource.zip -d .
pip install ttsfrd_dependency-0.1-py3-none-any.whl
pip install ttsfrd-0.4.2-cp310-cp310-linux_x86_64.whl
Read the second filename closely: cp310 and linux_x86_64, meaning Python 3.10 on 64-bit Linux and nothing more. The setup notes call the step optional and say that without ttsfrd the project uses wetext by default, but they also present the package as being for better text normalization performance, so the better path exists for exactly one platform combination. On macOS, on Windows, on arm64 hardware, or on any interpreter other than 3.10, ttsfrd does not install and wetext does the work. The 2024/07 roadmap entry that added WeTextProcessing support when ttsfrd is not available is the fallback being treated as a supported case.
Nine languages and eighteen-plus Chinese dialects, and no route past that list
Language reach is specific and bounded. Coverage is given as nine common languages, Chinese, English, Japanese, Korean, German, Spanish, French, Italian and Russian, plus eighteen or more Chinese dialects and accents with Guangdong, Minnan, Sichuan, Dongbei, Shan3xi, Shan1xi, Shanghai, Tianjin, Shandong, Ningxia and Gansu among them, on top of multi-lingual and cross-lingual zero-shot voice cloning. Text normalization is handled without a traditional frontend module, reading numbers, special symbols and various text formats.
The consequence is a hard edge for anyone outside the list. A request in Portuguese, Hindi or Turkish falls outside the listed coverage, and zero-shot cloning selects a reference voice rather than fixing an unsupported language, so the language has to be one the base model already covers. Control features exist for what is listed: instructions covering language, dialect, emotion, speed and volume, and pronunciation inpainting for Chinese Pinyin and English CMU phonemes.
The 150ms figure belongs to streaming, not to finished files
The headline latency number is tied to a specific mode. Bi-Streaming is described as supporting text-in streaming together with audio-out streaming, reaching latency as low as 150ms while maintaining high quality audio output. The roadmap shows the machinery behind it: streaming inference mode with kv cache and sdpa for rtf optimization, and Repetition Aware Sampling for llm stability, both dated 2024/08.
The consequence is that 150ms does not transfer to a script that sends a paragraph and waits for a finished file. Those paths use the same model with different plumbing, and the rtf work belongs to the streaming side. If your use case is generating audio for later playback, read the number as evidence about streaming responsiveness rather than about batch throughput, and read example.py to see which entry points exist per model.
vLLM support has a tested window with an untested gap in the middle
The serving story is stated precisely: CosyVoice2 and CosyVoice3 support vLLM 0.11.x and newer on the V1 engine, plus vLLM 0.9.0 as a legacy path. Versions older than 0.9.0 do not support CosyVoice inference, and the versions in between, 0.10.x for instance, are described as not tested.
That gap has a direct effect on deployment. A cluster on 0.10.x is neither supported nor disowned but untested, so the README does not tell you whether it works, and a failure there looks like a CosyVoice bug rather than an untested pairing. The notes also warn that vllm carries a lot of specific requirements, which is a warning about the surrounding environment rather than about this code. The repository root holds vllm_example.py next to example.py and webui.py as the separate serving paths.
English WER sits above the human row, Chinese CER sits below it
The evaluation table is where the benchmark numbers appear, and the columns disagree with each other. On test-zh, Fun-CosyVoice3-0.5B-2512 records CER 1.21 against 1.26 for the Human row and 1.45 for CosyVoice2, with speaker similarity 78.0 against 75.5 for Human and 75.7 for CosyVoice2. On test-hard, CER is 6.71 against 7.59 for Seed-TTS, 8.67 for F5-TTS and 8.87 for VoxCPM. The RL variant, Fun-CosyVoice3-0.5B-2512_RL, reaches CER 0.81 on test-zh and WER 1.68 on test-en.
The English column is the one to read twice. That 1.68 is measured against 2.14 for the Human row, while the non-RL checkpoint sits at 2.24, above the human figure, and test-en speaker similarity is 71.8 against 73.4 for Human, with the RL variant lower still at 69.5. Read together, those columns say English recognition and speaker match are not where this checkpoint leads, which matters if your content is English rather than Mandarin.
Three model generations, separate weight downloads, different serving paths
One repository carries several generations, and their weights are separate downloads. The setup asks for Fun-CosyVoice3-0.5B, CosyVoice2-0.5B, CosyVoice-300M, CosyVoice-300M-SFT and CosyVoice-300M-Instruct plus the CosyVoice-ttsfrd resource, and recommends Fun-CosyVoice3-0.5B for better performance. Weights arrive through the modelscope SDK:
from modelscope import snapshot_download
snapshot_download('FunAudioLLM/Fun-CosyVoice3-0.5B-2512', local_dir='pretrained_models/Fun-CosyVoice3-0.5B')
snapshot_download('iic/CosyVoice2-0.5B', local_dir='pretrained_models/CosyVoice2-0.5B')
The consequence is that the model choice is a real fork in behaviour, not a version number. vLLM support is stated for CosyVoice2 and CosyVoice3, so CosyVoice-300M does not share that path, while instruction support and pronunciation inpainting are described for the 3.0 line. The clone must be recursive, or the submodule update has to be repeated until it succeeds after a network failure.
No releases exist, so versions are commits and checkpoint names
There are no release tags to pin, which shapes how you track this project. The repository has no GitHub releases at all, and the most recent push to the default branch is dated 2026-05-25. The roadmap carries its own timeline: checked entries for 2025/12 releasing the Fun-CosyVoice3-0.5B-2512 base model, its rl model, the training and inference script and a modelscope gradio space, and for 2025/08 adding triton trtllm runtime support contributed by NVIDIA's Yuekai Zhang together with cosyvoice2 grpo training support.
The consequence is that version identity comes from commit hashes and model directory names rather than tags, so record the commit next to any checkpoint you use. The layout shows where the unglamorous parts sit: docker/, runtime/, third_party/, tools/, an FAQ.md, and example directories for grpo, libritts and magicdata-read. The 2024/07 entries for flow matching training and a fastapi server and client are the fine-tuning and deployment hooks if you need them.
Editorial conclusion
CosyVoice suits Mandarin-first speech work where streaming latency and dialect coverage matter, and where a pinned Python 3.10 environment is acceptable. It suits English content less well, given a test-en WER above the human row for the non-RL checkpoint, and it does not suit macOS, Windows or arm64 users who want ttsfrd normalization. Before you commit, read the wheel filename, pin a commit rather than a tag since there are no releases, and reproduce the CER and WER rows on your own audio.
Frequently asked questions
Is CosyVoice open source?
The repository carries an Apache-2.0 licence and holds the inference, training and deployment code for CosyVoice 1.0, CosyVoice 2.0 and the Fun-CosyVoice 3.0 line, with weights published through ModelScope and Hugging Face. No GitHub releases exist, so there is no tagged version to cite.
how to install cosyvoice
Clone the repository with git clone --recursive, create a conda environment with python=3.10, activate it, then run pip install -r requirements.txt with the Aliyun mirror and trusted-host flags from the setup notes. If sox raises compatibility errors, install it with apt-get install sox libsox-dev on Ubuntu or yum install sox sox-devel on CentOS.
how to use cosyvoice
Download a checkpoint first, such as FunAudioLLM/Fun-CosyVoice3-0.5B-2512 or iic/CosyVoice2-0.5B through the modelscope SDK, then use the documented entry point python example.py, which carries the detailed usage for each model. webui.py and vllm_example.py are the other two entry points at the repository root.
What is voice cloning and how does it work?
In this project it appears as multi-lingual and cross-lingual zero-shot voice cloning: speech is synthesised in one of the supported languages from a reference voice rather than from one adapted in advance. How closely the result matches that speaker is tracked by the SS column of the evaluation table.
cosyvoice vs qwen tts
The README evaluation table does not include Qwen TTS. The evaluation table compares CosyVoice2, Fun-CosyVoice3-0.5B-2512 and its RL variant against Seed-TTS, MiniMax-Speech, F5-TTS, Spark TTS, FireRedTTS2, Index-TTS2, VibeVoice, HiggsAudio-v2, VoxCPM and GLM-TTS on CER, WER and speaker similarity.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qwenaudio-cosyvoice)Star history chart for your README
[](https://hysenlabs.com/projects/qwenaudio-cosyvoice)Was this useful?