real-time-voice-translator is a loop of service wrappers
A desktop application that uses AI to translate voice between languages in real time, while preserving the speaker's tone and emotion.
At a glance
- What is it?
- A GPL-2.0 desktop app that captures speech, translates the text and speaks the result back. The README calls it a deep neural network project, and the requirements file lists no inference library at all.
- Who is it for?
- Adopt this repository if you want to read how a capture, translate and playback loop is wired together in a few hundred lines of Python, and you are content to depend on hosted speech services. Do not adopt it expecting a local model or a current release: the last tag is v2.0.1 from 2023-11-02, the last push was on 2026-05-04, and the dependency list contains no inference package.
- Can I use it commercially?
- Yes, with conditions. GPL-2.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Tcl, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
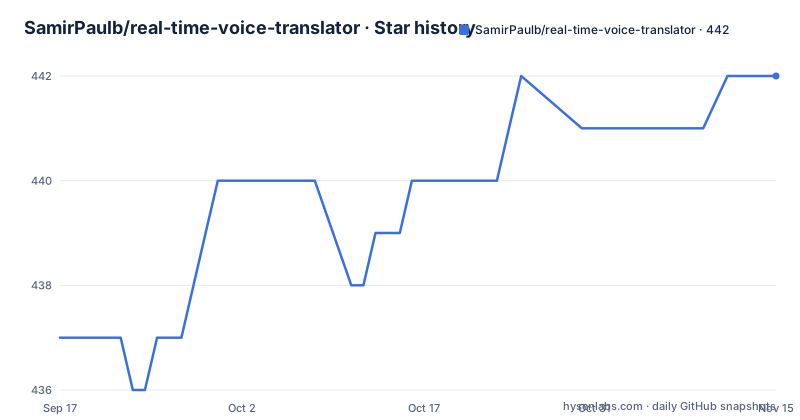
- SamirPaulb/real-time-voice-translator442 ★ · +5
| Repository | 2026-09-17 | 2026-11-15 |
|---|---|---|
| SamirPaulb/real-time-voice-translator | 437 | 442 |
5 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The last tag is from 2023, the last commit from 2026
The release history stops three years before the repository does. Three tags exist: v1.0.1 and v1.0.2 both on 2023-10-30, then v2.0.1 on 2023-11-02. The last push to the default branch landed on 2026-05-04.
Nothing in the visible documentation says what the untagged work has been, and there is no changelog in the repository to check. What you can say from the dates is that a released installer and the current code are not the same thing, which matters because the project distributes binaries through those releases.
The packaging file carries the version forward in one place: `version="v2.0.1"`. It matches the newest tag exactly, so a build from the current branch will also claim v2.0.1 even if the source has moved since November 2023. Nothing in the build increments it.
The repository is not archived, so the code is still reachable, but treat any binary under the releases page as a 2023 snapshot rather than as the current state of the project.
The requirements file lists no inference library
The README describes a machine learning project that uses deep neural networks to translate voice while preserving the speaker's tone and emotion. The dependency list does not contain a neural network. It is seven packages:
gTTS
pyaudio
playsound==1.2.2
cx-Freeze
deep-translator
SpeechRecognition
google-transliteration-api
Read by role, that is a microphone and a playback layer, two translation services and a packaging tool. `SpeechRecognition` captures and transcribes. `deep-translator` and `google-transliteration-api` translate text, one by transliteration for scripts that need it. `gTTS` turns the translated text back into audio, and `pyaudio` with `playsound==1.2.2` handle playback. `cx-Freeze` builds the installer.
So the loop is speech to text, text to text, text to speech. Where tone and emotion preservation happens, if it happens at all, is not visible in the dependency list, and the repository has no model files, no weights directory and no configuration naming a service. Anyone adopting this expecting a self-hosted translator should verify that question before anything else.
Python 3.11 is a ceiling, and setup.py does not say so
The dependency line in the README is written as `<=Python3.11`, alongside the same packages. That is an upper bound, not a recommendation, and it is the only place the Python version is stated in prose.
The packaging file does not repeat it. setup.py declares a name, a version, a description, one executable and build options, and nothing else: no `python_requires`, no install_requires, no classifiers. Whether a Python version is acceptable is therefore enforced only by whatever the dependencies decide for themselves, at install time.
The install sequence is otherwise conventional, with a virtual environment created per project and the requirements file installed into it:
# Create virtualenv
python -m venv env

# Linux/MacOS
source env/bin/activate

# Windows
env\Scripts\activatepip install --upgrade wheel
pip install -r requirements.txt`pyaudio` needs a PortAudio system library before it builds, and the requirements file pins nothing except `playsound`, so a fresh install on a new platform is where you will find out whether the wheels still exist.
main.py is the application, and build artifacts are committed
The repository is flat and small: `.gitignore`, `LICENSE`, `README.md`, `build/`, `dist/`, `icon.ico`, `icon.png`, `main.py`, `requirements.txt` and `setup.py`. There is no package directory and no test directory. The entry point is `main.py`, run directly:
python main.pyTwo entries deserve comment. `build/` and `dist/` are in version control, which means generated output from a build machine is being carried in git, including whatever interpreter and platform produced it. That is common in small desktop projects and it makes the repository history noisier than the code warrants.
The README also has two headings with no content under them. Program Flow and GUI are both bare anchors, so the promised flow diagram and screenshots are either images that did not survive being read as text or sections that were never written. The document does not describe the interface, which for a desktop app is the part a user needs most.
The homepage is a separate blog post rather than a documentation site, so the repository is where the code and the install steps both live.
cx_Freeze zips the virtualenv into the executable
Installer builds go through cx_Freeze, and the settings live in setup.py rather than in a spec file. The executable is `main.py` with `icon.ico`, and the target name is `voice-translator.exe`. The build options include `icon.png` as an extra file and put `env/` into `zip_include_packages`, which is the detail that explains the size of these installers: the whole virtual environment is bundled inside the binary.
That choice follows from the install steps. The README tells you to create a virtual environment and install into it, and the build then ships that environment, so the installed program does not need Python or the packages on the target machine.
Three platform targets are given, one per line:
python setup.py bdist_msi
python setup.py bdist_rpm
python setup.py bdist_mac
These are the older setuptools invocation style rather than the modern build backend, which matches a project last tagged in 2023. Note also that `target_name` is hardcoded to a `.exe` name even in the RPM and Mac targets, and that setup.py imports `sys` and `os` without using either.
Two or more people on one machine is the stated use
The intended interaction is simple enough to state in full: pick the two languages, start speaking, and the application listens and translates. It is also described as usable for translating a conversation between two or more people, which is a harder claim than it sounds. Two speakers sharing a machine means the application has to handle turn taking and two voices through one input path, and nothing in the visible documentation says how that is disambiguated.
The project is described as supporting Windows, Linux and Mac, and the install instructions differ by platform in only two lines, the virtualenv activation. The three installer targets are one command each.
What is not documented is where the translation happens. Every package in the dependency list that does the actual work is either a hosted service or, in the case of pyaudio and playsound, a local audio library. There is no mention of an offline mode, no API key configuration step and no settings file, so the data path for a conversation leaves the machine as a matter of architecture rather than of choice.
Editorial conclusion
Adopt this repository if you want to read how a capture, translate and playback loop is wired together in a few hundred lines of Python, and you are content to depend on hosted speech services. Do not adopt it expecting a local model or a current release: the last tag is v2.0.1 from 2023-11-02, the last push was on 2026-05-04, and the dependency list contains no inference package. Verify two things before building on it. Open requirements.txt and confirm the services still answer, since SpeechRecognition, gTTS and deep-translator are all remote calls that can change without notice. Then check your Python version against the stated ceiling, because the dependency line caps Python at 3.11 while setup.py declares no python requirement.
Frequently asked questions
How does real-time-voice-translator work?
The requirements file shows the loop: SpeechRecognition captures and transcribes, deep-translator and google-transliteration-api translate the text, gTTS turns it back into audio, and pyaudio with playsound==1.2.2 play it. cx-Freeze is used to bundle the result as an installer.
Does real-time-voice-translator run a local AI model?
Nothing in the dependency list suggests so. The seven packages are speech recognition, two translation services, text to speech, two audio libraries and cx-Freeze, and the repository contains no model or weights directory. The README describes the project as using deep neural networks to preserve tone and emotion.
How do I build an installer for real-time-voice-translator?
With cx_Freeze, driven by setup.py. Run python setup.py bdist_msi on Windows, bdist_rpm on Linux or bdist_mac on Mac. The build options bundle icon.png and zip the env/ virtual environment into the executable.
Which Python version does real-time-voice-translator need?
The README dependency line states a ceiling of Python 3.11 or lower. setup.py declares no python requirement, so the only stated bound is that line, and the requirements file pins a version for playsound alone.
Which operating systems does real-time-voice-translator support?
Windows, Linux and Mac are all named. The difference in the setup steps is the virtualenv activation command, and there is one cx_Freeze installer target per platform.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/samirpaulb-real-time-voice-translator)Star history chart for your README
[](https://hysenlabs.com/projects/samirpaulb-real-time-voice-translator)Was this useful?