100x-LLM: the quick start clones a different repository, and the requirements file is a pip freeze
Code snippets and examples from the 100x Applied AI cohort lectures.
At a glance
- What is it?
- 100x-LLM collects 140-odd implementations from a paid applied-AI cohort, arranged as seven numbered sections with a named starting file for each. Its setup steps point at another repository and its dependency list is an exported environment rather than a curated one.
- Who is it for?
- Use 100x-LLM as a map of the applied-AI curriculum rather than as a codebase, because the numbered sections with a named starting file each is genuinely the fastest way to find the one pattern you want, and the two retrieval paths are a reasonable basic-versus-from-scratch ladder. Do not follow the setup steps literally, since the clone command targets a repository that is not this one and every later step refers to that other tree.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 28 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
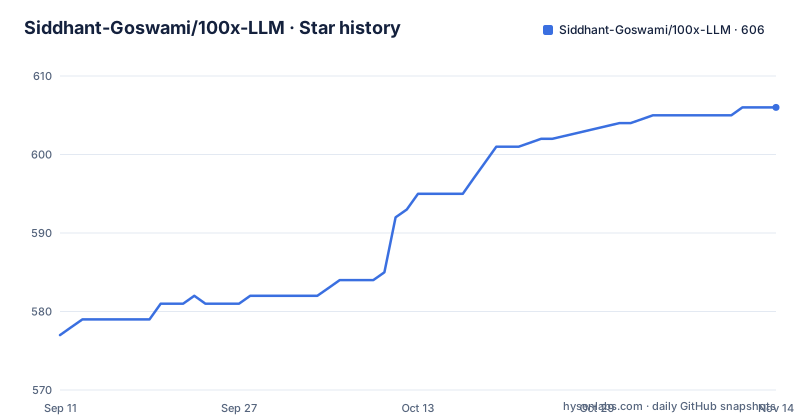
- Siddhant-Goswami/100x-LLM606 ★ · +29
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| Siddhant-Goswami/100x-LLM | 577 | 606 |
29 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The first setup step clones a repository that is not this one
Read the quick start as a sequence and step one stops you.
The command clones `github.com/Siddhant-Goswami/open-source-project` and the next line changes into a directory called `open-source-project`. The repository you are reading is `Siddhant-Goswami/100x-LLM`. Same owner, different name.
Everything after that step belongs to the other tree. Step three installs from `requirements.txt`, step four copies `.env_example`, and step five runs `llm_workflows/prompt_chaining.py`. All four are paths described as belonging to this repository's structure section, so the page describes one layout and the clone command fetches another.
The most likely explanation is a rename that the page never caught. Repositories get renamed, the old URL usually redirects, and a quick start that predates the rename keeps pointing at the old name. That is a small, common, harmless mistake.
It is worth writing down anyway, because the failure mode is confusing rather than loud. If the redirect works, you land somewhere, and if that tree has a different set of directories then step five fails on a missing file and the reader concludes their Python setup is broken.
The dependency file is an environment export, which is why it contains a Debian hotfix and a prerelease
The requirements file runs to around ninety lines, every one of them an exact pin, and several entries are only explicable as the output of an environment export rather than as a curated list.
The clearest tells are the odd names. There is a package literally called `pyarrow-hotfix`, pinned at 0.6, which is a distribution Debian builds to ship patched PyArrow builds rather than something anyone adds to a Python project on purpose. `Deprecated` is capitalised, where the package everyone actually installs is lower-case. There is a prerelease, `pydeck` at a beta version.
Alongside those sit packages that only make sense as transitive debris: `fastapi-cli`, `gitdb`, `dill`, `dirtyjson`, `minijinja`, `mpmath`, `nest-asyncio`, `distro`, `appdirs`.
The practical consequence is that following the instruction to install all required packages brings in an entire working environment, not the dependencies of the examples. Roughly half of what lands is there because something else needed it, and there is no way to install only what a given script uses.
There is also a naming detail in the setup steps worth noticing. The environment template is written with an underline character between the two words rather than the dot-separated form most gitignore rules for environment files expect, so a pattern written for the common spelling will not match this one.
The stated Python floor of 3.8 is contradicted by a resolution from mid-2024
The prerequisites section says Python 3.8 or higher, and then the dependency file describes exactly one environment.
Look at the pins and they date from a narrow window. The certificate bundle is a February 2024 build, packaging is the 24.0 series, pandas is 2.2.2, pydantic 2.7.1, fastapi 0.111.0, numpy 1.26.4, openai 1.23.6, the Groq client 0.4.2, the LlamaIndex stack 0.10.36, datasets 2.19.0, and the Altair release is 5.3.0.
A set of exact pins like that is not a set of constraints, it is a photograph. It installs on the interpreter it was resolved on and on nothing else, because so many of those packages dropped older interpreters between then and now. The page's promise that 3.8 or higher will work is not something this file can support, and the failure would appear at install time as a resolver error rather than as a clear version message.
The instructions also assume pip and a virtual environment with no lockfile discipline beyond the frozen list itself, and no mention anywhere of Python version management. So the first thing a careful reader has to do is ignore the stated floor and work out what the pins imply.
There is no project manifest either, no package declaration and no version of any kind, so the frozen environment is the only description of what this code was written against.
Two LlamaIndex generations and a managed-cloud client are installed at the same time
The LlamaIndex portion of the dependency file contains about fifteen entries, and among them are two things that should not sit in one environment without thought.
The first is the legacy package, pinned at the 0.9 series, alongside the current stack pinned at the 0.10 series. That combination is what the library itself shipped during its migration, and keeping it means two API generations are importable at once. A learner copying an example has to know which generation the snippet targets, and the page does not say.
The second is a set of managed-cloud packages: an indices package scoped to a hosted service, and a client library for the same service's API. So the frozen environment includes an account-backed hosted index implementation, which means the basic retrieval example has an available path that is not local at all.
That matters for how the retrieval sections are framed. The basic section offers two levels, the easier one using a hosted file search API from a model vendor and the second using LlamaIndex. The advanced section builds retrieval from scratch and stores vectors in a hosted vector database.
Both ends of that ladder point outward. The only rung in the middle that could run entirely on your machine is the LlamaIndex one, and even that arrives with the managed-cloud packages already installed.
The retrieval ladder's easiest and most advanced rungs both need someone else's account
The two retrieval sections are the clearest teaching structure in the repository and the one place where the dependency choices show through.
The basic section is numbered by level. Level one uses a model vendor's hosted file search and is labelled the easiest. Level two uses LlamaIndex and is labelled as giving more control. The advanced section builds the retrieval loop yourself, with an embedding step, vector storage in a hosted vector database, semantic search, and custom retrieval strategies.
Each rung names a single starting file, which is the most useful thing on the page: `rag/openai_file_search.py` for level one and `rag_from_scratch.py` for the advanced section. Every numbered section in the structure does this, and it turns a directory listing into a curriculum.
The gap is that the ladder has no local rung. The easiest rung needs a vendor account, and the most advanced one stores its vectors in someone else's database. A reader who wants to understand retrieval without an account, a bill, or a service that stores their documents has no documented path.
The rest of the sections follow the same shape and are honest about their scope: tool calling across three providers, workflows covering prompt chaining, routing, parallel processing and code review, and agents covering a reasoning-then-acting loop, research agents and a reflection pattern.
Verification is a missing traceback, and it needs a key the setup does not actually require
Step five is the test your setup, and it is one script.
The environment step is:
# Create a virtual environment (keeps dependencies isolated)
python -m venv venv

# Activate the virtual environment
# On Mac/Linux:
source venv/bin/activate
# On Windows:
venv\Scripts\activate

# You should see (venv) in your terminal now
Then the page says to run one prompt-chaining script and, if you see output without errors, that you are ready to start learning.
So the acceptance criterion for the whole setup is that a script did not throw. There is no expected output to compare against, and nothing distinguishes a working call from an empty one.
That test also has a precondition the setup treats as optional. The keys section says you need at least one provider, notes that most have free tiers, and lists three. But it also says most examples use one specific provider, with a second offered as a free and fast alternative. A reader who filled in only the alternative key, following the letter of the instruction, gets an authentication error from the verification script and no indication that the key is the problem rather than the environment.
And if step one fetched the other repository, the script may not be there at all.
Two directories in the tree are missing from the numbered structure
The structure section numbers seven areas and names a starting file for six of them.
One is the full-stack directory, with three sub-applications described as a customer relationship tool, an authentication system with a third-party identity provider integration, and RESTful API examples. Another is a prompts directory holding twenty-eight role templates, with five named and a line accounting for the rest. Then tool calling, basic retrieval, advanced retrieval, workflows, and agents.
The prompts section is the only one that declines to name a single starting file, and it is also the only one with twenty-eight items. Everything else gets you a specific path.
Now compare that with the repository root. There are ten content directories, and two of them appear nowhere in the numbered structure: a directory for Hugging Face examples, and one named for miscellaneous items.
The Hugging Face one is the more consequential omission, because it is the only place local model work would live, and the keys section does ask for a Hugging Face token for open-source models. So the page asks you for a credential for a section it does not describe.
A miscellaneous directory is a normal thing to have, but naming it in the root and not in the curriculum means a reader who wants to know what is in it has to go and look.
No version, no continuous integration, no contribution guide, and a homepage that sells a course
The repository root holds fourteen entries, and what is missing from that list is as informative as what is in it.
There is no package manifest, no project file, no setup script and no version marker of any kind. The frozen dependency list is the only description of the code's target environment.
There is no continuous integration directory, no issue templates, no pull request template and no changelog. For a repository with several hundred forks that people are meant to learn from and contribute to, there is no automated check that any of the examples still imports, and the table of contents promises a contributing section that is not present in the repository root.
What the root does have is a licence file, a gitignore, the environment template, the requirements file, the readme and the ten content directories.
The homepage is a course-selling site for the organisation that ran the cohort, and the repository's own summary calls itself code snippets and examples from cohort lectures. So the relationship is: a commercial programme, and this is its teaching material published under a permissive licence.
That relationship also explains what the repository cannot tell you. It does not name who teaches the cohort, what the programme costs, or what the selection criteria were, and nothing in the visible text would let a reader judge whether any of it is still accurate.
Editorial conclusion
Use 100x-LLM as a map of the applied-AI curriculum rather than as a codebase, because the numbered sections with a named starting file each is genuinely the fastest way to find the one pattern you want, and the two retrieval paths are a reasonable basic-versus-from-scratch ladder. Do not follow the setup steps literally, since the clone command targets a repository that is not this one and every later step refers to that other tree. Treat the dependency file as a historical record rather than an install list: it is an environment export with roughly ninety exact pins from mid-2024, it installs two LlamaIndex generations at once, and it will not resolve on the interpreter version the page tells you to use. If you do run any of it, build your own environment per example instead of installing the whole file.
Frequently asked questions
What is 100x-LLM and how is it organised?
A collection of 140-odd implementations from a 100x Applied AI cohort, arranged into numbered sections: full-stack applications, prompt templates, tool calling, basic retrieval, advanced retrieval, workflows, and agents. Most sections name a specific starting file so a reader can begin at one pattern rather than browse a directory.
How do I install the 100x-LLM examples?
The documented steps are to clone the repository, create and activate a virtual environment, install from requirements.txt with pip, copy .env_example to .env and add provider keys, then run one prompt-chaining script and check that it does not throw. Note that the clone command in the page targets a repository with a different name.
Which API keys do the 100x-LLM examples need?
At least one of three: a key for a major model vendor, a key for a fast hosted inference provider described as a free alternative, or a Hugging Face token for open-source models. The page notes that most examples use the first vendor, and that the third is for a directory of local model examples the numbered structure does not describe.
Can I run the 100x-LLM retrieval examples without a paid service?
The basic retrieval section offers two levels, the easier one using a hosted file search API from a model vendor and the second using LlamaIndex, and the advanced section stores vectors in a hosted vector database. No rung in the documented ladder avoids someone else's account entirely.
What Python version does 100x-LLM support?
The page states 3.8 or higher. Its requirements file is an environment export of around ninety exact pins dating from early to mid 2024, which describes a single resolved environment rather than a version range, so the stated floor is not something the file supports in practice.
Who teaches the 100x cohort and what does it cost?
The repository does not say. It describes itself as code snippets and examples from 100x Applied AI cohort lectures and links to the organisation's programme site as its homepage, but it names no instructors, no price, and no selection criteria for the cohort.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/siddhant-goswami-100x-llm)Star history chart for your README
[](https://hysenlabs.com/projects/siddhant-goswami-100x-llm)Was this useful?