Thirteen skills, one vendor key, and an install that runs an unpinned package first
AI agent skills for social media research. Outlier posts, comment mining, competitor teardowns, ad libraries & trends across TikTok, Instagram, YouTube, Reddit, X, LinkedIn & more. Powered by ScrapeCreators. Works with Claude Code, Cursor, Codex, Gemini CLI.
At a glance
- What is it?
- social-media-research-skills is a set of thirteen agent skill directories that turn social media questions into named business artefacts, and twelve of the thirteen cannot run without one commercial API key. Installing them executes an unpinned package through the runtime before any instruction is read, and the repository has no releases and no tests.
- Who is it for?
- social-media-research-skills is worth reading as a template even if you never run it, because the design principles are unusually disciplined, particularly the fence against promising logged-in data and the insistence on judging a creator against their own baseline rather than against raw counts. Two things to decide before you do run it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 87 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
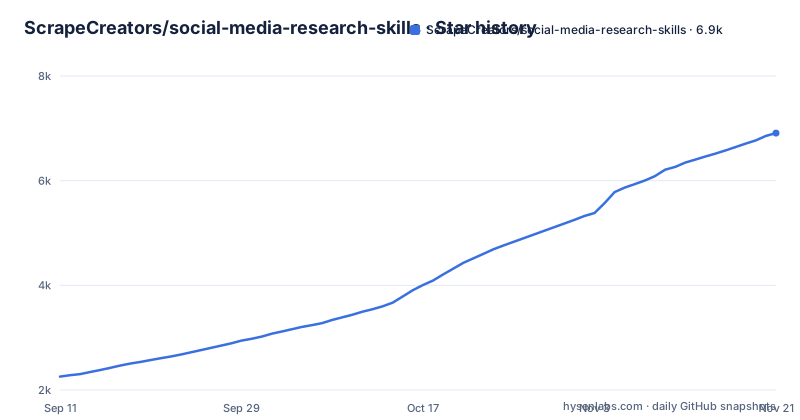
- ScrapeCreators/social-media-research-skills6,909 ★ · +4,653
| Repository | 2026-09-11 | 2026-11-21 |
|---|---|---|
| ScrapeCreators/social-media-research-skills | 2.3k | 6.9k |
4,653 Stars in the last 71 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Thirteen skills and one key behind twelve of them
The repository is thirteen directories under a skills folder, and each one has a name, a stated purpose, and a promised output artefact. What they share is a dependency. The setup section asks you to export a single API key under one environment variable name, obtained from the vendor's site, and one of the thirteen skills exists purely to route a raw request to the right endpoint on that service. The architecture diagram makes the dependency explicit: the routing skill sits at the top and feeds the other twelve. So the skill set is not thirteen independent prompts you can mix and match; it is one data layer with twelve workflows on top, and the workflows produce nothing without a key for that layer. The MIT licence covers the instruction files. It does not make the calls behind them free.
Installing runs an unpinned package before anything is read
The install section is a single command that hands a repository slug to a package called skills, invoked through the runtime's own package runner. Nothing in that command pins a version, so the first thing that executes on a fresh machine is whatever that package resolves to at that moment, before a single line of these instructions has been read by you. That ordering is the whole supply chain question in one line. These instructions are going to run with your API key and be trusted by your agent; the mechanism that installs them is itself an unpinned fetch. The key is a single environment variable, set before anything else runs:
export SCRAPECREATORS_API_KEY=sk_...There is a second, narrower path in the tree as well, a plugin manifest directory for one specific assistant alongside the spec-based route.
The intro claims thirteen platforms and no single skill covers them
Read the two lists against each other. The introduction says the workflows run across TikTok, Instagram, YouTube, Reddit, X and Twitter, LinkedIn, Facebook, Threads, Bluesky, Pinterest, Rumble, ad libraries, and more. Now look at the widest single skill in the table. The transcript skill names eight platforms, and Threads, Bluesky and Pinterest are not among them. The ad teardown skill names three networks. So the platform list in the introduction is the union of everything, presented in a way that reads as coverage, while no individual skill delivers it. That is a reasonable thing for an index to do and a poor thing for a reader in a hurry, because the natural question, which platforms does the one skill I care about cover, cannot be answered from the introduction at all.
The repository disclaims endpoint routing and ships a routing skill
The second sentence of the introduction says this is not just endpoint routing, and then names the goal as giving an agent complete research workflows rather than calls. That positioning is the right one, and the table mostly honours it: each of the twelve workflow skills is named after a question rather than a resource, and each promises a document instead of a payload. Then there is the thirteenth row, whose stated purpose is to route a raw scraping or fetching request to the right endpoint, with output described as API calls and endpoint references. So the repository opens by disavowing the thing it also ships. Read charitably, the routing skill is the escape hatch for when a workflow is not the right shape; read literally, the claim in the introduction does not describe the shipped set.
Two of thirteen outputs carry an uncertainty marker
Look down the outputs column and eleven of the thirteen entries promise a clean artefact with no caveat built in. The exceptions are worth noting because they are the only two. The audience research skill promises an audience-fit report with confidence labels. The social listening skill promises a multi-source brief with sentiment caveats. Everything else promises findings: a prospect list with a fit score, a demand signals report, a positioning teardown, a trend brief with an evidence table. One design principle does apply across all of them, which is that outputs should cite source URLs for posts, videos, ads and comments whenever possible, and another is that exact language should be preserved verbatim so a comment is quoted rather than paraphrased. Those two principles carry the honesty. The confidence labels do not generalise.
Portability rests on an external spec and a Claude-specific manifest
The compatibility claim is long and specific: Claude Code, Cursor, OpenAI Codex, GitHub Copilot, Gemini CLI, Windsurf, VS Code, and other agents that support a named skills specification hosted on its own domain. So portability here is not a property of this repository; it is a property of how closely these directories follow somebody else's format, and it changes if that format changes. The tree also contains a plugin manifest directory and an instruction file named for one specific assistant, which is the second distribution path and the one that is definitely not portable. Alongside them is a general agent instruction file, so three kinds of instruction file sit at the root of a repository whose entire content is instruction files.
No releases, no workflows directory, and no tests for thirteen skill folders
The repository has no releases, and its top level holds seven entries: a plugin manifest directory, two instruction files, the licence, this readme, a scripts directory, and the skills directory. There is no workflows directory, so nothing in the tree runs these skills or checks them. The language recorded for the repository is Python, which points at the scripts directory rather than at the skills, since the skills are instruction text. So there is no visible mechanism by which a change to one of the thirteen skills is verified to still work: an edit to an instruction file produces no failing build, because there is no build. For a set of prompts whose entire value is that they produce a consistent artefact shape, that is the largest gap in the repository.
Baseline-relative performance is the one opinionated idea here
Strip away the plumbing and there is a single substantive claim in the design principles, and it is a good one. Performance should be judged against a creator's own normal performance, not only raw vanity metrics. That is what the outlier skill is built on, since finding a post that beats a creator's baseline is a different and harder question than finding a post with a high absolute number, and it is the difference between research and a leaderboard. The other principles are guardrails rather than methods: public data only, do not promise logged-in or private data; cite source URLs; preserve exact language verbatim; end with something actionable rather than raw JSON. The workflow-first framing, that a user asks for a business outcome rather than an endpoint, is the organising idea and the routing skill is the concession to reality.
Editorial conclusion
social-media-research-skills is worth reading as a template even if you never run it, because the design principles are unusually disciplined, particularly the fence against promising logged-in data and the insistence on judging a creator against their own baseline rather than against raw counts. Two things to decide before you do run it. Twelve of the thirteen skills use one vendor's API as their data layer, so an MIT licence on the instruction files does not make the workflows free. And the documented install runs an unpinned package through the runtime before it copies anything, which means the first thing you execute is not the thing you read.
Frequently asked questions
What is social-media-research-skills?
Thirteen agent skill directories for social media research, covering outlier post finding, transcript analysis, comment mining, competitor research, ad library teardowns, trend discovery, influencer prospecting, audience research, social listening, product demand research, creator teardowns, content repurposing, and endpoint routing. The listed output for each is a named artefact rather than raw data.
Do these social media research skills work without an API key?
Twelve of the thirteen cannot. The setup step is to export a single vendor API key, and one of the skills exists solely to route requests to that vendor's endpoints, with the architecture diagram placing it above the other twelve as their data layer. The thirteenth skill is the router itself, so the whole set depends on one commercial service.
Which platforms do these skills cover?
The introduction lists TikTok, Instagram, YouTube, Reddit, X and Twitter, LinkedIn, Facebook, Threads, Bluesky, Pinterest, Rumble, and ad libraries. No single skill covers all of them: the widest, transcript analysis, names eight platforms and omits Threads, Bluesky and Pinterest, and the ad teardown skill covers three advertising networks only.
How do I install these agent skills?
One command hands the repository slug to a package called skills, invoked through the runtime's own package runner, with no version pinned. Then you export the API key under a single environment variable name. The repository also carries a plugin manifest directory for one specific assistant as a narrower second route, and it targets agents that support an external skills specification.
Are the outputs of these skills verified in any way?
Nothing in the repository checks them. There are no releases, no workflows directory, and no tests, so an edit to any of the thirteen skill folders produces no failing build. The design principles ask for cited source URLs and verbatim preservation of exact language, and only two of the thirteen outputs promise a confidence or sentiment caveat.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/scrapecreators-social-media-research-skills)Star history chart for your README
[](https://hysenlabs.com/projects/scrapecreators-social-media-research-skills)Was this useful?