docetl: two sample environment files, and a stack that starts happily with a placeholder API key
A system for agentic LLM-powered data processing and ETL
At a glance
- What is it?
- DocETL is a Python package from UC Berkeley that turns natural language steps into LLM map, filter and reduce operations over documents, with a YAML form and a browser playground on top. Its repository carries two sample environment files, and the compose file gives the API key a placeholder default, so a stack that comes up without a .env file looks healthy until the first model call.
- Who is it for?
- docetl suits someone processing a large collection of unstructured documents who would rather describe each step in English than hand-write every model call. Start from the Python API, since the readme calls it the recommended interface, and set rate limits before the first run, because both calls per minute and tokens per minute are capped by your provider rather than by docetl.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
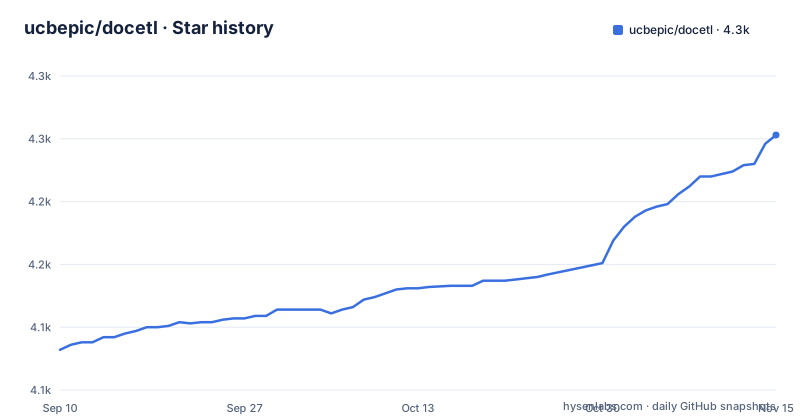
- ucbepic/docetl4,253 ★ · +171
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| ucbepic/docetl | 4.1k | 4.3k |
171 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The compose stack boots with a placeholder key and fails on first use
Installation is two lines.
pip install docetl
export OPENAI_API_KEY=your_key   # or any LLM provider key
The comment on the second line is the important part. The variable is named for OpenAI because that is the default, not because the package talks to one provider. The environment sample makes that explicit by listing Anthropic, Google and Cohere keys as alternatives.
Now look at how the container stack handles the same variable. The compose file passes it through with a default:
- OPENAI_API_KEY=${OPENAI_API_KEY:-your_api_key_here}That syntax means use the host value if it is set, and this literal string if it is not. So a stack started without a .env file comes up with a health check passing, a frontend responding and a backend answering, and fails on the first operation that actually calls a model.
The rest of the compose file is more carefully defaulted, with a health check against localhost:8000/health every thirty seconds, a frontend on host port 3031 and a backend on 8081, both overridable by environment variables.
Two sample environment files and one that the Dockerfile requires
The repository root contains both `.env.example` and `.env.sample`. Two files, same purpose, and the readme and compose file refer to neither by name.
The environment sample itself is a single commented file describing backend configuration, with a header explaining that it is used by the Python server that executes pipelines and that you should copy it to .env and fill in your values. Inside it, the required key, the four backend variables for allowed origins, host, port and reload, the two frontend variables, the two host port mappings, and the text file encodings.
Then there is the Dockerfile problem. Its final stage copies the environment file into the image:
COPY .env ./So a Docker build requires a .env file to exist in the build context, which is exactly the file you are supposed to create afterwards from a sample and which is normally excluded from version control. If the sample is named one thing and the readme expects the other, the first build is where you find out.
The sample also documents the encodings used when reading documents, with a fallback chain of utf-8, latin1, cp1252 and iso-8859-1, which is a reasonable way to survive a document saved with the wrong code page.
Rate limits are set per resource type in the Python API
The Python API is the recommended interface, and the first thing the example does after setting a default model is set limits.
docetl.default_model = "gpt-4o-mini"
docetl.rate_limits = {
    "llm_call": [{"count": 500, "per": 1, "unit": "minute"}],
    "llm_tokens": [{"count": 200_000, "per": 1, "unit": "minute"}],
}
Two resource types, each with a count, a period and a unit, and each holding a list so a single call can carry several limits. A thousand tokens a second is a different shape from five hundred calls a minute, and the two are separate because a provider enforces them separately.
The entries are also more than bookkeeping. The dependency list includes a rate limiter package pinned below its fourth major version, which is what turns these declarations into actual pacing rather than a note in a file.
The rest of the example shows the pipeline shape. A dataset is read, then chained: a map operation takes a prompt containing a template reference and an output schema of two string fields, then a reduce operation takes a reduce key and a prompt that loops over the inputs. The chain returns another pipeline object, so each step is a call on the result of the last.
Operations are plugin entry points, not a fixed list in the code
The project file declares a console script and then a plugin group.
[project.scripts]
docetl = "docetl.cli:app"

[project.entry-points."docetl.operation"]
map = "docetl.operations.map:MapOperation"
parallel_map = "docetl.operations.map:ParallelMapOperation"
filter = "docetl.operations.filter:Filt...
The entry point group is namespaced under the package, with a comment in the file saying the plugin entry points are preserved under a namespaced group. So the operator list is a registration mechanism rather than a hardcoded dispatch table.
The documentation lists the operators as map, filter, reduce, resolve, split, gather, extract and more, with a page for each. What is not in the readme is the full set the entry point group accepts, so the definitive list lives in the project file rather than in the documentation.
The presence of a separate parallel map operation is worth noting. Map and parallel map as two distinct registrations rather than a flag on one operation suggests parallelism is a property of how an operator runs rather than a parameter inside it.
The container runs Python and Node in one image for a UI written separately
The Dockerfile has three stages and the final one installs Node.js into a Python image.
The first stage is Python, installs curl, fetches the uv installer from astral.sh by piping the script to a shell, then copies the project file, the `docetl/`, `server/` and `tests/` directories and touches an empty README, before syncing the environment. The README is created empty because the project file declares it as the readme and the file is not copied at that point.
The second stage is Node 20 on Alpine, which builds the `website/` directory with npm.
The third stage starts again from Python 3.11 slim and installs curl plus two graphics libraries, then adds Node.js by fetching a setup script from deb.nodesource.com and running it through bash, then apt-get installing the package.
So the runtime image carries two language runtimes and a build-time curl script execution, for a tool whose CLI is Python and whose playground is a web application. The compose file exposes two ports for the same reason: 3031 to the frontend on 3000 inside the container, and 8081 to the backend on 8000.
The data directory is created with mode 777 and owned by nobody
One line in the Dockerfile sets up where the tool keeps its state.
RUN mkdir -p /docetl-data && chown -R nobody:nogroup /docetl-data && chmod 777 /docetl-dataThe compose file mounts a named volume at that path, so the contents survive a container replacement, and the environment variable `DOCETL_HOME_DIR` points at it in both the builder and the final stage.
The permissions are the part to notice. The directory is created and then made world writable, so any process in the container can write to it regardless of which user it runs as. The image also sets a port variable to 3000 while the compose file maps the backend to 8000 inside the container, which is one of the two reasons there are two services rather than one.
There is a second service in the compose file, called docetl-aws. It extends the first one, adds AWS profile and region variables defaulting to `us-west-2`, mounts the host's `~/.aws` directory read-only at `/root/.aws`, and sits behind a compose profile named `aws`, so it only starts when you ask for that profile.
Three papers, one acronym for the optimizer, and a make target priced in cents
The readme closes with the research behind the project and the credits for the people who did it, all created at the EPIC Data Lab and the Data Systems and Foundations group at UC Berkeley.
Three papers are cited. DocETL itself is a VLDB 2025 paper on agentic query rewriting and evaluation for complex document processing. DocWrangler is a UIST 2025 paper that received a best paper honourable mention, and it is the interactive playground the readme tells you to try. MOAR is a VLDB 2026 paper on multi-objective agentic rewrites, and the name appears in the documentation table as the automatic cost and accuracy optimization layer.
That is the claim to test. The readme says the system optimizes a pipeline automatically, swapping models, rewriting prompts, decomposing operations, and replacing subtasks with code wherever possible, to raise accuracy and cut cost. The optimizer's own paper is where that behaviour is described.
The development section is more modest and more useful. Two commands: clone the repository and run `make install`, then `make tests-basic`. The comment on the second one is that it costs under a cent with OpenAI, which is a sensible constraint on a test suite that calls a paid model.
Editorial conclusion
docetl suits someone processing a large collection of unstructured documents who would rather describe each step in English than hand-write every model call. Start from the Python API, since the readme calls it the recommended interface, and set rate limits before the first run, because both calls per minute and tokens per minute are capped by your provider rather than by docetl. Put a real key in .env before starting the compose stack, since the placeholder default lets it boot cleanly and fail later. And if you intend to extend it, the operators are declared as plugin entry points rather than hardcoded.
Frequently asked questions
what is docetl and how do I install it
docetl is a Python package for running LLM map, filter and reduce operations over collections of structured and unstructured documents. Install it with `pip install docetl` and export a provider key such as `OPENAI_API_KEY`. The model layer is LiteLLM, so the key name depends on the provider you use, and Anthropic, Google and Cohere keys are documented as alternatives.
is Python used for docetl ETL pipelines
Yes, and the Python API is the recommended interface, described as best for production code, notebooks and scripting. There is also a YAML form for declaring a pipeline in a config file with no Python, run with `docetl run pipeline.yaml`, and the project requires Python 3.10 or newer.
what are the operators docetl supports
The documentation lists map, filter, reduce, resolve, split, gather, extract and more, with a reference page for each. The authoritative list is the plugin entry point group in the project file, which registers operators including a separate parallel map, under a namespaced group so plugins can be preserved.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ucbepic-docetl)Star history chart for your README
[](https://hysenlabs.com/projects/ucbepic-docetl)Was this useful?