Semble: an MCP code search server that trades grep for embeddings
Fast and Accurate Code Search for Agents. Uses 99% fewer tokens than grep+read
At a glance
- What is it?
- MinishLab's Semble indexes a repository on CPU in about half a second and returns code chunks to an agent instead of whole files. The claim is roughly 99 percent fewer tokens than grep plus read, and the design is deliberately narrow: it is retrieval for agents, not an editor or a refactoring tool.
- Who is it for?
- Adopt Semble if you run a coding agent on a repository that is too large to grep comfortably and you want retrieval to stay local, with no API key and no GPU. Skip it if your workflow depends on exact string matching, on searching inside generated or vendored code that the ignore rules exclude by default, or on a language whose extension is not in the default index set.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
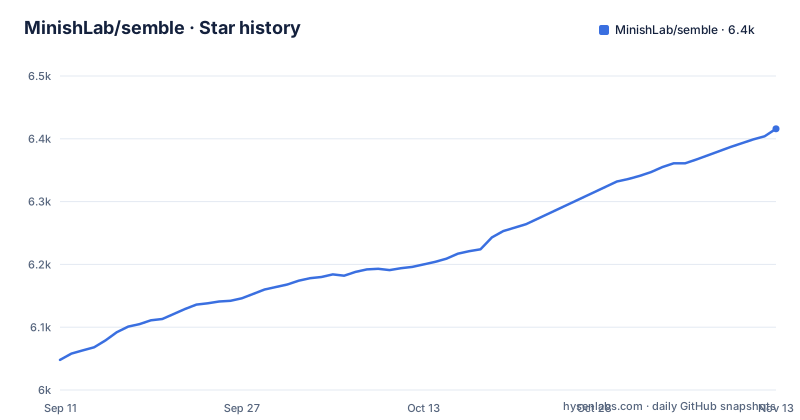
- MinishLab/semble6,416 ★ · +368
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| MinishLab/semble | 6k | 6.4k |
368 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The token bill that grep plus read leaves behind
An agent asked how authentication is handled has two options in a plain shell environment. It can grep for a plausible identifier, then read the surrounding file, then read the file that imports it, and so on until it has enough context to answer. Every one of those reads lands in the context window, and most of the bytes are irrelevant to the question. Semble replaces that loop with a single retrieval call. The README frames the problem as token cost, and the headline claim is that it uses roughly 99 percent fewer tokens than grep plus read. The intended user is not a human browsing a repository. It is an agent, or a developer wiring an agent up, who wants a search tool that returns the relevant chunk and stops there. The README lists Claude Code, Cursor, Codex, OpenCode and VS Code as targets, and describes three integration shapes: an MCP server, CLI instructions written into AGENTS.md or CLAUDE.md, and a dedicated sub-agent called semble-search.
How the index and query path actually work
The mechanism is embedding-based retrieval over code chunks. The README says Semble matches the retrieval quality of a code-specialized transformer while indexing about 480 times faster and querying about 23 times faster, and it reports NDCG@10 of 0.855 on its own benchmarks. Those numbers come from the project's own benchmarks, not from independent measurement, so treat the figures as the project's own. The operational properties are more useful than the scores. Everything runs on CPU, with no API keys, no GPU and no external services. Indexes are built and cached on first run and, per the CLI section, invalidated automatically when files change. A full codebase index and search completes in under a second according to the README, with an average repo indexed in around 500 ms and queries answered in around 1 ms. The data flow is: point Semble at a local path or a git URL, it clones on demand if remote, chunks the files it decides to index, embeds them, caches the index, and returns ranked snippets with path and line range. The agent never sees the rest of the file unless it asks for it.
Installing it and pointing an agent at it
The documented path is uv. Install uv, then run uv tool install semble followed by semble install. The installer detects coding agents such as Claude Code, Codex and OpenCode and prompts for which integrations to enable: the MCP server, the AGENTS.md or CLAUDE.md instructions, or the semble-search sub-agent. semble uninstall reverses it. For scripted or sandboxed environments the README gives the non-interactive form: semble install --agent claude --type mcp subagent --yes. The --agent flag takes one or more agent ids such as claude, codex or pi. The --type flag accepts mcp, instructions, subagent, skill or all, with all but skill as the default, and --yes skips the confirmation prompt but requires --agent for a fully unattended run. Without the installer, the CLI is standalone: semble search "authentication flow" ./my-project builds and caches an index on first use. Flags worth knowing are --top-k to limit results and --content with values code, docs, config or all. There is also a find-related command, which takes a known location and finds similar code. If the binary is not on PATH, the README suggests uvx --from "semble[mcp]" semble as a substitute. Upgrades are uv tool upgrade semble, and MCP users are told to run uv cache clean semble and restart the MCP client.
Ignore rules decide what the index can ever find
This is the part most likely to surprise a new user. Semble reads both .gitignore and .sembleignore, merges their patterns, and applies them recursively, so a .sembleignore in a subdirectory governs that subtree. The separate file exists so you can add Semble-specific rules without editing .gitignore. Exclusions work as in gitignore: a line like generated/ or *.pb.go drops matching files. Inclusions use a leading exclamation mark, and the README's examples are !*.proto and !*.cob, which force-include Protobuf and COBOL files that Semble would not index by default. That last detail is the constraint. Semble has a default set of indexed extensions, and anything outside it is invisible to search unless you opt in explicitly. It also always skips well-known non-source directories regardless of ignore files, listing node_modules/, .venv/, dist/, build/ and __pycache__/ among them. If your question is about a file in dist/ or a generated client, retrieval will not surface it and the agent will get an empty or misleading result with no obvious signal about why.
The savings counter and what it does not prove
Semble ships a command called semble savings that prints accumulated token savings across searches, broken down by period. The README's sample output shows totals in the hundreds of millions of tokens and a ratio near 94 percent. This is a self-reported counter maintained by the tool, so it is not an independent measurement. It is useful as a rough indicator that retrieval is returning small snippets rather than whole files. It is not a measurement of whether the agent answered correctly, and a high ratio is consistent with an agent that is being handed the wrong chunks cheaply. The README's own benchmark claim is the 99 percent figure; the savings command reports a lower number in the sample output, which is worth noting if you plan to quote either one.
Where embedding search is the wrong instrument
Natural-language retrieval and exact matching solve different problems, and Semble is built for the first. If you need every call site of a specific symbol, or you are auditing for a literal string such as a hardcoded credential or a deprecated API name, an embedding index can rank a semantically similar function above the exact match you wanted, and it may omit the exact match entirely if it falls outside the top k. The --top-k flag is the only lever for recall, and raising it costs tokens, which erodes the premise. A second limitation is the default extension set combined with the always-skipped directories. A third is that the retrieval quality numbers are the project's own, on the project's own benchmarks. The honest framing is that Semble is a context-reduction tool that happens to search code, not a replacement for grep in a debugging session where you need certainty about coverage.
How it differs from a code-specialized embedding model you host yourself
The obvious comparison is running a code embedding model directly, the way the project's own model2vec repository is used as a remote example in the search command. The difference is packaging and cost profile rather than retrieval concept. A code-specialized transformer typically needs a model download, a vector store, and enough memory to hold the encoder; Semble's pitch is that the whole thing runs on CPU with no external service and indexes an average repo in roughly half a second. The README's 480x indexing and 23x querying comparisons are against exactly that kind of model. The trade-off is control. With your own encoder and store you choose the chunking strategy, the distance metric and the index refresh policy. Semble makes those decisions for you; the README shows --content, --top-k, --format and the ignore files as adjustment points.
Licence, upgrade path and maintenance surface
Semble is MIT licensed, which permits commercial use, modification and redistribution provided the copyright notice and permission notice are retained. That is the permissive end of the spectrum and imposes no copyleft obligation on your own code, but the usual caveat applies: read the LICENSE file in the repository rather than relying on a summary, and if you redistribute Semble inside a product, keep the notice intact. This is not legal advice. On maintenance, the release cadence is three releases in about three and a half weeks, v0.6.2 through v0.7.1, with the last push in November 2026. The project is not archived. The upgrade path is a single command, uv tool upgrade semble, with an extra cache clean step for MCP users followed by a client restart. The cache clean step in the README suggests the MCP path can hold stale state. The maintenance cost for a team is low: no server to run, no API key to rotate, no vector database to back up. The cost that does not disappear is the ignore-file maintenance, since the ignore files control much of what is searchable and they drift as a repository grows.
Editorial conclusion
Adopt Semble if you run a coding agent on a repository that is too large to grep comfortably and you want retrieval to stay local, with no API key and no GPU. Skip it if your workflow depends on exact string matching, on searching inside generated or vendored code that the ignore rules exclude by default, or on a language whose extension is not in the default index set. Before trusting it, run semble search on a query whose answer you already know, check whether the returned line ranges actually contain that answer, and run semble savings afterwards to see whether the token accounting matches what your agent session reports.
Frequently asked questions
What is Semble?
Semble is a Python code search library and CLI built for coding agents. It indexes a repository so an agent can ask a question in natural language and get back the relevant code snippets, instead of grepping and reading full files. It uses static embeddings and runs on CPU with no API key, GPU or external service.
How do I install Semble?
Install uv, then run `uv tool install semble` followed by `semble install`. The second command detects installed agents such as Claude Code, Codex and OpenCode and lets you enable the MCP server, CLI instructions in AGENTS.md or CLAUDE.md, or a `semble-search` sub-agent. `semble uninstall` undoes the setup.
How do I use Semble day to day?
Through MCP, through a sub-agent, or from the command line with `semble search "authentication flow" ./my-project`. Indexes are built and cached on first run and invalidated when files change. Useful flags: `--top-k` to limit results, `--content` to include docs, config or all instead of code only, `--format text` for readable output.
What is Semble used for?
Cutting down the tokens an agent spends finding code. It reports using roughly 99% fewer tokens than a grep and read approach, indexing an average repository in about 500 ms and answering in about 1 ms on CPU. It also works as a standalone CLI in scripts, searching local paths or git URLs, and can search several repositories as one corpus.
Is Semble safe to run?
It is MIT licensed and runs locally on CPU with no API keys, GPU or external services. It reads your source files to build an index and respects `.gitignore` plus `.sembleignore` for what to index, and `semble install` writes agent configuration that `semble uninstall` removes.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/minishlab-semble)Star history chart for your README
[](https://hysenlabs.com/projects/minishlab-semble)Was this useful?