MedicalGPT: three tags in two weeks, then five months of commits
MedicalGPT: train your own medical GPT model with a ChatGPT-style training pipeline, including continued pretraining (PT), supervised fine-tuning (SFT), RLHF, DPO, ORPO and GRPO.
At a glance
- What is it?
- A training pipeline for medical language models, assembled from named papers and one conference talk, whose stage three lists four preference optimization methods while the project's own description counts a fifth.
- Who is it for?
- This is a pipeline to read if you already know how to drive supervised fine-tuning and want one repository that covers continued pretraining, reward modelling, DPO, ORPO, GRPO and on-policy distillation against the same entry point shape. It is not an evaluation result, and the page never claims to be: not one of the medical model news entries carries a metric, a dataset size or a baseline, and the repository ships a DISCLAIMER file next to the code.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 61 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
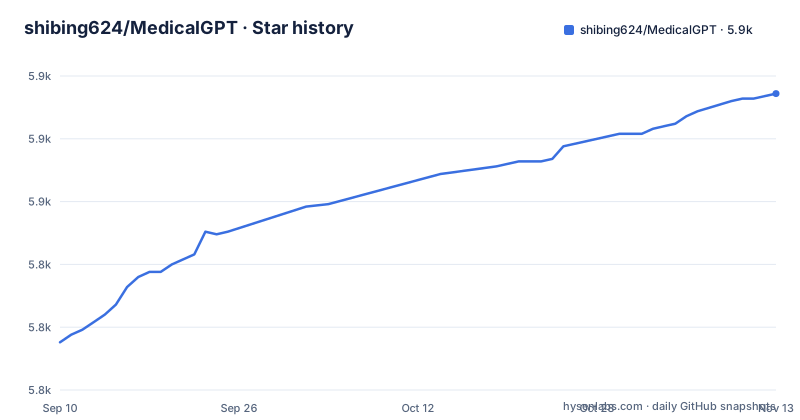
Star history
- shibing624/MedicalGPT5,893 ★ · +99
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| shibing624/MedicalGPT | 5.8k | 5.9k |
99 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The stage three list has four methods and the project description counts five
The training pipeline is laid out as three stages. Stage one is continued pretraining on domain documents, and it is marked optional. Stage two is supervised fine-tuning on instruction data. Stage three is where the choices live, and the page lists four things inside it.
The first is RLHF, split into two steps: a reward model trained on ranked human preference data, following what the page calls the HHH principle, helpful, honest and harmless, and then reinforcement learning where that reward model updates the policy. The second is DPO, described as optimising the model directly without the machinery of reinforcement learning. The third is ORPO, which needs no reference model and folds SFT and alignment into one step, which the page says mitigates catastrophic forgetting. The fourth is on-policy distillation, abbreviated OPD in this README, where a stronger teacher supervises a student's output distribution along the student's own rollout trajectories, not trained jointly with PPO or GRPO in the first version, and producing an artefact that deploys like an SFT model.
The repository's own description line also names GRPO, which appears in the stage three list nowhere. It shows up in the news entries for v2.4 and v2.5, and in the OPD line, which says the first version is not trained jointly with PPO/GRPO.
Three tags in thirteen days, and then a push with no tag behind it
The three most recent releases are 2.5.0 on 2026-04-07, 2.6.0 on 2026-04-14 and 2.7.0 on 2026-04-20. That is a fortnight in which the project added support for a model family, added agent tool call training, and added on-policy distillation, with a release note for each.
Since then the repository has been pushed to, most recently on 2026-09-15, and nothing has been tagged. Five months of pushes are sitting on the default branch with no release behind them, which means the version in the news section at the top of the page is the newest thing you can install by tag, and the newest code is something you have to pull.
The longer cadence is the other half of the story. Between v2.4 on 2025-04-18 and v2.5 on 2026-04-07 there is almost exactly a year with no entry at all. So the shape is a long silence, a burst of three releases inside a month, and then a longer silence. Nothing on the page says whether the recent work is being held back deliberately.
A disclaimer at the root, and model weights on a model hub
The repository ships a `DISCLAIMER` file at the root next to the license. For a project whose published artefacts are fine-tuned weights for Chinese medical question answering, that is the single most load-bearing file in the tree, and the visible part of the page does not mention it.
The weights themselves are released rather than merely described. The news entries record a LoRA adapter and a merged full-weight model for a 13B medical model based on Ziya-LLaMA-13B-v1, and a Chinese and English Vicuna-13B model fine-tuned on ShareGPT4 with its LoRA counterpart, both published on a model hub under the same account as the repository. The role play feature added in v2.2 went further and pointed at generation scripts for doctor and patient dialogue data, with support for OpenAI and two domestic providers.
What none of those entries carries is a number. The medical entries say the question answering improved. They do not name a benchmark, a test set, a baseline model, a sample size or an evaluation protocol, so the claim cannot be checked against those entries. This is a training codebase rather than a result, and the difference matters to anyone deciding whether to use the weights.
The quantisation library is commented out and DeepSpeed is absent
The dependency file is short, and it has one line that is commented out on purpose:
accelerate
datasets>=2.14.6
loguru
peft>=0.19.1
sentencepiece
scikit-learn
tensorboard
tqdm>=4.47.0
transformers>=5.6.0
trl>=0.29.0
# bitsandbytes # not available on pypi
latex2sympy2_extended
math-verify==0.5.2
The comment says bitsandbytes is not available on PyPI, which means the quantised training and inference paths it backs are not installed by following the requirements file. You are expected to source it separately.
The other gap is bigger. The v2.5 news entry says mixture of experts training is supported through DeepSpeed ZeRO-3, and DeepSpeed is not in the file. Six packages carry no version bound at all, including the accelerator and the tensor board, while `transformers` is floored at a major version well past what most existing fine-tuning scripts were written against, and `trl` is floored too. At the bottom sit two packages that have nothing to do with medicine: a LaTeX to SymPy converter and an exact pin on a maths verification library at version 0.5.2. Something in the pipeline is evaluating mathematical output.
Six demo entry points for one set of weights
The `demo` directory holds six scripts, and they are the deployment surface of the whole project:
`inference.py`, `inference_multigpu_demo.py`, `fastapi_server_demo.py`, `gradio_demo.py`, `openai_api.py` and `chatpdf.py`.
Read together they describe what you are expected to do with a model you trained here. Run inference directly, or split it across multiple GPUs. Wrap it in a FastAPI service, or give it a Gradio interface. Expose it through an OpenAI compatible API.
`chatpdf.py` is the odd one out. It arrived in v1.7 as a retrieval augmented question answering feature that combines the fine-tuned model with a document knowledge base, and its news entry links to a separate ChatPDF repository while naming the code as `demo/chatpdf.py` in this one.
The RLHF stage is four sentences and one conference talk
The page credits its methods rather than claiming them. The RLHF pipeline is attributed to a state of GPT talk by Andrej Karpathy, linked as a PDF, and to a conference video on the same topic. DPO is attributed to the paper on direct preference optimisation, ORPO to the monolithic preference optimisation paper that removes the need for a reference model, and the v2.4 entry attributes GRPO to its own paper.
That is the right way to build this, and it also sets a limit. Once a stage is credited to someone else's method, this repository's contribution is the wiring: the scripts under `scripts/`, the entry points under `training/`, the chat templates and the data formats. The OPD entry, for instance, names its own new files, a training module and a shell script, which is the level of detail a reader can actually use.
Earlier entries follow the same pattern of adopting published techniques: RoPE interpolation for extending context length, the squared attention method from LongLoRA for LLaMA models, noise on embeddings during training, and mixture of experts fine-tuning for Mixtral. The v1.3 entry is the widest, adding multi-turn fine-tuning for six model families along with domain vocabulary expansion and Chinese pretraining and instruction datasets.
One model upgrade added four chat templates, two of them for thinking turned off
The v2.5 entry is the most concrete thing on the page. Supporting one model family meant four new chat templates: `qwen3`, `qwen3_5`, `qwen3_nothink` and `qwen3_5_nothink`, covering the base, instruct and mixture of experts variants of that family. Two of the four exist purely to turn off the thinking behaviour, which means the templates are not a naming convenience but the switch that decides whether the model emits reasoning traces before its answer.
The same release adapted the whole flow, claiming the pretraining, fine-tuning and preference optimization paths all work against the new family. The v2.6 entry, two days later, added agent tool call and function call fine-tuning, with code to convert and parse tool data formats for different models and a sample tool call dataset added under `data`.
That is the shape of the project's real work, and the page is honest about it. What is easy to miss is that a chat template is the place where a model's special tokens and turn markers are defined, so a mismatch there produces degraded output rather than an error. Four templates with two of them toggling behaviour off is more surface area than the single sentence in the news log suggests.
Editorial conclusion
This is a pipeline to read if you already know how to drive supervised fine-tuning and want one repository that covers continued pretraining, reward modelling, DPO, ORPO, GRPO and on-policy distillation against the same entry point shape. It is not an evaluation result, and the page never claims to be: not one of the medical model news entries carries a metric, a dataset size or a baseline, and the repository ships a DISCLAIMER file next to the code. Before you build on it, check what your GPU budget actually needs, since the quantisation library is commented out of the requirements file as unavailable from PyPI and the DeepSpeed path used for mixture of experts training is not listed there at all.
Frequently asked questions
What is MedicalGPT?
It is a training pipeline for medical language models, not a released chatbot. The page lays out continued pretraining, supervised fine-tuning and a third stage covering RLHF with a reward model, DPO, ORPO and on-policy distillation, with GRPO named in the repository description and the v2.4 news entry.
Does MedicalGPT publish a medical model I can download?
Yes. The news entries record a LoRA adapter and a merged model for a 13B medical model based on Ziya-LLaMA-13B-v1, plus a Chinese and English Vicuna-13B model and its LoRA version, all published on a model hub under the same account as the repository. The repository also ships a DISCLAIMER file at its root.
What does MedicalGPT require to install?
The requirements file lists thirteen lines, with `transformers` floored at 5.6.0 and `trl` at 0.29.0, and six packages carrying no version bound. The bitsandbytes line is commented out with the note that it is not available on PyPI, and DeepSpeed, used for the mixture of experts path, is not listed at all.
Is medicalgpt production ready for diagnosis use?
The repository is a training codebase and none of the news entries names a benchmark, test set or baseline; they say only that medical question answering improved. A DISCLAIMER file sits at the root of the repository, and the newest tag is 2.7.0 from 2026-04-20.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shibing624-medicalgpt)Star history chart for your README
[](https://hysenlabs.com/projects/shibing624-medicalgpt)Was this useful?