tick-stock-panel: a self-hosted A-share workbench that stops before it recommends anything
TSP is a self-hosted, zero-maintenance quant workbench for A-share stock picking, monitoring and backtesting, with LLM-driven strategy customization, stock analysis and review. Freely connect third-party data sources and custom data. A personal open-source project, not an official third-party product.
At a glance
- What is it?
- TSP bundles screening, backtesting, intraday monitoring and post-close review into one Docker container over local Parquet files, and it draws its own limits in writing: no stock recommendations, no limit-up prediction, and factor candidates that never publish themselves.
- Who is it for?
- TSP suits a solo A-share researcher who wants the whole chain in one container and is willing to own data sources, keys and patching themselves. It does not suit anyone expecting a terminal, a recommendation feed or a hosted service.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
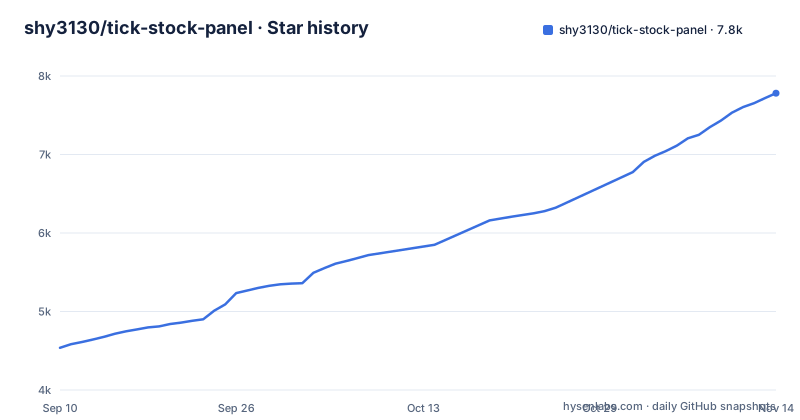
- shy3130/tick-stock-panel7,781 ★ · +3,243
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| shy3130/tick-stock-panel | 4.5k | 7.8k |
3,243 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One container, one FastAPI process, and a dist bundle it serves itself
The deployment story is a single service. The compose file in the repository root declares one service named `app`, builds it from the repo `Dockerfile`, names the container `TickFlow_Stock_Panel`, and maps `${HOST:-0.0.0.0}:${PORT:-3018}:3018`. Its own comment explains the shape: FastAPI starts, serves the API, and also hosts the built frontend `dist`. There is no separate web container and no database service to run, which is what the badge means by one container and zero external database.
The image build is two stage. A `node:20-alpine` stage installs pnpm, reads `frontend/package.json` and the lockfile, and runs `pnpm build`; the output is copied into the backend image. A second stage installs a pinned Codex CLI (`CODEX_CLI_VERSION`, default 0.144.3) and copies only its binary into the runtime image. Registry choices are build args too: `USE_CN_MIRROR=1` is the default, `NPM_REGISTRY` points at `registry.npmmirror.com`, `PYPI_INDEX` at the Tsinghua mirror, and `PYPI_FALLBACK` at Aliyun for when the primary index lags.
Development does not require the container at all: the tree ships `dev.sh` and `dev.ps1`, and `BACKEND_EXTRAS` is the switch for older CPUs without AVX2 and FMA support, documented as a value like `legacy-cpu backtest`.
Six data capabilities route independently so a source swap keeps the caliber
The problem the project names first is data source lock in: if a script hardwires one vendor, changing vendor means rewriting the fetch layer. The answer is a capability routing matrix, where six kinds of dataset are routed independently by what a source can actually deliver, so the indicator definitions and the backtest caliber stay put while the source underneath changes.
The panel reads that the sources are pluginized, so a third-party source can be plugged in rather than patched into the core, and extension fields can be turned into pages. History is filled in by day.
What you get is local data stored as Parquet rather than a live feed contract. That is convenient for a single user and it is also the boundary: nothing here negotiates a data license for you.
One enriched Parquet table carries screening into backtesting and review
The unifying object is an enriched Parquet table with 68 columns of indicators and signals, written in a single table scan. Screening, backtesting, monitoring and post-close review all read that same table, which is the reason a signal you screened this morning can be monitored live and reviewed after close without re-deriving anything.
Screening runs fully custom strategies plus custom signals and AI generated ones over the whole A-share market with Polars, at millisecond scale by the README's claim. Backtesting has four research views covering factor, strategy and minute backtests, with T plus 1 rules, fees, slippage and factor attribution, and parameter selection is checked with rolling out-of-sample tests.
Factor work has its own loop: a DSL for custom factors plus testing and combination, linked in both directions with strategies.
Write actions stall on a confirmation card that times out after 120 seconds
The AI assistant answers questions about data across the whole panel, and each retrieval step is shown and can be expanded and checked. It can also generate signals, run backtests and backfill data, but only after you approve a confirmation card. The README describes the assistant as the reference implementation of the extension layer, and deleting an extension's directory uninstalls it.
Configuration for the assistant is optional. `AI_PROVIDER` accepts `openai_compat` or `ollama`, the shipped default base URL points at a DeepSeek compatible endpoint with `deepseek-chat` as the model, and `AI_DAILY_TOKEN_BUDGET` defaults to 500000. Leaving the AI block blank skips those features rather than failing startup, which is worth knowing before you wire a self-hosted model in.
Mined factor candidates enter the library and wait for you to publish them
The mining page is the part of the project most likely to surprise you, because it produces candidates and then refuses to use them. Search over multi-factor combinations is out of sample. Candidates land in the library, publication happens only after an explicit confirmation, and nothing goes live automatically.
For a researcher that guardrail is the point. A search that quietly promoted its own best-looking factor into a live strategy would be the standard way factor platforms poison results, and the project refuses it in the interface rather than in a warning. The cost is that a mining run produces nothing measurable until you sit down and publish, so a schedule that only runs mining will look idle.
Around it sit the manual equivalents: the stock analysis page pairs nine categories of key price levels with a four-dimension AI analysis, the market regime page divides sentiment into six stages and ranks concept and industry themes, and the limit-up ladder adds consecutive-board statistics, concept rotation and a post-close AI review.
A relative DATA_DIR in your .env is ignored by the container on purpose
This is the single most useful line in the compose file. `DATA_DIR=./data` in `.env` is a development setting, and the compose file overrides it:
    environment:
      # 强制固定为容器内绝对路径, 防止 .env 里的 DATA_DIR=./data(开发模式用)
      # 被 env_file 原样传入容器后按错误的相对路径解析, 写到未挂载卷的目录,
      # 导致每次 up --build 重建容器都丢数据。environment 优先级高于 env_file,
      # 无论 .env 怎么写这里都以容器路径为准。
      - DATA_DIR=/app/data
Because `environment` outranks `env_file`, the container path wins no matter what `.env` says. The reasoning is spelled out in the comment: a relative path passed through as-is would resolve against the wrong directory, write into a directory that is not the mounted volume, and lose data on every rebuild. Volume mounts keep the rest of the state visible: `./data` to `/app/data`, `tiers.yaml` and `.env` both read-only, and your host Codex home mapped read-only so the backend can copy it into a temporary `CODEX_HOME` per request. There is also an extra host entry for `host.docker.internal` and a `restart: unless-stopped` policy.
The stock-sdk scraper plugin is excluded from the image by default
The shipped default expects an API key: leaving `TICKFLOW_API_KEY` blank puts the panel in a Free trial mode that reaches only historical daily K for a single stock, which is enough to look around and not enough to run the intraday features that depend on live quotes. Anything richer has to come through the pluginized source layer you are allowed to use.
The repository is not archived, and the last push landed on 2 November 2026 with tag `v0.3.27` published the same day, so the interface is still moving.
The project states what it refuses to become, and what is still unbuilt
The README opens its scope section with a warning rather than a feature list. The project offers a way to solve problems locally and is explicitly not investment software and not a market-watching tool. It does not position itself against Tonghuashun or TongdaXin, and it does not include AI stock recommendation or limit-up prediction. The repository description repeats that it is a personal open-source project and not a third-party official product.
The clearest limit shows up inside intraday monitoring, where three tabs cover the trading timeline. The README says this covers auction, intraday and deviation anomalies on one page, with real-time pop-ups, voice alerts and Feishu push.
A reader who wanted a recommendation feed will find a wall. What remains is research tooling: unified caliber, factor work, backtesting with costs and slippage, and an open surface of 65 API endpoints across six token tiers plus 12 MCP tools for AI clients.
Editorial conclusion
TSP suits a solo A-share researcher who wants the whole chain in one container and is willing to own data sources, keys and patching themselves. It does not suit anyone expecting a terminal, a recommendation feed or a hosted service. Before you rely on it, check which of the six routed data capabilities your key actually unlocks, and confirm the bind mount for your data directory survives a rebuild.
Frequently asked questions
Do I need a paid data terminal to use tick-stock-panel?
No terminal is required to run it. Leaving `TICKFLOW_API_KEY` blank starts the panel in Free trial mode, which is limited to historical daily K data for a single stock. Third-party sources can be added through the pluginized data source layer, and richer live data comes from a key you supply.
Can tick-stock-panel run a backtest for me without asking?
No. The README says the AI assistant can generate signals, run backtests and backfill data only after you approve them on a confirmation card.
What stops mined factors from going live by themselves?
Mining searches multi-factor combinations out of sample, and the README says publication is explicit and mined results never go live by themselves.
Why does my DATA_DIR change in .env not take effect?
The compose file sets `DATA_DIR=/app/data` in `environment`, which outranks `env_file`. The comment explains why: a relative `DATA_DIR=./data` passed through from `.env` would resolve incorrectly, write to a directory that is not the mounted volume, and lose data on every rebuild.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shy3130-tick-stock-panel)Star history chart for your README
[](https://hysenlabs.com/projects/shy3130-tick-stock-panel)Was this useful?