SimpleKernel: the headers are the lesson, and five of the thirteen interfaces are header-only anyway
Interface-Driven OS Kernel for AI-Assisted Learning.
At a glance
- What is it?
- SimpleKernel is a teaching kernel written in C++23 for two architectures, built around an unusual premise: a learner should read interfaces rather than implementations, have a coding assistant produce the implementation, and validate it with the bundled tests. The premise is stated clearly and repeated with diagrams. What the interface table quietly undercuts is the same document's claim that headers hold declarations only.
- Who is it for?
- Use it if you want a kernel whose reading material is contracts rather than code, and if you are content to let a tool write the implementation against them. Read the interface table before you start, because the stated rule is that headers carry declarations and implementations live in separate files, and five of the thirteen entries are marked header-only instead.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
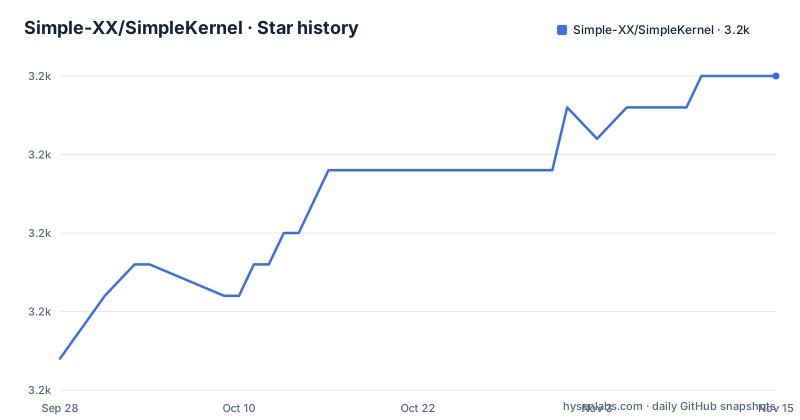
Star history
- Simple-XX/SimpleKernel3,215 ★ · +9
| Repository | 2026-09-28 | 2026-11-15 |
|---|---|---|
| Simple-XX/SimpleKernel | 3.2k | 3.2k |
9 Stars in the last 48 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The premise is that you should not read the implementation
The project states its method in one line and then argues for it at length.
The design goal is an interface-driven kernel: the body of the project is the interface definitions. Headers carry class declarations, pure virtual interfaces, type definitions, and Doxygen documentation. The implementation is produced by an AI coding assistant, and a reference implementation is included so that generated code can be checked against something known to work.
The traditional path it argues against is named explicitly: read the code, understand the principles, imitate and modify. Three objections are raised against it. Kernel code is large enough that a beginner gets lost in implementation detail. Modules are tightly coupled, so a single subsystem cannot be understood in isolation. And implementing a module from scratch has a high threshold with a long feedback cycle.
The replacement path is four steps: read an interface, understand the contract, let the assistant implement it, and verify with tests. The document says the Doxygen comments on an interface are the best prompt available, which is the whole thesis in a sentence.
Five of thirteen interfaces are header-only, against the stated rule
The document has a rule and an exception, and the exception is in a table.
The rule is interface and implementation separation: headers contain only declarations and contracts, with implementations in separate source files. That is stated in the highlights table and repeated in the project summary.
Then comes the interface table, which lists thirteen headers and, for each, where its implementation lives. Eight point at a separate source file. Five do not:
The five header-only entries are the device manager, the driver registry, the platform bus that enumerates the device tree, a UART driver written in the probe and remove pattern, and the spinlock interface, the last of which is marked header-only for performance reasons.
That is not a fatal contradiction, since a header-only component is a legitimate design and the spinlock case is argued explicitly. But it does mean the principle is a guideline rather than a rule, and a learner told that implementations live in separate files will find five that do not. The table is the more precise document.
Two architectures with different boot chains and different interrupt models
The support matrix is a small table and it is worth reading closely, because the two architectures differ in every column.
RISC-V 64 boots through a bootloader and an openSBI implementation, writes to the serial port through an SBI call, handles interrupts in what the table calls Direct mode, and takes its time from the SBI timer.
AArch64 boots through the same bootloader with a trusted firmware and a secure world component, uses a specific UART, takes interrupts through a version three generic interrupt controller, and reads the generic timer.
So the same interfaces sit on top of two quite different machines: one with a priority controller and one without, one timer path and another, and two different boot handoffs before the kernel runs at all. The interrupt interface's own documentation names the known implementations for each architecture, which is the clearest statement of how the abstraction is supposed to hold together.
The project also records an interface for the architecture-independent entry point, with implementations in per-architecture subdirectories.
The documented build runs inside a container, and the presets are named after the architecture
The setup section offers two methods and recommends the first by a wide margin.
The recommended one is a development container. Clone the repository, then either reopen it in a container from the editor, or drive the same container from the command line with a globally installed tool:
git clone https://github.com/simple-xx/SimpleKernel.git
cd SimpleKernel
and then two commands that bring up the environment and open a shell in it. Hosted workspaces are supported through a button on the repository page, and a local setup is documented separately in a file whose name is in Chinese.
Inside the environment, the build is a preset name and a make target:
cmake --preset build_riscv64
cd build_riscv64
followed by a target that builds the kernel, one that runs it under an emulator, and one that runs the unit tests. Two presets exist, one per architecture, and the toolchain, cross compiler, build system and emulator are all listed as already present in the container, which is the reason the container is the recommended path rather than an optional convenience.
The reference implementation is the answer key for generated code
The fourth step of the workflow is the one that makes the method safe, and it is stated more briefly than the other three.
After the tests run, if something does not pass, the documentation says you can consult the reference implementation provided by the project to compare and learn from it.
That makes the repository self-verifying in a specific sense. The interfaces are the exercise, the assistant produces a candidate, the test suite decides whether the candidate satisfies the contract, and the reference implementation is the fallback explanation for a failure. None of those four roles is stated as a formal grading policy, and the tutorials are not part of any assessed assignment, but the structure is unambiguous.
The testing half is named in the highlights as contract verification: a GoogleTest suite checks that generated implementations match the interface contract. The documentation also suggests the reverse order for a learner who wants to think first, work out an implementation, and then compare it against what the assistant produced, which is a different use of the same four artefacts.
Four diagrams in this copy of the document stop mid-drawing
This copy of the readme is the Chinese version, and an English version sits beside it at the root. The Chinese file is structured with a table of contents of eleven sections, and it leans on box-drawing diagrams to carry its arguments.
Three of those diagrams do not finish.
The workflow diagram, which draws the four steps from interface to test, breaks off in the middle of a connector line near the bottom. The layered architecture diagram, which stacks the syscall layer over task management, memory management, and interrupt handling, stops mid-word in its interrupt layer. The project structure tree stops partway into the device directory, with a comment column that has been cut in half.
The learning path section is cut differently: it opens with advice to work through the modules in order, and then stops inside the heading of its first stage, mid-word.
None of this changes what the project is, and a reader of the full page on a hosting site would see the complete diagrams. But anyone working from this text is missing the closing half of the flow chart, the bottom of the layer stack, the tail of the directory tree, and the stage list that the table of contents promises.
The licence badge points at a labour-law initiative, and the licence field says nothing
The badge row at the top of the document contains two links that do not look like the rest of it.
One goes to a repository about a numeric reference in a set of labour regulations, and the other to that project's website. Those are not software licences. The usual reason for a badge of that shape is a reference to the specific numeric provision a project wants its readers to know about, but what the readme is asking for is not stated anywhere in the visible text.
Meanwhile the repository has its own licence file at the root, and the project's licence field in its metadata records nothing at all.
So a reader has three sources and no statement of how they relate: a file in the repository, an empty field, and a badge pointing at a document that is about employment law rather than about software. The readme does have a licence section in its table of contents, which is the place where the relationship would be explained, and that section falls past the end of the text available here.
Editorial conclusion
Use it if you want a kernel whose reading material is contracts rather than code, and if you are content to let a tool write the implementation against them. Read the interface table before you start, because the stated rule is that headers carry declarations and implementations live in separate files, and five of the thirteen entries are marked header-only instead. Also note what the environment requires: the documented path runs inside a development container, the last commit is dated 2026-03-20, and this copy of the documentation is the Chinese one.
Frequently asked questions
How can I create my own kernel?
This repository proposes starting from interfaces rather than from an empty file. Read a header, understand the contract it documents, hand the header to a coding assistant as context, ask for the implementation in the matching source file, and run the bundled tests to check the result. The interfaces are C++23 pure virtual classes with descriptions, preconditions and postconditions in Doxygen comments.
What are the three types of kernels?
This repository does not classify kernels; monolithic, microkernel and hybrid designs are not discussed anywhere in it. Its own layer diagram is organised by function instead, stacking the syscall layer above task management, then memory management, then interrupt and exception handling, with interface types named at each level.
What is SimpleKernel?
It is a teaching operating system kernel written in C++23 for RISC-V 64 and AArch64, built on the idea that the headers are the lesson and the implementation is something a coding assistant writes against them. A reference implementation and a GoogleTest suite are included so that generated code can be validated, and the most recent commit is dated 2026-03-20.
Can you give me an example of a kernel?
The worked example in the repository is the interrupt subsystem: an abstract base class with two pure virtual methods, one executing a handler given a cause code and a trap context, one registering a handler for a cause. The documentation names the known implementations per architecture, a platform interrupt controller for RISC-V and a generic interrupt controller for AArch64.
How do you build SimpleKernel?
The documented path is a development container. Clone the repository, then reopen it in a container from the editor or drive the container from the command line. Inside it, configure with the preset for your target architecture, build the kernel target, run it under the emulator, and run the unit test target. A local setup without a container is documented in a separate file.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/simple-xx-simplekernel)Star history chart for your README
[](https://hysenlabs.com/projects/simple-xx-simplekernel)Was this useful?