GustoBot routes first, then fans one question out across five data stores
Five-Star Chef: a fully multi-agent customer-service chatbot built on LangGraph, with text-to-SQL, text-to-Cypher, LightRAG, and multimodal capabilities.
At a glance
- What is it?
- A multi-agent customer service system for recipe knowledge, built as a template to be retargeted at other domains. A router picks a subgraph, a planner splits the question, and up to four tool calls run in parallel against a graph database, a relational store, two vector stores and an external search.
- Who is it for?
- This fits someone building a domain assistant and wanting the routing, guardrails and fallback order already designed, since the separation of router, subgraph and atomic tools is the reusable part and the recipe domain is the swappable part. It does not fit a small personal project, because standing up five data stores to answer cooking questions is a large deployment for the problem.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
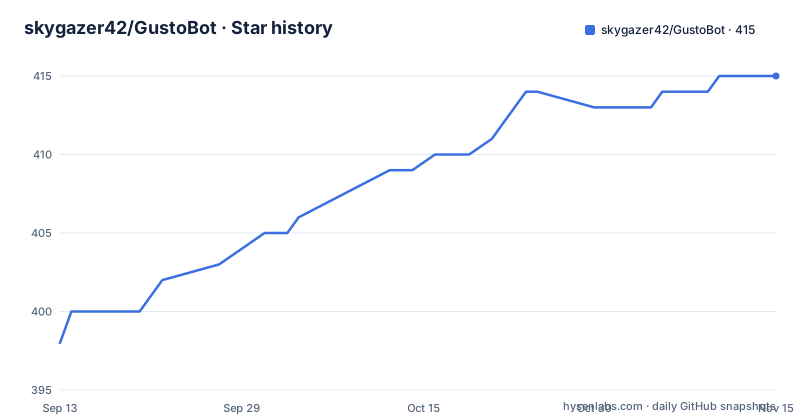
Star history
- skygazer42/GustoBot415 ★ · +17
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| skygazer42/GustoBot | 398 | 415 |
17 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three layers, and the router is the part you cannot swap out
The architecture is three layers, and the split is by responsibility rather than by feature.
The top layer is a main router that recognises intent and dispatches. The middle layer is a set of subgraphs that decompose a task and orchestrate tools. The bottom layer is a set of atomic tools that each talk to one data store.
The router itself has two independent mechanisms behind it: heuristic keywords and a language model, described as double insurance. A prompt guides the model into choosing a category, the heuristics catch what the model misses, and the output is a structured model rather than prose, so the next node can branch on a field rather than parse a sentence.
Seven query types are supported. A conditional edge reads the chosen type and dispatches to a subgraph, and the same node also checks whether an image or a file was attached, since an attachment changes which path makes sense.
One route is worth calling out because it bypasses the machinery entirely: a general question route that generates an answer with the model alone and calls no external tool at all.
That is the design decision to keep in mind when retargeting the system. The router is the only layer with no data-source dependency in it, so it is the layer you will edit least.
PostgreSQL first, then Milvus, then an external search
Retrieval is ordered, and the order is the same everywhere it appears: structured data first, semantic search as the fallback, and an outside search only in hybrid mode.
The reasoning is about cost as much as quality. A recipe name, a cuisine or an ingredient list is structured, and asking a relational store with a vector extension for it returns something precise and fast. Long passages such as historical anecdotes are the opposite, and those go to the vector store.
The knowledge base subgraph spells the rule out step by step: query the structured store first, and if it returns anything, use it and skip the second store entirely.
That skip is the part that matters. It means a well-covered question costs one lookup rather than two, which is the behaviour you want when a chain of agent nodes is already multiplying the number of calls.
The third step is different in kind. An external search API is only consulted in hybrid mode, and it is described as supplementing for recent information rather than as part of the retrieval chain.
One question can fan out into four parallel tool calls
The graph subgraph is where the multi-agent naming earns its keep.
A question enters a guardrails node, which checks scope and validates the graph schema before anything is attempted. A planner node then breaks the question into independent subtasks. A tool selection node shows the model the available tool schemas and lets it choose, with up to four tools run in parallel.
The four are deliberately different in kind. One generates a graph query on the fly. One uses a predefined query template. One retrieves community summaries through a graph-augmented pipeline. One converts natural language into SQL for statistical questions against a relational store.
Then two nodes collapse the results: one merges everything and gives the model a first pass at tidying it, and one writes the final answer, citing sources and optionally running a check for invented content.
The parallel execution is the part worth understanding before adapting this. A subtask that needs a count and a subtask that needs a relationship are genuinely independent, so running them concurrently is correct, and the summarise node is what makes the concurrency invisible to the user.
The knowledge subgraph refuses cooking questions outright
The second subgraph is narrower, and its guardrails are stricter than the first.
Where the graph subgraph checks scope in general terms, this one only handles historical and cultural questions, and explicitly rejects cooking steps and ingredient pairings. Those are the questions the other subgraph exists to answer.
After the guardrails, a router node picks between three retrieval strategies and then picks a store: local, external, or hybrid, with the structured store or the vector store underneath. The search node applies a similarity threshold, and a reranking stage runs optionally after it.
The reranking stage is where the second half of the quality control lives, and it is described with named thresholds rather than a single score. One threshold applies to the similarity returned by the search, and a second applies to the reranking score, with both configurable as named settings.
Requiring both is a stricter filter than either alone: a document can be close to the query and still rank poorly once a reranker has read it, and a document can rank well and still be outside the neighbourhood the first stage searched.
The documentation lists several reranker backends as supported, so the second stage is pluggable rather than tied to one scoring service.
One compose file, five data stores, passwords in the defaults
The runtime shape is visible in the compose file, and it is larger than the application needs to sound.
There is a relational store, a graph database, a vector store, a cache, and the backend itself, each with its own service name resolved over a private network. The backend listens on one published port, and the compose file pins the container to two public resolvers explicitly.
What is worth noting is what sits in the defaults. The relational store ships with a fixed root password, a fixed database name, a fixed user and a fixed user password. The graph database ships with a fixed account and the same fixed password reused from the relational one. The cache has a fixed port and an optional password, plus tuning values for cache lifetime, a similarity threshold and a maximum entry count.
These are development defaults, which is normal, but they are in a file that is meant to be used as-is by someone following the quick start. Anything reachable from outside a laptop needs them replaced first.
The language model settings sit in the same block, with an open provider as the default and the key supplied from the environment.
The quick start itself is short, and it makes the split explicit: the backend and its data stores go up in containers, while the web frontend is installed and started on the host.
# 克隆项目
git clone https://github.com/skygazer42/GustoBot.git
cd GustoBot

# 配置环境变量
cp .env.example .env # 编辑 .env 文件,配置必要的 API 密钥

# 启动后端服务(Docker)
docker-compose up -d

# 安装并启动前端(本地)
cd web
npm install
npm run dev

# 访问应用
# 前端: http://localhost:5173 (可通过 VITE_PORT 修改端口)
# 后端API: http://localhost:8000
Two things follow from reading it as written. The frontend port is adjustable by one variable, while the backend port is fixed in the instructions, which is the opposite of how a multi-developer setup usually needs to behave. And the frontend being on the host while the backend is in a container is why the compose file pins the resolvers it does.
The image bakes in a provider endpoint while warning against build secrets
The container build is where the configuration story gets complicated.
The image starts from a slim Python base and replaces the system package sources with a set of mirrors, then installs from a Python package mirror as well. Both substitutions are regional, which will be wrong for some users and is the kind of decision that follows whoever wrote the file rather than whoever deploys it.
The build arguments are the interesting part. There is a flag that initialises a retrieval store's data at build time, and arguments for the model endpoint, the model name, the embedding model, the embedding endpoint, the embedding dimension and an initialisation limit. The defaults are filled in with a specific provider's compatible-mode endpoint, a specific model name, a specific embedding model and a dimension of 4096.
Those defaults are then persisted as runtime environment variables, which means the endpoint chosen at build time is the one the container talks to afterwards.
And the compose file carries a comment warning not to pass secrets through build arguments because they would leak into build logs, immediately above a build step that declares arguments for an API key and an embedding key.
Both are true at once. The design intent is right and the defaults undercut it, so check what your build logs contain before building this on a machine you share.
Editorial conclusion
This fits someone building a domain assistant and wanting the routing, guardrails and fallback order already designed, since the separation of router, subgraph and atomic tools is the reusable part and the recipe domain is the swappable part. It does not fit a small personal project, because standing up five data stores to answer cooking questions is a large deployment for the problem. Two things to check before building on it. The compose file ships default database passwords, which must be replaced before anything is exposed. And the image bakes a provider endpoint and model name into its build defaults, so the build is not neutral about which service you talk to.
Frequently asked questions
What does GustoBot answer questions about?
Chinese recipe knowledge: how to cook a dish, how many dishes a cuisine contains, historical origins and anecdotes, and nutrition. It can also generate dish images, and is built as a template intended to be retargeted at other subjects.
What are the three layers of GustoBot?
A main router layer for intent recognition and dispatch, a multi-tool subgraph layer for task decomposition and parallel tool orchestration, and an atomic tool layer that runs the individual graph, relational and vector queries.
What does the PostgreSQL-first strategy in GustoBot do?
Structured data is queried in PostgreSQL with its vector extension first, and if that returns anything the second store is skipped entirely. Semantic search in Milvus handles longer passages, and an external search API is added only in hybrid mode.
Can GustoBot be pointed at a different subject?
That is the stated purpose of the design: swap the knowledge source and the graph schema. Five example domains are given with the knowledge sources and graph node types each would need.
How many query types does the GustoBot router support?
Seven. The category is chosen by heuristic keywords with a language model as a second check, and the output is a structured model, so the next node branches on a field rather than parsing text.
What does running GustoBot require?
Python 3.10, Node.js 16 or newer, and Docker with Compose. The backend and its data stores run in containers while the web frontend is installed and started locally on its own development port.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/skygazer42-gustobot)Star history chart for your README
[](https://hysenlabs.com/projects/skygazer42-gustobot)Was this useful?