DeepResearchAgent: one requirements file that also installs four exchanges
DeepResearchAgent is a hierarchical multi-agent system designed not only for deep research tasks but also for general-purpose task solving. The framework leverages a top-level planning agent to coordinate multiple specialized lower-level agents, enabling automated task decomposition and efficient execution across diverse and complex domains.
At a glance
- What is it?
- Deep Research Agent is a Python runtime for agent systems built around two protocol layers, one for resources and one for self-evolution, with a four step loop of act, observe, optimize, remember. The interesting material is in the dependency file, which is much wider than the framework's stated purpose.
- Who is it for?
- DeepResearchAgent suits a research team that wants an agent runtime where prompts, tools, environments and memory are versioned resources and where improvement runs go through an auditable propose, assess, commit loop. Four things to check before you install it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
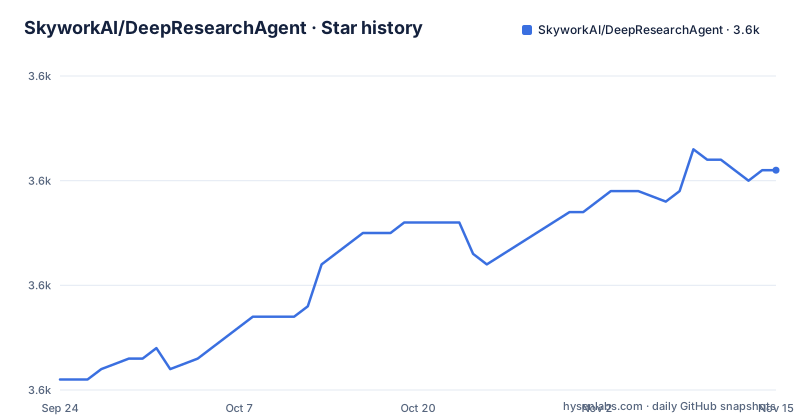
- SkyworkAI/DeepResearchAgent3,571 ★ · +20
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| SkyworkAI/DeepResearchAgent | 3.6k | 3.6k |
20 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One dependency file that also drives Android devices and four exchanges
The core claim of the page is a runtime with protocol layers, and the dependency file is where the project's real centre of gravity shows. The agent plumbing is what you would expect: a language model framework and four of its provider integrations, a graph library, and an engine the config system is modelled on. After that the list changes character. There is a library for talking to Android devices over the platform's debug bridge. There are four exchange clients: two for derivatives futures, one for spot, one a general connector, plus a separate client for a second decentralised exchange. There are two market data providers, one of them Chinese, plus a technical analysis library, a data frame library, a vector index, a web framework, a dashboard framework, a browser automation tool, three separate search engine clients, and a pair of crawling services. None of that is in the feature list. It is all in one file, with no extras groups, so the single example command the page offers runs on top of the lot.
Two packages appear twice under different version floors
Read the dependency file as a file rather than as a list of capabilities and two problems jump out. One package appears in the trading and financial data group and then again further down in a group of its own, carrying the same version floor both times. Another appears in the same group with one floor and then again later with a higher one. Duplicating a dependency is harmless on its own, because an installer intersects the constraints. Duplicating it with two different floors is a small trap: the higher one silently wins, so the lower one tells you nothing about what the author actually tested. Neither duplicate is marked as an error, and the grouping comments around them are not consistent, which suggests the file was assembled over time by appending rather than by maintaining a single list. It is a small thing, and it is the kind of small thing that makes a reader stop trusting the rest of the file.
One dependency is pinned exactly, and it is an old one
Every other entry in the dependency file has a lower bound and no upper bound, which is a defensible choice for a research repository where you want the newest model client. Exactly one entry is pinned to a specific version with no flexibility at all, and it is the machine learning transformers library, pinned far behind the current line while the deep learning framework beside it has a floor that admits modern releases. That combination is the interesting part: an old transformers pin next to a torch floor that wants a recent one. Pinning is sometimes necessary when an API changed, so this may well be deliberate, but nothing on the page says so. It also means the file cannot be resolved by simply taking the newest of everything, and a reader who upgrades that one dependency to see what breaks is doing the author's work for them with no changelog to consult.
The layout block and the building blocks section disagree about two directories
The page has two inventories of the source tree and they do not line up. The repository layout block lists nine directories under the source root, including one for model management and provider backends and one for prompt templates and a prompt manager. The core building blocks section describes seven areas, and it covers none of those two; instead it introduces a configuration directory under the source root that the layout block does not list. So a reader planning an extension has two directories with no description and one directory described but not shown. Neither omission is fatal, since both are named in the other list, but it means the page's own diagram is not the authority on where things live. That matters more than usual here, because the project's stated design goal is composability, and composability means people are expected to go and add their own agent, tool, environment or memory implementation.
The repository description and the page describe two different projects
The repository's own description field says the system is a hierarchical multi-agent system for deep research and general task solving, with a top-level planning agent coordinating specialised lower-level agents to decompose and execute tasks. The page says something different: it is a self-evolution protocol and runtime, built from a resource protocol layer that treats prompts, agents, tools, environments and memory as registered resources with state and versions, and an evolution protocol layer that adds a closed loop to propose, assess and commit improvements with lineage and rollback. Both are defensible descriptions of the same codebase, since a hierarchical agent system is how the loops drive the work. But they imply different extension points. The first invites you to add a specialised sub-agent. The second invites you to add a versioned resource and an operator. Neither page reconciles the two, and the loop the page describes is the more specific of the pair.
Two releases on one day, half an hour apart, titled as notes to self
The release list has two entries and they were published on the same date about thirty five minutes apart. Their titles are not version summaries. One reads as a note that this is the evolving version and the other as a note that this is the pre-release version. That is the entire history of this project's tagged releases: a pre-release marker and a later marker, minutes apart, both labelled in the author's own shorthand rather than with a description of what changed. The repository was pushed on 4 May 2026, which is a couple of months after both tags, so there are untagged changes as well. There is no change log on the page and no migration note between the two, which means adopting this means reading the source rather than reading release notes.
The web access layer is three search engines and two crawlers
The dependency file's search and scraping section is the part of this project most likely to surprise you, because a research agent needs a web and it needs several. There are three distinct search engine clients: one for a Chinese engine, one for a global engine and a Python package wrapping Google's. There are also two crawling services, one of them a commercial API with its own client and the other a general purpose crawler framework. Then there is a document conversion library with every extra enabled, a scraping framework, an HTML parser and an HTML to text converter. Nothing on the page explains why three search engines are needed rather than one, or whether they are alternatives a configuration selects between. That matters for anyone running this as a service, because a research agent behind six web access paths behaves differently in terms of rate limits, terms of service and failure modes depending on which path it picks.
The one-command example still needs the whole stack
The page offers an optional quick path and it is worth reading exactly. You install the dependencies in your environment, copy a template environment file to the real one, set a model API key, and run one script with a config file:
python examples/run_tool_calling_agent.py --config configs/tool_calling_agent.pyYou can then override the model and the work directory on the command line with dotted keys, where the model is given as a provider-prefixed identifier and the work directory and a tag. The config file itself is a Python file, not a data file, which is what the engine-style configuration system the page describes implies. The catch is step one. Installing the dependencies means installing the full file, so a reader who only wants to run a tool-calling agent with one model provider also installs Android device tooling, four exchange clients, two market data feeds, a vector index, a dashboard framework and a pair of crawlers. The examples directory shows what the rest of the stack is for: trading runs, a mobile agent run, benchmark runs, debate harnesses, and a set of experiment scripts for two reasoning benchmarks against three different optimizers.
Editorial conclusion
DeepResearchAgent suits a research team that wants an agent runtime where prompts, tools, environments and memory are versioned resources and where improvement runs go through an auditable propose, assess, commit loop. Four things to check before you install it. The dependency file is not scoped to the core: it includes Android device tooling, four exchange clients, two market data providers, a vector index, three search engines and two crawlers, so a core user installs all of it. The version discipline is uneven, with two packages listed twice under different floors and one dependency pinned exactly at an old version. The layout block in the page and the building blocks section disagree about two directories. And the repository's own description frames the project as a hierarchical multi-agent system while the page frames it as a protocol and runtime.
Frequently asked questions
What are Deep Research agents?
The repository describes its own version of the idea rather than the term. Its framing is a hierarchical multi-agent system with a top-level planning agent coordinating specialised lower-level agents for task decomposition, and its page adds an iterative loop of acting, observing, optimizing and remembering. What it adds on top is the idea that prompts, agents, tools, environments and memory should be versioned resources, and that improvements should go through a propose, assess and commit loop with lineage and rollback.
How do I build a Deep Research agent?
With this repository, the short version is: install the dependencies, copy the environment template, set a model API key, and run the tool-calling example script against a config file, overriding the model and work directory with dotted keys. The dependency file is not scoped, so installing it brings in device tooling, exchange clients, market data providers and crawlers as well as the agent framework. Adopting only part of the stack means pruning the dependency file yourself.
Can I use DeepSearch for free?
The repository is published under the MIT licence and the page asks for a model API key before its example will run, so the framework itself carries no cost and the model provider is the thing that costs money. It also lists a hosted option in the context of the model identifier, which is a router rather than a model vendor. Nothing on the page describes pricing for either.
Which AI agent is best for Deep Research?
The repository does not compare agents and does not recommend one. What it does provide is a separation of concerns: a layer that registers prompts, agents, tools, environments and memory as resources with explicit state and versions, and a layer that adds operators to propose, assess and commit an improvement with an audit trail and a rollback. Whether a given model is best is left to the provider configuration, which the example overrides by name.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/skyworkai-deepresearchagent)Star history chart for your README
[](https://hysenlabs.com/projects/skyworkai-deepresearchagent)Was this useful?