HealthGPT says fourteen days of your health data goes to OpenAI, in the disclaimer
Query your Apple Health data with natural language 💬 🩺
At a glance
- What is it?
- An experimental Stanford iOS app that answers questions about Apple Health data, where the only account of where your data goes is the last sentence of a medical-advice disclaimer, the privacy-preserving execution modes are opt-in, and adding a single health quantity means editing three Swift files, the last of which is a prompt.
- Who is it for?
- HealthGPT is best understood as a Spezi reference application rather than a health product, and read that way it is a good one. The three execution targets are the interesting part: cloud models, an eight-billion-parameter model downloaded to the device during onboarding, and a Docker node somewhere on your local network.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 125 days ago.
- What is it written in?
- Mainly Swift, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
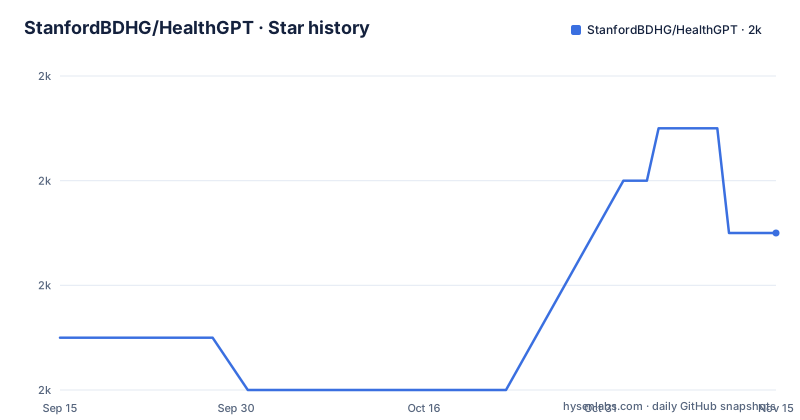
Star history
- StanfordBDHG/HealthGPT1,967 ★ · +2
| Repository | 2026-09-15 | 2026-11-15 |
|---|---|---|
| StanfordBDHG/HealthGPT | 2k | 2k |
2 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The only account of data egress is the last sentence of the disclaimer
The disclaimer runs to five sentences. Four of them are about medicine: the app is for general information, it is not a substitute for professional advice, language models are known to hallucinate, use is at your own risk, and you should consult a qualified provider. All of that is appropriate and unremarkable.
The fifth sentence is the one that matters, and it is where the data-flow disclosure sits:
> Aggregated HealthKit data for the past 14 days will be uploaded to OpenAI.
It appears after the advice about seeing a doctor, and it is followed by a pointer to OpenAI's own privacy policy for more information. So the most consequential fact about the application is disclosed in a legal section rather than in the setup instructions, in a feature list that separately advertises privacy-preserving local execution, or anywhere a user would look while deciding whether to install it.
Two details of the disclosure are precise and worth reading twice. The window is fourteen days, so the upload is a rolling slice of recent history rather than everything, and the data is described as aggregated rather than raw, though the word aggregated is doing unspecified work: no definition is given for what aggregation means here.
Nothing is wrong with using a hosted model. What is easy to miss is the default. The application ships configured for GPT-3.5 and GPT-4 through a module whose whole purpose is calling a remote API, so an install and a first question send fourteen days of health history to a third party unless you change that configuration. The two modes that avoid it are described further down as options.
For anyone evaluating this, the disclosure is the fact to act on. Read it, then decide which of the three execution targets in the next section you actually want.
Three execution targets, and two of them keep the data on your hardware
The application can put the model in three places, and they differ in more than latency.
The first is the cloud, through a module that issues queries to GPT-3.5 and GPT-4. This is the configured default and the one with the fourteen-day upload. It needs an API key and a network connection, and it is the only one of the three that needs neither a large download nor a spare machine.
The second runs on the device, through a local module using Llama 3 8B. The feature list is specific that this includes automated download and storage of the model files during onboarding, which means the first launch pulls an eight-billion-parameter model onto the phone before anything else works. In exchange, the queries stay local. There is a hardware condition, stated in an important note: this mode requires installation on a physical device, because the local module needs a modern Metal GPU family and simulators do not provide one.
The third puts the model on a machine on your local network. It is described as fog-node execution, where the app discovers a node via mDNS, connects to it, streams responses back and dispatches inference tasks to it. The readme gives the claimed benefits as low latency, strong performance and improved privacy, on the grounds that the model runs on your own hardware inside your own network. A minimal Docker-based node for Linux or macOS is documented separately, so this mode ships a server component alongside the iOS app.
So the privacy story in the feature list is accurate, and it applies to two of the three paths. The framing that makes it easy to miss is that local execution is presented as an option you add, while the upload is what happens if you do not.
The simulator can do neither real data nor local inference
Two separate notes, and they matter because the setup instructions otherwise read as though the simulator is a full substitute for a device.
The first note is about the simulator's Health data. Apple's Health app in a simulator has no history in it, so the results all read zero. The fix is not a setting: you have to add data to the Health app by hand. So simulator work means manually populating the database before the application can be exercised at all, which is fine for a screenshot and tedious for anything else.
The second note removes the second option entirely. Local execution needs a physical device, because the local module requires a modern Metal GPU family that simulators do not provide. Combined with the first note, the simulator supports exactly one thing: seeing the chat interface and the settings against data you typed in yourself.
The setup instructions themselves are short and assume a Mac. Building and running requires Xcode 16.2 or newer. You clone the repository, open the project file in Xcode, wait for dependencies to install and indexing to finish, then run on a device or in the simulator. There is no package manager command, no simulator bootstrap script and no configuration step, which is what you would expect from an application distributed as an Xcode project rather than as a Swift package, even though its dependencies are Swift packages.
There is also a route that avoids building at all. A note points at a TestFlight link, so the application can be installed on a device without Xcode. That is the fastest way to see what it does, and it comes with the same privacy question attached to whatever the released configuration happens to use.
Adding one health quantity means editing three Swift files, and the third is a prompt
The extension story is where the architecture shows itself, because the data model, the query layer and the prompt are three separate concerns and all three have to be touched by hand.
The documented procedure for adding a HealthKit quantity or category is three steps, each naming a specific file. First, update the configuration for the health integration in the application delegate, with a link to the module's own documentation. Second, edit the data fetcher to write the query appropriate to the new data type. Third, update the prompt generator so the newly acquired data is passed through to the API.
That third step is the one worth pausing on. It is not a registry entry or a metadata addition. Adding a data type means editing the text that instructs the model. So the surface you extend to read a new quantity is, in the end, the prompt, and any change to what the model is told has to be reviewed as a prompt change rather than as a schema change.
Two smaller details in the same list. The file paths are given inconsistently: the first step points one directory deep and the next two point two directories deep, which is a small sign that these instructions were written at different times against a moving tree. And the documentation link for the health module is pinned to a specific earlier version of that module rather than its current documentation, so the configuration instructions you are sent to may not match the code you have.
None of this is unusual for a prototype. It is, however, the real shape of the framework: the claim that the architecture is easy to extend is true in the sense that nothing is closed, and the cost is that extension happens in Swift source across three files.
Six quantities work without code, and they are named
The out-of-the-box data coverage is a short explicit list: sleep, step count, active energy, exercise minutes, heart rate and body mass.
Six. That is the difference between an application that can be used and an application that has to be extended, and it is worth stating plainly because the framing elsewhere is about querying your health data in natural language, which suggests broader coverage than a six-item list delivers.
None of the six is unusual or difficult to add; the three-file procedure above is the whole cost. But the list also sets the shape of what the model can be asked. Aggregations across a single quantity over the fourteen-day window are straightforward. Anything spanning two quantities, or requiring a metric the framework does not already compute, is outside what ships.
The interface around the data is a chat module rather than a custom view, and it brings speech-to-text recognition and text-to-speech synthesis described as accessibility capabilities, plus the ability to export a conversation. Export matters more than it sounds in a health context, because it is the mechanism by which a user can take a generated answer somewhere else, and the screenshots include an export screen as one of three shown.
The screenshots themselves are all dark variants. Three images are referenced, for the conversation, the settings and the export view, and every one is a dark-mode file. There is no light-mode screenshot on the page, which says nothing about the application and a small amount about what was captured.
The fog node is found by broadcast and nothing describes how it is authenticated
The local-network mode is the most novel piece of the system and the least documented, and the gap is worth naming rather than glossing.
What is described: the application discovers a fog node via mDNS, connects to it, streams model responses back, and dispatches inference tasks to it. The node is a container, with minimal Docker-based instructions for Linux or macOS in a separate document. The claimed benefits are latency, performance and privacy, with the privacy claim resting entirely on the model running on your own hardware inside your own network.
What is not described anywhere in the visible text: how the application decides a discovered node is trustworthy, whether the connection is encrypted, whether the node authenticates the phone or the phone authenticates the node, and what an attacker on the same wireless network would have to do to become the node that receives a user's health queries.
That is a real question rather than a rhetorical one, because mDNS discovery is a broadcast. Any host that advertises the right service name on the same network is discoverable as a fog node by every client on that network, which is the convenience that makes zero-configuration local discovery attractive and also the reason the trust question has to be answered somewhere. A developer extending this for real use will have to answer it themselves, and the readme does not tell them whether anyone has.
The privacy framing elsewhere in the document is careful, including an explicit acknowledgement that language models hallucinate and can return false information. It is a shame the same care is not applied to the network path, where the risk is concrete rather than statistical.
Dead-code detection and licence metadata on a demo app
The repository tooling is more disciplined than the application, which is worth noticing because it tells you how the project is maintained rather than what it does.
There is a Swift lint configuration and a configuration for an unused-code detector, which is the tool that finds declarations nothing references. There is a test plan file at the root, with its own licence sidecar file, alongside separate unit test and user interface test directories. There is a directory for release automation. There is a contributors file, a code of conduct link, and a Zenodo DOI badge for citing the project.
The licence handling is the most thorough part. There is a licence file, a directory of licences, a metadata file for source reuse compliance, and the readme itself opens with an SPDX copyright block naming Stanford University and the contributors with an MIT identifier. Sidecar licence files on non-text assets are how that standard is satisfied, and one is present on the test plan.
The release history shows a project moving in fits. Version 0.4.1 was published in May 2025, 0.5.0 in September 2025, and 0.5.1 in July 2026, with the last commit to the branch dated the same day as that final release, one second apart. So the project is pre-1.0, its releases are irregular, and the newest tag was cut from the tip of the branch rather than lagging behind it.
Provenance is documented better than most. The project belongs to a named Stanford digital health team, the initial prototype was built on the framework's template application by a named person, and the framework itself is a separate open-source project rather than something vendored into this repository.
Editorial conclusion
HealthGPT is best understood as a Spezi reference application rather than a health product, and read that way it is a good one. The three execution targets are the interesting part: cloud models, an eight-billion-parameter model downloaded to the device during onboarding, and a Docker node somewhere on your local network. Two of the three never send your data to anyone, and the feature list advertises the privacy-preserving mode while the account of what the default mode uploads is the final sentence of a legal disclaimer. That placement is the thing to fix before trying the app, and it is worth deciding deliberately which of the three you want rather than accepting the first one. Two practical constraints to plan around. The simulator is close to useless for real work, since there is no Health data in it and you have to enter data by hand, and on-device inference needs physical hardware because simulators do not provide the required graphics family. And the six quantities that work without code are a short list, so any real question about your health beyond sleep, steps, active energy, exercise minutes, heart rate and body mass is a software task involving a data query and a prompt edit. Treat the output as a query interface over a database you already have, not as anything clinical.
Frequently asked questions
What is HealthGPT and what can it query?
It is an experimental iOS app built on the Stanford Spezi framework that lets you ask questions about your Apple Health data in natural language. Out of the box it supports sleep, step count, active energy, exercise minutes, heart rate and body mass.
Does healthgpt send my health data to OpenAI?
In its default cloud configuration, yes. The disclaimer states that aggregated HealthKit data for the past 14 days will be uploaded to OpenAI, and points to OpenAI's privacy policy for more information. The app is configured for GPT-3.5 and GPT-4 out of the box.
Can healthgpt run a model locally instead?
Yes, in two ways. A local module can run Llama 3 8B on the device, downloading and storing the model files during onboarding, which requires a physical device because simulators do not provide the required Metal GPU family. There is also a fog-node mode that runs the model on a machine on your local network, discovered automatically.
Do I need an Apple device to build healthgpt?
You need a Mac with Xcode 16.2 or newer. You can then run on an iOS device or in the simulator, but the simulator has no Health data in it, so you must add data by hand or all results read zero, and the local LLM mode does not work there at all.
How do I add a new health data type to healthgpt?
By editing source in three files. You update the health integration configuration in the application delegate, add the query in the data fetcher, and update the prompt generator so the new data is passed to the API. There is no registry or configuration file for adding a quantity.
Is there a fog node for healthgpt?
Yes. The app discovers a fog node on the local network via mDNS, connects to it and dispatches inference tasks to it, and a minimal Docker-based node for Linux or macOS is documented in a separate file. The readme does not describe how the app verifies a discovered node or whether the connection is authenticated.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/stanfordbdhg-healthgpt)Star history chart for your README
[](https://hysenlabs.com/projects/stanfordbdhg-healthgpt)Was this useful?