VectorHub was a learning hub, and its licence blocks commercial reuse
Deprecated historical repo. Superlinked now develops SIE, a self-hosted inference engine for embeddings, reranking, OCR, extraction, and document processing.
At a glance
- What is it?
- A content repository rather than a library: blog posts, documentation and research notebooks about adding vector retrieval to a machine learning stack, plus one comparison tool for vector databases. The README states the work is licensed under a non-commercial share-alike licence, and the repository description marks it deprecated in favour of a self-hosted inference engine the same company now develops.
- Who is it for?
- Read VectorHub if you are still choosing a vector database and want a structured comparison rather than a vendor list, and treat everything else in it as dated reading rather than reference. The four learner outcomes are a reasonable curriculum for someone new to retrieval, and the comparison tool is still the most concrete artifact here.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
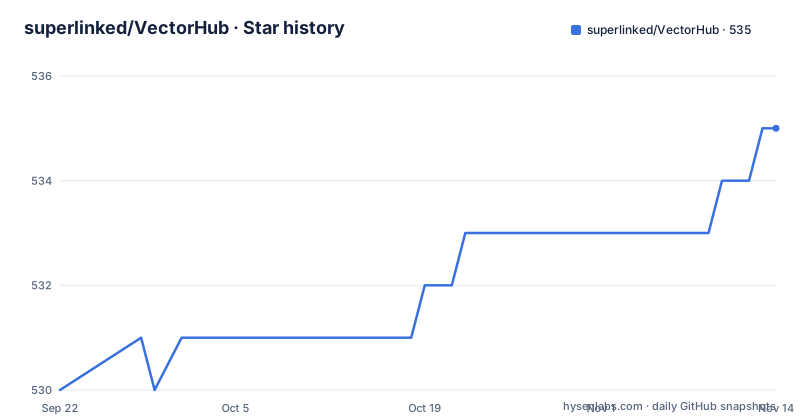
- superlinked/VectorHub535 ★ · +5
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| superlinked/VectorHub | 530 | 535 |
5 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
This is a content repository, and GitHub agrees
The first thing to establish is what kind of artifact this is, because the name suggests a package and it is not one. The README describes VectorHub as a free and open-sourced learning hub for people interested in adding vector retrieval to their machine learning stack, and the useful resources it offers are practical ones rather than code you install. The top level of the repository confirms the shape: a blog directory, a docs directory and a research directory, alongside editor and repository configuration files, a licence file and the README. Three content types in three directories is a publication, not a library. The strongest signal is the language GitHub reports, which is Jupyter Notebook, and that only makes sense if the research material is notebooks you read and run. There is no build script, no package manifest and no entry point in the tree. So if you arrived looking for a retrieval library to add to a dependency list, this is the wrong repository, and the description at the top is the fastest way to find that out before you clone anything.
The licence is non-commercial and share-alike, not a software licence
The licence is the most consequential fact on this page and it is stated plainly in the license section. The work is licensed under a Creative Commons Attribution, NonCommercial, ShareAlike 4.0 International licence, and the README carries a badge for it. Two words in that title do most of the work. NonCommercial means you may not use the material, adapted or unadapted, in anything whose purpose is commercial, which rules out the obvious move of lifting a comparison table or a set of learning materials into internal documentation for a product you sell. ShareAlike means that if you do adapt and redistribute under the same non-commercial terms, your adaptation inherits those terms. A Creative Commons licence is also the wrong instrument for software: it grants permissions over content rather than granting the right to link against an API, so there is no dependency question here at all. Note also that the repository metadata does not report a recognised licence, so a tool that reads licences from metadata rather than from the file will tell you nothing. If you need commercial rights, the licence has to be read directly, and it says no.
The comparison tool admits its own features are verified unevenly
There is exactly one tool here, and it is a comparison rather than a program. The Vector DB Comparison is described as a free and open source tool from VectorHub for comparing vector databases, created to outline the feature sets of different solutions, and it lives on the company website rather than in this repository. The caveat attached to it is the sentence worth quoting in full: each of the features outlined has been verified to varying degrees. That is an unusually candid admission, and it changes how the tool should be read. A comparison table is only as good as its weakest cell, and a table whose author says the cells were checked to different standards is a starting point for your own evaluation rather than a decision. The value it still has is structural. Laying the feature sets of several vector databases side by side forces you to name the dimensions you actually care about, which is a useful exercise even when you fill in the answers yourself. The failure mode to avoid is treating a checked box in a third-party table as a verified claim about a product you have not run.
The curriculum is four learner outcomes, not a feature list
The README states what the hub is for as four concrete things a reader will be able to do, and the framing is worth keeping because it describes a learning path rather than a product. The first is creating minimum viable products with easy-to-follow learning materials. The second is solving use-case-specific problems in vector retrieval, which is the one that acknowledges retrieval is not solved by a library. The third is getting confident enough to take those prototypes to production and make them actually useful, with the word actually doing the work in that sentence. The fourth is learning about the vendors in the space and selecting the ones that fit a particular use case. Read in order, that is a curriculum: prototype, debug, harden, choose. The page also points to a manifesto file in the repository for the reasoning behind the approach, which is the sort of document that is either absent or everything when a project has one. What none of the four outcomes promises is an implementation you can adopt, which returns the question to the top of this page.
The successor is an inference engine, and it is a different product
The repository description is two sentences and the first one changes the reading of everything else. VectorHub is marked as a deprecated historical repository, and the same description says the company now develops something called SIE, described as a self-hosted inference engine covering embeddings, reranking, OCR, extraction and document processing. Those are five capabilities rather than a curriculum, and self-hosted is the opposite of a hosted service, so the company has moved from teaching people to evaluate a category to shipping a component in it. That is a normal arc for a company that starts by educating a market and then builds in it, and it means what is published here has value mainly as a record of how the category was framed at a particular moment. It also means anything you were planning to get from this hub in the future, such as updated comparisons or new learning material, is not coming from here. The homepage the README points at has also moved on, pointing at an examples gallery rather than the hub itself.
Three content directories and no release history
There is very little in the tree to describe, and that is itself informative. Alongside the three content directories and the configuration files there is a repository for continuous integration, an editor directory, and a file whose name begins with a dot and ends in a JSON extension, which is the kind of configuration a static site generator for a blog expects. The absence of any release tag or published version is the point to note for anyone pinning. The repository has no GitHub releases, so there is nothing to depend on and nothing to compare against, and the version of any material here is the commit you read. It is not archived, and the default branch was last pushed on 28 September 2026, so commits still arrive even though the project is described as historical. That combination is normal for a company keeping a public archive current, and it means the safest way to treat this repository is as a fixed snapshot: read it, take what is useful, and check the date on any notebook before you believe a vendor list or a feature matrix in it.
Editorial conclusion
Read VectorHub if you are still choosing a vector database and want a structured comparison rather than a vendor list, and treat everything else in it as dated reading rather than reference. The four learner outcomes are a reasonable curriculum for someone new to retrieval, and the comparison tool is still the most concrete artifact here. Do not reuse the content in a product, because the licence is non-commercial and share-alike, and that clause is the first thing a legal review will find. Four things to check before you rely on anything here. The licence, which is not a software licence and does not grant rights you would expect from a permissive one. How old a given notebook is, since the content predates the company's current direction. Whether the comparison tool has been maintained, because a comparison is only useful while the compared products exist. And whether the successor project covers what you need, since the company has moved to a different product entirely.
Frequently asked questions
What is VectorHub?
A free and open-sourced learning hub from Superlinked for people adding vector retrieval to a machine learning stack. It publishes learning materials, documentation and research notebooks rather than an installable library, and the repository is marked as a deprecated historical repository.
Can I use VectorHub content in a commercial product?
Not under the licence it carries. The work is licensed under Creative Commons Attribution, NonCommercial, ShareAlike 4.0 International, so commercial use is excluded and adaptations must be redistributed under the same terms. The repository metadata does not report a recognised licence, so the licence file has to be read directly.
What is the Vector DB Comparison tool?
A free and open source tool from VectorHub for comparing vector databases, outlining the feature sets of different solutions. The README notes that each feature outlined has been verified to varying degrees, so it is best treated as a starting point for your own evaluation rather than a decision.
What did Superlinked replace VectorHub with?
The repository description says Superlinked now develops SIE, a self-hosted inference engine covering embeddings, reranking, OCR, extraction and document processing. VectorHub itself is marked as a deprecated historical repository, and its default branch was last pushed on 28 September 2026.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/superlinked-vectorhub)Star history chart for your README
[](https://hysenlabs.com/projects/superlinked-vectorhub)Was this useful?