f5-tts benchmarks the same model three and a half times apart
Official code for "F5-TTS: A Fairytaler that Fakes Fluent and Faithful Speech with Flow Matching"
At a glance
- What is it?
- F5-TTS is an MIT licensed text-to-speech system built on flow matching, from the SWivid group, that clones a voice from a short reference recording. It supports NVIDIA, AMD, Intel and Apple hardware and can be installed as a pip package, cloned for training, or run from a container. Its own benchmark table reports the same model at a real-time factor of 0.0394 in one serving mode and 0.1467 in another, and its container image is built by cloning the default branch.
- Who is it for?
- F5-TTS is a credible choice for voice cloning where you need offline or self-hosted synthesis, since it runs without a hosted API and covers four hardware families. Three things to settle first.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
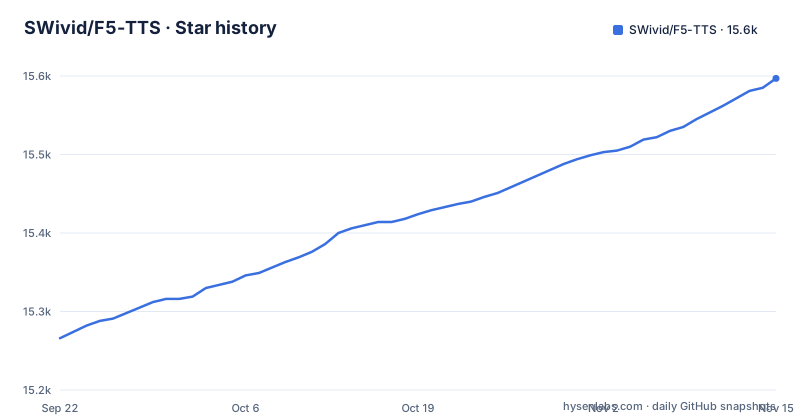
- SWivid/F5-TTS15,597 ★ · +331
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| SWivid/F5-TTS | 15.3k | 15.6k |
331 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One model, one GPU, three different real-time factors
The benchmark table is short and worth reading carefully, because it reports the same model three times.
The setup is decoding on a single L20 GPU, using 26 different prompt audio and target text pairs, at 16 NFE. Under that setup, F5-TTS Base with the Vocos vocoder appears three times.
As a client-server deployment at concurrency 2, average latency 253 ms and RTF 0.0394. As offline TRT-LLM at batch size 1, RTF 0.0402. As offline PyTorch at batch size 1, RTF 0.1467.
So the TensorRT-LLM and client-server paths agree with each other, and the plain PyTorch path is roughly three and a half times slower in real-time terms. Same model, same GPU, same sample set.
That gap is what the table is really telling you, more than any of the individual figures. Real-time factor is the number to quote in a capacity plan, and which one you quote depends entirely on which serving path you deploy. If you plan to run PyTorch directly, the 0.0394 figure is not yours and the 0.1467 figure is. The detailed instructions for the runtime live behind the link at the end of that section.
The container pins an older PyTorch than the install instructions
There are two different PyTorch versions in play, in two different places, and they are not the same.
The installation guidance tells you to match your PyTorch to your device, and the example given for an NVIDIA GPU is a recent release, torch and torchaudio at 2.8.0 with a CUDA 12.8 extra index URL.
The Dockerfile starts from an image pinned several versions back, on PyTorch 2.4.0 with CUDA 12.4 and cuDNN 9.
So a local install following the documentation and a container built from the repository are not running the same PyTorch. The manifest's own floor is only torch at 2.0.0 or later, so nothing forces the newer one.
Whether that matters depends on what you are doing. In plain inference the difference is mostly uninteresting. It becomes interesting if you rely on a behaviour that changed between those releases, or if you benchmark locally and deploy in the container and try to reconcile the numbers.
So decide which environment is the one you are measuring, and measure there. Pinning the container image to match your validated local stack is a small change with a disproportionate effect on the usefulness of your own benchmarks.
The image clones the default branch, so a build is not reproducible
Look at what the container build actually does rather than what it installs.
The Dockerfile clones the repository from GitHub, changes into it, initialises submodules recursively, and installs the package in editable mode with no cache. There is no reference to a tag, a commit or a version anywhere in that sequence.
The editable install matters too. It links the container's Python to a source tree that was cloned at build time, so the container is carrying a working copy rather than an installed snapshot.
The documented way to run the container compounds this, because it pulls the main tag from the container registry rather than a version tag.
So building or pulling the image gets you whatever the default branch held at that moment. Two images built a fortnight apart can differ, and neither records which commit it came from.
For anything reproducible, pin the commit in your own build and record the digest of the image you deploy. For a quick demo this is entirely acceptable, and it is worth knowing which of the two you are doing. The container also exposes port 7860 and declares a volume for the Hugging Face hub cache, which is where model weights land and the main reason to mount one.
ROCm 6.x fails outright on RDNA 3.5 and 4 hardware
The AMD section is the most specific documentation in the README, and it is a hard requirement rather than advice.
For older AMD GPUs, only the RDNA 1, 2 and 3 generations, the example given uses a ROCm 6.2 build of PyTorch.
Then the note. RDNA 3.5 and RDNA 4 GPUs, specifically the Radeon 8050S and 8060S and the RX 9060 and 9070 series, require ROCm 7.x, because those architectures, named as gfx1151 and gfx1201, are not included in ROCm 6.x. Using ROCm 6.x on those cards causes a HIP error reading invalid device function, and the README links an issue where this is tracked.
That is a complete answer for someone with an AMD GPU: which generation you have decides which ROCm major you install, and the failure mode if you get it wrong is a specific error rather than a slow run.
The Intel path has its own prerequisite, since either Intel Deep Learning Essentials or the oneAPI Base Toolkit must be installed first, with an alternative through IPEX that does not require either. The Apple path is simply a stable PyTorch install with no extra index URL, which is the cheapest of the four to set up.
bitsandbytes is excluded on Apple Silicon, which removes the quantisation paths
Look at the dependency list for the one entry with an environment marker that excludes rather than constrains.
The quantisation library bitsandbytes is required above a version floor, but only where the platform machine is not arm64 and the operating system is not Darwin.
Read that as: on Apple Silicon, and on macOS generally, bitsandbytes is not installed at all.
This is the correct thing to do, since that library does not run on that hardware, and a marker is better than an install failure. But the consequence is that any workflow depending on it is unavailable rather than merely slower.
So if your plan involves training or running a model in 4-bit or 8-bit, check that path on Mac hardware before designing around it. The Apple install instructions are the shortest of the four because there is nothing to match, and that simplicity comes with this limitation attached.
The Intel and NVIDIA paths do install it, so a quantised workflow there behaves differently from the same workflow on a Mac for reasons that have nothing to do with your model.
The numpy cap applies only to Python 3.10 and below
One dependency is constrained by both a version ceiling and an interpreter marker, and the marker is the part that matters.
numpy is capped at 1.26.4 or lower, but only when the Python version is 3.10 or below.
The environment the README sets up for you uses Python 3.11, which is created by the conda command in the first installation step. On 3.11 and later the cap does not apply and numpy resolves to whatever the resolver picks.
So the same repository gives you two different numpy behaviours depending on the interpreter you choose, with no warning at install time. The reasoning is almost certainly sound, since numpy 1.x is a constraint on older interpreters that does not hold on newer ones, and imposing it everywhere would be worse.
The practical effect is on reproducibility. A lockfile built on Python 3.10 caps numpy at 1.26.4 and one built on 3.11 does not, so moving an environment between interpreter versions does more than change the interpreter. If you maintain separate environments per Python version, expect the scientific stack underneath them to differ as well.
The evaluation extra goes further and pins one dependency exactly, with faster_whisper fixed at a single version, so evaluation is reproducible to a degree the training stack is not.
The pip package is for inference, and training needs a clone
The installation section offers two routes and labels what each is for.
Start with an environment. The first step creates a conda environment on Python 3.11 and installs ffmpeg:
conda create -n f5-tts python=3.11
conda activate f5-tts

# Install FFmpeg if you haven't yet
conda install ffmpeg
Then match PyTorch to your device, and finally choose a route. As a pip package, if you are only doing inference, it is a single command:
pip install f5-ttsLocal editable, if you also want to do training and finetuning, it is a clone followed by an editable install:
git clone https://github.com/SWivid/F5-TTS.git
cd F5-TTS
# git submodule update --init --recursive  # (optional, if use bigvgan as vocoder)
pip install -e .
The training route has one subtlety in the commented line beneath the clone. Initialising submodules recursively is marked optional, and needed only if you use bigvgan as the vocoder.
So there are two vocoder paths and one of them needs a recursive submodule initialisation that the other does not. Default installs silently skip it, which is correct and means the default path is the Vocos one you see named throughout the documentation.
One more detail about what the pip package gives you. It installs four console entry points, two for inference and two for finetuning, named with an infer and a finetune prefix and split between command line and Gradio variants. So an install intended purely for inference still brings the training entry points with it, and the application code behind them.
If you are packaging this, that is the file list to account for.
Editorial conclusion
F5-TTS is a credible choice for voice cloning where you need offline or self-hosted synthesis, since it runs without a hosted API and covers four hardware families. Three things to settle first. Decide which serving path you will actually use, because the published real-time factor varies by almost four times between them and plain PyTorch is the slowest of the three. Check your GPU against the ROCm compatibility note if you are on AMD, since older ROCm fails outright on newer architectures. And if you need training rather than inference, install from the clone rather than from the pip package.
Frequently asked questions
What is F5-TTS?
F5-TTS is described as a diffusion transformer with ConvNeXt V2 that trains and infers faster, presented alongside E2 TTS, a flat UNet transformer that the project calls a closest reproduction from an earlier paper. A third component, Sway Sampling, is an inference-time flow step sampling strategy that the project says greatly improves performance.
is f5 tts open source
Yes, under the MIT licence, with the licence recorded in the project manifest and a licence file at the root. The base models were published on Hugging Face, Model Scope and Wisemodel in October 2024, with a v1 base model announced in March 2025 that the project says has better training and inference performance.
how to install f5 tts
Create a conda environment with Python 3.11, install ffmpeg, then install PyTorch matched to your device, using a CUDA build for NVIDIA, a ROCm build for AMD on Linux, an XPU index for Intel, or a plain stable install for Apple Silicon. Then either run pip install f5-tts for inference alone, or clone the repository and install it in editable mode if you also want to train.
how to use f5-tts
Launch the Gradio web interface with f5-tts_infer-gradio, optionally with a port, host or a share link, for basic text to speech with chunk inference, multi-style and multi-speaker generation and voice chat. For scripted use, f5-tts_infer-cli takes a model, reference audio, reference text and generation text, or reads a TOML configuration file.
what is e2 f5 tts
The two are separate models in the same project. F5-TTS is the diffusion transformer with ConvNeXt V2. E2 TTS is a flat UNet transformer, described as the closest reproduction from a separate paper, and both are hosted on the same model repositories. The project also offers Sway Sampling as a shared inference-time strategy.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/swivid-f5-tts)Star history chart for your README
[](https://hysenlabs.com/projects/swivid-f5-tts)Was this useful?