MIRA OS has one conversation thread forever and scores its memories in SQL
This is the public release of MIRA OS. Discrete memories decay through momentum loss, tools auto-configure when dropped into tools/ folder, and the system prompt composes from modular trinkets. I would like to think I've made an elegant brain-in-box. You load it and send cURL requests - it talks back, learns, and uses tools. Contributions welcome.
At a glance
- What is it?
- MIRA OS is a self hosted agent stack built around a single restriction: there is no way to start a new chat. Instead of a new window, older turns collapse into first person memories that decay by a formula stored in a SQL file unless they earn their keep, while two small systems bracket every response, one preparing context before the answer and one auditing it after. The runtime underneath is FastAPI on Postgres with pgvector, plus a Redis compatible cache and an in process scheduler.
- Who is it for?
- MIRA OS fits a single user willing to own the whole stack and to keep talking to the same instance for months, because every design choice here assumes continuity rather than sessions: decay is measured in days you actually used it, so a vacation costs nothing and a return conversation is still threaded. It does not fit multi user work, because the entire model of who the user is is a single behavioural profile rewritten in place.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
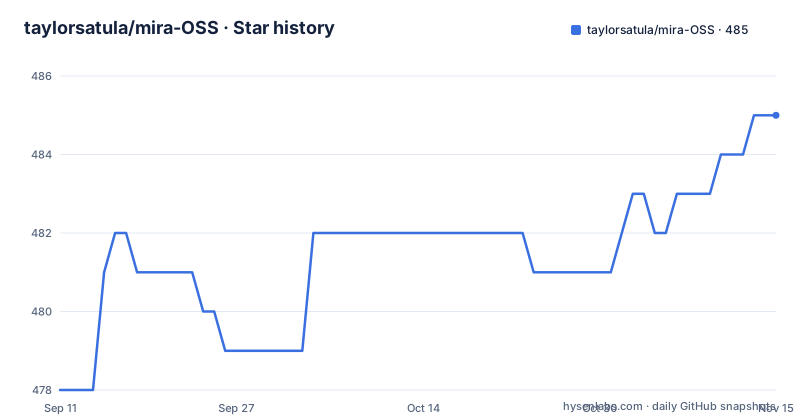
- taylorsatula/mira-OSS485 ★ · +7
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| taylorsatula/mira-OSS | 478 | 485 |
7 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
There is no way to start a new chat
The defining constraint of this system is a missing feature. There is one conversation thread, forever, and no functionality to start a new one.
The stated reason is that this forces the hard question directly: how do you build believable persistence inside a framework built on forward pass transformers, which are inherently ephemeral. Everything else in the design is downstream of refusing to dodge that.
Conversation processing runs two ways at once. There is asynchronous work described as akin to REM sleep, and there is active self directed context window manipulation. The effect is that active history stays live in the window while it is relevant, and older material collapses into memories.
There is a second collapse path for the case where a conversation grows too large before it would collapse naturally. Then the older messages are compressed into one rolling continuation brief while the most recent turns are left untouched. So you get two different compression behaviours: a real collapse into memories when the segment is ready, and a flat summarisation into a brief when the window is under pressure and the segment is not.
That distinction is what stops a memory system from fabricating a past. The brief is continuity for a conversation still in progress; the memories are claims about work that happened. Mixing the two would make the archive a paraphrase of a paraphrase.
Summaries are first person and dated absolutely
When a conversation segment collapses, the summary is written in the first person. The example given is of the form I debugged the IndexError in process_batch.py, and the rejected form is The assistant discussed debugging.
The reason is stated as an observation rather than a style preference. Third person summaries created epistemic distance: the system read them as logs about someone else rather than as memories of work it actually did. The pronoun is doing the work of establishing that the memory belongs to the speaker.
Timestamps are absolute for a similar reason. On Jan 8 replaces yesterday, because relative time becomes a lie the moment the sun sets. Any memory that says yesterday is wrong by tomorrow, and a store that accumulates wrong timestamps cannot be trusted to place events.
Continuity comes from a sliding window of five. When generating a new segment summary, the model sees the previous five summaries as context, which is enough to produce hazy references such as building on Tuesday's API work or continuing the recipe experiments from last week, without carrying the full weight of everything before it. Each summary knows roughly where it came from and nothing more.
The output format is four fields: a three to four sentence memory trace, a two sentence precis, a short display title, and a complexity score. Only the trace is for remembering. The other three exist to keep the conversation manifest useful without pushing the full history back into the context window, which is the trade this design keeps making everywhere.
Memories decay by a formula that lives in a SQL file
The memory system is designed so that it manages itself, and the stated expectation is that you should not have to housekeep old memories, which is described as context rot.
The decay logic is not in Python. It is a formula stored in `lt_memory/scoring_formula.sql`, which is a detail that tells you where the project thinks the interesting part lives: scoring queries the database can run, rather than a scorer that has to be loaded into a process.
A memory survives decay by earning its keep, through any of four routes: access, an explicit reference, a link to another memory or entity, or real temporal relevance. So forgetting is the default and retention is the exception that has to be argued for.
Decay is measured in use-days rather than calendar days, explicitly so that going on vacation does not make the system forget you. That single design decision does more for retention than any of the scoring terms, because it stops absence from being interpreted as disinterest.
Recall is mostly passive. Memories are discrete synthesized pieces of information loaded into the context window by semantic similarity, entity hubs, memory traversal, filtering, and reranking, and most of it happens before a response is generated. That ordering matters: the system does not have to notice that something is missing and then decide to search for it. An explicit path still exists for the cases where a deliberate lookup, a new memory, a link, or exact control over what is recalled is the right move.
Domaindocs are the documents that refuse to decay
Alongside decaying memories there is a second document type that is explicitly exempt, and the exemption is the point.
Domaindocs are stable encrypted documents, reachable through a separate tool, that do not decay. They are what the project reaches for when the content is document shaped and large: big chunks of text where a memory trace would be the wrong abstraction. They carry section level version history, sharing, pinned sections, and nested subsections.
The context window problem for a long document is solved by expanding and collapsing at section granularity. When a section is not in use, the system closes the drawer: the body stops occupying the context window, while the section's title, its summary, and its location in the document tree remain visible. That residue is enough for the system to reexpand it later without the user re describing where it was.
MIRA can expand, collapse, and add subsections to these documents on its own, and you can edit the contents directly through the app or the API. Both kinds of edit are reflected in the next composed context, which is the sentence that keeps the two writers from fighting: there is no merge step because there is only one context assembly.
So the memory system has two tiers with different physics. Memories are short, first person, self scoring, and expected to fade. Domaindocs are long, section addressed, versioned, and permanent.
Subcortical gathers before the answer, Peanut Gallery audits after
Two small systems sit on opposite sides of the main response, and the framing is anatomical.
Subcortical is the reflex. It is an information retrieval pass that runs on every user turn, reading the current message, the recent conversation, and the memories already in context. It resolves pronouns and fragmentary references into concrete search phrases, extracts named entities for graph lookup, decides which old memories are still relevant enough to keep, and classifies the turn as straightforward or as needing heavier reasoning. Its output is never shown to the user and it does not answer the question. It prepares what the primary model gets to think with.
Peanut Gallery is the second set of eyes, and it works afterwards. Every five turns it asynchronously reads the recent conversation alongside a compact ledger of the system's own commitments, tool calls, and tool results. Most of the time it says nothing at all.
When the conversation has measurably gone off the rails, it can put a short lived concern or coaching directive into the context window. It can also nudge the system to take one bounded initiative when an answer was technically correct but made the user carry too much of the conversational work. Standard guidance gets repaired silently. Critical guidance is different: it can authorise breaking the fourth wall, admitting the slip, and correcting itself outright. Every directive expires after two turns or when the segment collapses.
The five turn cadence, the two turn expiry, and the mostly silent default are all doing the same job, which is to bound how much a self correction mechanism can talk.
Text-Based LoRA rewrites the system prompt every seven use-days
The adaptation layer starts from an admission: an LLM's weights cannot be retrained per user, but its prompts can. The name given to that is Text-Based LoRA, and the stated goal is the same one that name suggests, achieved through text manipulation instead of gradient descent.
The loop has three stages. After each conversation segment collapses, an assessment extractor compares the conversation against a behavioural contract and records alignment, misalignment, and contextual passes, each with the specific evidence and the specific prompt section involved. Those signals accumulate in Postgres.
Every seven use-days, a pattern synthesizer folds the accumulated signals into a descriptive user model covering what works, what fails, where friction appears, and what needs a check in. A separate critic examines the synthesis before it is allowed anywhere near the system prompt.
The last property is the one that makes it safe to run unsupervised. The synthesis is evolutionary rather than a replacement: each run builds on the previous one, and an individual pattern can be reinforced, refined, revised, settled, or allowed to go dormant. Nothing is deleted outright, and a bad week is data rather than a reset.
The tradeoff is worth stating plainly. Nothing here modifies the model, so every effect is a change to the text the model reads, which means the adaptation is inspectable, reversible, and limited to whatever the base model can already do.
Three stateful services, and a requirements file that cites its own files
The runtime is FastAPI on an ASGI server, with hypercorn marked as required for all environments, Starlette for middleware, and httpx with HTTP/2 for outbound calls. State lives in three places: Postgres through psycopg v3 with a connection pool and the pgvector extension for embeddings, a Valkey cache described as Redis compatible, and APScheduler driving three named services.
The requirements file is organised by job rather than alphabetically, and every entry carries a comment naming the module that uses it. That discipline is stated at the top of the file: it was generated by analysing actual usage, and each package was verified to be used in files that are not deprecated.
Two of those comments are more than bookkeeping. The torch entry says the CPU wheel is managed explicitly for sentence transformers, and the file opens with a PyTorch CPU-only extra index URL, which fixes the install to the CPU build rather than letting a CUDA wheel be pulled in by a transitive dependency. The spacy entry needs a second step that pip cannot express, because the named entity model is a separate download:
python -m spacy download en_core_web_lgThe model stack also explains the memory design. Sentence embeddings power one retrieval path, while scikit-learn supplies TF-IDF candidate discovery for the memory linking pipeline and spaCy supplies entity extraction for the same pipeline, so the entity hubs that memories attach to are built by a dedicated lexical and NER pass rather than by the embedding model alone.
The repository root shows the same habit applied to layout: `main.py` sits at the top level, memories live in two separate directories, and a design brief for the next memory curation version is committed alongside the code.
Two required keys decide whether you get a wizard
Configuration is one example file, and it branches the boot path rather than just supplying values.
Two keys are required. `MIRA_ANTHROPIC_KEY` is the primary language model provider credential, and `MIRA_PROVIDER_KEY` is a generic fast inference key with Groq and OpenRouter named as examples. When both are present, first boot runs non interactively. When they are absent, you instead run `docker compose run -it mira` to get an interactive setup wizard. That is a friendly default rather than a hard failure, and it does mean the very first run differs depending on what is already in your environment.
Four more variables are optional and all of them have defaults worth knowing. Provider name, endpoint, and model are optional, with Groq as the default provider and an endpoint pointing at its OpenAI compatible chat completions route. A separate Anthropic key for batch operations is optional and defaults to the main key, which is a clean way to spend a different budget on the background work without forking the config. A Kagi search key is optional. A database password is optional and defaults to an internal default, which is worth checking before you expose the deployment.
The release history uses calendar versioning: v2026.06.25, v2026.05.29, and v2026.05.21, the last of which is titled as a security hardening and reliability sync. The last push to main is dated 2026-09-01, so the branch is ahead of the newest tag. The project has 479 stars, 44 forks, 3 open issues, and an AGPL-3.0 licence.
Editorial conclusion
MIRA OS fits a single user willing to own the whole stack and to keep talking to the same instance for months, because every design choice here assumes continuity rather than sessions: decay is measured in days you actually used it, so a vacation costs nothing and a return conversation is still threaded. It does not fit multi user work, because the entire model of who the user is is a single behavioural profile rewritten in place. Three things to check before you run it. Set both required keys, MIRA_ANTHROPIC_KEY and MIRA_PROVIDER_KEY, because that is what makes first boot non interactive, and expect an interactive setup wizard instead if you do not. Read the behaviour contract, since a critic inspects every synthesis before it reaches the system prompt and that contract is what it is checking against. And note that the adaptive layer is text only: it rewrites prompts, never weights, so it is reversible by deleting what it wrote and it inherits whatever the base model already believes.
Frequently asked questions
Does MIRA OS let you start a new conversation?
No, and that is the core design constraint. There is one conversation thread forever, with no functionality to start a new chat, because the stated goal is believable persistence inside a transformer framework that is inherently ephemeral.
How do MIRA OS memories avoid decaying away?
Decay runs on use-days rather than calendar days, so absence does not count against a memory, and a memory survives by earning its keep through access, an explicit reference, a link to another memory or entity, or real temporal relevance. The scoring formula lives in lt_memory/scoring_formula.sql rather than in Python.
What are Subcortical and Peanut Gallery in MIRA OS?
Subcortical is a retrieval pass that runs on every user turn, resolving references, extracting entities, and pruning memories before the answer is generated, without ever answering the question itself. Peanut Gallery is a metacognitive observer that reads the conversation every five turns and can inject a short lived coaching directive, which expires after two turns.
What does Text-Based LoRA actually change in MIRA OS?
Only prompts, never model weights. After each segment collapse an assessment extractor records alignment and misalignment signals, and every seven use-days a synthesizer folds them into a user model that a separate critic reviews before it is loaded into the system prompt. Each synthesis builds on the last rather than replacing it.
What does MIRA OS need before it will start?
Two required keys, MIRA_ANTHROPIC_KEY and MIRA_PROVIDER_KEY, and with both set first boot runs non interactively. Without them you run docker compose run -it mira to get the interactive setup wizard. Provider name, endpoint, and model are optional and default to Groq.
How does MIRA OS store and search its memory?
Postgres with the pgvector extension, a psycopg v3 driver with connection pooling, and a Redis compatible Valkey cache, with APScheduler running the background jobs. Recall is mostly passive, loading memories through semantic similarity, entity hubs, traversal, filtering, and reranking before a response is generated.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/taylorsatula-mira-oss)Star history chart for your README
[](https://hysenlabs.com/projects/taylorsatula-mira-oss)Was this useful?