TensorBoard shows nothing until your code writes tfevents files
TensorFlow's Visualization Toolkit
At a glance
- What is it?
- TensorBoard is a suite of web applications that read event files your training run writes to disk. Understanding its directory driven run model, tag hierarchy, and legacy logdir_spec flag explains most of its surprising behavior.
- Who is it for?
- TensorBoard suits teams already writing summary ops and willing to keep their log directory organized, since runs, folders, and history are all inferred from files on disk. It is a poor fit if you need remote access to shared experiments without extra infrastructure, or if you are starting from a framework with no summary writer yet.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 9 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
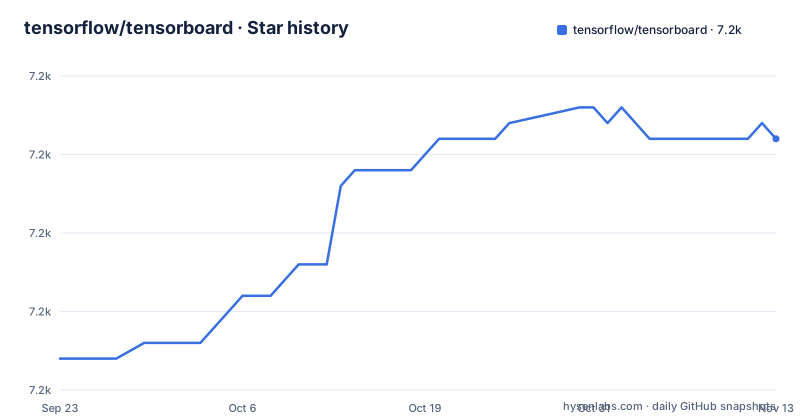
Star history
- tensorflow/tensorboard7,241 ★ · +14
| Repository | 2026-09-23 | 2026-11-13 |
|---|---|---|
| tensorflow/tensorboard | 7.2k | 7.2k |
14 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
TensorBoard refuses to start without a logdir
The most common first run failure is not a bug, it is ordering. Point TensorBoard at a log directory to inspect summary data. For example, TensorFlow 2 can write a scalar with a summary writer:
import tensorflow as tf

writer = tf.summary.create_file_writer("logs/example")
with writer.as_default():
    tf.summary.scalar("loss", 0.345, step=1)
writer.flush()
The writer records the scalar in an event file under the chosen directory. TensorFlow 1 graph-mode code can instead use `tf.compat.v1.summary.FileWriter`; it is not compatible with eager execution. Graph visualization requires separately recorded graph information.
Once event files exist, a pip installed package is started with:
tensorboard --logdir path/to/logsIt prints that TensorBoard has started, and you connect to http://localhost:6006. For anything beyond the basics, `tensorboard --help` is where configuration questions go.
Summary writing in TensorFlow 2 and TensorFlow 1
In TensorFlow 2, summary functions such as `tf.summary.scalar` write to the current default summary writer. Use a writer context and provide a step for time-series data. Image, audio, text and histogram summaries are also available.
In TensorFlow 1 graph-mode code, summary operations can produce serialized summaries that are evaluated in a session and passed to `tf.compat.v1.summary.FileWriter`. This legacy workflow differs from the TensorFlow 2 writer API; choose the example that matches your runtime.
Runs are discovered by walking the directory tree
You do not declare a run with a flag. When TensorBoard is passed a logdir at startup, it recursively walks the directory tree rooted at logdir looking for subdirectories that contain tfevents data. Every time it encounters such a subdirectory, it loads it as a new run, and the frontend organizes the data accordingly.
That is how you compare multiple executions of a model, such as changing hyperparameters to see whether the run converges faster. The convention is one subdirectory per run:
/some/path/mnist_experiments/
/some/path/mnist_experiments/run1/
/some/path/mnist_experiments/run1/events.out.tfevents.1456525581.name
/some/path/mnist_experiments/run1/events.out.tfevents.1456525585.name
/some/path/mnist_experiments/run2/
/some/path/mnist_experiments/run2/events.out.tfevents.1456525385.name
tensorboard --logdir /some/path/mnist_experiments
The cost of this design is that layout is meaning. Naming and directory structure are your only grouping controls.
A crashed run leaves fragments that get stitched together
summary.FileWriters take summary data from TensorFlow and write it to a specified directory, known as the logdir. The data lands in an append only record dump that will have tfevents in the filename.
TensorBoard reads data from a full directory, not from an individual file, and organizes it into the history of a single TensorFlow execution. The reason is recovery. If you were using supervisor.py to run your model and TensorFlow crashed, the supervisor restarts it from a checkpoint. On restart it starts writing to a new events file, and TensorBoard stitches the various event files together to produce a consistent history of what happened.
What you get in the charts is therefore a reconstruction, not a raw stream.
Tags double as folder paths in the dashboard
When you make a summary op you also give it a tag, and the tag is basically a name for the data recorded by that op. It is used to organize the data in the frontend. The scalar and histogram dashboards organize data by tag and group the tags into folders according to a directory like hierarchy.
The practical guidance is to group tags with slashes when you have a lot of them, because a slash becomes a folder boundary in the dashboard. This is a naming decision with a long tail. Renaming a tag does not migrate old data, so a schema change splits one series into two across historical runs, and a series whose tag you changed stops lining up with the runs recorded before the change.
Note also the scope. Tag based organization is stated for the scalar and histogram dashboards.
logdir_spec exists and the project tells you not to use it
You may also pass a comma separated list of log directories, and TensorBoard will watch each directory. Individual directories can be named by putting a colon between the name and the path:
tensorboard --logdir_spec name1:/path/to/logs/1,name2:/path/to/logs/2The project discourages this flag and says it can usually be avoided, because TensorBoard walks log directories recursively anyway. The replacement is a symlink tree for finer grained control.
The failure mode is stated but not bounded: some features may not work when using logdir_spec instead of logdir. The README does not list which features are affected. Treat the flag as legacy, and if a colleague reaches for it to give two directories friendly names, build the symlink tree instead so the dashboards you get match the ones everybody else gets.
Offline by design, Chrome and Firefox by assumption
TensorBoard is designed to run entirely offline, without requiring any access to the Internet. The named situations are your local machine, behind a corporate firewall, or in a datacenter. That constraint shapes deployment: the server reads local files and the browser fetches them, so access control is your network's problem, not the tool's.
Browser support is stated narrowly. TensorBoard can be used in Google Chrome or Firefox. Other browsers might work, but there may be bugs or performance issues. For a dashboard people keep open all day on an engineering team, that is the line to check before standardizing on it, because the failure mode is vague rendering or sluggish interaction rather than a clear error.
One nuance worth naming: a TensorBoard.dev link appears alongside a hosted experiment in the project's own introduction. That hosted service and the local server are different things, and the offline guarantee describes the local server.
Building from source pulls in Bazel, Node, and a nightly TensorFlow
If you installed via pip, one command starts the program. Building from source is a different exercise, and the commands come from the Bazel build system:
bazel build tensorboard:tensorboard
./bazel-bin/tensorboard/tensorboard --logdir path/to/logs

# or even more succinctly
bazel run tensorboard -- --logdir path/to/logs
The container recipe shows what the build actually needs. It starts from ubuntu:latest, installs wget, unzip, python3, pip, python3-dev, a default JDK, nodejs, and npm, then downloads Bazel with a pinned BAZEL_VERSION of 8.7.0 and verifies it against a SHA256 checksum. It installs @bazel/ibazel globally through npm, and it installs TENSORFLOW_VERSION set to tf-nightly alongside the pip package requirements.
Two consequences for readers. The frontend is TypeScript with its own tsconfig.json and yarn.lock, and package.json is marked private with the version 0.0.0-unused, so the package manifest is not something you depend on directly. And pinning a nightly TensorFlow in the image means the build environment tracks a moving target, which is a maintenance cost you accept or avoid by using the released package.
Editorial conclusion
TensorBoard suits teams already writing summary ops and willing to keep their log directory organized, since runs, folders, and history are all inferred from files on disk. It is a poor fit if you need remote access to shared experiments without extra infrastructure, or if you are starting from a framework with no summary writer yet. Before relying on it, check that your environment can install a nightly TensorFlow if you build from source, that you run Chrome or Firefox, and that your log directory layout matches the run hierarchy you intend to present.
Frequently asked questions
What is TensorBoard used for?
It is a suite of web applications for inspecting and understanding your TensorFlow runs and graphs. The Scalar Dashboard visualizes scalar statistics that vary over time, such as the model's loss or learning rate, and data is organized by tag.
How can I access TensorBoard?
Run it with a log directory, tensorboard --logdir path/to/logs, and it prints that TensorBoard has started. Then connect to http://localhost:6006, and use tensorboard --help for configuration.
how to use tensorboard
In TensorFlow 2, create a writer with `tf.summary.create_file_writer`, enter its `as_default()` context and write summaries such as `tf.summary.scalar` with a step. Start `tensorboard --logdir path/to/logs`, then open http://localhost:6006. The older `tf.compat.v1.summary.FileWriter` is intended for TensorFlow 1 graph-mode code.
how to install tensorboard
A precompiled package installed via pip is started with tensorboard --logdir path/to/logs. From source, the project builds it with bazel build tensorboard:tensorboard or runs it with bazel run tensorboard -- --logdir path/to/logs.
how to use tensorboard in colab
The project's introduction points to the TensorBoard getting started tutorial, where documentation on working with images, graphs, hyper parameters, and more is linked, along with tutorial walk throughs in Colab.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tensorflow-tensorboard)Star history chart for your README
[](https://hysenlabs.com/projects/tensorflow-tensorboard)Was this useful?