GeoPulse turns your GPS history into a timeline you own
A self-hosted, privacy-first location timeline platform: an open-source alternative to Google Timeline with automatic trip detection, Immich integration, and rich analytics.
At a glance
- What is it?
- A self-hosted location timeline that reads OwnTracks, Overland, Dawarich and friends, classifies stays and trips, and enriches them with Immich photos, Memos notes and weather. The documentation is unusually careful about cookie domains; the deployment surface is unusually wide, with six compose files and a Makefile whose default target publishes a chart.
- Who is it for?
- GeoPulse fits anyone who has years of location data trapped in a consumer timeline and wants it queryable, exportable and attached to their own photos, since the import paths and the integrations are the actual product. Three things to check before you expose it.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
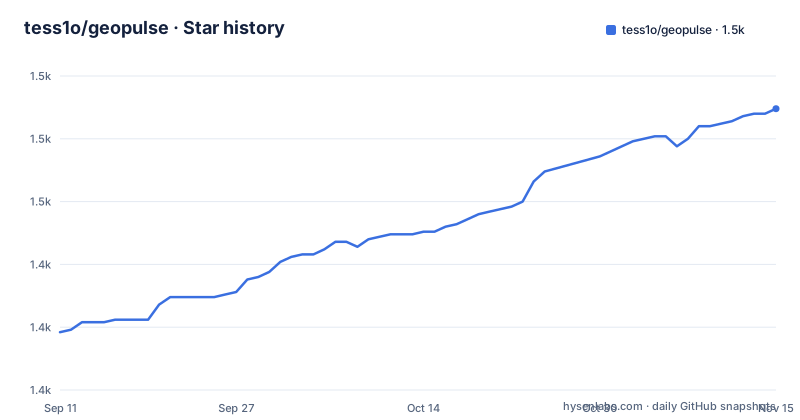
Star history
- tess1o/geopulse1,487 ★ · +89
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| tess1o/geopulse | 1.4k | 1.5k |
89 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The first account to register becomes the administrator
GeoPulse is a self-hosted, privacy-first alternative to a consumer location timeline. It reads raw GPS from OwnTracks over HTTP or MQTT, Overland, GPSLogger, Home Assistant, Traccar, Dawarich and Colota, and turns those points into stays, trips and data gaps with configurable detection sensitivity and travel-mode classification. Historical data can be bulk imported from a Google Timeline export, GPX, GeoJSON, OwnTracks exports or CSV, and everything can be exported back out.
The bootstrap sequence is where the deployment documentation becomes security-relevant, and it is short. The Docker path downloads the environment file and the compose file from the repository's main branch and starts the stack:
# Create directory and download config
mkdir geopulse && cd geopulse
curl -L -o .env https://raw.githubusercontent.com/tess1o/GeoPulse/main/.env.example
curl -L -o docker-compose.yml https://raw.githubusercontent.com/tess1o/GeoPulse/main/docker-compose.yml

# Start
docker compose up -d
That fetches configuration from a moving branch, so what you deploy is whatever main declares on the day you run it, and the project's own note tells you to review the environment file's security settings before production. The Helm path is three commands instead:
helm repo add geopulse https://tess1o.github.io/geopulse/charts
helm repo update
helm install my-geopulse geopulse/geopulse
Either way the post-deployment steps are the same: create the first account, which automatically becomes the administrator, or set an explicit administrator email variable; finish setup in the admin panel; and read the initial setup guide.
First-account-wins is a common pattern and a common weakness. On any deployment that is reachable by more than you, whoever registers first owns the instance. That is tolerable on a laptop and unacceptable on a host with a public address, so the first action after installing should be registering your own account before anything else is up, with a reverse proxy and TLS in front of it.
The rest of the access model is more considered. Sharing is per-user with visibility controls for live location and history, guest access is a shareable link with optional password protection and instant revocation, there are built-in invitations, roles and admin audit logs, and OIDC single sign-on sits alongside ordinary username and password login.
The signing key is written world-readable
Key generation is handled automatically by a dedicated service in the compose file, which is a good design decision on its own. The service runs an Alpine image with a once-and-done restart policy, mounts a keys directory, and generates a JWT keypair and a separate AI encryption key if they are absent.
The generation itself is ordinary: an RSA private key and its public counterpart, plus thirty-two random bytes base64-encoded for the encryption key, with OpenSSL installed on the fly if the image does not have it. Running this as a compose service means a fresh install needs no manual key ceremony.
Two details in that script are worth noting. The file mode is set to 644 on all three files, including the RSA private key, and the keys directory is a bind mount from the host. A world-readable mode on a bind-mounted signing key means any local account on that machine can read it.
The regeneration condition is also written with an or rather than an and: the pair is rebuilt if the private key is missing or the public key is missing. If you lose only the public half, the script generates a fresh keypair and overwrites your existing private key, which invalidates every token already issued. Restoring a single file from that directory is not the safe operation it appears to be.
A separate shell script for key generation also exists at the repository root, so there are two mechanisms for the same job, one automatic and one manual.
The version number is grepped out of pom.xml
The build and release machinery is a Makefile, and its first job is to discover the current version. It does that by running a shell pipeline over the Maven descriptor: grep for the first version element in the file, then strip everything around it with a substitution.
That works, and it is the kind of shortcut every Maven project reaches for eventually. The fragility is in the first-match behaviour. Taking the first occurrence of the element in the document means the answer depends on what appears earliest in the file, and in a multi-module or parent-declaring descriptor the earliest version element is not guaranteed to be the project's own. If a parent version is inherited and listed first, every image you build is tagged with the parent's version.
The rest of the Makefile is more disciplined. It derives two image tag suffixes from that version, one for a native build and one for a JVM build, and defines separate image names for the backend and the frontend service. It pins the target platforms to two Linux architectures. It creates or reuses a named buildx builder rather than assuming a default one exists.
There is also a multi-architecture manifest helper. It inspects the already-pushed image manifests, filters for the amd64 and arm64 entries with a JSON processor, forces the arm64 variant to v8, and then merges them into one annotated manifest. The catch is that it depends on a JSON processor being installed on whatever machine runs the release.
The default make target publishes a chart
The first target in the build file is named all, and its prerequisites read like a release checklist: build the backend as a JVM image, build the backend as a native image, build the frontend, generate the OpenAPI output, and publish the Helm chart.
Publishing is the last prerequisite. So running make with no arguments in a fresh clone does not build you a local stack, it builds four images and pushes a chart to a chart repository. There is a separate build-all target that omits the publishing step, which suggests the author knows the difference, but the default landing on the publishing target is the kind of thing that catches someone out.
That matters more than usual here because the project ships several publishing paths. Alongside the chart, there is a release script, a retag script and a version-update script, all at the repository root, and the compose file itself defaults the backend image to a registry path built from the version variable. One of those variables is a registry namespace for a second image host, and the corresponding backend and frontend image variables are declared twice in the file with identical values, which is harmless in a Makefile but is a copy-paste artefact a reviewer would flag.
The native build has its own arm64 target alongside the multi-platform one, so the architecture coverage is assembled by more than one mechanism.
Six compose files live at the repository root
The deployment surface is wide, and the clearest evidence is the root listing. There are six compose files: a default one, a development one, a complete one, an Unraid one, an Unraid complete one, and one specific to Apprise, which is the notification integration rather than the core application.
The complete and Unraid variants imply the default file is the lean one, and looking at it confirms that. The default compose file has a key generation service and a backend service, and the backend service is the one with a hard memory limit of 512 megabytes and a reservation of 128 megabytes, an init process enabled, an environment file, a PostgreSQL connection string assembled from parts, and three bind mounts for keys, an import drop directory and a backup directory.
Those limits line up with the stated resource figures, described as under 100 megabytes of RAM and under one percent CPU in regular usage, so the cap is headroom rather than a contradiction.
Eight shell scripts sit alongside them, covering key generation, release, retagging, version updates, three development entry points and an MQTT broker entry point. The MQTT script is the one with a visible purpose, since real-time OwnTracks tracking can arrive over MQTT and the default compose path does not include a broker.
Alongside all of this are two documentation trees and two Helm directories, plus a Maven wrapper with its own directory. For a project whose selling point is a lightweight personal timeline, the number of ways to install it is the opposite.
The default image is a native build, with a fallback for old CPUs
The backend image the compose file pulls is suffixed for a native build rather than a JVM build, and the alternative is a second suffixed variant. The comment above it explains when to switch: old CPUs in the x86-64 version 2 range, or a Raspberry Pi 3 or 4.
That is an ahead-of-time compiled image rather than a runtime-dependent one, which is what makes the memory and start-up numbers work. It also explains why the release pipeline builds both a native and a JVM target from the same source, and why the arm64 native build has its own separate target rather than being produced by the multi-platform manifest helper.
The cost of that choice is build time. Native compilation of a Java service is considerably slower than a JVM build, and it happens twice per release, once per flavour. For a project with a release every couple of weeks that is a real cost paid for a real benefit on the Raspberry Pi and NAS hardware its users actually run.
The registry choice is also configurable in the compose file, where a commented line points the same image at a second host. That is a small thing that matters for anyone who cannot reach the primary registry.
The version itself comes from a variable in the environment file, with a comment stating that the app, frontend and backend should use the same version. Since the quick install downloads that environment file from the repository's main branch, the version you get is whatever main currently declares.
The cookie domain guidance is the best documentation here
One part of the configuration deserves praise rather than criticism. The cookie domain setting carries a comment block longer than most of the settings around it, and it is written for someone deploying rather than someone reading.
It starts by explaining why the setting usually does not need touching: the application proxies all requests, frontend and backend together, so the browser sees everything as same-origin. It then says for local, homelab and production deployments behind that proxy, leave the value empty, and marks that as the recommended path for the overwhelming majority of deployments. Three example domains are given that should stay empty, including a bare localhost address and two bare IP addresses.
Only after all that does it say when to set the value: when you deploy without the proxy and use separate subdomains, naming the frontend and backend subdomains and the shared parent domain to enter. The block closes by saying this is not a standard deployment.
That is the right shape for security-sensitive documentation. It leads with the safe default, gives concrete cases, says which way to err, and states the exception only after the common path is unambiguous.
The same file carries a deprecation note on the older UI URL variable, telling you it is kept for compatibility with older deployments and that new ones should use the origins list and a public base URL instead. Two settings that describe the same thing in different generations, with the older one labelled, is more than most projects manage.
Editorial conclusion
GeoPulse fits anyone who has years of location data trapped in a consumer timeline and wants it queryable, exportable and attached to their own photos, since the import paths and the integrations are the actual product. Three things to check before you expose it. The first account to register becomes the administrator, so register yours deliberately and put a reverse proxy with TLS in front of it. Review the cookie domain setting rather than copying the example, because getting it wrong on a subdomain split breaks authentication. And if you run bare make in a clone, know that its default target publishes a Helm chart.
Frequently asked questions
What is the GeoPulse alternative to?
GeoPulse describes itself as the open-source, privacy-first alternative to Google Timeline. It transforms raw GPS data from sources such as OwnTracks, Overland, Dawarich, GPSLogger, Home Assistant, Traccar and Colota into a searchable timeline of stays, trips and movement patterns on your own infrastructure.
How do I install GeoPulse quickly?
Create a directory, download the environment file and the compose file from the repository's main branch with curl, then run docker compose up -d and open port 5555. For MQTT support with OwnTracks, Kubernetes, Unraid, Proxmox or bare metal, separate deployment guides are provided.
How do I become the GeoPulse administrator?
Create the first account, which automatically becomes the administrator, or set the administrator email variable explicitly. Because it is first-account-wins, register your own account before anything else can reach the instance.
What does GeoPulse integrate with besides GPS apps?
Immich for photos on the map timeline, Memos for timestamped notes, and Weather for current conditions on trips, stays, map layers and journey insights. It also offers an AI chat using your own OpenAI-compatible key, and a read-only MCP server authenticated with an API token.
Does GeoPulse phone home or send telemetry?
No. The README states there is no telemetry, no analytics beacons and no third-party tracking, and that your location data stays on your own infrastructure. Full data export and per-account deletion are also supported.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tess1o-geopulse)Star history chart for your README
[](https://hysenlabs.com/projects/tess1o-geopulse)Was this useful?