The 100knocks Jupyter container starts with its token disabled, and the compose file names it twice
Data Science 100 Knocks (Structured Data Processing Edition).
At a glance
- What is it?
- The-Japan-DataScientist-Society/100knocks-preprocess is an exercise set for structured data processing, with the same hundred questions answered in SQL, Python and R, shipped with a Postgres container, dummy data and a browser notebook. The pedagogy is the interesting part. The packaging is where the detail sits: an unauthenticated notebook on port 8888, two different credential pairs for one database, a description section that lists the same Dockerfile path twice, and release tags that stopped in 2022 while commits carried on.
- Who is it for?
- Use this repository if you want one set of data processing exercises solved three ways, with real CSVs and a database rather than toy fragments, and if you are willing to work in a container rather than a local Python environment. Four things to check before you start.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 8 days ago.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 7, 2026, and from our analysis. They are not legal advice.
Star history
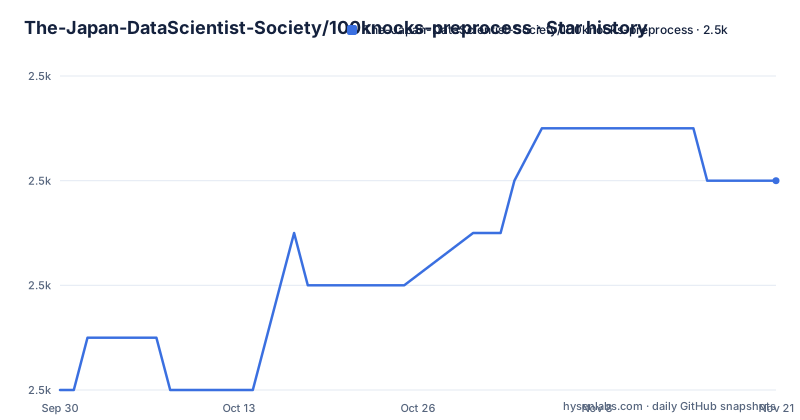
- The-Japan-DataScientist-Society/100knocks-preprocess2,537 ★ · +5
| Repository | 2026-09-30 | 2026-11-07 |
|---|---|---|
| The-Japan-DataScientist-Society/100knocks-preprocess | 2.5k | 2.5k |
5 Stars in the last 38 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The notebook service starts with its token set to an empty string
The notebook container is started by a command override rather than by the image's own entrypoint:
command: start-notebook.sh --NotebookApp.token=''Passing an empty token is how you turn off Jupyter's authentication. Combined with the environment line `JUPYTER_ENABLE_LAB=yes`, the result is a JupyterLab server with no password and no token, which is exactly what the Usage section expects a reader to do: open `http://localhost:8888` in a browser.
The exposure is bounded by two things, and it is worth being precise about both. The port mapping is `127.0.0.1:8888:8888`, so the port is published on the loopback interface only and is not reachable from another host without a deliberate change. And the target of that mapping is a container started from this repository's own notebook Dockerfile, running the exercise notebooks rather than anything a stranger supplied.
So the configuration is coherent for a single user on a laptop, and wrong for anything shared. The token is disabled rather than set, so there is no value to add later without editing the compose file, and nothing in the README mentions authentication at all. Two more binds complete the picture: `./docker/doc` is mounted read-write at `/home/jovyan/doc` and `./docker/work` at `/home/jovyan/work`, so the exercises, the answers and the guide are all visible inside the container as ordinary files.
Two credential pairs, one database, and a host variable pointing at localhost
The database service and the notebook service each carry their own set of credentials, and both point at the same database name, `dsdojo_db`.
The database side sets `POSTGRES_USER=postgres`, `POSTGRES_PASSWORD=postgres12345`, a `PGPASSWORD` with the same value, and `POSTGRES_DB=dsdojo_db`. It also sets `DATABASE_HOST=localhost`, which is the right address for a tool running inside that container and the wrong address for anything else on the network.
The notebook side uses a different user entirely: `PG_USER=padawan`, `PG_PASSWORD=padawan12345`, `PG_DATABASE=dsdojo_db`, with `PG_PORT=5432`. So the compose file provisions one database and then reaches it under two identities, and the role the exercises connect as is the second one. The naming is worth noting too: `padawan` is the apprentice term from the same fiction that the dummy data is drawn from.
Four plaintext passwords and a superuser named postgres are written into a tracked file. In context that is defensible for a local exercise database, and the port is bound to `127.0.0.1`, but the file also shows a `db` service whose healthcheck the notebook waits on, since `depends_on` uses the condition `service_healthy`. That condition means the Postgres image defines a health check, which is what makes `docker compose up --wait` in the install instructions a meaningful gate.
The description section lists the notebook Dockerfile twice
The Description section of the README enumerates what the repository contains, and the first item names two files:
`Dockerfile(`dockerfiles/notebook/Dockerfile`, `dockerfiles/notebook/Dockerfile`)`
The same path is written twice. The compose file shows what the second one should have been: the database service builds from `dockerfiles/postgres/Dockerfile`, and the notebook service builds from `dockerfiles/notebook/Dockerfile`. There are two Dockerfiles in the repository, in two directories, and the README pairs one of them with itself.
It is a small copy and paste slip in a document that is otherwise precise about where things live, and it matters more than it looks. A reader who copies the Description section to work out what to edit when the database configuration changes will open the notebook image twice and never look at the Postgres image, which is where the database's own entrypoint, its init scripts and its health check live.
The rest of that section is a usable inventory: the compose file, dummy supermarket purchase records and dummy personal information as CSVs, the scripts that initialise the database, and both notebook and HTML renderings of the questions and answers. The HTML copies are why the repository's primary language is HTML rather than Python.
A credential scanner guards commits, and the compose file is in the repository it guards
The contribution section asks anyone helping with development to clone the repository and install pre-commit following the instructions at pre-commit.com. The stated payoff is specific: the repository's `.pre-commit-config.yaml` then checks at commit time that credentials are not included in what you commit.
The top level backs that up with more configuration than the README mentions. There is a `.gitleaks.toml`, which is the configuration for a secret scanner, and a `.dockleignore`, which is the ignore file for a container image linter. Three separate tools, described in the README as one.
The gap between the stated policy and the tracked content is the part worth flagging, and it is not a criticism of the scanners. The compose file itself contains four plaintext database passwords, two usernames and a disabled notebook token, all committed and all, by the scanners' own logic, shaped like credentials. A secret scanner configured to catch leaked keys will either have to be told to ignore this file or will flag the project's own configuration on every run. Either way the exception is worth making explicitly, because a reader who trusts the pre-commit setup as a guarantee about what may be committed will draw the wrong conclusion about the file sitting in the tree.
What the setup does buy is real for the exercise notebooks, which is where a pasted API key would actually land.
Four dependency manifests for three languages, and one of them installs pipenv
Exercises are answered in SQL, Python and R, and the repository carries a manifest for each. At the top level there is a `Pipfile` with a `Pipfile.lock` beside it, an `environment.yml` for conda, an `install.R`, and a `requirements.txt`.
That is two Python dependency systems in one repository. Pipenv and pip requirements are both ways to pin Python packages, and having both means a contributor has to know which one the notebooks were resolved against. The choice of file for each is informative, though, because the requirements file is not a package list:
pipenv==2024.0.1One line, and it pins the tool rather than anything the notebooks import. So `pip install -r requirements.txt` installs the dependency manager and nothing else; the actual Python dependencies live in the Pipfile. The conda file and the R script cover the other two languages in the only form each of those ecosystems has.
The README's own guidance reflects this split rather than hiding it. For local work the supported path is Docker Desktop on Windows 10 or 11 or on macOS, with Docker Desktop 4.4.2 or later named as the requirement on Apple silicon Macs, and a note that WSL2 makes Docker Desktop usable on Windows Home. For cloud work there are links that import the exercise notebook and the answer notebook into Amazon SageMaker Studio Lab and into Colaboratory, which sidesteps the local toolchain entirely.
Tags stopped in 2022 and the commits did not
Three tags are visible, and two of them share a day: v1.1 and v2.0 both dated 2022-03-25, about an hour and a half apart, and v2.1 dated 2022-06-30. The most recent push to the default branch is dated 2026-09-12.
So the newest release is more than four years older than the newest commit, and the two tags from March 2022 suggest a version scheme that moved quickly and then stopped. Anyone following documentation that refers to a release will be reading about a tree from 2022, and anyone who wants the current state wants master.
The repository is not archived, and the exercise data and notebooks are versioned in git like everything else, so this is a maintenance pattern rather than a sign of abandonment. It does mean there is no tag to anchor a training cohort or a teaching term to, and no release notes beyond what the commit log carries.
The third-party link section reinforces how little the repository tries to be self explanatory. Six outside links are listed, covering a review video, a personal blog write-up, three separate Japanese community articles on running the material on macOS, in Google Colab and Azure Notebooks, and on getting it working on Windows 10 Home, plus a hosting company's knowledge base entry. Each is community documentation rather than project documentation, and several exist precisely because the project's own install notes are three short remarks about sharing, permissions and an extra directory of PDFs.
The other date worth knowing is the one in the LICENSE section, where the guide PDF under `docker/doc` is called out separately from the rest of the files.
One PDF is CC-BY-ND inside an otherwise MIT repository
The LICENSE section splits the repository in two. Most files follow the MIT license. One file does not:
`docker/doc/100knocks_guide.pdf` is CC-BY-ND, and the reason given is that it contains the association logo and similar marks.
That is a coherent position. Attribution plus no derivatives is the right licence for a document carrying an organisation's logo, and keeping it out of the MIT grant avoids implying that a reader may modify and redistribute the mark. It is also the file the install instructions point you at, since one of the three notes under Install tells readers to consult the explanation materials under `doc`.
The license shows as NOASSERTION in the repository metadata, while a `LICENSE` file exists at the root, so the README section is the statement to rely on. Nothing in the root file listing contradicts the README; there is simply one binary under `docker/doc` that the MIT grant does not cover.
Separately, the README advertises a companion guide book for sale and links to a store listing for it. That is a link to a published book, not a copy of one in the repository, and the PDF described above is the association's own material under its own terms. The Overview also states that every field resembling personal information is dummy data, which is the claim a reader of the personal-information exercises needs, and that organisations may use the material freely as long as they name the DataScientist Society skills definition committee's 100knocks as the source.
Two disclaimers close that section, and they are unusually direct for an exercise set. Questions about using the material are not answered individually, and the association accepts no responsibility for any problem arising from its use. The second one is the price of the permissive MIT grant on everything except the logo-bearing PDF: nothing about fitness is claimed. The third statement is the one that matters for the pedagogy, namely that some questions do not suit a particular language, and that the priority is the technique of expressing the thing in whichever language you have chosen.
Editorial conclusion
Use this repository if you want one set of data processing exercises solved three ways, with real CSVs and a database rather than toy fragments, and if you are willing to work in a container rather than a local Python environment. Four things to check before you start. The notebook has no authentication token and its port is published to loopback, so do not assume the binding is the only thing standing between your machine and arbitrary code execution over the network. The database has two credential pairs in the compose file, one per service, so confirm which one your notebooks use. The install instructions require directory permissions that the README says cause most failures, and on macOS anything outside your home directory needs extra Docker sharing. And the newest tag is from 2022, so read the current master rather than a release when you follow the documentation.
Frequently asked questions
How do I start the 100knocks-preprocess exercises locally?
Clone the repository, change into the directory and run `docker compose up -d --build --wait`, then open http://localhost:8888 in a browser. The local path assumes Docker Desktop on Windows 10 or 11 or on macOS, with 4.4.2 or later on Apple silicon Macs, and WSL2 on Windows Home.
Does the 100knocks Jupyter notebook require a password or token?
No. The notebook service is started with `command: start-notebook.sh --NotebookApp.token=''`, which disables authentication. The port is published as 127.0.0.1:8888, so it binds to loopback only.
Which database credentials does the 100knocks compose file use?
Two. The db service sets POSTGRES_USER=postgres with POSTGRES_PASSWORD and PGPASSWORD both set to postgres12345, while the notebook service connects as PG_USER=padawan with PG_PASSWORD=padawan12345. Both point at the database named dsdojo_db.
Which languages are the 100knocks exercises written in?
The exercises are common across SQL, Python and R, and the repository carries a manifest for each: a Pipfile with a lock file, an environment.yml for conda, an install.R, and a requirements.txt that pins only pipenv rather than any package the notebooks import.
What license covers the files in 100knocks-preprocess?
Most files are MIT. The guide PDF at docker/doc/100knocks_guide.pdf is CC-BY-ND because it contains the association logo. The license field is NOASSERTION in the repository metadata while a LICENSE file exists at the root.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/the-japan-datascientist-society-100knocks-preprocess)Star history chart for your README
[](https://hysenlabs.com/projects/the-japan-datascientist-society-100knocks-preprocess)Was this useful?