claude-mem compresses your sessions, and the install path that looks right is the wrong one
Persistent Context Across Sessions for Every Agent, Captures everything your agent does during sessions, compresses it with AI, and injects relevant context back into future sessions. Works with Claude Code, OpenClaw, Codex, Gemini, Hermes, Copilot, OpenCode + More.
At a glance
- What is it?
- claude-mem captures tool usage from a coding agent session, compresses it into semantic summaries and feeds the relevant parts into later sessions. It is well documented, aggressively cross-IDE, and it hides two decisions that matter: memory defaults to a hosted service, and the obvious npm install gives you a library with no hooks attached.
- Who is it for?
- claude-mem is worth trying if you lose context at the end of every session and you are comfortable deciding deliberately where the summaries are computed and stored. It is a poor fit if you expected `npm install -g claude-mem` to be the whole setup, because that path installs a library and none of the hooks, and the symptom is a tool that appears to do nothing.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
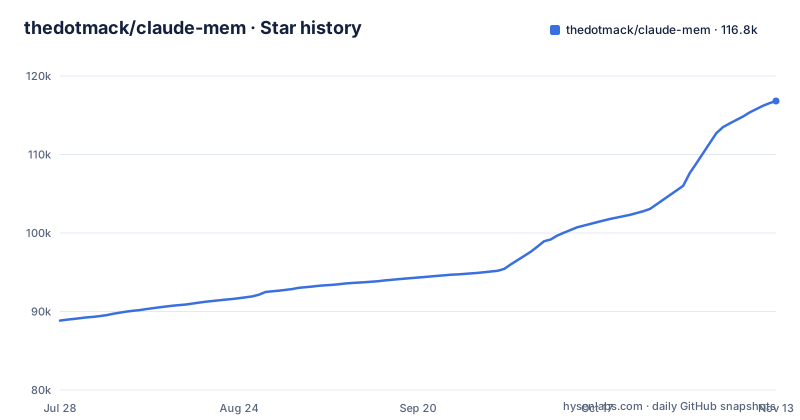
- thedotmack/claude-mem116,815 ★ · +27,968
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| thedotmack/claude-mem | 88.8k | 116.8k |
27,968 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Capture, summarise, inject: the middle step is what costs you model calls
The pipeline has three stages and the README states all three. First it captures tool usage observations as an agent works. Then it generates semantic summaries of those observations, which is the step that calls a model. Then it makes those summaries available to future sessions, so a new session starts with knowledge of the project that the previous session built up.
The compression is the point rather than a detail. Storing raw transcripts and replaying them would grow the context window without bound, so the system trades fidelity for size, keeping a summary of what happened instead of every step that produced it. That trade is also the limitation: a summary is a lossy record, and a decision whose reasoning mattered more than its outcome is exactly the kind of thing a summary drops.
The project is not Claude Code only in practice, despite being built for it. The repository ships plugin directories for several hosts at once, including `.claude-plugin/`, `.codex-plugin/`, `.cursor-plugin/`, `.grok-plugin/` and `.qoder-plugin/`, and the installer takes an `--ide` flag, so the same memory layer is aimed at Claude Code, Codex, Cursor, Grok Bot, Antigravity, OpenCode and OpenClaw.
npm install -g claude-mem installs the library and none of the hooks
This is the sharpest trap in the project and it is called out explicitly. Claude-Mem is published on npm, but a global install of the package gives you the SDK and library only. It does not register the plugin hooks and it does not set up the worker service. The documented paths are the installer and the marketplace commands:
npx claude-mem install
npx claude-mem install --ide opencode
Inside Claude Code the equivalent is to add the marketplace and install the plugin:
/plugin marketplace add thedotmack/claude-mem

/plugin install claude-mem
Restart Claude Code afterwards, and context from previous sessions appears in new ones. The same pattern holds for the other targets, with `npx claude-mem install --ide antigravity` and `npx claude-mem install --ide grok-bot`, and OpenClaw gateways use a single shell installer at `https://install.cmem.ai/openclaw.sh` that handles dependencies, plugin setup, provider configuration, worker startup and optional real-time observation feeds.
The consequence of getting this wrong is a confusing failure rather than a loud one. A global install succeeds, the package is present, and no memory ever appears, because the part that records sessions is the hook and the worker, and neither was installed.
Memory defaults to a hosted service, and the free observer lasts fourteen days
The default provider is CMEM Pro, the hosted memory. On installation you are asked to sign in through an email magic link with no card required, and signing in provisions a memory key for the account and unlocks the claude-mem observer, which runs off-plan and is free for up to 30 days. The stated benefit is up to 100% more usage from your own plan while it lasts.
What happens on day 31 is the part to notice. When the free trial ends, memory automatically falls back to your Anthropic plan unless you subscribe. So the compression step, which is a model call per session summary, moves from a bundled trial onto your own usage after 30 days without any change in how you invoke the tool. Anyone budgeting model spend should decide this on day one rather than discover it on the invoice.
There are three documented ways to stay off the hosted path, and all three are cheap. Pass an explicit `--provider` flag, set `CLAUDE_MEM_ONLINE_OPTIN=false`, or run in a CI or non-interactive shell, in which case the installer completes without any account interaction at all. The local observer is opt-in through `--provider host`.
Grok Bot has no host hooks, so it reads chat logs and gets a narrower memory
Not every host works the same way, and Grok Bot is the documented exception. It has no host hooks, so rather than receiving tool events the plugin watches the chat log files. Everything downstream of that is different in kind from the hook-based IDEs: the inputs are whatever was written to a log, not the tool calls themselves.
The awareness pilot for that host is narrow by design. Needle observations, the categories `decision`, `bugfix`, `security_alert` and `sensitive`, are appended as dated `- YYYY-MM-DD [awareness] …` lines into that bot's `memory/log/YYYY-MM.md`, and Grok Bot already re-reads that log from disk so no re-injection is needed. The pilot explicitly does not write `profile.md`, user memory or project memory, and it is turned off with `CLAUDE_MEM_GROK_BOT_AWARENESS_ENABLED=false`.
The consequence is that a Grok Bot user gets a partial memory with a different shape from a Claude Code user, sourced from text logs instead of structured events. Also worth knowing: installing the Grok Bot plugin does not install Cursor, so the two are separate installations rather than one bundle.
The self-hosted stack refuses to start without secrets and must not face the internet
The repository ships a server deployment, and its compose file opens with a security warning that is unusually direct. It states the file must not be deployed unmodified to any environment reachable from the public internet, including staging behind a VPN where lateral movement is possible. Postgres credentials are required environment variables with no defaults, and the stack refuses to start if any required secret is missing.
The shape of the stack is Postgres as canonical storage, Valkey as the BullMQ queue, a `claude-mem-server` that does HTTP and no generation, and a `claude-mem-worker` that consumes the queue and does generation. Generation scales by replica count, not by configuration:
POSTGRES_USER=... POSTGRES_PASSWORD=... docker compose up
docker compose up -d --scale claude-mem-worker=N
One more constraint is enforced rather than advised: the `local-dev` auth mode is rejected inside Docker, so the easy local configuration is unavailable in the container. The practical consequence is that self-hosting correctly is entirely your responsibility, and the file you would naturally copy is the one marked unsafe for a network. A deployment that adds authentication, terminates TLS in front, and supplies real secrets is required before this belongs anywhere shared.
Node 20.12 and Bun 1.1 are the floor, and 13.x ships several releases a day
The runtime requirements are stated in `package.json` rather than in prose: `node` at `^20.19.0 || >=22.12.0` and `bun` at `>=1.1.31`. The package is an ES module, exposes a single binary at `./dist/npx-cli/index.js`, and ships a `files` list that includes `dist`, `plugin/hooks`, `plugin/modes`, `plugin/skills`, `plugin/sqlite`, `plugin/ui` and the `openclaw` directory, which is what the installer copies into a host.
The versioning tells you how fast this moves. The current version is 15.9.0, and the three most recent releases, v15.9.0, v15.8.3 and v15.8.2, all shipped on 2026-11-02. The last push to the repository was on 2026-11-01.
The consequence for an adopter is that an unpinned install is a moving target measured in hours, and the hooks are the fragile part of it because they run inside someone else's agent. Pin the version you validate against, and expect to re-validate after an upgrade rather than assuming a patch bump changed only internals. The Apache-2.0 licence is one fixed point that makes that cadence tolerable.
Editorial conclusion
claude-mem is worth trying if you lose context at the end of every session and you are comfortable deciding deliberately where the summaries are computed and stored. It is a poor fit if you expected `npm install -g claude-mem` to be the whole setup, because that path installs a library and none of the hooks, and the symptom is a tool that appears to do nothing. Before you commit, run `npx claude-mem install --provider host` to keep compression local, and read the security note at the top of the repository's docker-compose file if you plan to self-host the server rather than use the hosted memory.
Frequently asked questions
What is Claude Mem?
Claude-Mem is a memory compression system for Claude Code, released under Apache-2.0 and published at version 15.9.0. It captures tool usage observations during a session, generates semantic summaries of them with AI, and makes those summaries available to future sessions so context survives the session ending.
How do I install claude-mem?
Run npx claude-mem install, or name a target with npx claude-mem install --ide opencode, --ide antigravity or --ide grok-bot. Inside Claude Code, add the marketplace with /plugin marketplace add thedotmack/claude-mem, then run /plugin install claude-mem and restart Claude Code.
Is Claude Mem free?
Not entirely. Signing in provisions a memory key and unlocks the claude-mem observer, which is free for up to 30 days, after which memory falls back to your Anthropic plan unless you subscribe. You can avoid the account by passing an explicit --provider flag, setting CLAUDE_MEM_ONLINE_OPTIN=false, or running in a CI or non-interactive shell.
Is Claude Mem safe to self-host?
The repository's own docker-compose file states it must not be deployed unmodified to any environment reachable from the public internet, including staging behind a VPN. Postgres credentials are required environment variables with no defaults, the stack refuses to start without them, and the local-dev auth mode is rejected inside Docker.
claude-mem vs mem palace
The comparison has to rest on claude-mem's own design, which is the three-stage design of capturing tool usage observations, generating AI semantic summaries and injecting them into later sessions, plus per-IDE plugin directories and an npm package whose global install deliberately omits the hooks.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Installing claude-mem uploads your last 30 days of prompts to cmem.ai, no opt-inHacker News · Oct 29, 2026 · 3 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/thedotmack-claude-mem)Star history chart for your README
[](https://hysenlabs.com/projects/thedotmack-claude-mem)Was this useful?